Key takeaway
- Apache Hudi explained for data leaders: timeline, copy-on-write vs merge-on-read, indexes, query types, concurrency and current Spark support, per docs.
What is Apache Hudi?
Apache Hudi is, in the words of its own site, an open data lakehouse platform built on a high-performance open table format. It adds database-style features to a data lake while the data stays in open file formats on storage you already own. Its documentation lists tables, transactions, efficient upserts and deletes, indexes, clustering and compaction, concurrency control, and support for streaming workloads and incremental batch pipelines.
For an enterprise team the practical answer is this: Hudi lets you update, delete and incrementally read records in lake storage without rewriting whole datasets. It sits in the same family as the other lakehouse table formats, so read it alongside our guides to the data lakehouse and to data lake vs warehouse vs data lakehouse.
Where does Hudi sit in a lakehouse stack?
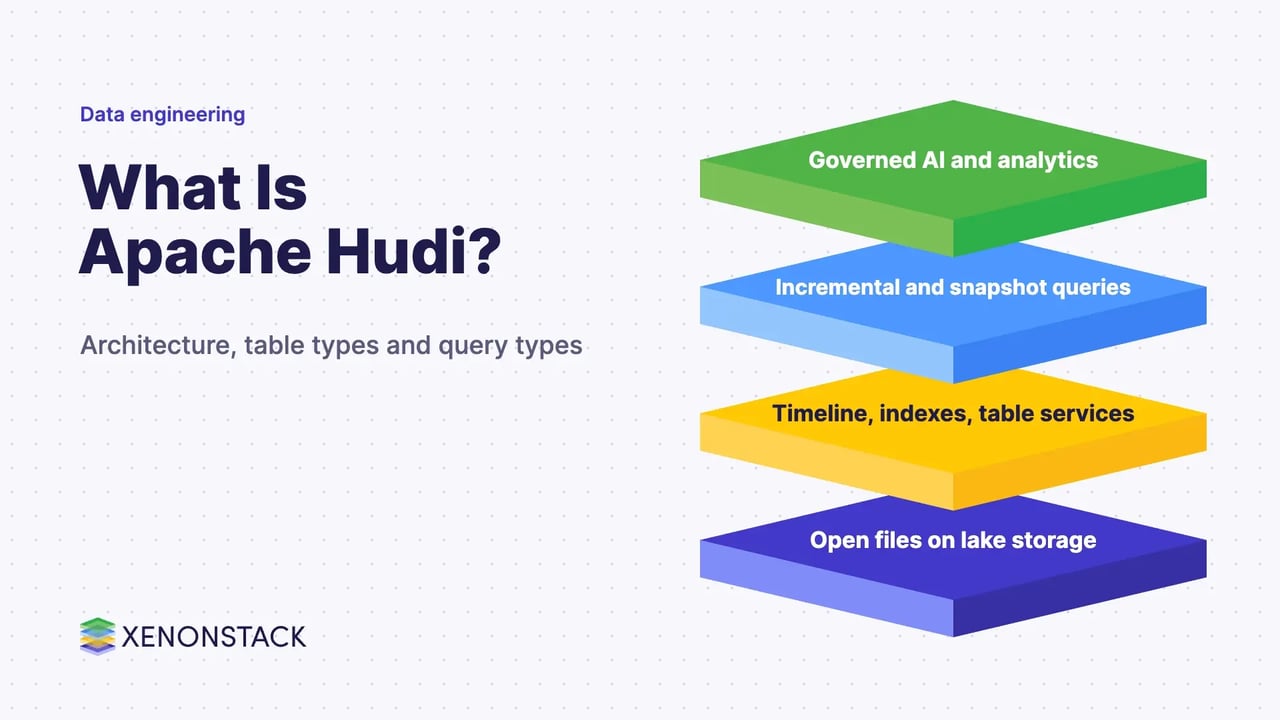
The Hudi stack page describes layers from the bottom up. Lake storage holds data and table metadata on HDFS or cloud stores such as Amazon S3, Google Cloud Storage and Azure Blob Storage. Open file formats such as Parquet and Avro hold the data. The table format layer manages file layout, partitioning, schema and change tracking. A storage engine layer adds indexes, table services and concurrency control. Writers and readers sit above that, and query engines and catalogs sit at the top.
| Layer | What it does | Why a platform lead cares |
|---|---|---|
| Lake storage | Holds data files and table metadata on HDFS or cloud object storage | Data stays in storage you control |
| File formats | Parquet base files and Avro log files, grouped into file groups and file slices | Open formats keep tools interchangeable |
| Table format | Timeline, file groups and a metadata table | Gives every table an auditable history |
| Storage engine | Indexes, clustering, compaction, cleaning, concurrency control | Decides write cost and read speed |
| Query engines | Spark, Flink, Trino, Presto, ClickHouse, StarRocks and others | Many engines read one copy of the data |
How does the Hudi architecture work?
Timeline
The timeline records every change to table state as an action at an instant, and the docs call it the source of truth for the state of the table. Actions include COMMIT, DELTA_COMMIT, REPLACE_COMMIT, CLEANS, COMPACTION, CLUSTERING, ROLLBACK, SAVEPOINT and RESTORE. Each action moves through the states REQUESTED, INFLIGHT and COMPLETED. Completed actions are archived into a log-structured merge tree history so the active timeline stays small.
File groups, file slices and the metadata table
Within each partition, data is organised into file groups. A file slice is a base file plus its log files. Log files record inserts, updates and deletes, and compaction merges them into new base files. The metadata table is itself a merge-on-read Hudi table that stores file paths, column statistics and schema, which reduces expensive cloud file listings.
Indexes
An index maps a record key to the file group that holds it, so an upsert can find the record to change. The docs list writer-side types set with hoodie.index.type, including SIMPLE, BLOOM, GLOBAL_BLOOM, GLOBAL_SIMPLE, HBASE, BUCKET, RECORD_LEVEL_INDEX and GLOBAL_RECORD_LEVEL_INDEX. The record-level indexes are available from Hudi 1.1.0. Which one fits depends on whether keys are unique per partition or across the table, and on table size.
Copy-on-write or merge-on-read: which table type should you choose?
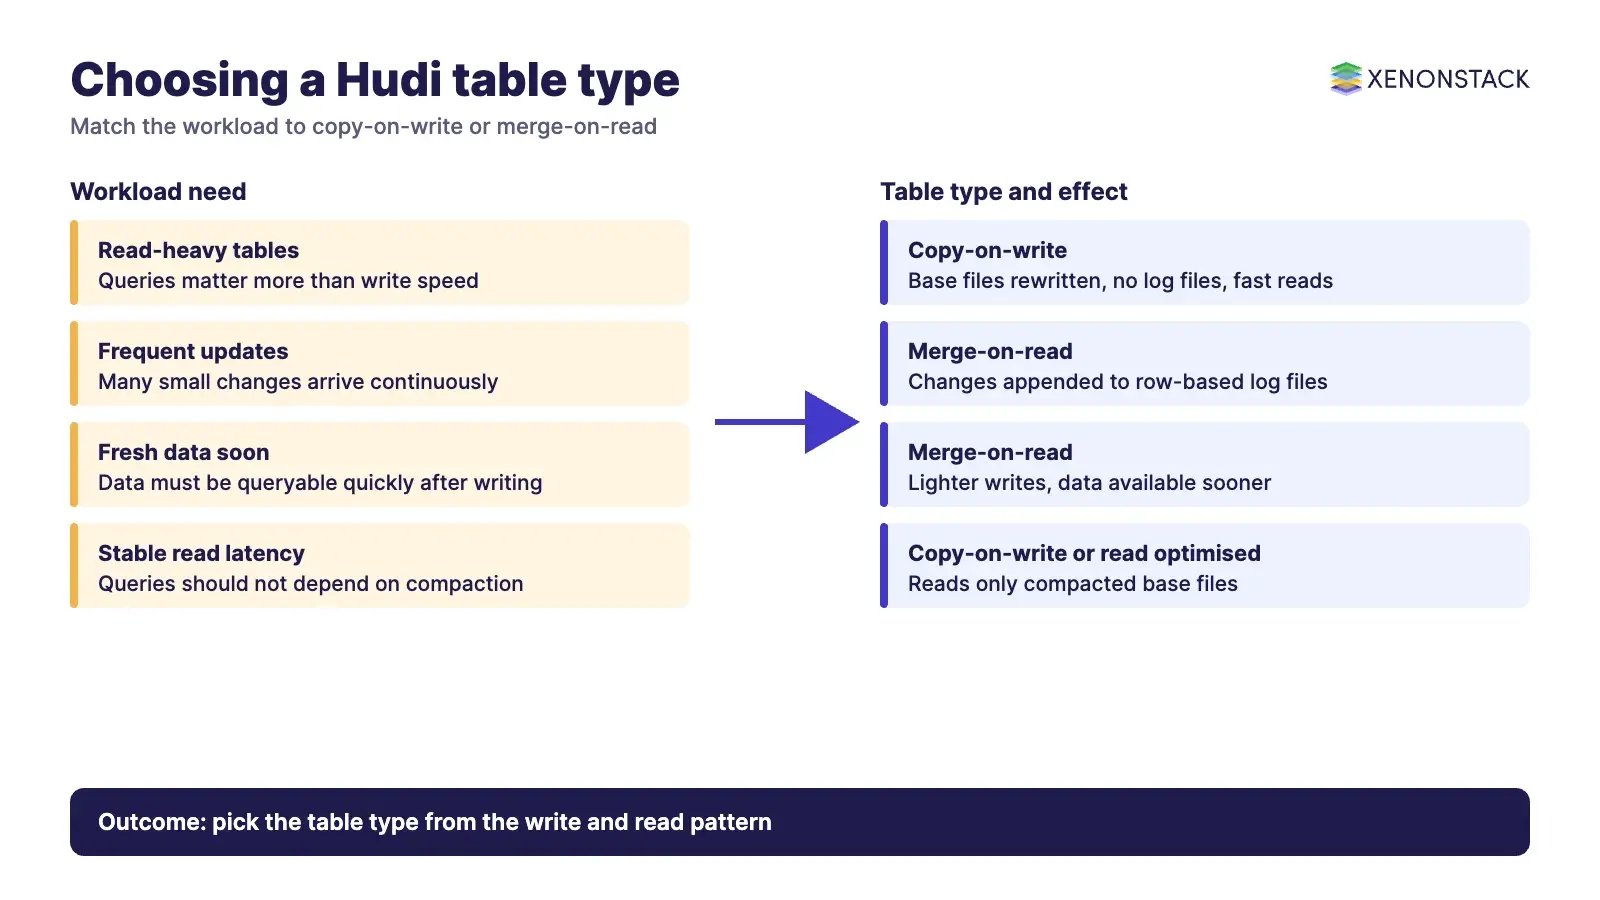
Hudi supports two table types. Copy-on-write rewrites base files on every update and writes no log files, so reads are fast and writes are heavier. Merge-on-read sends updates and deletes to row-based log files that are merged with base files at query time, and a periodic compaction folds the logs into new base files. Writes are lighter and data is available sooner, but query performance depends on how recently compaction ran.
| Trade-off | Copy-on-write | Merge-on-read |
|---|---|---|
| Write latency | Higher | Lower |
| Query latency | Lower | Higher |
| Update cost | Higher, base files are rewritten | Lower, changes are appended to logs |
| Read amplification | None | Grows with changed records in the file groups read |
| Best fit | Read-heavy workloads | Write-heavy or fresher-data workloads |
What query types and write operations does Hudi support?
The documented query types are snapshot, time travel, read optimised (merge-on-read only) and incremental. Snapshot queries return the latest state as of the latest completed action. Time travel returns the table as it was at a past instant or savepoint, which the docs note is useful for reproducing training data for models. Incremental queries return only records inserted or updated since a given instant, and a change data capture variant returns inserts, updates and deletes with before and after images. Read-optimised queries read only base files, so they are faster but can lag recent changes until compaction.
On the write side, the write operations are UPSERT (the default), INSERT, BULK_INSERT, DELETE, BOOTSTRAP, INSERT_OVERWRITE, INSERT_OVERWRITE_TABLE and DELETE_PARTITION. UPSERT uses the index to tag each record as an insert or update, and the docs state the target table will never show duplicates. INSERT skips the index lookup and is faster when duplicates are tolerable. BOOTSTRAP converts an existing large table into a Hudi table.
How does Hudi handle concurrent writers?
The concurrency control page describes three modes. With a single writer plus table services, readers get snapshot isolation through MVCC. With optimistic concurrency control, conflicts are detected at file level, so writers touching different files can both succeed, while overlapping writes allow only one to win. Non-blocking concurrency control lets several writers write to the same file group, and the docs say it works only for merge-on-read tables using the simple bucket index or partition-level bucket index. Lock providers include storage-based, ZooKeeper, Hive Metastore, DynamoDB and in-process options.
Which engines and versions work with Hudi today?
The Hudi documentation currently covers release 1.2.1. Its Spark quick start states that Hudi 1.2.x supports Spark 4.1, 4.0, 3.5 (the default build), 3.4 and 3.3, with Java 17 or later for Spark 4.0 and 4.1 and Java 8 or later for Spark 3.x. Other engines named in the docs include Flink, Presto, Trino and Hive. Confirm versions on the quick start guide before you plan a platform.
| Question | Where to confirm |
|---|---|
| Supported Spark, Flink and Java versions | Hudi quick start guide |
| Index choice and defaults | Hudi indexes page |
| Table type and query type behaviour | Hudi table types page |
| Multi-writer setup and lock providers | Hudi concurrency control page |
How does Hudi compare with Delta Lake and Iceberg?
All three are open table formats that add transactional behaviour to lake storage, but the right choice depends on your engines, write pattern and catalogue. Hudi's own design emphasises record-level upserts and deletes, indexes, incremental and change data capture reads, and built-in table services. From Hudi 1.1 its docs describe a pluggable table format, with Apache XTable (incubating) providing adapters for Iceberg and Delta Lake. Compare each format on its own documentation and test with your workload, because capabilities in all three keep changing.
Which Hudi best practices matter for an enterprise data platform?
Choose the table type from the workload: copy-on-write for read-heavy tables, merge-on-read where write latency and data freshness matter.
Pick the index from your key design. Use a global index only when keys must be unique across all partitions.
Set an ordering field so the larger value wins when two records share a key (
hoodie.table.ordering.fieldsin Spark,ordering.fieldsin Flink).Schedule compaction, clustering and cleaning deliberately, because compaction timing decides how current read-optimised queries are.
Use savepoints and time travel to reproduce a dataset for audit or model training.
Keep ingestion and catalogue decisions consistent with your wider architecture, for example the patterns in our big data architecture guide and the ingestion approach in Apache Gobblin.
When is Hudi not the right fit?
Hudi targets analytical datasets in lake storage, not low-latency transactional serving. If your tables are append-only and rarely updated, the indexing and compaction machinery adds operational work you may not need. If your platform is standardised on one engine and one catalogue, check that engine's support for Hudi before committing. When several writers contend on the same files, plan for the concurrency mode and lock provider up front.
What will governed AI need from your Hudi tables?
Once AI agents read from lakehouse tables, the table timeline, savepoints and time travel become evidence of which data version a decision used. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents. For questions in plain language over enterprise data, AgentAnalyst lets teams ask questions of enterprise data in plain language and get real-time insights.
To map one data-platform decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions about Apache Hudi
What does Apache Hudi do?
It adds database-style features such as transactions, upserts, deletes, indexes and incremental reads to data stored in open formats on a data lake.
What are Hudi's two table types?
Copy-on-write rewrites base files on update and favours read-heavy workloads. Merge-on-read writes updates to log files and merges them at query time or through compaction, which favours lighter writes.
What is an incremental query in Hudi?
It returns only records inserted or updated since a given instant. A change data capture variant also returns deletes and before and after images.
Can several writers write to one Hudi table?
Yes. Hudi documents optimistic concurrency control with a lock provider and non-blocking concurrency control for merge-on-read tables that use a bucket index.
Which Spark versions does Hudi 1.2.x support?
According to the Hudi quick start, Spark 4.1, 4.0, 3.5, 3.4 and 3.3. Confirm on the page before you build.
Ready to put AI agents to work? See an ElixirClaw demo: the agentic OS to build, orchestrate and govern AI agents across your enterprise systems.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE