Key takeaway
- Apache Gobblin is a distributed data integration framework. See its six components, job state, deployment modes and how it compares with Marmaray.
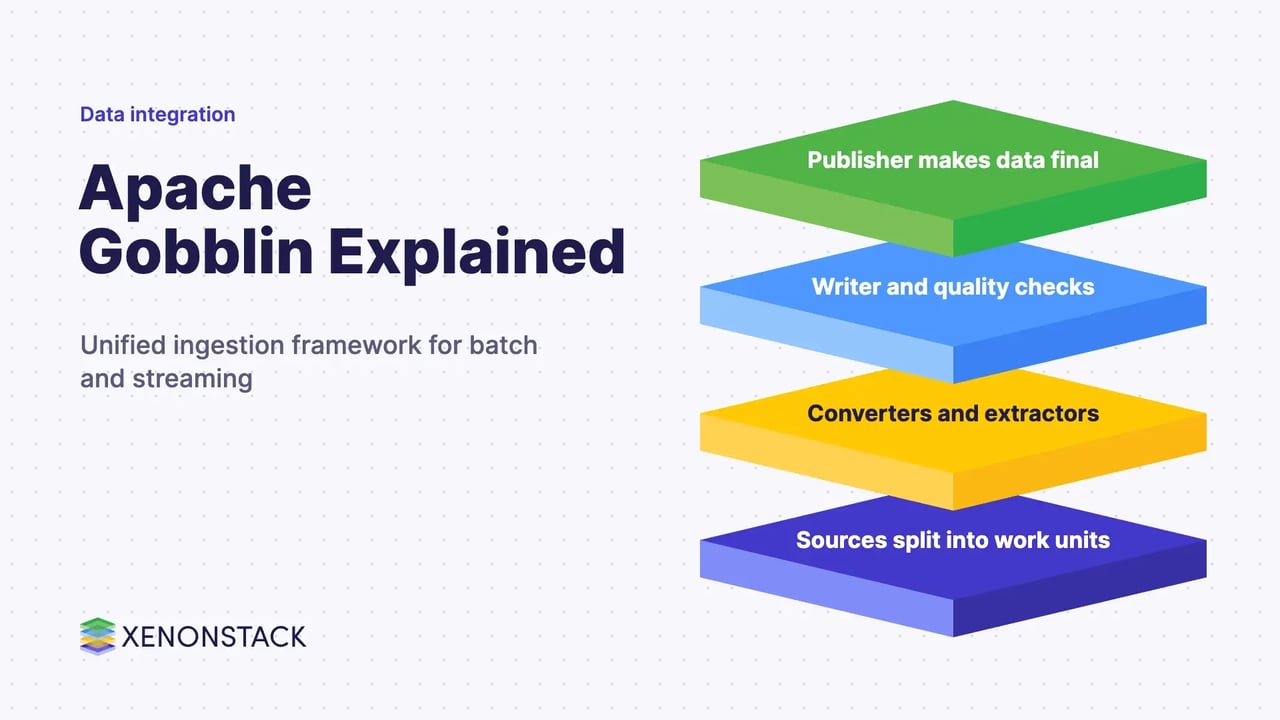
Apache Gobblin is a distributed data integration framework for ingesting, replicating, organising and managing the lifecycle of data, in both batch and streaming forms. The Apache Gobblin homepage describes it in those terms, and a January 2021 news item there records that it became a top-level Apache project.
This guide is for data engineers who need one framework to bring data from many sources into a lake or warehouse. It covers the six component interfaces, how a job runs, the deployment modes, how quality checks and publishing work, and where Gobblin sits against other options. For the concept behind it, start with our guide to data ingestion.
What is Apache Gobblin and what does it do?
Per its architecture documentation, Gobblin is built for extensibility: its constructs are pluggable through job configuration, while the runtime handles scheduling, retries, resource management, state, quality checks and publishing. In practice that means a team writes or configures the source-specific parts and reuses the common ingestion machinery, so many sources can run in the same execution framework instead of as many separate scripts. The same idea sits behind Uber Marmaray, which was inspired by Gobblin.
What are the components of Apache Gobblin?
The architecture page lists the following constructs.
| Component | What it does |
|---|---|
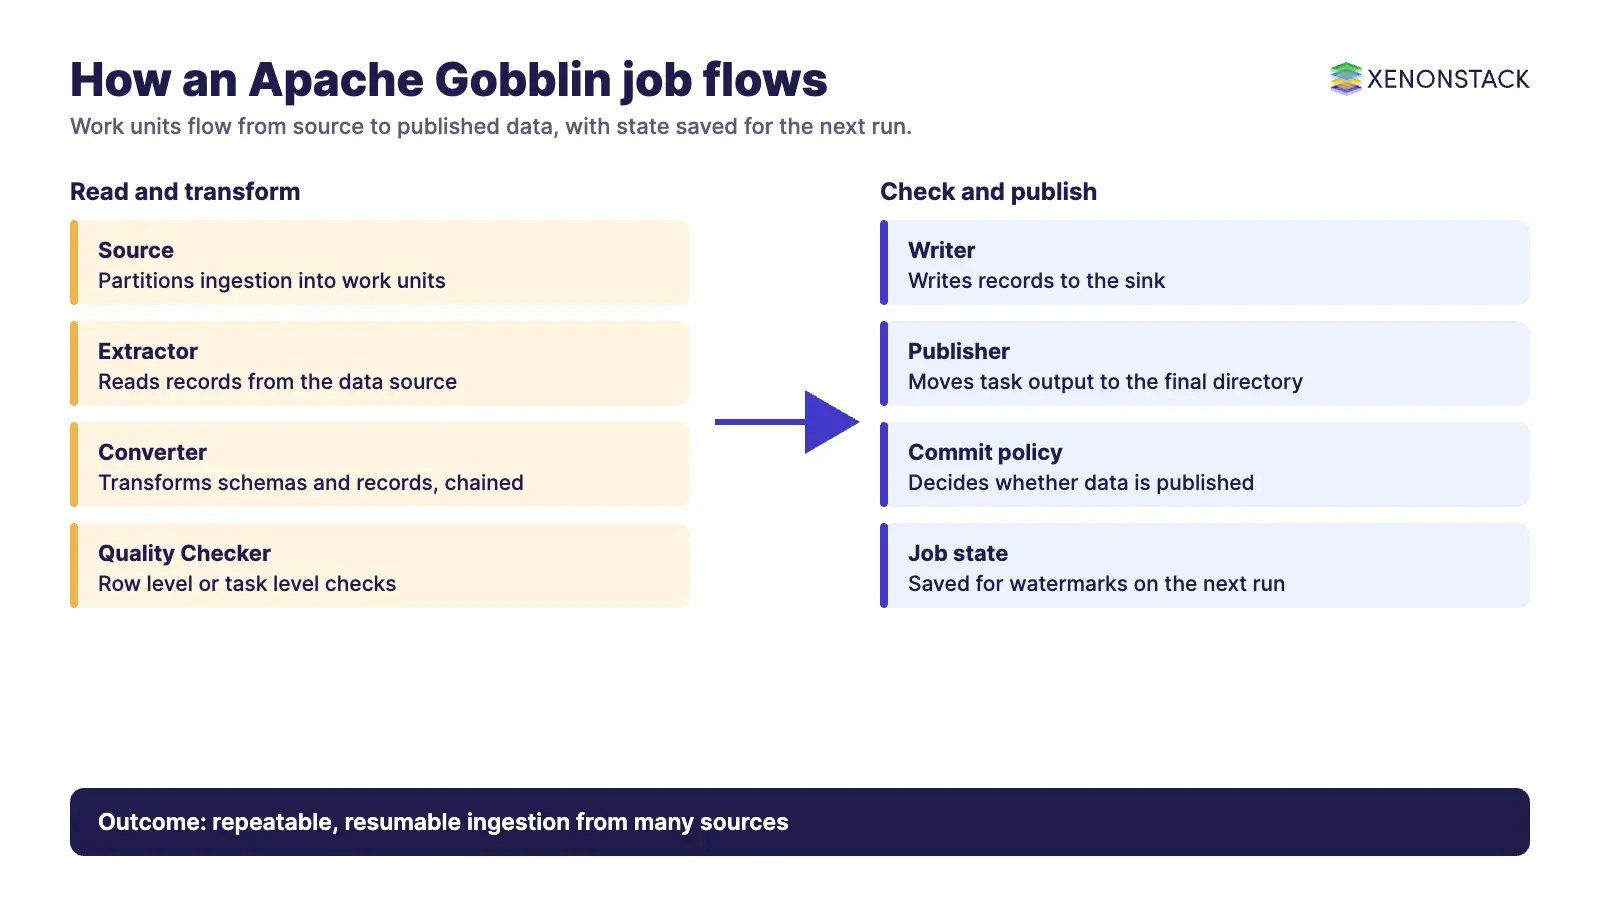
| Source | Partitions the ingestion into work units and creates an extractor for each one; modelled after Hadoop's InputFormat |
| Extractor | Connects to the data source and reads records one at a time |
| Converter | Transforms schemas and records and can be chained; the core construct for data transformation |
| Quality Checker | Runs at row level or task level; optional checkers are informational only, while mandatory checkers determine whether the check passes |
| Writer | Writes records to a sink; the default writes Avro to HDFS |
| Publisher | Makes extracted data final; the default moves each task's output into the job's final output directory |
A work unit is a unit of work that also acts as a container for job configuration at runtime. Normally one task is created per work unit, although a multi work unit can wrap several.
How does a Gobblin job run?
A job ingests data from a source into a sink and may split into many tasks. According to the documentation, job state is persisted after each run so that incremental extraction can resume: the next run loads the previous job and task states to recover details such as watermarks, so it knows where to start. By default that state is stored as Hadoop SequenceFiles, one per job run. Data is published only if the commit policy allows it, and a cancelled job does not persist state or publish data.
This is why Gobblin suits incremental loads. A failed or cancelled run does not advance the position, so the next run can try again from the last good point. Related guidance is in our notes on building a data ingestion platform with Apache NiFi and real-time data integration.
How can you deploy Gobblin?
| Mode | How it runs | Source |
|---|---|---|
| Standalone | Single node, with tasks running in a thread pool dedicated to each job | Architecture documentation |
| Hadoop MapReduce | Cluster mode, with tasks running inside mappers that act purely as containers | Architecture documentation |
| Cluster and cloud | The homepage lists cluster or YARN and cloud execution among the supported modes | Gobblin homepage |
The architecture page is older than the homepage: it says native YARN deployment was still being worked on, while the homepage now lists YARN and cloud modes. Check the current deployment guide on the project site before planning an installation. As a reference point, the homepage mentions Apache Gobblin 0.17.0, released in August 2023.
How does Gobblin compare with other ingestion tools?
| Question | Gobblin | Marmaray |
|---|---|---|
| Main purpose | Data integration: ingestion, replication, organisation and lifecycle management | Ingestion into Hadoop and dispersal out of it |
| Transformation | Converters transform schemas and records | No transformation capabilities, as Uber described it in 2018 |
| Status | Top-level Apache project | Repository archived on 5 January 2024, per its GitHub page |
For file formats on the sink side, see our guides to Apache Hudi and data serialisation in Hadoop. The extract, transform and load pattern that Gobblin automates is explained in our ETL glossary entry.
How do AI agents change data ingestion?
An ingestion framework decides which data is available, in what shape and how fresh it is. When agents rely on that data, errors in extraction or conversion become errors in decisions, so quality checks and run state matter more. Agents can help data teams by drafting source configurations, reading job state and quality results, and summarising failures, while people approve schema and sink changes. For the governed data layer behind such work, see ElixirData, XenonStack's Context OS.
What should you do first?
- List the sources you ingest today, with owners, formats and refresh needs.
- Run one source end to end in standalone mode and read the job and task state it writes.
- Mark which quality checks must be mandatory and which can be informational.
- Decide the commit policy for failed tasks before scaling out.
- Confirm the deployment mode against the current Gobblin documentation.
To map one decision your agents make, and the data and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is Apache Gobblin?
Apache Gobblin is a distributed data integration framework that simplifies data ingestion, replication, organisation and lifecycle management for batch and streaming data.
What are the main components of Gobblin?
Source, extractor, converter, quality checker, writer and publisher. The source splits work into work units, the extractor reads records, converters transform them, quality checkers test them, the writer writes to a sink and the publisher makes the data final.
How does Gobblin resume incremental loads?
It persists job and task state after each run, and the next run loads that state to recover details such as watermarks so it knows where to start.
What deployment modes does Gobblin support?
The architecture documentation describes standalone and Hadoop MapReduce modes, and the project homepage lists standalone, MapReduce, cluster or YARN, and cloud modes.
Is Apache Gobblin a top-level Apache project?
Yes. A January 2021 news item on the project homepage says Apache Gobblin became a top-level project.
Ready to put AI agents to work? See an ElixirClaw demo: the agentic OS to build, orchestrate and govern AI agents across your enterprise systems.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE