Key takeaway
- Marmaray is Uber's open-source Hadoop ingestion and dispersal framework on Spark. See its components, how it differs from Gobblin, and its archived status.
Uber Marmaray is an open-source, plug-in-based framework for ingesting data into a Hadoop data lake and dispersing processed data out to other stores, built on Apache Spark. In its 2018 Uber engineering post, the team describes it as a general-purpose ingestion and dispersal framework and library for Apache Hadoop, with the goal of a pipeline from any source to any sink.
This guide is for data engineers and platform owners who meet Marmaray in an existing estate or want to learn from its design. It covers what the framework does, its building blocks, how it compares with Gobblin, and an important status point: the Marmaray repository on GitHub has been archived. If you are comparing ingestion options, our guides to data ingestion and building a data ingestion platform with Apache NiFi give the wider picture.
What is Uber Marmaray and why was it built?
Uber describes two jobs for Marmaray. Ingestion moves raw data from sources such as Kafka, Schemaless and MySQL into the Hadoop data lake, where it is stored in Hive. Dispersal moves processed data from Hadoop out to low-latency online stores such as Cassandra so that it can be served quickly. The post gives Uber Eats restaurant recommendations as an example: dispersing them this way cut lookup time from seconds or minutes to milliseconds, according to Uber.
The motivation was consistency. Instead of many separate pipelines, each with its own handling of schemas and errors, one library supplies the common parts and teams plug in source and sink specifics. That idea carries over to any data lake and analytics platform. Uber also built other data infrastructure around the same period, such as the GPU engine covered in AresDB for real-time analytics.
What is the difference between ingestion and dispersal?
| Ingestion | Dispersal | |
|---|---|---|
| Direction | Source systems into the Hadoop data lake | Processed Hadoop data out to other data stores |
| Example sources or targets (per Uber) | Kafka, Schemaless, MySQL into Hive | Hive-based derived data out to Cassandra |
| Purpose | Reliable, schematised raw and derived datasets | Fast serving of results to applications |
| Pain it removes | Many separate pipelines to maintain | Duplicate and ad hoc dispersal pipelines |
Treating both directions in one framework is what separates Marmaray from tools that stop at the lake.
How does Marmaray work?
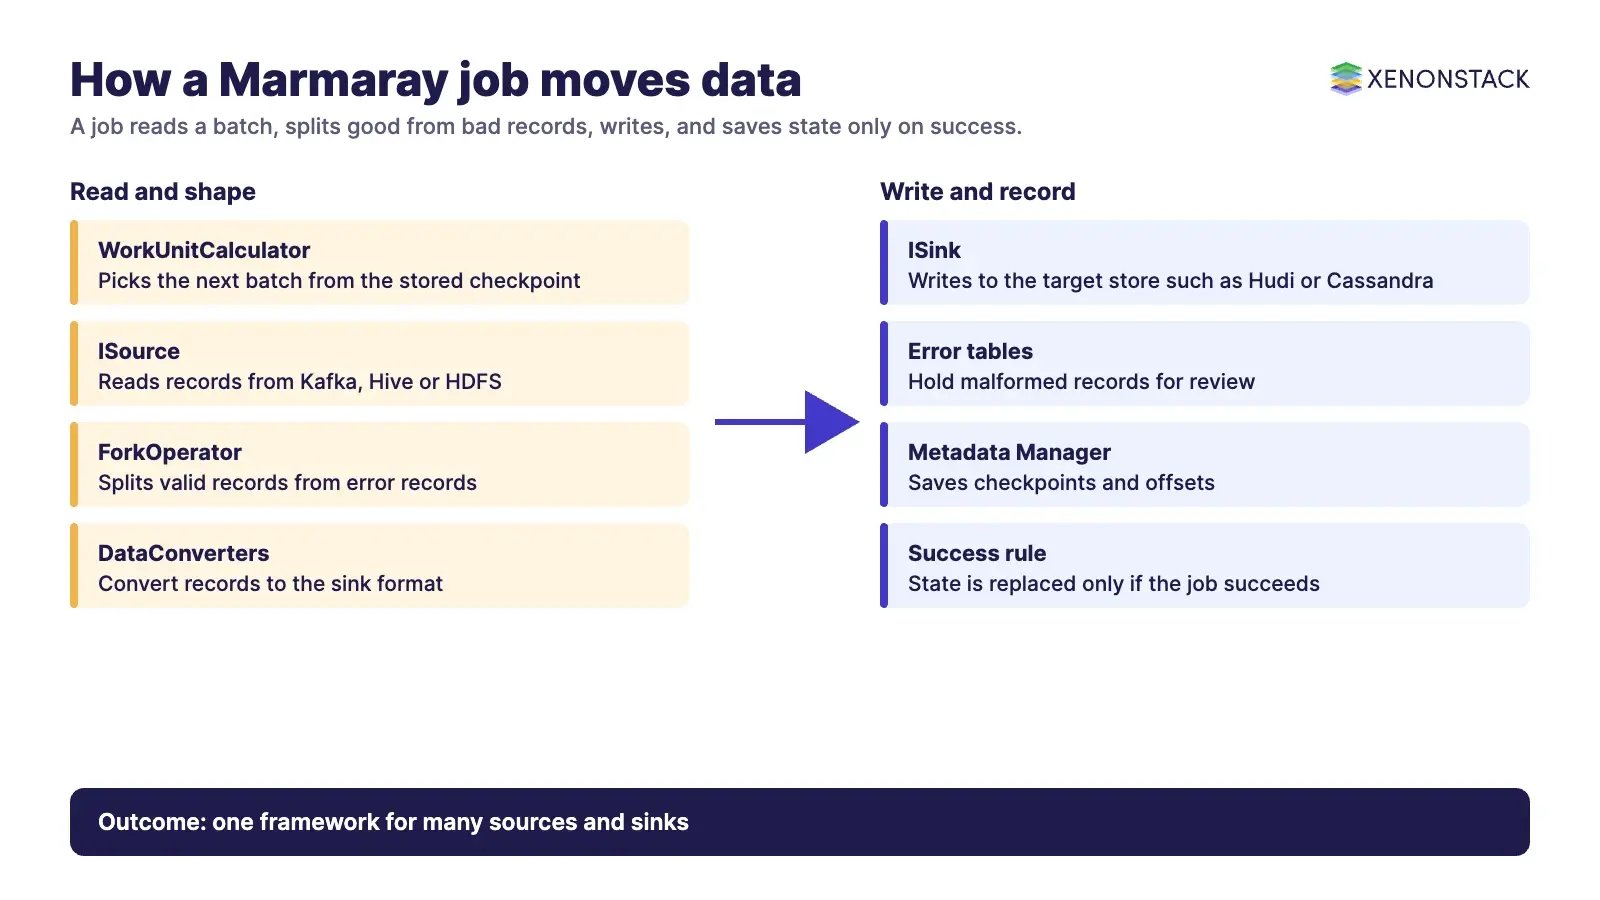
The Uber post lists the main building blocks. Each is pluggable, which is how one job definition can serve many sources and sinks.
| Component | What it does |
|---|---|
| ISource and ISink | Hold what is needed to read from a source (such as topic, offsets or cluster) and write to a sink (such as cluster, table or keys) |
| AvroPayload | Wraps an Avro record with metadata; sources convert into it and sinks convert from it, so any source can feed any sink |
| WorkUnitCalculator | Works out the next mini-batch from the input type and the previously stored checkpoint, and can apply throttling limits |
| DataConverters | Transform records into the target format, can be chained, and send malformed records to error tables |
| ForkOperator and ForkFunction | Split one input stream into several outputs, mainly valid records and error records |
| Metadata Manager | Stores job-level metadata such as checkpoints and Kafka partition offsets, and replaces saved state only if the job succeeds |
In outline, a job reads a bounded batch of raw records from the source, forks them into valid and error records, converts the valid ones to the sink schema, writes them, and saves the new checkpoint only on success. That last rule matters: a failed run does not move the checkpoint, so the next run starts from the last good position.
How does Marmaray compare with Gobblin?
Uber says Marmaray took inspiration from Gobblin, a similar LinkedIn project. The comparison below reflects the 2018 Uber post and the Gobblin architecture documentation; both projects have moved on since, so check current documentation before choosing.
| Question | Marmaray (as Uber described it) | Gobblin (as Uber described it) |
|---|---|---|
| Processing engine | Apache Spark | Hadoop MapReduce |
| Direction | Ingestion into Hadoop and dispersal out of it | Ingestion framework |
| Transformation | No transformation capabilities at the time of writing | Converters transform schemas and records |
| Scale trade-off | Spark met Uber's SLA needs | MapReduce can handle a much larger volume of data than Spark, so a fit at very large scale |
Uber describes Spark as faster because of its in-memory processing. Gobblin has since become a top-level Apache project, and its homepage now describes a distributed data integration framework. Our guide to Apache Gobblin covers its components.
Is Marmaray still maintained?
No. The GitHub repository states that it was archived by the owner on 5 January 2024 and is now read-only. The page names Kafka and Hive or HDFS among its sources, and Hoodie (Hudi) storage and Cassandra among its sinks. Treat Marmaray as a well-documented reference design rather than a base for new work. For table formats on the lake side, see Apache Hudi, Hadoop storage formats and Hadoop to Delta Lake migration if you are modernising an older estate.
How do AI agents change data ingestion and dispersal?
Ingestion pipelines decide what data an agent can see. If a pipeline silently drops or reshapes records, an agent reasons over a distorted picture. Marmaray's habit of routing malformed records to error tables is worth keeping in any design, because it makes data quality visible. Agents can help by drafting pipeline configuration, watching error tables and summarising failures, while people approve changes to schemas and sinks. For the governed data and policy layer behind such work, see ElixirData, XenonStack's Context OS.
What should you do first?
- List every pipeline that moves data into or out of your Hadoop estate, and mark which ones still depend on Marmaray.
- Record, for each, the source, sink, schema owner and how errors are handled.
- Check whether a maintained framework covers each case, and test it on one pipeline first.
- Keep error tables and checkpoint-on-success behaviour in whatever replaces it.
- Decide who approves schema changes before agents or automation are allowed to propose them.
If you want help with a migration, you can talk to a certified big data specialist.
To map one decision your agents make, and the data and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is Uber Marmaray?
Uber Marmaray is an open-source ingestion and dispersal framework and library for Apache Hadoop, built on Apache Spark. It moves data from sources into a Hadoop data lake and from the lake out to other data stores.
What is the difference between Marmaray ingestion and dispersal?
Ingestion brings raw data from sources such as Kafka or MySQL into the Hadoop data lake. Dispersal sends processed data from Hadoop to stores such as Cassandra so that applications can read it quickly.
How is Marmaray different from Gobblin?
As Uber described them in 2018, Marmaray uses Spark and covers both ingestion and dispersal but had no transformation capabilities, while Gobblin used MapReduce and is an ingestion framework with converters for transformation.
Is Uber Marmaray still maintained?
No. Its GitHub repository was archived by the owner on 5 January 2024 and is read-only, so it is best used as a reference design.
What does the Metadata Manager do in Marmaray?
It stores job-level metadata such as checkpoints and Kafka partition offsets, and it replaces the saved state only when the job succeeds.
Ready to put AI agents to work? See an ElixirClaw demo: the agentic OS to build, orchestrate and govern AI agents across your enterprise systems.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE