Key takeaway
- DataOps as a service is a managed way to run pipelines, quality checks and monitoring. See what it includes, how it works and when to buy or build.
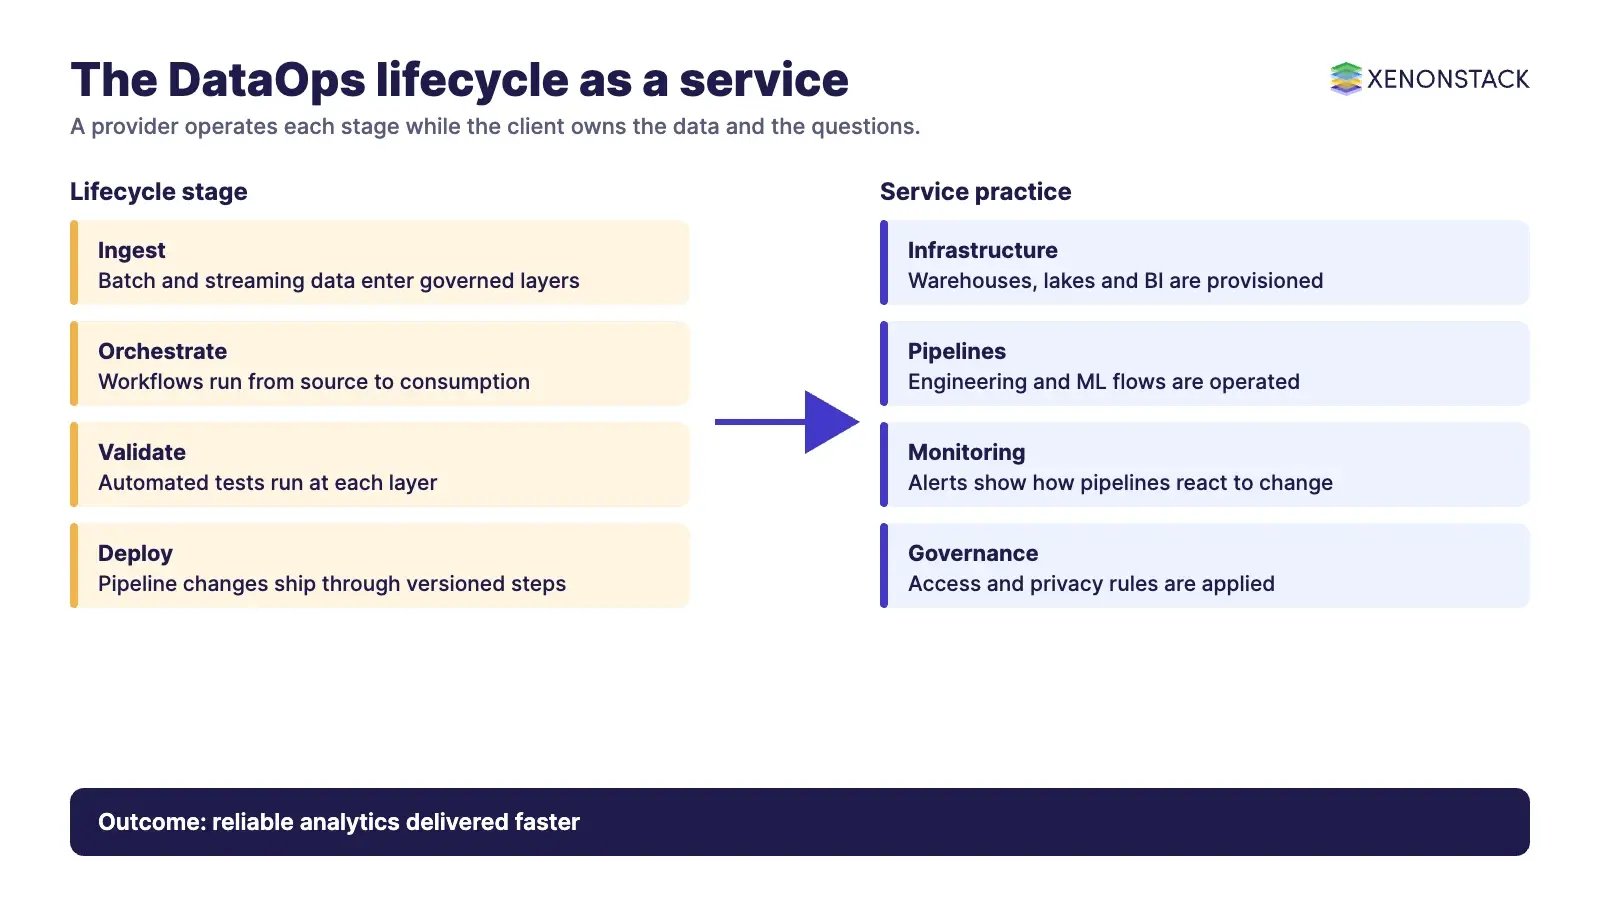
DataOps as a service is a managed arrangement in which a provider runs the pipelines, quality checks, monitoring and platform automation that DataOps practices call for, so a client's data teams can deliver analytics faster and more reliably. The provider operates the machinery; the client keeps ownership of the data and the business questions.
This guide is for data platform owners, analytics leaders and CIOs weighing whether to build DataOps in-house or buy it as a service. It covers what DataOps is, what a service typically includes, the lifecycle and principles behind it, and where AI agents fit. For architecture detail, see our guide to implementing DataOps architecture on AWS, Azure and GCP.
What is DataOps?
IBM describes DataOps as a set of collaborative data management practices designed to speed delivery, maintain quality and foster cross-team alignment. It is modelled on DevOps and underpinned by Agile methods. IBM puts the difference simply: DevOps accelerates software delivery, while DataOps accelerates data delivery by orchestrating pipelines across the data lifecycle.
The DataOps Manifesto states the intent in values: individuals and interactions over processes and tools, working analytics over comprehensive documentation, and cross-functional ownership of operations over siloed responsibilities.
What does DataOps as a service include?
Providers package the same practices as an operated service. The scope differs by vendor, so treat the table as a checklist of questions rather than a promise.
| Service area | What the provider runs | What to ask |
|---|---|---|
| Infrastructure automation | Provisioning for data warehouses, data lakes, BI platforms, data catalogues and machine learning infrastructure | Which clouds and tools are supported, and who owns the accounts? |
| Data engineering pipelines | Batch and real-time pipelines, plus common services such as data quality and cataloguing | How are pipeline changes tested and released? |
| Machine learning pipelines | Pipelines for model data in batch and real time | How are datasets and models versioned? |
| Monitoring and alerting | Dashboards and alerts that show how each pipeline reacts to change | Who is paged, and what is the response expectation? |
| Security and governance | Access controls, privacy and governance built into the platform | Where is data stored, and who can see it? |
How does the DataOps lifecycle work?
IBM lists five lifecycle stages: ingest, orchestrate, validate, deploy and monitor. The manifesto principles map onto them directly. It calls for beginning-to-end orchestration of data, tools, code, environments and team work, for reproducible results through versioning everything including data, and for analytic pipelines with automated detection of abnormalities.
| Stage | Practice | Manifesto principle it reflects |
|---|---|---|
| Ingest | Bring batch and streaming data into governed layers | Orchestrate data, tools, code and environments |
| Orchestrate | Run workflows from source to consumption as one flow | Beginning-to-end orchestration |
| Validate | Run automated quality tests at each layer | Automated detection of abnormalities |
| Deploy | Release pipeline changes through tested, versioned steps | Version everything, including data |
| Monitor | Track performance and quality and alert on drift | Monitor quality and performance |
Test-driven habits carry over from software, and our guide to test-driven development explains the approach that DataOps teams apply to pipelines.
How does a layered data architecture support DataOps?
A proven pattern is to organise the platform in layers, such as raw, enriched, reporting, analytics and sandbox, with each layer serving a distinct purpose and adding value over time. Register data assets at each stage so people can discover them, check quality at every layer, and apply security standards so providers and consumers can access data safely. Workflow orchestration binds the layers together and automates the flow from one to the next. Our data management best practices guide covers the surrounding disciplines, and the Amundsen at Lyft write-up covers a data discovery tool in practice.
Should you buy DataOps as a service or build it?
| Question | Points towards a service | Points towards building |
|---|---|---|
| Skills | Few engineers with pipeline, quality and platform experience | A mature platform team already exists |
| Control | You need results fast and accept shared operations | Policy requires full in-house control of data and tooling |
| Scope | A defined set of platforms and pipelines to operate | Constantly changing tooling that only insiders understand |
| Exit | Contract covers documentation, code ownership and handover | Hard to unpick from a vendor later |
Whichever route you choose, insist on the practices from the manifesto: working analytics delivered continuously, daily interaction between analytic teams and operations, and visible quality checks.
How do AI agents change DataOps?
Pipeline operations produce a steady stream of decisions: whether a failed run should be retried, whether a quality test result blocks a release, who should be told. AI agents can triage failures, read test results, draft fixes and open tickets, but only if they work from governed context about the data, its owners and the policies that apply. XenonStack's ElixirData is XenonStack's Context OS for governed data and decision context. Start by letting agents recommend actions, and keep release approvals with a named person.
What should you do first?
- List your most important pipelines and who owns each one.
- Define the quality tests and alerts each pipeline must have before release.
- Version pipeline code, configuration and data definitions in one place.
- Choose one pipeline for a pilot, whether run in-house or by a provider.
- Review results with the business owners weekly and adjust.
To map one data decision your agents make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is DataOps as a service?
It is a managed arrangement in which a provider operates data pipelines, quality checks, monitoring and platform automation using DataOps practices, while the client keeps ownership of its data.
How is DataOps different from DevOps?
IBM says DevOps accelerates software delivery and DataOps accelerates data delivery, orchestrating pipelines across the data lifecycle. DataOps is modelled on DevOps and shares its emphasis on automation and collaboration.
What are the stages of the DataOps lifecycle?
IBM lists five: ingest, orchestrate, validate, deploy and monitor.
What does the DataOps Manifesto say about quality?
It says analytic pipelines should be built on a foundation capable of automated detection of abnormalities, and it lists monitoring quality and performance among its principles.
When should you build DataOps in-house instead?
Build when you already have a mature platform team or when policy requires full in-house control of data and tooling. Buy when skills are scarce and you need results quickly.
Ready to put AI agents to work? See an ElixirClaw demo: the agentic OS to build, orchestrate and govern AI agents across your enterprise systems.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE