Key takeaway
- DataOps explained: the 18 manifesto principles, framework, tools and a staged adoption path, plus what agents need from your data operations.
DataOps is the practice of running data pipelines the way software teams run releases: version-controlled, tested at every stage, monitored in production and owned by cross-functional teams. It was named in the DataOps Manifesto, which sets out 18 principles for delivering analytics, including "Analytics is code", "Make it reproducible" and "Quality is paramount". For a CTO or Chief Data Officer, the practical test is simple: can a data change go from idea to a trusted, monitored production result repeatably and without heroics?
This guide covers the principles, the framework, the tool categories and a staged adoption path. It also covers the question leaders now ask next: what DataOps must provide before AI agents are allowed to act on enterprise data. For a closer look at the pipeline itself, see data pipelines and why they matter.
What is DataOps?
The DataOps Manifesto describes it as "a better way to develop and deliver analytics". It is not a product. It is a set of working practices that combines Agile delivery, DevOps automation and lean manufacturing thinking, applied to data and analytics. The manifesto was created and is maintained by DataKitchen and is licensed under Creative Commons.
It is easy to confuse DataOps with neighbouring terms. DevOps automates software delivery between development and operations. DataOps extends that discipline to data products, and adds business consumers, data suppliers and data preparers to the loop. CI/CD is one technique inside it, not the whole practice.
Which principles matter most to enterprise leaders?
The manifesto lists 18 principles. Not all carry equal weight for an executive sponsor. The table groups the ones that most often decide whether a programme succeeds, using the manifesto's own principle names.
| Manifesto principle | What it means in practice | Leadership question |
|---|---|---|
| Analytics is code | Pipelines, tests and configuration live in version control and go through review | Can we show who changed a data pipeline, when and why? |
| Make it reproducible | Data, tool code and environment configuration are versioned so results can be repeated | Can we rebuild last quarter's report and get the same answer? |
| Disposable environments | Cheap, isolated, temporary environments that mirror production | Do engineers test against production-like data without touching production? |
| Quality is paramount | Pipelines detect anomalies and security issues automatically and give operators continuous feedback | Where do bad records get stopped? |
| Monitor quality and performance | Continuous monitoring of performance, security and quality to catch unexpected variation | Who is alerted first when data drifts? |
| Reduce heroism | Sustainable teams and processes rather than reliance on individual effort | What breaks if one engineer leaves? |
| Improve cycle times | Minimise the time from a customer need to a repeatable production process | How long does a new data request take end to end? |
The manifesto also adds a bonus principle, "Start with data testing": test data at each stage the way software teams test code. Source: dataopsmanifesto.org.
What does a DataOps framework look like?
A DataOps framework borrows from three disciplines. Agile gives short sprints and regular re-prioritisation against business needs. DevOps gives version control, automated build and deployment, and shared ownership of production. Lean manufacturing gives the idea that a pipeline is a production line: remove waste, stop defects early and measure flow. The manifesto states this directly in "Analytics is manufacturing".
In operating terms, the framework has five layers that most enterprises recognise:
Sources and ingestion: raw data lands with its provenance recorded.
Transformation: modelled, tested and versioned logic turns raw data into data products.
Orchestration: scheduled and event-driven workflows connect the layers and manage dependencies.
Quality, lineage and observability: tests, lineage and monitoring run through every layer.
Access and governance: catalogues, access controls and audit trails decide who and what can use the data.
Which DataOps tools should you evaluate?
Choose tools by the job they do in the framework, not by brand. The table lists widely used open-source and vendor categories, with wording taken from each project's own documentation. Always confirm current versions and licensing on the vendor page before a purchase decision.
| Job in the framework | Example | What its own documentation says | When it fits |
|---|---|---|---|
| Workflow orchestration | Apache Airflow | "An open-source platform for developing, scheduling, and monitoring workflows" (stable docs show version 3.4.0 at the time of reading) | Batch and scheduled pipelines with many dependencies |
| SQL transformation and testing | dbt | Transforms warehouse data into data products; supports data tests, documentation, version control, branching, pull requests and CI/CD | Analytics engineering teams working in the warehouse |
| Data validation | Great Expectations | A Python library (GX Core) for data validation using Expectations | Explicit, code-defined quality checks in Python pipelines |
| Lineage standard | OpenLineage | An open framework for collecting lineage metadata about jobs as they run; hosted by LF AI & Data, graduate project | Vendor-neutral lineage across orchestrators and engines |
| Cloud-native pipeline kit | AWS DataOps Development Kit | Open-source framework on the AWS CDK for data workflows; the repository is marked archived and no longer maintained | Reference only; plan another route for new work |
Where a vendor's status or features cannot be confirmed on its own site, treat any comparison as unverified and run a proof of concept against your own data. For related architecture choices across clouds, see Implementing DataOps architecture in AWS, Azure and GCP.
How do you implement DataOps step by step?
| Stage | What to do | Exit test |
|---|---|---|
| 1. Baseline | List critical data products, owners, consumers and current failure points | Every critical product has a named owner |
| 2. Version everything | Put pipeline code, tests and configuration in version control with review | No production change without a pull request |
| 3. Test data and code | Add automated checks for completeness, accuracy, consistency and schema at each stage | Failed checks stop the pipeline before consumers see data |
| 4. Automate delivery | Use CI/CD for pipeline changes and disposable test environments | Changes deploy repeatably, with rollback |
| 5. Monitor and trace | Add monitoring, alerting and lineage across layers | An incident can be traced to its source in minutes, not days |
| 6. Govern and scale | Add catalogue, access policy and audit evidence, then self-service access | Business users find and use governed data without tickets |
Start with one or two high-value data products rather than the whole estate. The manifesto's "Reduce heroism" and "Reuse" principles argue for repeatable patterns that later teams can copy.
Where does DataOps deliver value in the enterprise?
| Use case | How DataOps helps | What to watch |
|---|---|---|
| Real-time analytics and BI | Automated ingestion, cleaning and delivery keep dashboards fresh | Freshness targets must be defined per data product |
| ML and AI data pipelines | Reproducible feature and training data, with versioned code and data | Training data lineage should be recorded |
| Continuous data quality | Tests at each stage catch drift before it reaches reports or models | Thresholds need business owners, not just engineers |
| Compliance and governance | Lineage, access control and audit logs built into the pipeline | Regulatory obligations come from official texts, not from tool vendors |
| Cloud data migration | Repeatable pipelines with automated validation between source and target | Validate reconciliation rules before cutover |
| Self-service analytics | Catalogues, governed access and curated data products | Self-service without governance multiplies inconsistent metrics |
For the governance and metadata side of these use cases, see the OpenMetadata platform guide for data leaders, data lineage tools and best practices and the five pillars of data observability.
How is agentic AI changing DataOps?
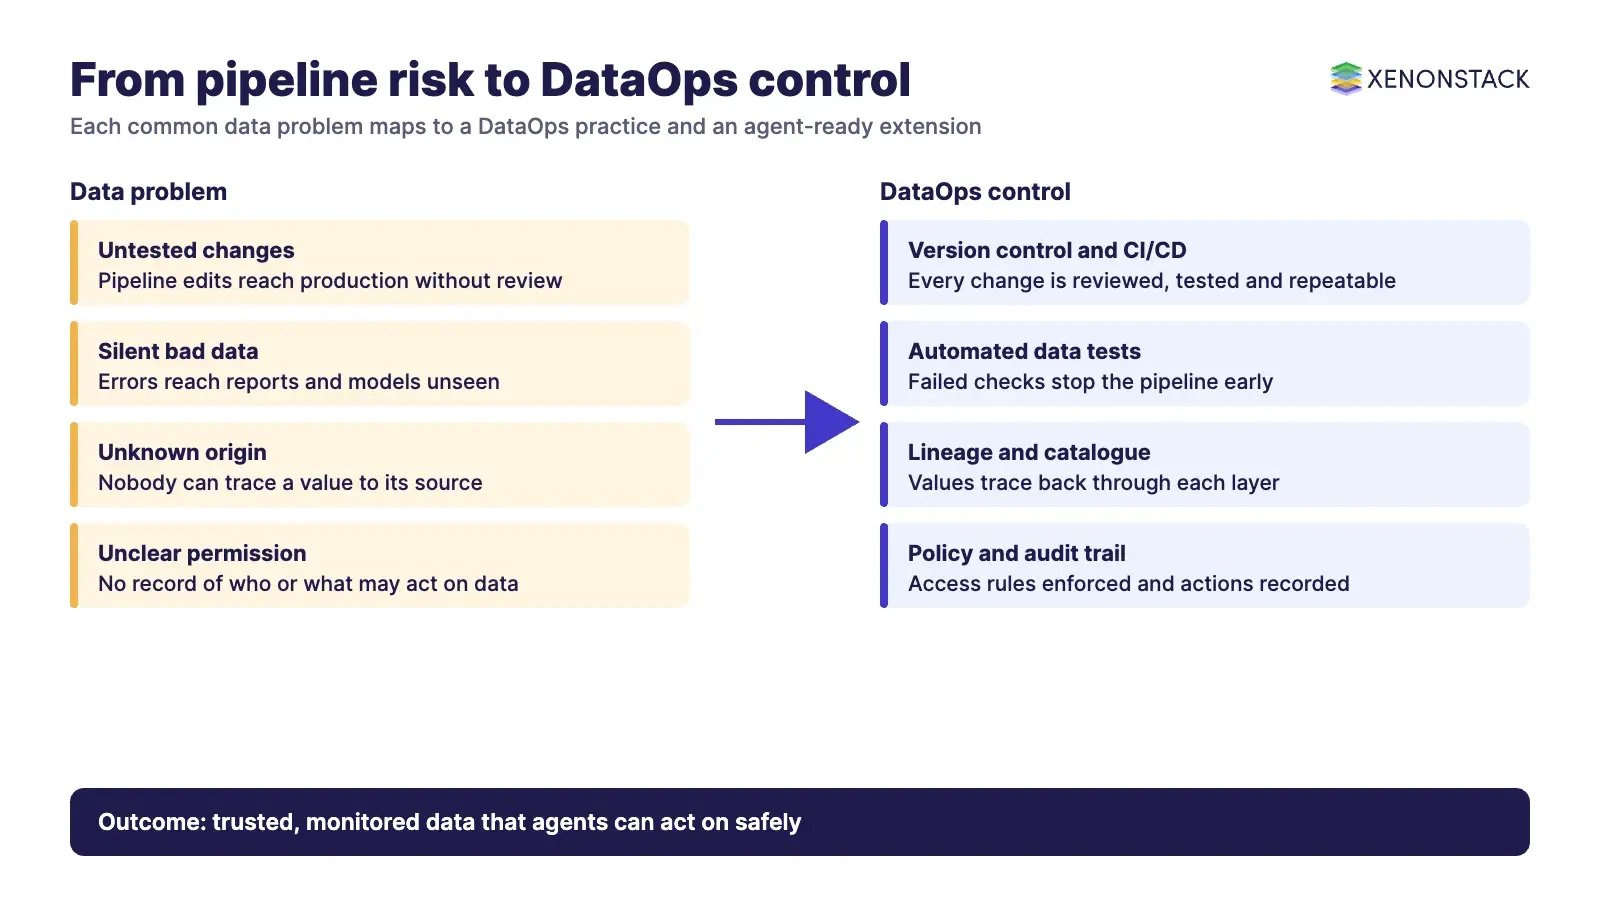
AI agents now read, transform and sometimes write enterprise data. That raises the bar for DataOps: an agent needs the same things a human pipeline owner needs, which are tested inputs, known lineage, policy it cannot step outside, and a record of what it did and why. Teams therefore extend DataOps with governed context and decision traces. The questions to settle before an agent touches a pipeline are below.
| Question | DataOps control | Agent-ready extension |
|---|---|---|
| Is the data it reads trustworthy? | Automated tests and quality monitoring | Agents act only on data products that pass quality gates |
| What changed, and who approved it? | Version control and CI/CD review | Agent-proposed changes follow the same review path |
| Where did this value come from? | Lineage and catalogue | Lineage is available to the agent as context |
| Is the action allowed? | Access control and policy | Policy is versioned and enforced at action time |
| Can we explain it later? | Audit logs | Decision traces record inputs, policy and outcome |
XenonStack describes its own approach in DataOps Reimagined and in Agentic AI for data quality: what agents can fix safely. ElixirData keeps governed context, versioned policy and decision traces in one decision layer above AI agents, and AgentGRC keeps autonomous agent actions inside policy, with the audit trail risk teams need. ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control.
What are the trade-offs and when is DataOps not the answer?
Small, stable data estates: a handful of reports from one source rarely justify a full framework. Version control and a few tests may be enough.
Tooling before ownership: buying orchestration without naming data product owners moves the problem rather than solving it.
Over-testing: checks nobody acts on become noise. Tie each alert to an owner and a response.
Cost and complexity: disposable environments and continuous monitoring consume compute. Budget for them and review usage regularly.
Governance gaps: DataOps speeds delivery. Without access policy and audit evidence, it speeds delivery of ungoverned data.
To map one data decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is DataOps in simple terms?
DataOps is a set of practices for delivering analytics and data products repeatably, using version control, automated testing, continuous monitoring and cross-functional teams. The DataOps Manifesto describes it as a better way to develop and deliver analytics.
How is DataOps different from DevOps?
DevOps automates software delivery between development and operations. DataOps applies similar ideas to data and analytics, and also involves data suppliers, preparers and business consumers. It adds data-specific concerns such as data quality tests, lineage and reproducible datasets.
What are the main principles of DataOps?
The DataOps Manifesto lists 18 principles, including "Analytics is code", "Make it reproducible", "Disposable environments", "Quality is paramount", "Monitor quality and performance" and "Improve cycle times", plus a bonus principle, "Start with data testing".
Which tools are used for DataOps?
Teams combine tools by job: orchestration such as Apache Airflow, transformation and testing such as dbt, validation such as Great Expectations, and lineage standards such as OpenLineage. Check each vendor's current documentation before choosing.
Does DataOps matter for AI agents?
Yes. Agents need tested data, known lineage, enforced policy and an audit trail of their actions. DataOps controls such as quality gates, version control and lineage provide the base, and governed context and decision traces extend it for agent use.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE