Key takeaway
- GraphQL for enterprise teams: the spec, Apollo Server and Federation, GraphQL vs REST vs gRPC, security limits, caching, governance and MCP for AI agents.
What is GraphQL?
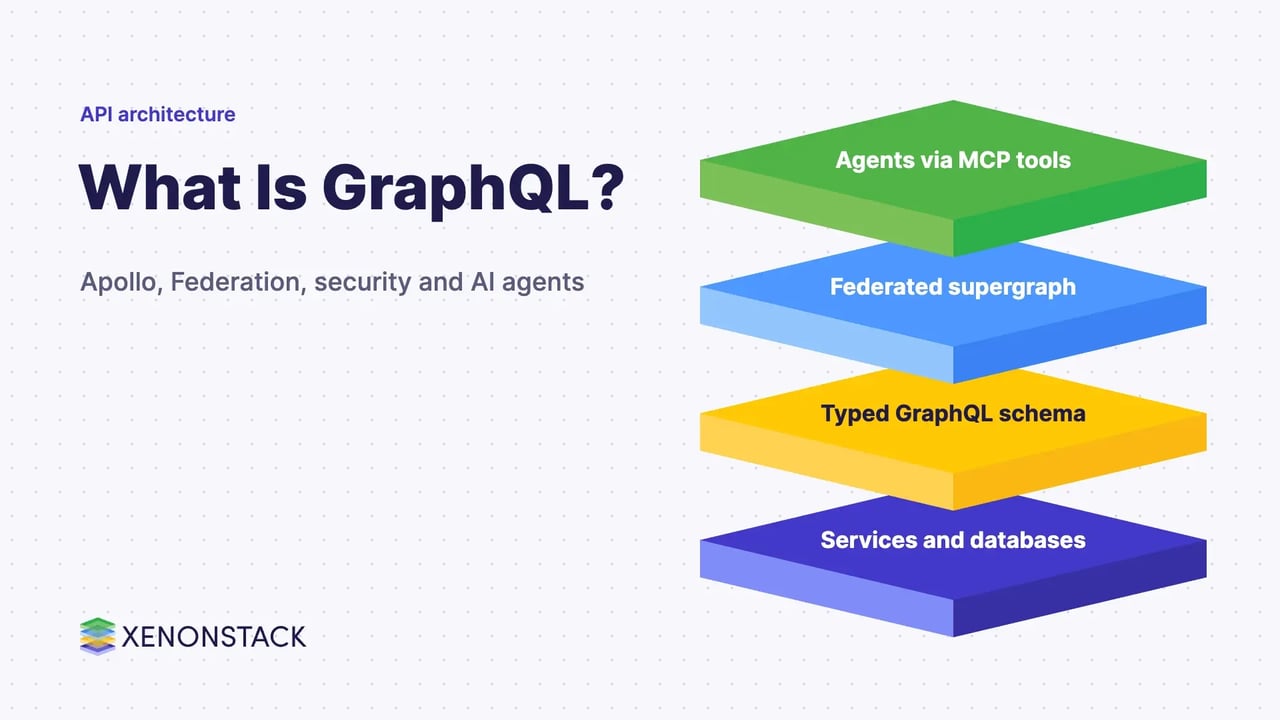
GraphQL is a query language for APIs and a runtime for fulfilling those queries with your existing data, according to graphql.org. The client states exactly which fields it needs, the server returns that shape, and a strongly typed schema describes what is possible.
For enterprise teams the practical question is where it fits: as a single graph over many services (Apollo Federation), as a client-driven layer next to REST and gRPC, and increasingly as a governed tool surface for AI agents through MCP. This guide covers each, with the security and governance controls that matter. For the transport side, see our guide to GraphQL subscriptions over WebSocket.
How does GraphQL work?
A GraphQL service publishes a schema of types and fields. Clients send operations in three kinds: queries (read), mutations (write) and subscriptions (events). The server validates each operation against the schema, then runs resolver functions that fetch each field from a database, service or REST API. The response carries data, errors and optional extensions. The same graphql.org Learn section covers schemas, validation, execution, response and introspection in order.
query {
  customer(id: "c-42") {
    name
    orders(first: 3) { id status }
  }
}
One request returns the customer and three orders, where an endpoint-per-resource REST design would often need two calls. The GraphQL specification is published at spec.graphql.org; on the date we read it (13 November 2026) it listed a September 2026 release as the latest, plus a working draft.
GraphQL vs REST vs gRPC: which should you choose?
| Question | GraphQL | REST | gRPC |
|---|---|---|---|
| Contract | Typed schema, introspectable | Resource URLs, often described by OpenAPI | Protocol Buffers (.proto) by default, per grpc.io |
| Best fit | Many client types needing different shapes of the same data; aggregating services | Simple resources, public APIs, HTTP caching | Service-to-service calls with generated clients |
| Main cost | Query cost control, caching and schema governance | Over-fetching and multiple round trips | Less natural for browsers and public consumers |
| When not to use | A small, stable, resource-shaped API with one client | Highly variable client data needs | Public APIs for unknown third parties |
The three are not exclusive. A common enterprise pattern is gRPC or REST between services, with GraphQL as the client-facing graph on top. For API test practice across all three, see API testing workflow, tools and best practices.
What are Apollo Server, Apollo Client and Apollo Federation?
Apollo is the most widely used commercial ecosystem around GraphQL. The older "Apollo Engine" service named in earlier guides, including this one, has been succeeded by Apollo's current platform, so check Apollo's documentation for current product names before you plan.
- Apollo Server: listed on Apollo's site as an open source product for building GraphQL servers with Node.js.
- Apollo Client: a client library for connecting GraphQL data to user interfaces, with a normalised cache.
- Apollo Federation: "enables you to declaratively combine multiple APIs into a single federated GraphQL API", according to Apollo's docs. The combined graph is the supergraph, its constituent APIs are subgraphs, and clients call a single entry point, the router.
Federation suits organisations where several teams own different parts of the domain. Each team owns a subgraph, and the router plans each request across them. It adds a platform component to run and a composition step to govern, so it is not worth it for one team and one service.
How do you secure a GraphQL API?
A flexible query language means one request can be expensive. The graphql.org security guidance lists these controls:
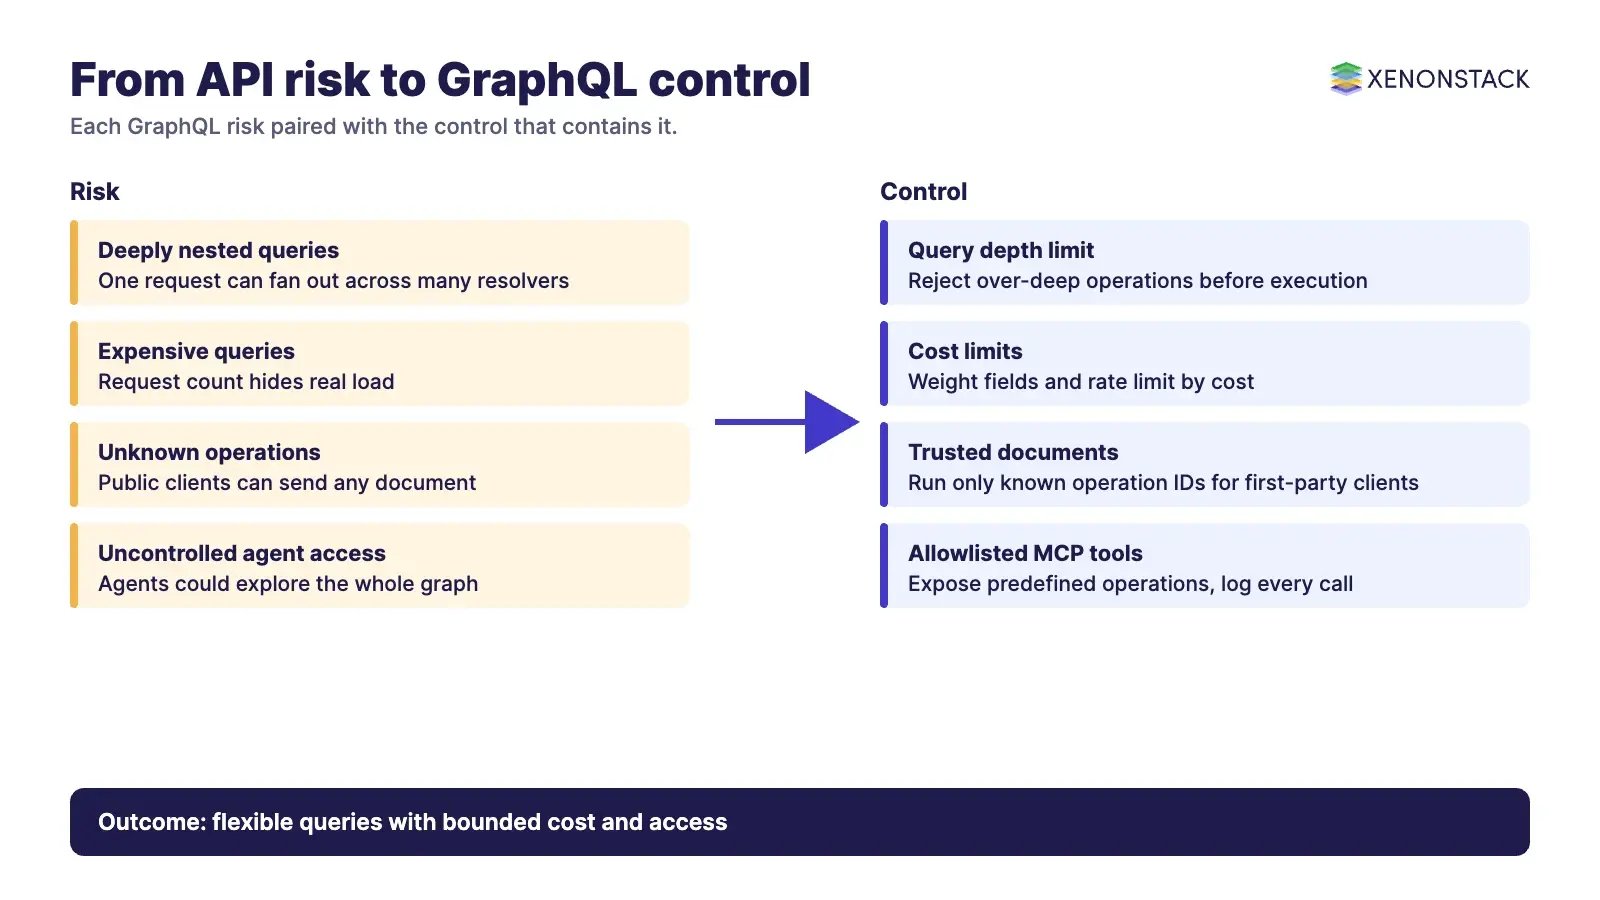
| Control | What it does | Note from graphql.org |
|---|---|---|
| Query depth limit | Rejects operations nested beyond a maximum before execution | Use a smaller limit for nested lists, which can grow data exponentially |
| Cost limits | Assigns weights to fields and rejects requests over a budget | A community cost directive draft exists |
| Rate limiting | Limits by cost, not only by request count | Apply in the business logic layer |
| Trusted documents (persisted queries) | Server runs only known operation IDs | For first-party clients only, not public APIs |
| Introspection | Schema discovery | May be disabled outside development, but this is obscurity, not protection |
Authorisation still belongs in the resolvers or a policy layer; none of the controls above replaces it.
How does caching work in GraphQL?
REST can use the URL as a cache key. GraphQL has no equivalent, so graphql.org recommends a globally unique id field on object types, which clients such as Apollo Client use to build a normalised cache. Plan caching explicitly: Red Hat's overview lists more complex caching among the drawbacks for corporate use.
How do you govern a GraphQL schema across teams?
The graphql.org best-practice lessons include schema governance: ownership models, governance tooling, schema review and change management. In practice, name an owner for each type, review changes in pull requests, check each change against known client operations before merging, and publish deprecations instead of removing fields. GraphQL is described there as versionless, which makes this change discipline the substitute for API version numbers.
Can AI agents use GraphQL? GraphQL and MCP
Agents need typed, bounded access to enterprise data, and a schema already provides that. Apollo MCP Server, per its docs, exposes GraphQL operations to AI clients as MCP tools, generated from operation files, persisted query manifests or schema introspection. The graph keeps enforcing its own authentication and authorisation.
The governance choice is how open the tool surface is. Predefined persisted operations give an allowlist of what an agent may call; introspection lets it explore the graph. For regulated data, start with the allowlist, log every call and keep a human approval step on mutations. ElixirData keeps governed context, versioned policy and decision traces in one decision layer above AI agents, and AgentGRC keeps autonomous agent actions inside policy, with the audit trail risk teams need. See also our guide to agentic workflows.
What is a sensible adoption sequence?
| Step | Action | Exit check |
|---|---|---|
| 1 | One graph over one or two existing services, for one client | Clients no longer chain calls for common screens |
| 2 | Add depth, cost and rate limits, and trusted documents for first-party clients | Expensive queries are rejected in test |
| 3 | Name schema owners and add review and change checks | No field removed without a client check |
| 4 | Federate only when several teams own the domain | Subgraph teams ship independently |
| 5 | Expose an allowlisted operation set to agents via MCP | Every agent call is logged and attributable |
To map one decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is GraphQL in simple terms?
A query language and runtime for APIs where the client asks for exactly the fields it needs from a typed schema.
Is GraphQL better than REST?
Not always. It suits varied client needs and aggregation; REST suits simple resources and URL-based HTTP caching.
What is Apollo Federation?
A way to combine multiple GraphQL APIs (subgraphs) into one supergraph, queried through a single router, according to Apollo's docs.
How do you stop expensive GraphQL queries?
Use depth limits, cost limits, cost-aware rate limiting and, for first-party clients, trusted documents, as described on graphql.org.
Can AI agents call a GraphQL API?
Yes. Apollo MCP Server exposes GraphQL operations as MCP tools; keep the operation set allowlisted and the API's own authorisation in force.
Ready to put AI agents to work? See an ElixirClaw demo: the agentic OS to build, orchestrate and govern AI agents across your enterprise systems.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE