

Key takeaway
- Golang unit testing in 2027: TDD with go test, table-driven t.Run subtests, native fuzzing, fakes over mocks, CI flags and compiled, working Go examples.
Golang unit testing needs no third-party framework. The go test command and the standard testing package cover unit tests, table-driven subtests with t.Run, benchmarks, runnable examples and, since Go 1.18, native fuzzing. Test-driven development (TDD) in Go is the same red, green, refactor loop as anywhere else: write a failing TestXxx function in a _test.go file, write the least code that passes, then refactor with the suite green.
This is the Go companion to our guide to test-driven development, which covers the method, TDD against BDD and ATDD, and AI coding agents. Here we cover the Go toolchain as it stands in November 2026 (Go 1.27), a worked example we compiled and ran, fuzzing, fakes instead of heavy mocks, the go test flags worth putting in CI, and an adoption sequence for engineering leaders. Python teams can read our TDD in Python guide.
What does Go's built-in testing toolkit cover going into 2027?
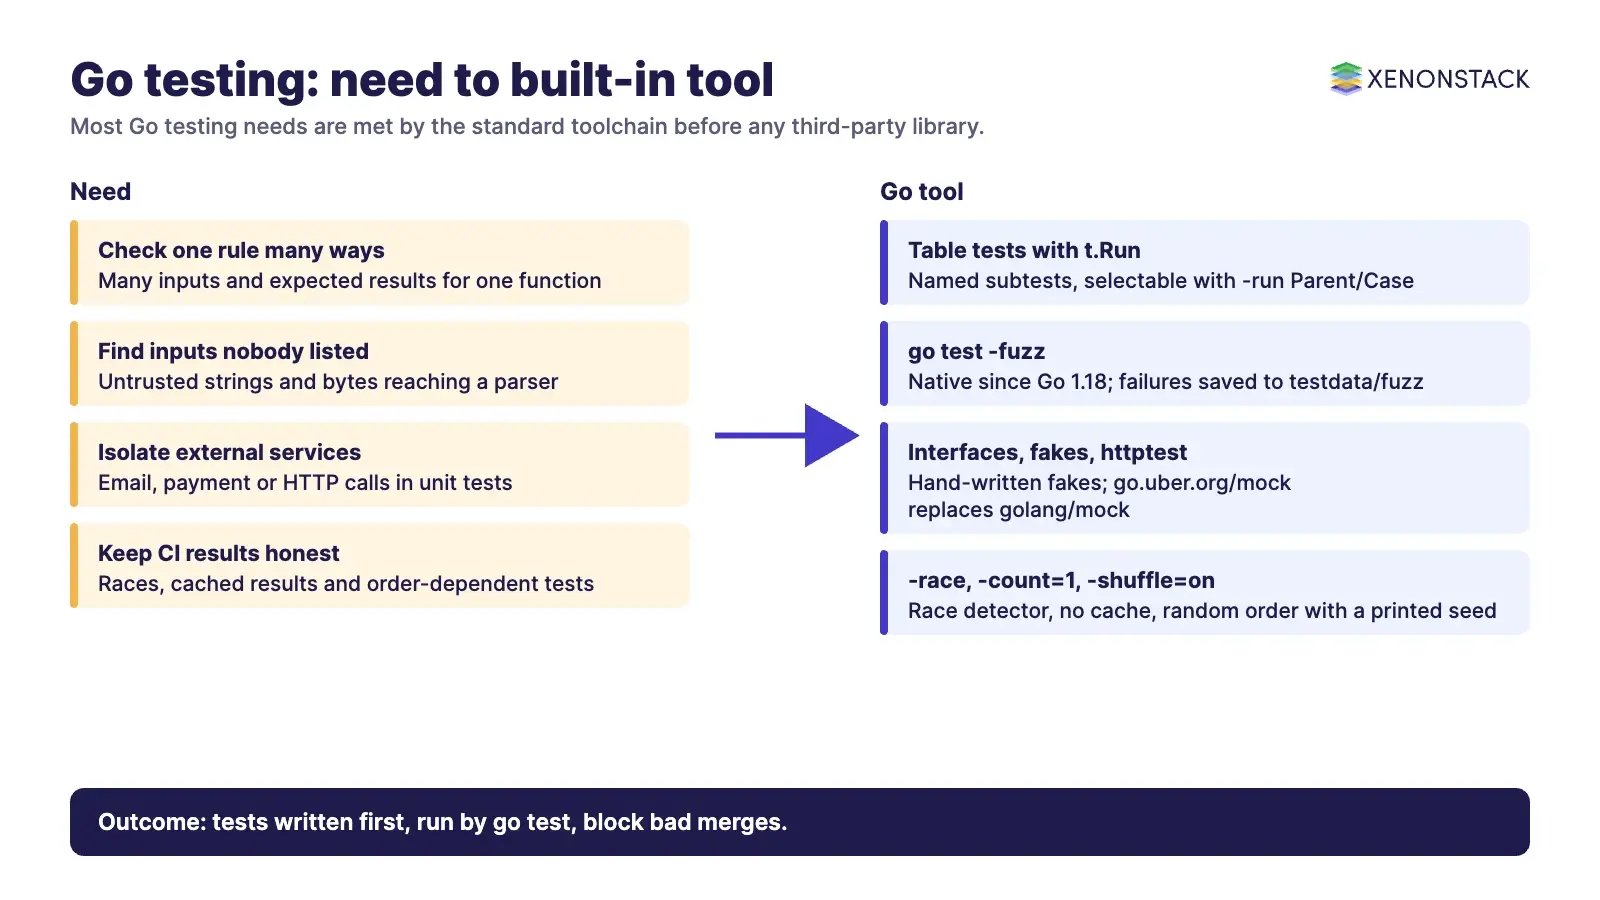
Most of what other ecosystems install as plugins ships with Go. The table lists each feature, when it fits and the Go version that added it, from the testing package documentation and the Go release history, read on 12 November 2026.
| Feature | What it does | When it fits | Status |
|---|---|---|---|
func TestXxx(t *testing.T) | Unit test in a _test.go file; excluded from normal builds | Every package | Core since Go 1 |
t.Run subtests | Named cases with their own pass or fail, selectable with -run Parent/Case | Table-driven tests of one rule | Stable |
t.Parallel, t.Cleanup, t.TempDir, t.Setenv | Concurrency, teardown, temporary folders and environment that are restored after the test | Isolating tests that touch files or settings | Stable; t.Setenv cannot be used in parallel tests |
func FuzzXxx(f *testing.F) | Coverage-guided fuzzing with a seed corpus | Parsers, decoders, validation, anything that takes untrusted input | Native since Go 1.18 |
func BenchmarkXxx(b *testing.B) with b.Loop() | Benchmarks; setup before the loop is not timed | Hot paths and performance regressions | b.Loop added in Go 1.24; recommended for new benchmarks |
func ExampleXxx() | Documentation example checked against its // Output: comment | Public APIs of shared libraries | Stable |
t.Context() | A context cancelled just before cleanup runs | Code that takes a context.Context | Added in Go 1.24 |
testing/synctest | Runs concurrent code in a bubble with a fake clock | Timeouts, retries and goroutine coordination | synctest.Test added in Go 1.25 |
t.ArtifactDir() | A directory for files a test produces | Keeping logs or snapshots from CI runs | Added in Go 1.26 |
Go follows a support policy where each major release is supported until two newer major releases exist. With Go 1.26 and 1.27 out, Go 1.24 is no longer supported, so check your go directive in go.mod before relying on the newer methods.
How do you run red, green, refactor in Go?
Our example is a small ledger package that turns an amount such as "12.34" into integer cents, the safe way to hold money. Set it up as a module with go mod init example.com/ledger, which creates go.mod; the GOPATH src layout shown in older tutorials is not needed. Files sit side by side: money/money.go and money/money_test.go.
Red: write one failing test
package money

import "testing"

func TestParseCentsTwoDecimals(t *testing.T) {
	got, err := ParseCents("12.34")
	if err != nil {
		t.Fatalf("unexpected error: %v", err)
	}
	if got != 1234 {
		t.Errorf("ParseCents(\"12.34\") = %d, want 1234", got)
	}
}
Run go test ./money. The build fails with undefined: ParseCents. That is the red step: the test exists, it can fail, and a later pass means something.
Green: write the smallest code that passes
package money

import (
	"strconv"
	"strings"
)

func ParseCents(s string) (int64, error) {
	whole, frac, _ := strings.Cut(s, ".")
	w, err := strconv.ParseInt(whole, 10, 64)
	if err != nil {
		return 0, err
	}
	f, err := strconv.ParseInt(frac, 10, 64)
	if err != nil {
		return 0, err
	}
	return w*100 + f, nil
}
The test passes. This version still has gaps: "12" fails because there is no decimal part, "12.3" returns 1203 instead of an error, and "-5.00" is accepted although amounts in this ledger must not carry a sign. Each gap becomes a test before it becomes code.
Refactor: grow the rule as a table
The next tests go into one table, and the implementation is tightened until all of them pass:
// Package money converts between "12.34" strings and integer cents.
package money

import (
	"errors"
	"fmt"
	"strconv"
	"strings"
)

// ErrInvalid is returned for any string that is not a plain amount.
var ErrInvalid = errors.New("invalid amount")

// ParseCents turns "12.34" into 1234. It rejects signs, spaces and
// anything other than two decimal places.
func ParseCents(s string) (int64, error) {
	whole, frac, found := strings.Cut(s, ".")
	if whole == "" || !digits(whole) || (found && (len(frac) != 2 || !digits(frac))) {
		return 0, ErrInvalid
	}
	w, err := strconv.ParseInt(whole, 10, 64)
	if err != nil || w > (1<<63-1)/100-1 {
		return 0, ErrInvalid
	}
	var f int64
	if found {
		f, _ = strconv.ParseInt(frac, 10, 64)
	}
	return w*100 + f, nil
}

// FormatCents turns 1234 into "12.34".
func FormatCents(c int64) string {
	return fmt.Sprintf("%d.%02d", c/100, c%100)
}

func digits(s string) bool {
	for _, r := range s {
		if r < '0' || r > '9' {
			return false
		}
	}
	return true
}
We compiled and ran every listing in this post with Go 1.24.7, the oldest release that has every feature used here, including b.Loop and t.Context. go vet was clean, go test -race -cover passed with 93.3% statement coverage on the money package, and a 15-second fuzz run found no failures.
How do table-driven tests and t.Run keep Go suites readable?
A table-driven test lists each case as data, with a name, the input and the expected result, and runs the same check over every row. The Go wiki recommends wrapping each row in t.Run so a failure names the exact case. Here is the table that drove the refactor above:
package money

import (
	"errors"
	"testing"
)

func TestParseCents(t *testing.T) {
	tests := []struct {
		name    string
		in      string
		want    int64
		wantErr error
	}{
		{"whole amount", "12", 1200, nil},
		{"two decimals", "12.34", 1234, nil},
		{"zero", "0.00", 0, nil},
		{"one decimal", "12.3", 0, ErrInvalid},
		{"negative", "-5.00", 0, ErrInvalid},
		{"plus sign", "+5.00", 0, ErrInvalid},
		{"letters", "ten", 0, ErrInvalid},
		{"empty", "", 0, ErrInvalid},
	}
	for _, tc := range tests {
		t.Run(tc.name, func(t *testing.T) {
			t.Parallel()
			got, err := ParseCents(tc.in)
			if !errors.Is(err, tc.wantErr) {
				t.Fatalf("ParseCents(%q) error = %v, want %v", tc.in, err, tc.wantErr)
			}
			if got != tc.want {
				t.Errorf("ParseCents(%q) = %d, want %d", tc.in, got, tc.want)
			}
		})
	}
}- Names matter:
go test -run "TestParseCents/negative"runs one case, because-runsplits its pattern on slashes, one level per subtest. - Errorf or Fatalf:
t.Errorfrecords a failure and carries on, which can reveal a pattern across cases. Uset.Fatalfwhen the rest of the check makes no sense, as with a wrong error above. - Parallel cases:
t.Parallel()inside the subtest runs rows concurrently. From Go 1.22 each loop iteration has its own variable, so the oldtc := tccopy is no longer required. - Compare errors with
errors.Is, not by matching message text, so wrapped errors still match.
How does native fuzzing find the inputs you did not think of?
A table only checks the inputs someone thought of. A fuzz test states a property that must hold for every input and lets the engine search for a counter-example. Ours says: any string ParseCents accepts must survive a round trip through FormatCents.
func FuzzParseCents(f *testing.F) {
	for _, seed := range []string{"0", "12.34", "999999.99", "1.5", "-1"} {
		f.Add(seed)
	}
	f.Fuzz(func(t *testing.T, s string) {
		c, err := ParseCents(s)
		if err != nil {
			return // invalid input is allowed; a panic is not
		}
		back, err := ParseCents(FormatCents(c))
		if err != nil || back != c {
			t.Errorf("round trip %q -> %d -> %q -> %d (%v)", s, c, FormatCents(c), back, err)
		}
	})
}
go test ./money # runs the seed corpus as ordinary tests
go test -run=NONE -fuzz=FuzzParseCents -fuzztime=30s ./moneyFacts from the Go fuzzing documentation that shape how teams use it:
- Fuzz arguments are limited to
string,[]byte, the integer and unsigned types,float32,float64andbool. -fuzzmust match exactly one fuzz test in one package, and fuzzing runs until stopped unless-fuzztimeis set.- A failing input is minimised and written to
testdata/fuzz/FuzzXxx/. Commit it: every latergo testreplays it as a regression test. - Coverage instrumentation, which guides the search, is available on AMD64 and ARM64. Run long fuzz jobs on those machines, on a schedule rather than on every pull request.
How should Go teams handle dependencies without heavy mocking?
Go interfaces are satisfied implicitly, so the usual pattern is to define a small interface where the code uses a dependency and pass a hand-written fake in tests. The test then checks behaviour you own, not the internals of an email or payment service.
// Package alert warns when an account balance falls below a threshold.
package alert

import (
	"context"
	"fmt"
)

// Notifier is the boundary: email, chat or a webhook in production.
type Notifier interface {
	Notify(ctx context.Context, msg string) error
}

// CheckBalance sends one alert when cents is below threshold.
func CheckBalance(ctx context.Context, n Notifier, cents, threshold int64) (bool, error) {
	if cents >= threshold {
		return false, nil
	}
	if err := n.Notify(ctx, fmt.Sprintf("balance low: %d cents", cents)); err != nil {
		return false, fmt.Errorf("notify: %w", err)
	}
	return true, nil
}
package alert
import (
"context"
"testing"
)
// fakeNotifier records messages instead of sending them.
type fakeNotifier struct{ sent []string }
func (f *fakeNotifier) Notify(_ context.Context, msg string) error {
f.sent = append(f.sent, msg)
return nil
}
func TestCheckBalanceSendsOneAlert(t *testing.T) {
fake := &fakeNotifier{}
sent, err := CheckBalance(t.Context(), fake, 5000, 10000)
if err != nil || !sent {
t.Fatalf("CheckBalance() = %v, %v; want true, nil", sent, err)
}
if len(fake.sent) != 1 {
t.Errorf("got %d alerts, want 1", len(fake.sent))
}
}- HTTP: the standard
net/http/httptestpackage givesNewServer, a real server on a loopback address, andNewRecorder, which captures a handler's response. Prefer these to mocking an HTTP client. - Generated mocks: the original
golang/mockrepository was archived on 27 June 2023 and points to the maintained fork atgo.uber.org/mock. Move anymockgenusage there. - Assertions: testify adds
assert,require,mockandsuitepackages and is maintained at v1. It is optional; the standard library is enough for most teams. - Databases: keep queries behind an interface for unit tests, and test the real schema separately, as covered in our guide to database unit testing.
Which go test flags belong in continuous integration?
These come from the go command documentation. Note that go test already runs a high-confidence subset of go vet checks and will not run tests if they fail.
| Flag | What it does | Use it for |
|---|---|---|
-race | Builds with the data race detector, on the platforms it supports | Every CI run of packages with goroutines |
-count=1 | Runs each test once and is the idiomatic way to bypass the test cache | CI jobs that must not report cached results |
-cover, -coverprofile=cover.out | Coverage percentage and a profile for go tool cover | Trend reporting, not a hard gate |
-shuffle=on | Randomises test order and prints the seed | Finding tests that depend on each other |
-run, -skip | Select tests by pattern, including subtest paths | Reproducing one failing case |
-short | Asks long tests to cut their run time (tests check testing.Short()) | Fast pre-merge runs |
-bench=. -benchmem | Runs benchmarks and reports allocations | Performance checks on hot paths |
-json | Machine-readable test output | Feeding results into dashboards or agents |
What has changed since the older Go testing approach?
| Older practice | Current practice | Why it matters |
|---|---|---|
GOPATH src folders | Modules with go.mod | How Go code is organised in the official "How to Write Go Code" guide |
| Plain loops over test cases | Table rows inside t.Run subtests | Named, selectable and parallel cases |
| External fuzzers | Native go test -fuzz | Built in since Go 1.18, with a committed regression corpus |
for i := 0; i < b.N; i++ with b.ResetTimer | for b.Loop() | Setup is excluded from timing without extra calls (Go 1.24) |
context.Background() in tests | t.Context() | Cancelled automatically when the test ends (Go 1.24) |
| Real sleeps in concurrency tests | testing/synctest | Fake clock, so tests are fast and deterministic (Go 1.25) |
github.com/golang/mock | go.uber.org/mock | The original repository is archived |
| Tests written by people only | Tests as the specification for AI coding agents | Agents need a failing test to aim at; people must still own and review it |
The original version of this article showed a test that did not compile (total: = Sum(5.5, 5)) and passed a float to an int function. Every listing above has been compiled and run. Inside XenonStack, our engineering teams now practise agentic TDD on platform work: a shared skills file defines the steps, the workflow was proven on one repository before being extended to others, and coverage targets were set aside in favour of tests written before the code. The point we would pass on is the order: test first, one codebase first.
What are the governance, cost and trade-offs?
- Cost: the first features take longer while the habit forms, and fuzzing uses CPU time. The return is a regression suite that runs in seconds and a corpus of failures that can never quietly return.
- Governance: treat tests as the specification. Require review of any change that deletes an assertion, adds
t.Skip, edits an expected value or deletes a fuzz corpus file, whether a person or an agent wrote it. Where agents produce or change code, AgentQA continuously tests AI agent outputs and workflows, and ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control. For sprint-level delivery, Agent Scrum automates Scrum practices on ElixirClaw. - Security: fuzz every function that parses untrusted input. Never put real credentials or customer data in
testdata. - When not to use strict TDD: spikes you will throw away, generated code, and thin wrappers whose behaviour is the library's. Do not chase a coverage number; a high percentage of shallow tests protects little.
What adoption sequence works for a Go engineering organisation?
- Step 1: set the
goversion ingo.modto a supported release and rungo test -race -count=1 ./...in CI so failures block merges. - Step 2: run red, green, refactor on new code in one service, with table-driven tests and review of tests in every pull request.
- Step 3: introduce interfaces and fakes at the boundaries, and
httptestfor HTTP. - Step 4: add fuzz tests for parsers and validators, run them on a schedule, and commit the corpus.
- Step 5: add benchmarks with
b.Loopon hot paths, and move concurrency tests tosynctest.
For the wider picture, read our guide to unit testing techniques and best practices and, for other languages, TDD for Java with JUnit.
To map one release decision your teams and AI agents make, and the tests, context and policy it depends on, book a Context Workshop. See what happens in the workshop.
What should you plan for in 2027?
Planning for 2027 means making the practices above routine rather than adding new tools. Three points carry most of the value for an engineering team.
- Keep the toolchain supported. Set the go version in go.mod to a supported release and run go test with the race detector and a fresh cache in CI, so that failures block merges.
- Grow tests as tables and fuzz targets. Write each new rule as a table row before the code, add fuzz tests for anything that parses untrusted input, and commit the fuzz corpus so every past failure stays a regression test.
- Keep human review on the tests. Review any change that deletes an assertion, adds a skip or edits an expected value, whether a person or an AI coding agent wrote it.
Frequently asked questions
Do I need a framework for Golang unit testing?
No. The go test command and the standard testing package cover unit tests, subtests, benchmarks, examples and fuzzing. Libraries such as testify are optional.
How do you name and place Go test files?
Put tests in a file ending in _test.go next to the code, with functions named TestXxx that take *testing.T. Normal builds exclude these files.
What is a table-driven test in Go?
A test that lists cases as rows of input and expected output and runs each row in its own t.Run subtest, so a failure names the exact case.
When should a Go team use fuzzing?
For any function that parses or validates untrusted input. Native fuzzing has been part of Go since 1.18; failing inputs are saved under testdata/fuzz and replayed by every later go test run.
Which Go version do the newer testing features need?
t.Context and b.Loop need Go 1.24, synctest.Test needs Go 1.25 and t.ArtifactDir needs Go 1.26. Go 1.24 itself is no longer supported.
Is golang/mock still maintained?
No. The repository was archived in June 2023 and points to the maintained fork at go.uber.org/mock.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE


