Key takeaway
- Edge AI vs federated learning for enterprise leaders: where each runs, what stays private, the trade-offs, and how to combine them in one architecture.
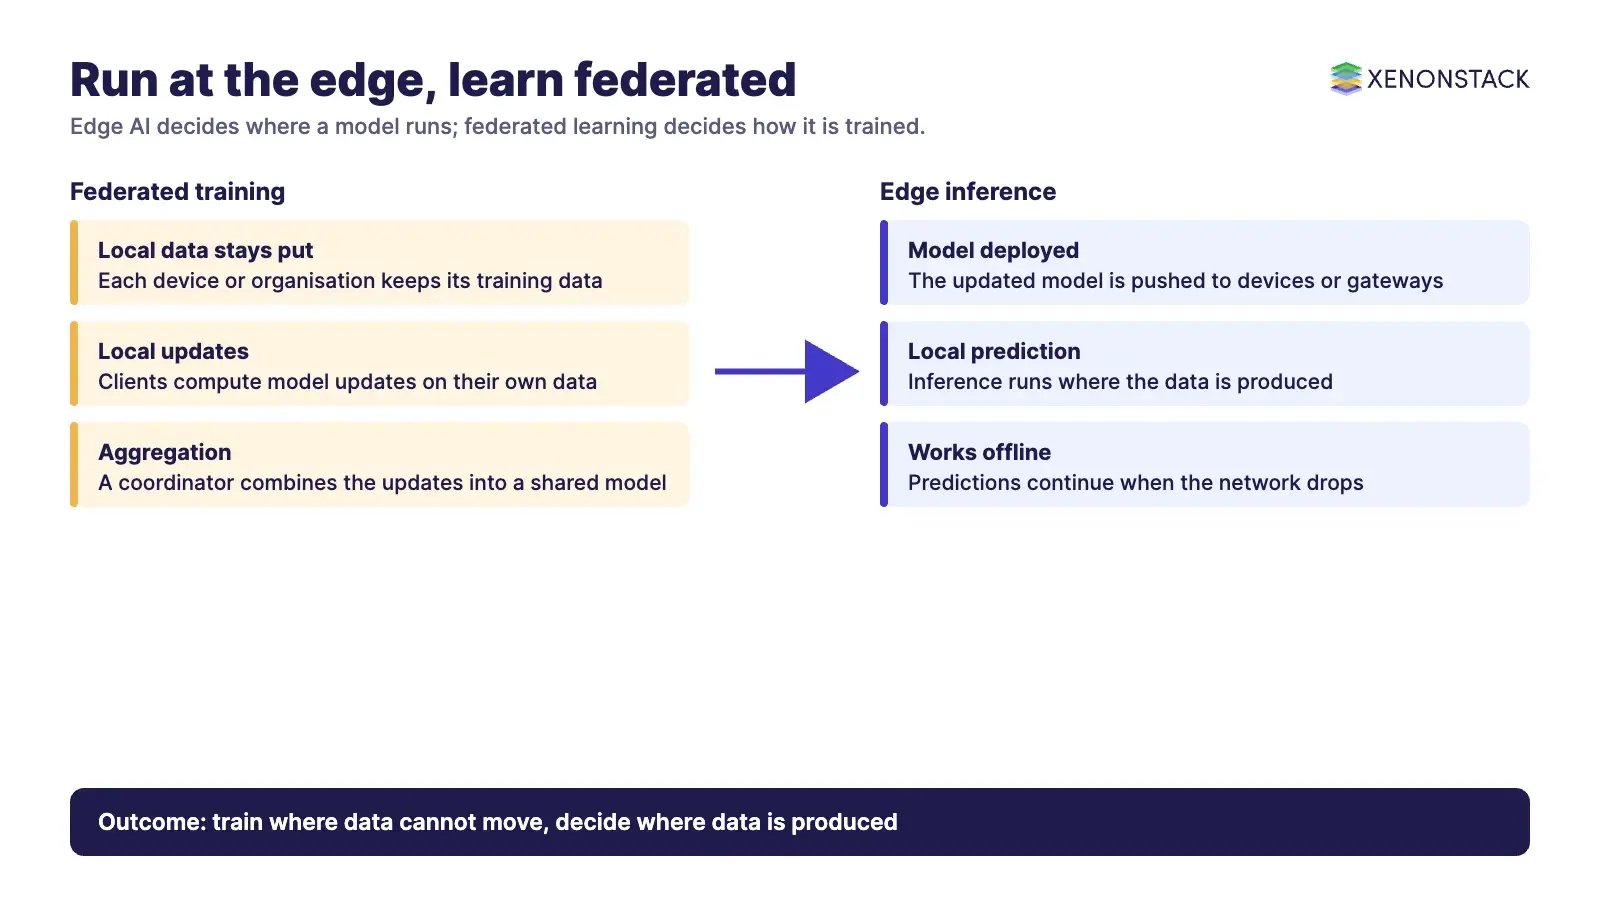
Edge AI and federated learning answer different questions, so they are not true alternatives. Edge AI decides where a trained model runs: on the device or gateway that produces the data, so predictions do not need a round trip to a server. Federated learning decides how a model is trained: on many devices or organisations that keep their data local and share only model updates.
Most enterprises end up needing both, one for fast local decisions and one for learning from data that cannot be pooled. This post is about that choice. For sector examples and tooling on the training side, read our guide to federated learning applications for enterprises.
What is the difference between edge AI and federated learning?
The simplest test is to ask which stage of the model lifecycle you are deciding. Edge AI is about inference (using a trained model). Federated learning is about training. The table sets out the contrast for planning purposes.
| Question | Edge AI | Federated learning |
|---|---|---|
| What does it decide? | Where the model runs | How the model is trained |
| Where does data go? | Processed where it is produced | Training data stays with each participant; updates go to a coordinator |
| Main benefit | Low delay, works with weak or no connectivity | Learns from data you cannot or should not centralise |
| Main cost | Fleet of devices to deploy, monitor and update | Coordination, communication rounds and uneven data |
| Typical owner | Platform or operations engineering | Data science with security and legal input |
How does edge AI work?
A model is usually trained in a data centre or cloud, then compressed and deployed to run on a phone, camera, gateway or machine. Google's LiteRT (formerly TensorFlow Lite) is one example of a runtime for this: it runs models on mobile, web, desktop and IoT devices, and its documentation shows large language models running on a phone without a server round trip (read 12 Nov 2026, developers.google.com/edge/litert).
For leaders, the practical effects are shorter response times, less raw data leaving the site and the ability to keep working when the network drops. Note that edge AI on its own does not train a better model: the model on the device is only as good as the training that produced it. Our posts on AI in edge computing, edge AI in manufacturing and edge AI with agentic AI for distributed intelligence cover deployment patterns in more depth.
How does federated learning work?
In the original federated learning paper, McMahan and colleagues describe training a shared model by combining updates computed locally on many mobile devices, so the training data stays on the devices. They report that their iterative model averaging needed 10 to 100 times fewer communication rounds than synchronised stochastic gradient descent, and that it coped with unbalanced and non-IID data (arXiv 1602.05629, submitted Feb 2016, latest revision Jan 2023).
The clients can be devices or whole organisations such as hospitals. The "Advances and Open Problems in Federated Learning" survey describes the approach as following the principles of focused data collection and data minimisation, which can reduce the systemic privacy risks and costs of centralised training (arXiv 1912.04977, December 2019, v3 March 2021).
What has changed in federated learning?
Research has moved from the basic averaging idea towards four practical concerns, summarised below.
Model Aggregation Techniques
Federated averaging (FedAvg), for example, has been recommended to enhance the efficiency of federated learning. Therefore, depending on the data's non-IID distribution, the technique remains concerned with efficiently updating the model combination.

Personalization
This has led to local fine-tuning and meta-learning, among other approaches, as a way of helping to get those highly desired personal models. They enable models to learn from local data to bring that data closer home, reducing relevance and increasing precision.
Robustness to Adversarial Attacks
As soon as people embraced federated learning in practice, they realized security was a problem. Measures were proposed for safely summarizing the model's received local updates and detecting attacks or other violations by participants.

Cross-Silo Federated Learning
This variant allows information exchange between different organizations (silos) that cannot exchange data because of data protection issues. Usually, cross-organizational silo or federated learning refers to a situation.
What are the limits of each approach?
| Limit | Edge AI | Federated learning |
|---|---|---|
| Device capability | Models must fit the memory, power and compute of the target hardware | Devices differ widely in hardware, connectivity and power, and only some are active at any time |
| Data | A local model sees only local conditions unless it is updated | Data across participants is often non-IID, which complicates training |
| Communication | Model updates still have to be shipped to the fleet | Communication is slower and costlier than local computation, so updates must stay small |
| Privacy | Raw data can stay local, but the device itself must be secured | Updates are not automatically safe: the Deep Leakage from Gradients paper shows private data can be recovered from shared gradients |
The leakage result is worth taking to your security team. Zhu and colleagues showed that images and text could be recovered from shared gradients, and they name gradient pruning as the most effective defence they discuss (arXiv 1906.08935, June 2019). Keeping data local is a strong start, not a complete privacy guarantee. Our overview of distributed AI trends gives wider context.
Which should you choose?
| Your situation | Choose | Why |
|---|---|---|
| A decision must be made in milliseconds on site, or the network is unreliable | Edge AI | Inference runs next to the data source |
| Several organisations hold data that cannot be pooled | Federated learning (cross-silo) | Each keeps its data and shares updates only |
| Many user devices generate data you should not upload | Federated learning (cross-device) | Training happens where the data is |
| One site, data can be centralised legally and cheaply | Neither is required | Conventional central training is simpler |
| Local decisions need a model that improves from many sites | Both | Train federated, deploy to the edge |
How do edge AI and federated learning work together?
The common pattern is to train with federated learning and serve with edge AI. Sites or devices improve a shared model from local data, a coordinator combines the updates, and the new version is pushed back to the edge for inference. In physical AI settings such as factories and robots, edge AI is the execution layer, and NexaStack is an agentic operating platform for physical AI that runs across on-premises, cloud and hybrid environments.
What about governance, security and cost?
- Governance: record which model version runs where, and which participants contributed to each training round, so decisions can be audited later. AgentGRC keeps autonomous agent actions inside policy, with the audit trail risk teams need.
- Security: secure the device fleet, validate incoming updates and test for gradient leakage before relying on "data stays local" in a compliance statement.
- Cost: edge AI shifts spend to hardware and fleet operations; federated learning shifts it to coordination and communication. Neither removes the need for monitoring.
- Decision context: ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents.
In what order should you adopt them?
- Decide the latency, connectivity and data-residency needs per use case.
- Start with edge inference using a centrally trained model, and measure the gain.
- Add federated training only where data truly cannot be pooled.
- Add update validation, privacy testing and model version tracking before scaling the fleet.
- Review each use case regularly: if data can later be centralised safely, simplify.
To map one edge or federated decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
Is federated learning a type of edge AI?
Not exactly. Federated learning is a training method that often uses edge devices as clients, while edge AI is about running a model locally. They overlap in practice but solve different problems.
Does federated learning guarantee privacy?
No. Training data stays local, but research shows private data can sometimes be recovered from shared gradients, so extra defences and testing are needed.
Can edge AI work without an internet connection?
Yes, once the model is on the device. Runtimes such as LiteRT run models on the device itself, though updates still need a connection at some point.
When do I not need federated learning?
When your data can be centralised legally, safely and at reasonable cost. Central training is simpler to run.
What is the difference between cross-device and cross-silo federated learning?
Cross-device involves very many user devices, while cross-silo involves a small number of organisations. The terms are our planning shorthand for the device and organisation clients described in the research.
Where can I read about federated learning use cases?
See our post on federated learning applications.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE