Key takeaway
- Build a CI/CD pipeline for a Python app: containerise with Docker, push to a registry, deploy to Kubernetes and verify the rollout. Steps and pitfalls.
A CI/CD pipeline for a Python application builds the code into a container image, tests it, pushes the image to a registry and deploys it to Kubernetes automatically on every change. Continuous integration merges and tests changes often. Continuous delivery keeps the result in a state that can be released to production at any point.
This guide is for developers and DevOps engineers who have a Python service and want a repeatable route from source code to a running Kubernetes workload. It covers containerising the app, publishing the image, writing the Deployment and Service files, verifying the rollout, and where an automation server and AI agents fit. For the Jenkins side, see Continuous Delivery Pipeline with Jenkins.
What does a Python delivery pipeline need before you start?
The pieces are the same whether you run a local cluster or a cloud one. The Kubernetes documentation describes a Deployment as something that "manages a set of Pods to run an application workload, usually one that doesn't maintain state", which is the shape most Python web services take.
| Item | Purpose | Note |
|---|---|---|
| Kubernetes cluster and kubectl | Runs the container and lets you manage it from the command line | A local cluster is enough for a first test |
| Application source code | The Python service you want to ship | Pin dependencies in requirements.txt |
| Dockerfile | Lists the steps that build the image | Keep it small and cache dependency installs |
| Container registry | Stores versioned images the cluster pulls | Docker Hub, a cloud registry or a private registry |
| Shared persistent storage | Keeps files that must outlive a pod | Only needed if the app writes files, not for a database |
How do you containerise a Python application?
The Docker guide to containerising a Python app states that containerising means "packaging it together with its dependencies, configuration, and runtime". Its Dockerfile has two stages. A builder stage creates a virtual environment and installs requirements, and a runtime stage copies that environment and the source code. The guide notes that you should download dependencies as a separate step to take advantage of Docker's caching, and that its minimal runtime image runs as nonroot by default. It also lists paths a .dockerignore file keeps out of the build, such as __pycache__, .venv, .git and .env.
A minimal single-stage version looks like this. Use a Python release that is currently supported, not the Python 2.7 base image that many older tutorials used.
FROM python:3.12-slim
WORKDIR /usr/src/app
COPY requirements.txt .
RUN pip install --no-cache-dir -r requirements.txt
COPY . .
EXPOSE 5035
CMD ["python", "wsgi.py"]
Build and tag the image with a version, for example docker build -t my-app:1.0 .. Never rely on a moving "latest" tag in a deployment file.
How do you publish the image to a registry?
Retag the image with the registry address, log in, and push it. Login commands differ between registries and change between command-line versions, so copy the current login steps from your registry's own documentation rather than from an old script. Do not put cloud access keys in files that are committed or baked into an image. If you use a private registry that is not served over TLS, the Docker daemon has to be told to allow it, and that setting weakens transport security, so prefer a registry with a valid certificate.
How do you deploy the image to Kubernetes?
Describe the workload in two files, a Deployment and a Service, and apply them with kubectl. The sample manifests in older guides used the extensions/v1beta1 API group, which is no longer how Deployments are declared. Use apps/v1 and include a selector that matches the pod labels.
| File | What it defines | Fields to check |
|---|---|---|
| Deployment | The image, number of replicas and labels for the pods | apiVersion, selector, image tag, containerPort |
| Service | A stable address and port in front of the pods | Selector matches pod labels, port and type |
| PersistentVolumeClaim (optional) | A request for storage that survives pod restarts | Access mode, size, mount path |
Apply the files with kubectl apply -f so that later changes update the running workload instead of failing because it already exists. A NodePort Service exposes the app on a port of every node, which suits testing. For production traffic, put an ingress or load balancer in front instead.
How do you verify and troubleshoot the release?
Check that the pods are running with kubectl get pods in the right namespace, find the exposed port with kubectl get svc, then open the node address and port in a browser or call the health endpoint. The Kubernetes documentation also lists reference pages for kubectl rollout status, rollout history and rollout undo, which let a pipeline wait for a release and roll it back. When something fails, work through this order: pod status, container logs, service port and selector, and finally the dependencies in requirements.txt.
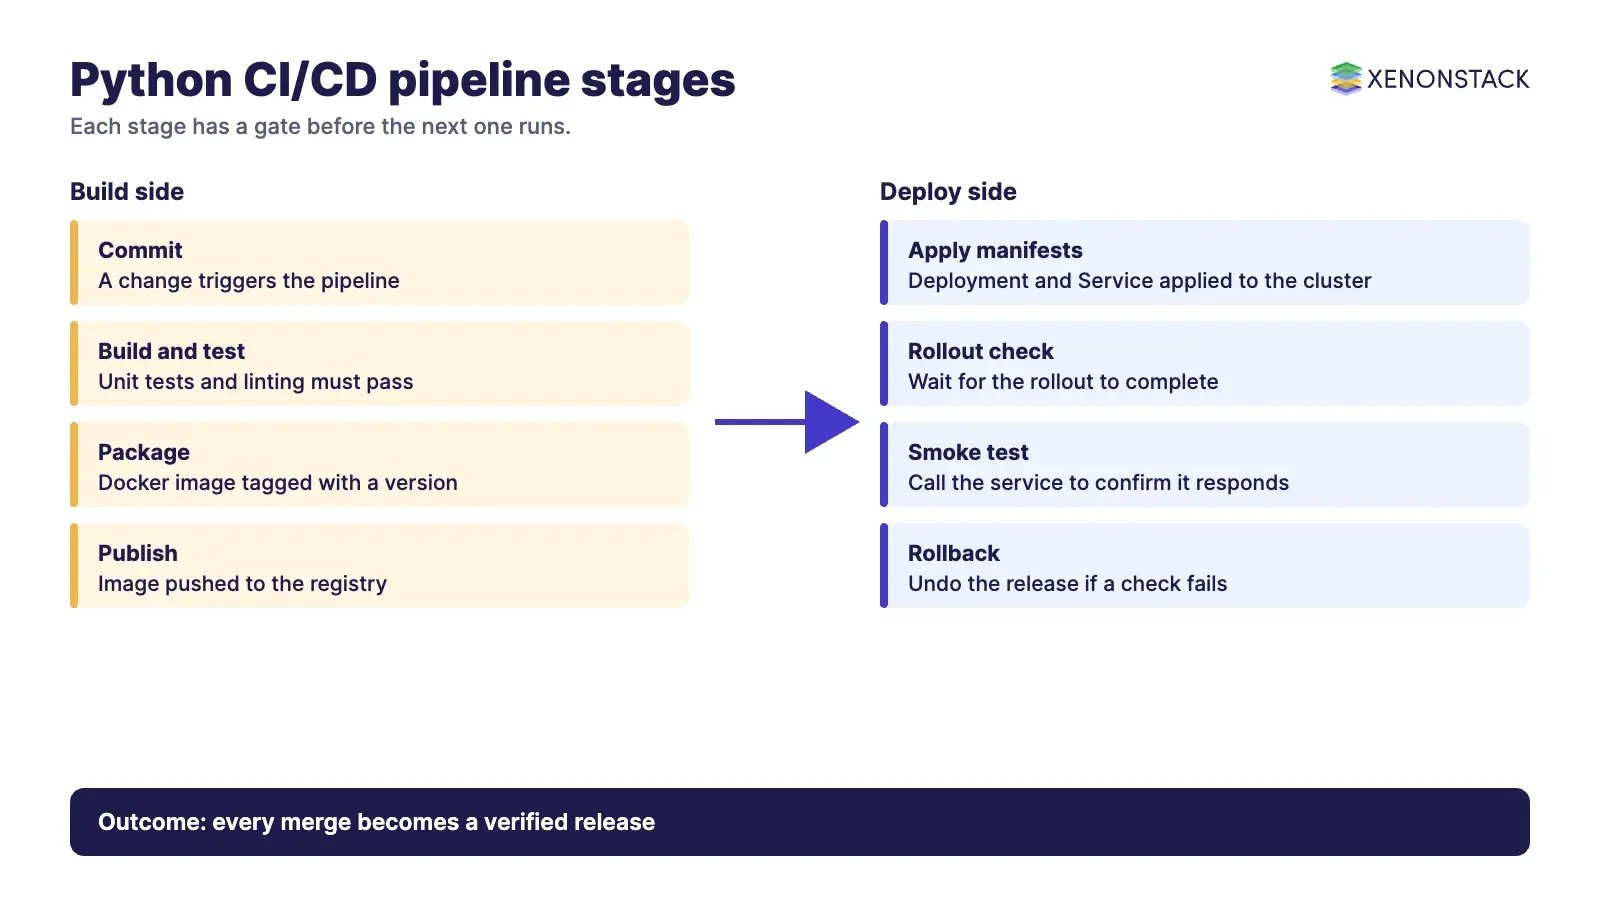
Which stages should the pipeline automate?
| Stage | Trigger | Gate before the next stage |
|---|---|---|
| Build and test | Every commit or pull request | Unit tests and linting pass |
| Package | Merge to the main branch | Image builds and is tagged with the commit or version |
| Publish | Successful package stage | Image is in the registry |
| Deploy | Publish done, or manual approval for production | Rollout completes and a smoke test passes |
Teams that want help setting this up can read about DevOps consulting services, or follow the same pattern for other stacks in Azure DevOps Pipeline for Laravel Php and Continuous Delivery for Scala Applications.
How do AI agents change a Python delivery pipeline?
A fixed pipeline runs the same steps every time. An AI agent can read a failed build log, propose a fix, open a pull request or check a rollout, while the pipeline's gates and approvals still decide what reaches production. The useful design question is which actions an agent may take alone and which need a human sign-off. The AI agents computing platform is XenonStack's route to building and governing agents for DevOps and automation work like this.
What should you do first?
- Containerise one service with a pinned, supported Python version and a .dockerignore file.
- Push a versioned image to a registry with credentials held outside the repository.
- Write the Deployment and Service files with apps/v1 and apply them to a test namespace.
- Add a pipeline that builds, tests, publishes and deploys on merge.
- Add a rollout check and a rollback step before you add production approvals.
To map one decision your agents make in the pipeline, and the data and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is the difference between continuous integration and continuous delivery?
Continuous integration merges and tests code changes frequently. Continuous delivery goes further and keeps every successful build ready to deploy to production.
Do I need persistent storage for a Python app on Kubernetes?
Only if the app writes files that must survive a pod restart, such as uploads. Services that keep state in a database usually do not need it.
Which registry should I use for container images?
Any registry your cluster can reach works, including Docker Hub, a cloud provider registry or a private registry. Choose by where the cluster runs, access control and cost.
Why should I avoid the latest image tag?
A moving tag makes it unclear which build is running and makes rollbacks harder. A version or commit tag ties each deployment to one image.
How do I roll back a failed Kubernetes release?
Use the kubectl rollout undo command on the Deployment, and check the result with kubectl rollout status. Add both to the pipeline so a failed smoke test triggers the rollback.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE