Key takeaway
- Deep learning vs machine learning vs neural networks: how they relate, where each fits, what it costs, and how to govern models in the enterprise.
What is the difference between deep learning, machine learning and neural networks?
They are nested ideas, not rivals. Machine learning is the broad approach of learning patterns from data instead of writing rules by hand. A neural network is one kind of machine learning model, built from layers of simple units. Deep learning is machine learning that uses neural networks with many hidden layers, so the model can learn its own features from raw data.
For a CTO or Chief AI Officer the useful question is which one to fund for a given decision. Classic machine learning is often enough, and cheaper to run, for structured business data. Deep learning earns its cost on images, speech, text and other raw signals. For a closer look at network designs and applications, read our guide to artificial neural network applications.
How do machine learning, neural networks and deep learning relate?
IBM defines a neural network as “a machine learning model that stacks simple ‘neurons’ in layers”, with an input layer for the raw features, hidden layers that combine inputs using learned weights and biases, and an output layer that produces the prediction (IBM, neural networks). MathWorks describes deep learning as a branch of machine learning that uses neural networks, where “deep” usually refers to the number of hidden layers (MathWorks, deep learning).
| Term | What it is | Typical input | Where it fits |
|---|---|---|---|
| Machine learning | Algorithms that learn patterns from data, from linear models and decision trees to neural networks | Structured, tabular business data, with features chosen by the team | Forecasting, scoring, segmentation, anomaly detection |
| Neural network | A machine learning model made of layers of connected units with learned weights | Numeric inputs such as vectors | Non-linear patterns that simpler models miss |
| Deep learning | Neural networks with many hidden layers that learn features directly from data | Images, audio, text, sensor streams | Vision, speech, language, complex sequences |
How do the three differ in practice?
Deep learning vs machine learning
In a classic workflow, people extract the important features first and then train a model on them. MathWorks notes that deep models can often learn features directly from the data without manual feature extraction. The trade-off is cost: deep learning typically needs very large datasets, and GPUs with a parallel architecture can cut training time from weeks to hours or less (MathWorks). Transfer learning from a pretrained model usually needs less labelled data and time than training from scratch.
Deep learning vs neural networks
Every deep learning model is a neural network, but not every neural network is deep. The difference is depth and what it demands: a deep network needs more data, more GPU time and more care in testing. There is no fixed layer count that separates the two, because MathWorks says only that “deep” usually refers to the number of hidden layers.
Machine learning vs neural networks
Machine learning is the wider field and a neural network is one model family inside it. A gradient-boosted tree and a neural network are both machine learning, but they suit different data. On medium-sized tabular data, an arXiv study by Grinsztajn, Oyallon and Varoquaux (submitted 18 July 2022) reports that tree-based models such as XGBoost and random forests remain state-of-the-art, so a neural network is not automatically the better choice for spreadsheets and database tables (arXiv 2207.08815). It is a preprint, so treat it as evidence, not a rule.
Which types of neural network should enterprise teams know?
| Type | What it is built for | Current status |
|---|---|---|
| Feedforward (multilayer perceptron) | General prediction from fixed inputs; IBM calls it the standard design | Foundation for most other designs |
| Convolutional (CNN) | Grid-like data such as images, using convolutional filters to detect spatial features | Widely used in vision |
| Recurrent (RNN) | Sequences, using feedback loops that carry information across time steps, for example speech and time series | IBM notes transformers have replaced RNNs for many sequence tasks |
| Transformer | Sequences and language, using attention instead of recurrence | Introduced in the 2017 paper “Attention Is All You Need” (arXiv 1706.03762, submitted 12 June 2017); GPT is an example of a transformer-based model |
The transformer paper describes a network “based solely on attention mechanisms, dispensing with recurrence and convolutions entirely” (arXiv 1706.03762).
When should you choose machine learning, a neural network or deep learning?
| Situation | Better fit | Why |
|---|---|---|
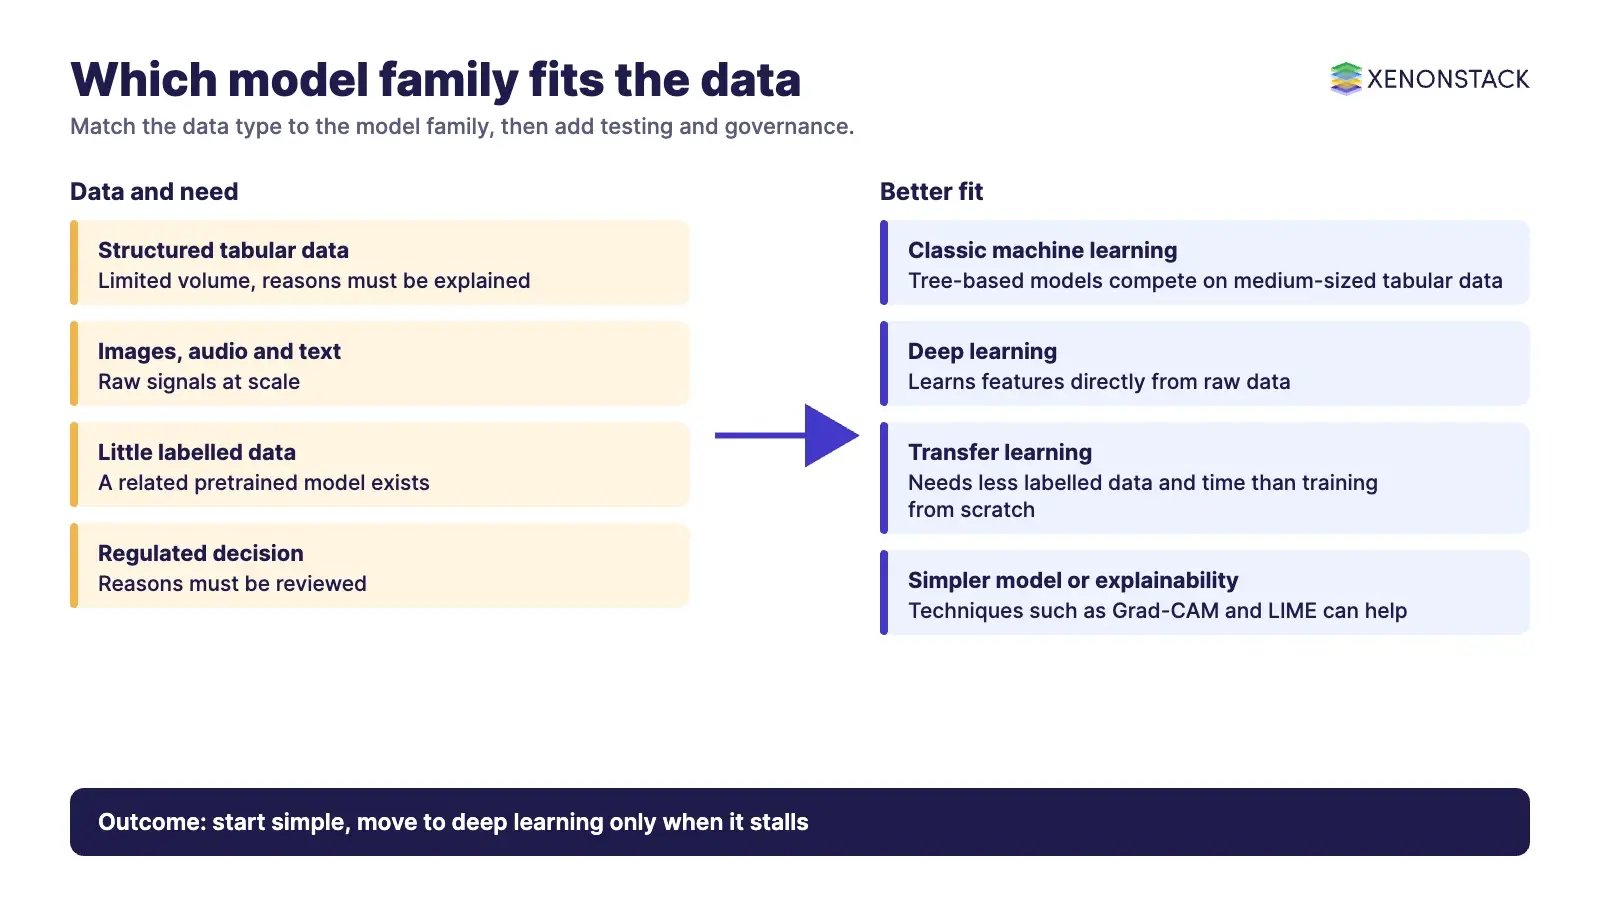
| Structured tabular data, limited volume, need for fast explanation | Classic machine learning, including tree-based models | Competitive accuracy on medium-sized tabular data, lower compute, easier to explain |
| Images, audio, text or sensor streams at scale | Deep learning | Learns features directly from raw data, and accuracy improves as training data grows |
| Little labelled data but a related pretrained model exists | Deep learning with transfer learning | Usually needs less labelled data and time than training from scratch |
| Regulated decision where reasons must be reviewed | Simpler model first, or deep model with explainability | MathWorks notes deep models are often seen as black boxes, though techniques such as Grad-CAM and LIME can help |
When not to use deep learning: when you have little data, no GPU budget, or a regulator who expects a clear reason for each outcome. Start with the simplest model that meets the accuracy target, and move to deep learning only when the simpler one stalls.
What does it take to run these models in production?
Training is only the start. Models need versioned data and code, automated tests, deployment pipelines and drift monitoring. Our guides on the machine learning pipeline, DevOps for machine learning and model deployment testing cover these stages, and our machine learning development services page explains how we support them. For tooling choices, see machine learning tools.
How should leaders govern deep learning and machine learning models?
The NIST AI Risk Management Framework 1.0, released on 26 January 2023, is intended for voluntary use and organises risk work into four functions: Govern, Map, Measure and Manage. NIST published a Generative AI Profile (NIST-AI-600-1) on 26 July 2024 (NIST AI RMF). For cost, track GPU hours, data labelling effort and monitoring effort per model, because deep models usually carry the highest bill.
Governance also applies to the decisions that models feed. ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control. AgentAnalyst lets teams ask questions of enterprise data in plain language and get real-time insights.
What is a sensible adoption sequence?
Pick one decision and measure the current baseline.
Try a simple machine learning model first and record its accuracy and cost.
Move to a neural network or deep learning only if the baseline stalls and you have the data and compute.
Add testing, explainability and drift monitoring before go-live.
Review cost and risk against the NIST functions each quarter.
To map one decision your AI models should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
Is deep learning the same as a neural network?
No. A neural network is a model made of layers of connected units. Deep learning uses neural networks with many hidden layers, so every deep learning model is a neural network but not the reverse.
Is deep learning better than machine learning?
Not always. Deep learning can learn features directly from raw data such as images and text, but it typically needs very large datasets and more compute. An arXiv study reports tree-based models remain state-of-the-art on medium-sized tabular data.
How many layers make a network deep?
There is no fixed number in the sources we checked. MathWorks says the term deep usually refers to the number of hidden layers.
Why does deep learning need GPUs?
GPUs have a parallel architecture suited to training, and MathWorks says they can cut training time from weeks to hours or less.
Are transformers a type of neural network?
Yes. Transformers use attention instead of recurrence, were introduced in the 2017 paper Attention Is All You Need, and IBM notes they have replaced RNNs for many sequence tasks.
Which risk framework applies to these models?
The NIST AI Risk Management Framework 1.0 (26 January 2023) is voluntary and uses four functions: Govern, Map, Measure and Manage.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE