Key takeaway
- Test an ML model before and after release: data checks, canary and A/B rollout, drift monitoring, rollback and tools, per Google's ML Test Score.
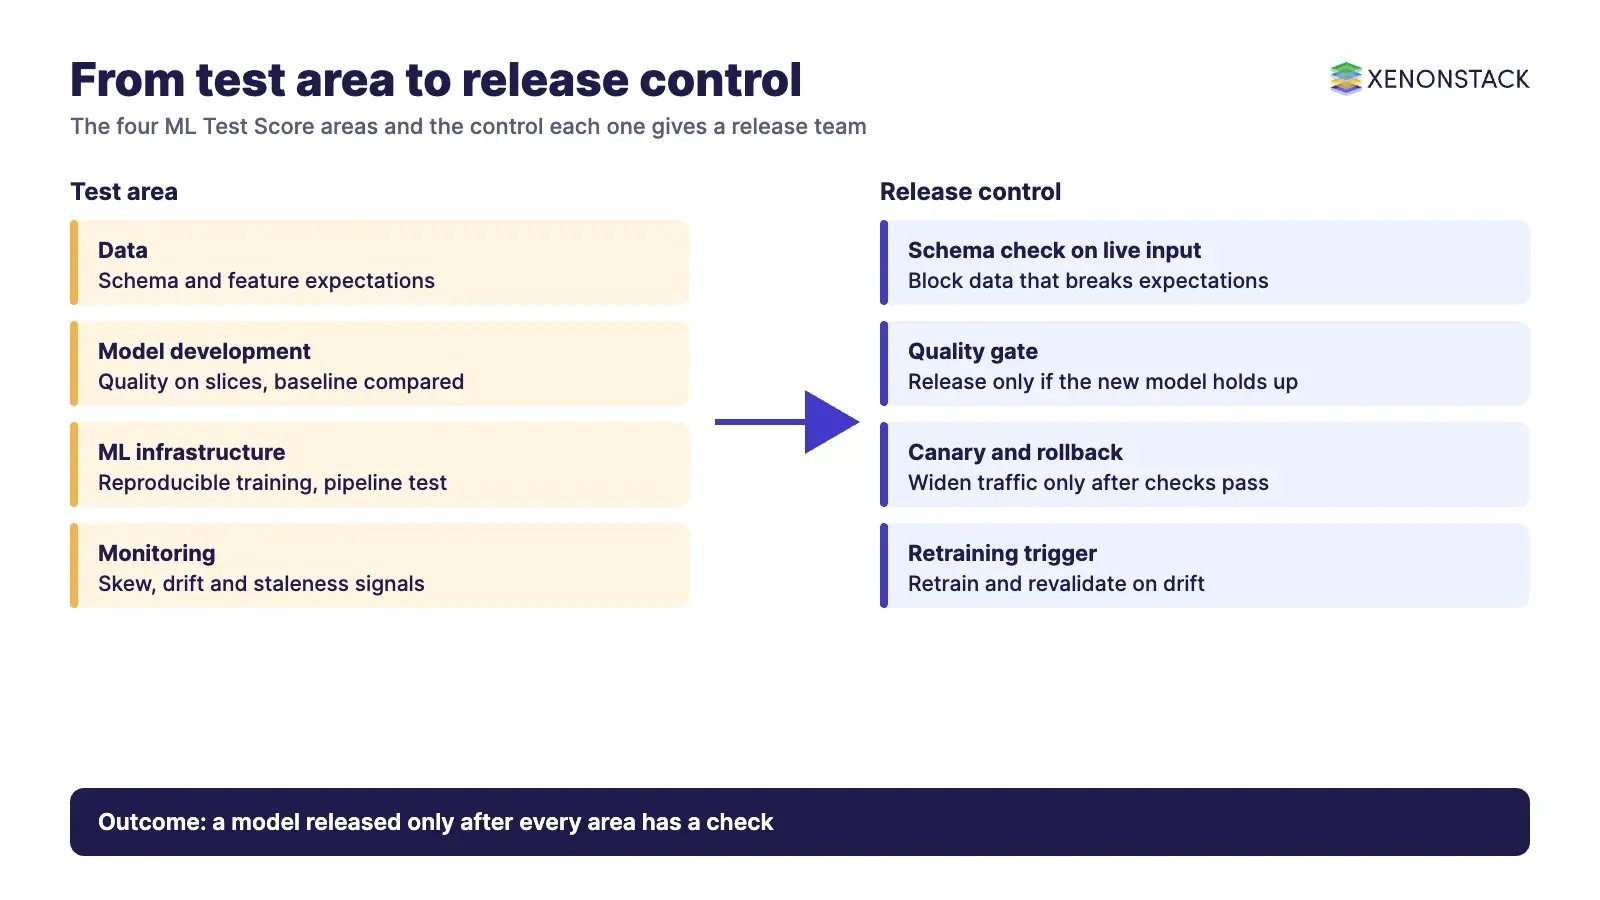
Machine learning model deployment testing is the set of checks that decide whether a model is safe to release and still safe to keep serving. It covers the data the model sees, the code that trains and serves it, the release step, and the monitoring that follows. Google's ML Test Score paper lists 28 such tests in four areas: data, model development, ML infrastructure and monitoring.
Testing does not stop at release, because live data changes. This guide focuses on the deployment stage: what to check before go-live, how to roll out safely, and what to watch afterwards. For the earlier stages, see our guides to machine learning model testing, model validation testing and the machine learning pipeline.
What is machine learning model deployment testing?
A model is code plus data, so it can fail in ways ordinary software tests do not catch. The inputs can shift, a feature can be computed differently in training and in serving, or accuracy can slowly fall. The ML Test Score paper (Breck, Cai, Nielsen, Salib and Sculley, IEEE Big Data 2017) groups the checks into four areas, seven tests each.
| Area | What it checks | Examples from the paper |
|---|---|---|
| Data | Features and the data pipeline | Feature expectations captured in a checkable schema; unit tests for feature-creation code |
| Model development | Model quality before release | Quality on important data slices; a simpler baseline is not better than the production model |
| ML infrastructure | Training and serving machinery | Reproducible training; integration test of the full pipeline; canary before serving; safe rollback |
| Monitoring | The model while it serves | Training and serving features compute the same values; prediction quality has not regressed; models are not too stale |
Source: Google Research, The ML Test Score (read 13 November 2026).
Which tests should pass before a model goes live?
Google's MLOps architecture guide calls the pre-release step offline model validation. According to that guide, it evaluates the new model on a test dataset, compares it with the current production or baseline model, checks that performance holds across data segments, and confirms the model is compatible with the infrastructure and the prediction service API.
- Data checks: inputs match the expected schema and ranges, and live inputs resemble the training data.
- Quality gate: the new model beats or matches the current one on agreed metrics, including on important slices, not only on the average.
- Pipeline checks: training is reproducible and the whole pipeline passes an integration test.
- Serving checks: the packaged model returns the same predictions as in testing and fits the latency and memory budget.
- Fairness and review: the model specification is code-reviewed and checked into a repository, and fairness and inclusion concerns are tested.
How do you release a new model safely?
Google's guide describes online model validation as the step before a model serves all traffic, run as a canary deployment or an A/B test. In practice, send a small share of requests to the new model, compare it with the current one, and widen the share only if it holds up. The ML Test Score paper adds two infrastructure tests that belong in every release plan: canary before serving, and a way to roll back quickly and safely.
A model registry makes rollback a routine action. According to the MLflow Model Registry documentation, each registration creates a new numbered version, versions link back to the run that produced them, and an alias such as champion is a movable name that points to one version. Moving the alias changes which version production uses.
What should you monitor after deployment?
Google's guide separates the failure types that monitoring should catch, and each has a different response.
| Signal | Meaning, per Google's guide | Usual response |
|---|---|---|
| Training-serving skew | Features in production differ from those used in training, often because of how data is handed over between teams | Fix the feature logic; a shared feature store helps |
| Data values skew | A significant statistical change in the input data | Treat as a signal to retrain |
| Concept drift | Significant change in the feature distributions used for prediction, so the model has gone stale | Retrain and revalidate |
| Data schema skew | Input does not match the expected schema | Stop the pipeline and investigate |
The same guide lists retraining triggers: on demand, on a schedule, when new training data arrives, when performance degrades, and when data drift appears. Choose the trigger by how fast your data changes and what each retraining run costs. A retrained model should pass the same release tests as any other model.
Source: Google Cloud, MLOps: continuous delivery and automation pipelines (read 13 November 2026).
Which tools help with ML model testing and monitoring?
Check each tool's current status before you commit, because this market has changed. The table reflects each vendor's own pages as read on 13 November 2026.
| Tool | What it does | Current status |
|---|---|---|
| MLflow | Model registry with versions, aliases and lineage | Open-source documentation current |
| Evidently | Evaluation, testing and monitoring, with built-in metrics for predictive performance, data drift and data quality | Open source under Apache 2.0, according to its site |
| Arize | Observability and evaluation; Arize AX is managed and Phoenix is open source | Positioned by its site for agent and LLM applications as well as models |
| Neptune | Experiment tracking and metadata | Hosted service ended on 5 March 2026 after the OpenAI acquisition agreement, according to its transition page |
| WhyLabs | Data and model monitoring (Observe) and guardrails (Secure) | Platform source released under Apache 2.0 and not open to contributions, according to its repository; GeekWire reports the company is discontinuing operations |
Our machine learning tools guide compares the wider tool landscape, and model visualization helps when you need to explain results to reviewers.
How do you score deployment readiness?
The ML Test Score gives each test up to one point: half a point if you run it manually and document the result, a full point if it runs automatically and repeatedly. You add the points within each of the four areas, and the final score is the lowest of the four totals, so a strong data pipeline cannot hide weak monitoring. The paper reads 0 as more a research project than a production system, and a score above 3 as strong automated testing and monitoring suitable for mission-critical systems.
How does this apply to AI agents built on models?
When a model sits behind an AI agent, the release question widens from "is the model accurate" to "does the agent act correctly on real tasks". AgentEvaluation from ElixirData scores and benchmarks enterprise AI agents before and after they go live, according to its site. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents, so a release test can refer to the same policy the agent follows in production. XenonStack is the publisher of this guide and ElixirData is a related product.
What is a sensible adoption sequence, and when is it too much?
- Start with a schema check on live inputs and a quality gate against the current model.
- Add a canary or A/B release step and a documented rollback.
- Monitor skew and drift, and set one retraining trigger.
- Automate the tests, then score yourself with the ML Test Score.
The trade-off is effort: every automated test needs an owner. For a low-risk internal model that changes rarely, manual checks with documented results (half a point each in the rubric) may be enough. For a model that affects customers or money, automate.
To map one model decision your agents rely on, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop. For wider reading, see machine learning trends.
Frequently asked questions
What is machine learning model deployment testing?
It is the set of tests that decide whether a model is ready to serve and still healthy once live, covering data, model quality, infrastructure and monitoring.
What is the ML Test Score?
It is a rubric of 28 tests in four areas from Google researchers. Each test earns half a point if run manually and one point if automated, and the overall score is the lowest area total.
What is the difference between canary deployment and A/B testing for models?
Google's guide names both as ways to validate a model online before it serves all traffic. Both send part of the traffic to the new model; the aim is to compare it with the current one before widening the rollout.
What is training-serving skew?
It is a mismatch between the features used in training and those available in production, which can make a model perform worse live than in testing.
How often should a model be retrained?
Google's guide lists on-demand, scheduled, new-data, performance-degradation and drift triggers. Pick one based on how quickly your data changes and what retraining costs.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE