Key takeaway
- EtLT vs ELT vs ETL compared for architects: what the light transform does, a Kafka, Spark and Delta Lake code example, and when not to use it.
EtLT (extract, light transform, load, transform) is a data processing pattern that applies only small, safe fixes to data before loading it, then runs business logic inside the warehouse or lakehouse. It sits between classic ETL, where heavy transformation happens before load, and plain ELT, where nothing is changed until the data has landed. The small "t" keeps pipelines fast and the landing zone clean; the large "T" keeps business rules in one governed place.
This guide is for architects and data leaders choosing between the three patterns. It compares them in a decision table, shows a working Kafka, Spark and Delta Lake example, and sets out when EtLT is the wrong choice. For the tools that feed the pipeline, see our guide to data ingestion tools and architecture.
What is EtLT and how does it differ from ETL and ELT?
ELT, as Databricks describes it, extracts data from source systems, loads it into a central repository in raw or near-raw form, and transforms it there using the platform's own compute. Traditional ETL cleans and reshapes data before it reaches the target. EtLT splits the work: a light, source-facing "t" before load, and the business-facing "T" after. As reported by a 2023 article by an Apache DolphinScheduler committer on HackerNoon, the small "t" converts heterogeneous source data into a structured form the target can load, for example by splitting, filtering and changing field formats on change data capture streams, while business rules stay in the large "T".
| Pattern | Where transformation happens | When it fits | Main risk |
|---|---|---|---|
| ETL | Before load, on a separate engine | Strict targets, small curated outputs, data that must never land raw | Pipeline changes are slow, and every rule change means reprocessing at source |
| ELT | After load, inside the warehouse or lakehouse | Clean, well-structured sources and a strong target platform | Messy raw formats and unmasked fields land in the target |
| EtLT | Light fixes before load, business logic after | Streaming and batch from mixed sources, CDC feeds, raw history kept for reuse | Teams blur the line and put business rules in the small "t" |
What does each EtLT stage do?
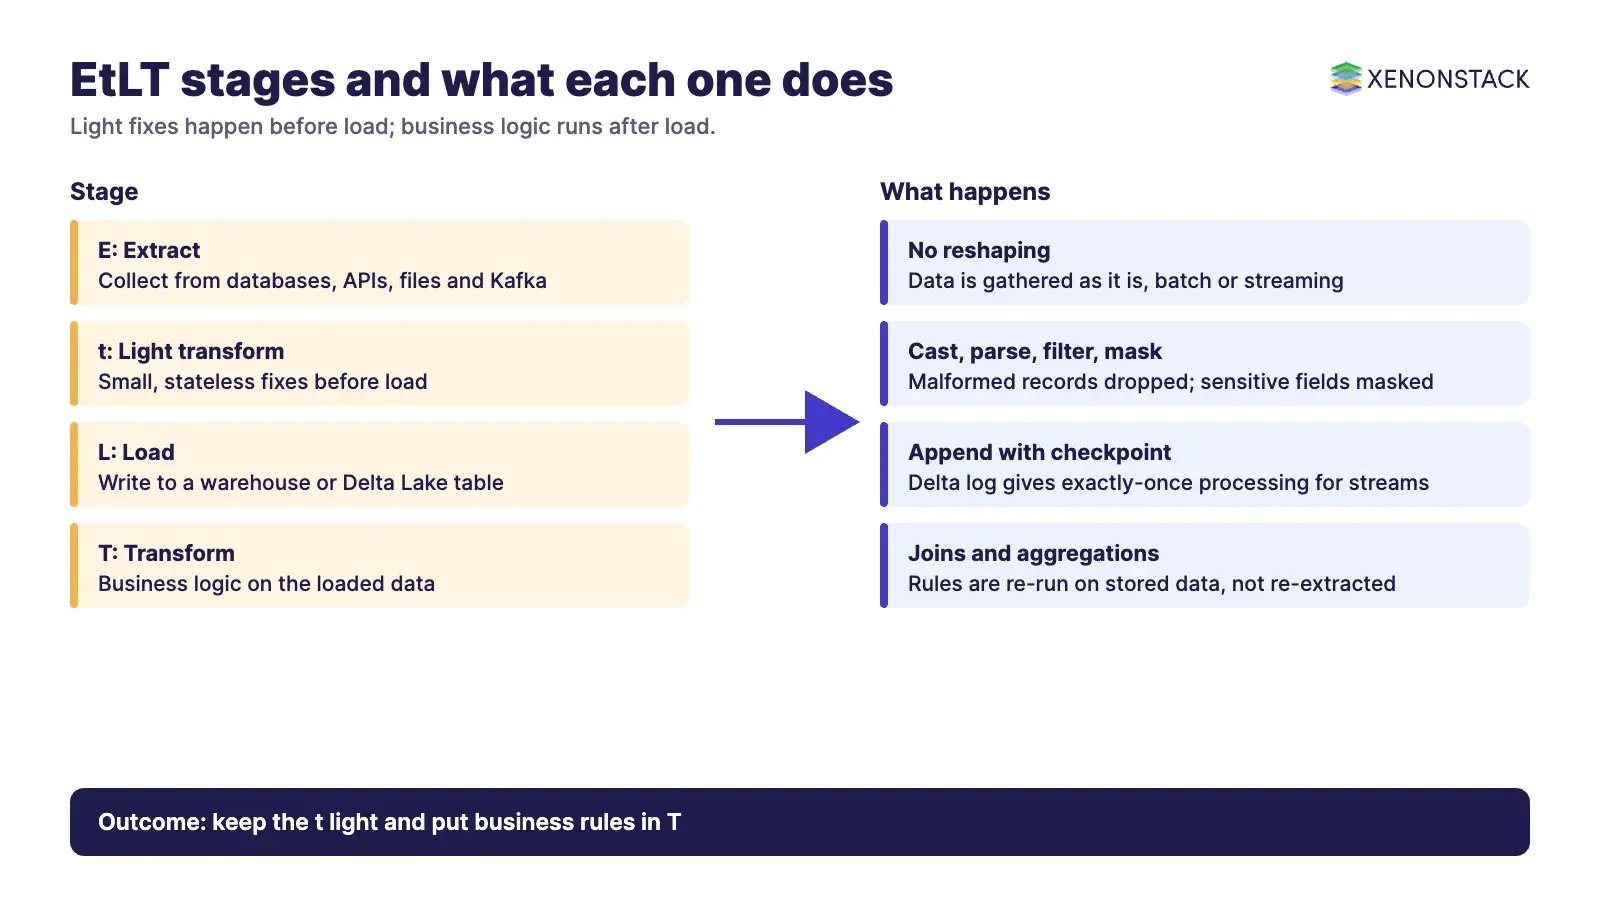
Each stage has one job. Keeping the jobs separate is the whole point of the pattern, so each rule below can be tested in code review.
E: Extract
Collect data from databases, APIs, files and event streams such as Apache Kafka, without reshaping it. Tool choice for this stage is covered in our data ingestion pipeline architecture guide.
t: Light transform
Apply only changes that are cheap, stateless and independent of business meaning: cast types, parse a payload into columns, drop malformed records, standardise timestamps, and mask or drop fields that must not be stored. As design guidance, if a rule needs a join, a lookup or a metric definition, it belongs in the large "T".
L: Load
Write the lightly transformed data to durable storage: a data warehouse, a Snowflake architecture, or a lakehouse on Delta Lake. The Delta Lake documentation describes one table acting as a batch table, a streaming source and a streaming sink, so ingestion, backfills and queries can share the same data.
T: Transform
Run aggregations, joins and business logic on the loaded data, in SQL or Spark, and version that logic like application code. Because raw and lightly cleaned data is retained, a changed business rule is re-run on stored data instead of re-extracted from the source.
When should you choose EtLT over ELT or ETL?
| Situation | Better choice | Reason |
|---|---|---|
| Mixed streaming and batch sources, different owners | EtLT | Source quirks are handled once at the edge, and business rules stay with analysts |
| Clean, structured sources already in a cloud warehouse | ELT | A light step adds little when the data is already well formed |
| Regulated fields that must not be stored in the target | ETL or EtLT | Mask or drop in the small "t" before load, or transform fully before load |
| Small, stable reporting feed with fixed outputs | ETL | The extra landing layer and its storage are not worth it |
| Business rules change often | EtLT or ELT | Rules run after load, so no source re-extraction is needed |
When not to use EtLT: skip it when sources are already clean, when the team cannot keep the "t" genuinely light, or when the target cannot hold raw history for cost or policy reasons. Retaining raw data has a storage cost and, as design guidance, a governance cost, because every retained field needs an owner and a retention rule. For streaming design patterns see real-time streaming with Apache Spark.
How do you build an EtLT pipeline with Kafka, Spark and Delta Lake?
The example below uses Spark Structured Streaming to read from Kafka, apply a light transform, write to a Delta table, and then run a business aggregation. Treat it as a pattern, not production code; the Spark Kafka connector and the Delta Lake package must be on the cluster classpath.
Step 1: Extract from Kafka
The Spark Kafka source needs kafka.bootstrap.servers and exactly one of assign, subscribe or subscribePattern. Each row carries key and value as binary, plus topic, partition, offset and timestamp. Per the Spark documentation, startingOffsets defaults to "latest" for streaming queries, so set "earliest" if you need history.
df = (spark.readStream
    .format("kafka")
    .option("kafka.bootstrap.servers", "localhost:9092")
    .option("subscribe", "topic_name")
    .load())
Step 2: Apply the light transform
Cast the binary columns, parse the fields you need, and drop records that cannot be parsed. Nothing here depends on a business definition.
from pyspark.sql.functions import get_json_object

light_df = (df.selectExpr("CAST(value AS STRING) AS raw", "timestamp")
    .withColumn("user_id", get_json_object("raw", "$.user_id"))
    .where("user_id IS NOT NULL"))
Step 3: Load into Delta Lake
Streams write to Delta in append mode, and you set a checkpointLocation. The Delta Lake documentation states that the transaction log guarantees exactly-once processing, even when other streams or batch jobs write to the same table. Overwrite mode would replace the table on each batch, so it is not the right choice here.
(light_df.writeStream
    .format("delta")
    .outputMode("append")
    .option("checkpointLocation", "/mnt/delta/_checkpoints/events")
    .start("/mnt/delta/events"))
Step 4: Apply the final transform
Run business logic on the stored table, for example the number of actions per user.
final_df = spark.sql("""
    SELECT user_id, COUNT(*) AS action_count
    FROM delta.`/mnt/delta/events`
    GROUP BY user_id
""")
Video: ingestion, processing and architecture layers for big data and IoT.
What has changed in EtLT thinking and tooling?
| Topic | Current position | Source |
|---|---|---|
| Naming | EtLT is a practitioner term, described in 2023 as splitting ETL and ELT and combining real-time and batch processing; it is not a formal standard | HackerNoon article (as reported by) |
| ELT | Described by Databricks as a modern approach for cloud-native analytics platforms | Databricks glossary |
| Spark | Spark documentation currently lists release 4.3.0 with the Kafka connector at the same version | Apache Spark docs |
| Delta Lake | One table serves as batch table, streaming source and streaming sink, with ACID transactions on Spark | Delta Lake docs |
How do governance, security and cost apply to EtLT?
As design guidance, the small "t" is the right place for field-level controls, because data that is dropped or masked before load never reaches the lakehouse. Access control, lineage and retention then apply to the loaded tables. Cost follows from retaining raw history: you pay for storage and for recomputation when rules change, and you save the cost of re-extracting from source systems.
Governing the decisions made on top of the pipeline is a separate layer. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents.
How do you adopt EtLT in a sensible sequence?
- Pick one pipeline with mixed sources or frequent rule changes, not the whole estate.
- Write the "t" rule list: casts, parsing, malformed-record handling, masking. Anything else goes to "T".
- Land in a table format that supports streaming and batch, such as Delta Lake, with checkpoints.
- Version the "T" logic in code with tests.
- Serve results to analysts and agents and review the pattern after one quarter.
Once the loaded tables are stable, AgentAnalyst lets teams ask questions of enterprise data in plain language and get real-time insights. Our big data architecture guide shows where the pipeline sits in the wider platform.
To map one decision your data pipeline feeds, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
FAQ
What does the lowercase t in EtLT mean?
It is the light transformation done before load: casting types, parsing, filtering malformed records and standardising formats. Business logic is left for the capital T after load.
How is EtLT different from ELT?
ELT loads raw or near-raw data and transforms everything afterwards. EtLT adds a small, source-facing step before load, so the landing zone is already structured and sensitive fields can be dropped or masked.
Does EtLT support both streaming and batch?
Yes. The example in this post reads a Kafka stream with Spark Structured Streaming and writes to Delta Lake, where the same table can also be queried in batch.
Why not use overwrite mode when streaming into Delta Lake?
Overwrite replaces the table contents on each batch. Streams normally use append mode with a checkpoint location, and the Delta transaction log provides exactly-once processing.
When should we not use EtLT?
When sources are already clean, when the target cannot hold raw history, or when the team cannot keep the pre-load step light. In those cases ELT or ETL is simpler.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE