Key takeaway
- AI agent observability and evaluation tools compared: what to measure, how Langfuse, DeepEval and Galileo differ, and a sequence for adopting them.
AI agent observability records what an agent actually did in production: each model call, tool call and decision, with its cost and latency. AI agent evaluation scores whether that behaviour was correct before release and again on live traffic. You need both, because an agent that passes a test set can still fail on real data, real integrations and real load.
This guide is for CTOs, heads of engineering, platform leads and solution architects who must choose tooling and decide who owns agent quality. It covers what to measure, how the main tools differ, where the standards are still moving, and a sequence for adopting them. It builds on our observability services and on the wider question of why enterprise agent pilots stall before production.
How do AI agent observability and evaluation differ?
Evaluation is a controlled check of capability. Observability is continuous measurement of behaviour. Microsoft describes observability for generative AI as the ability to "monitor, understand, and troubleshoot AI systems throughout their lifecycle", and places evaluation, monitoring and tracing inside it (Microsoft Learn, updated 17 October 2026).
| Question | Evaluation answers | Observability answers |
|---|---|---|
| When it runs | Before release, after every prompt, tool or model change, and on sampled live traffic | Continuously in production |
| What it needs | Test cases, scoring criteria, a judge model or deterministic checks | Traces, metrics and logs from the running agent |
| Typical finding | The agent chose the wrong tool for a class of tasks | One tool call accounts for most of the latency or cost |
| Owner | Product and AI engineering | Platform, SRE and AI engineering |
What should an enterprise measure for production agents?
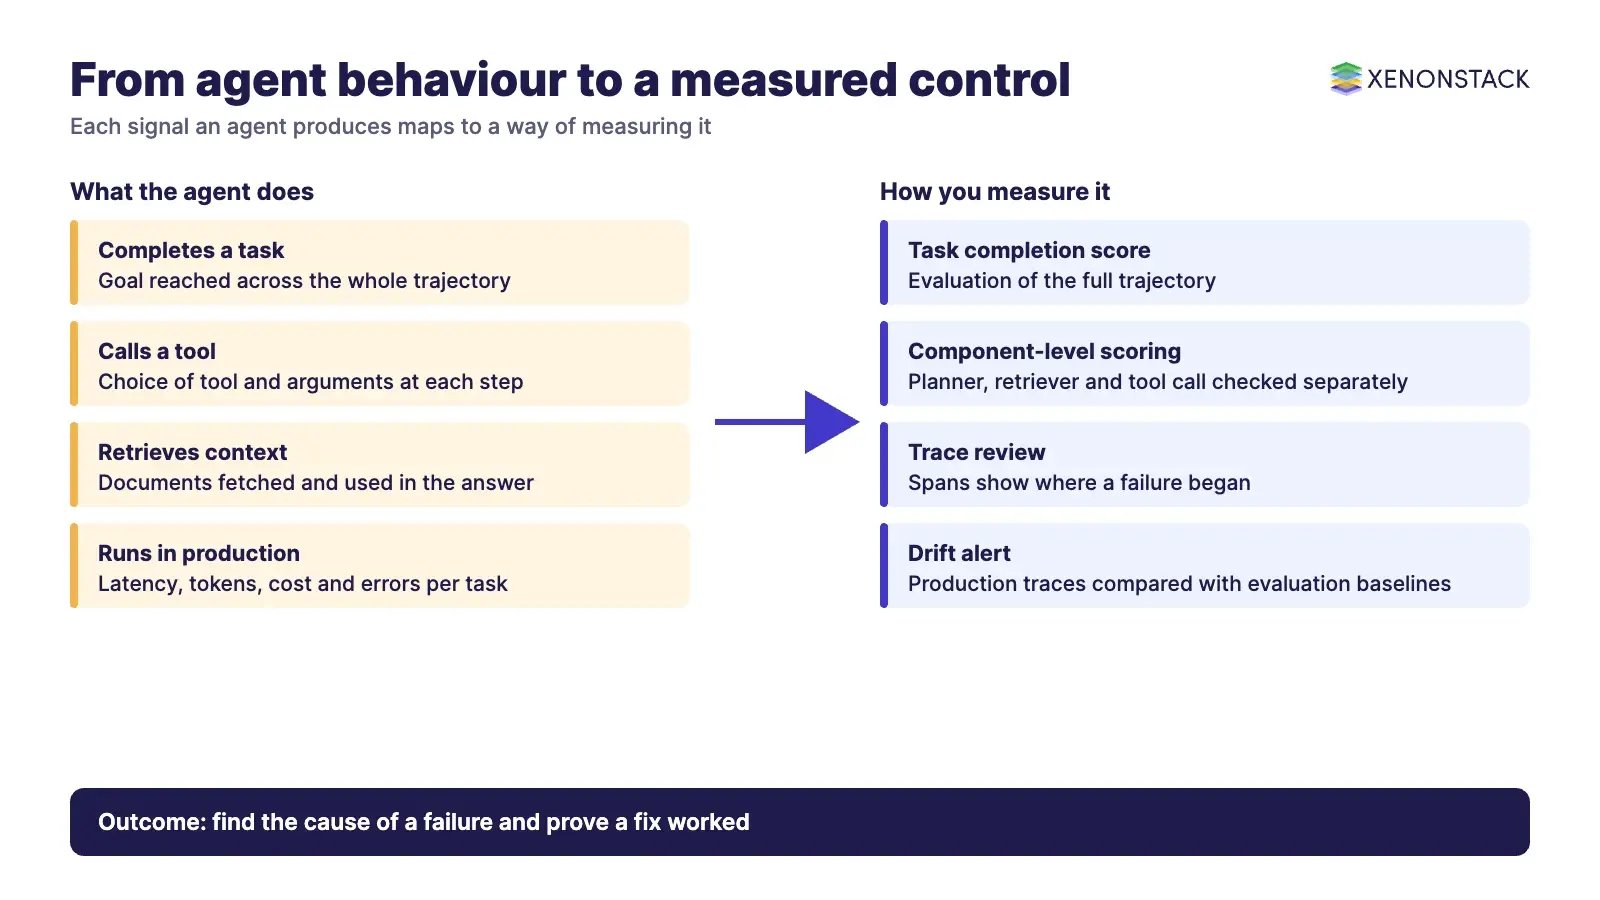
A single LLM call is one span in a longer chain of decisions, so measure at three levels: the whole task, each step, and the platform underneath. Set the thresholds yourself from your own service levels and user tolerance. Published targets differ by use case, so treat any fixed number as a starting point to test, not a standard.
| Level | Signals to track | Why it matters |
|---|---|---|
| Task | Task completion, hallucination rate, consistency across repeated inputs | Shows whether the agent achieved the goal |
| Step | Tool choice and tool arguments, retrieval quality, context kept across turns | Locates where a failure started |
| Platform | Latency, token use, cost per task, error and timeout rates | Links agent behaviour to infrastructure and budget |
| Governance | Which policy applied, who approved, what was blocked or escalated | Gives audit and risk teams evidence |
Why is explainability part of observability?
When a multi-agent system fails, the question is which agent misread which context. A trace that stores the intermediate steps answers that. Without it, engineers debug from the final answer alone, and risk teams cannot show how a decision was reached.
Which tools support AI agent observability and evaluation?
The table uses only what each vendor says on its own pages, read on 12 November 2026. Check current licensing, hosting options and pricing with the vendor before you commit.
| Tool | What its own page states | When it fits |
|---|---|---|
| Langfuse | Open source tracing and observability for LLM apps; logs prompts, replies, token use, latency and tool or retrieval steps; can be self-hosted; offers scores and LLM-as-a-judge evaluation | You want trace-level debugging and may need to self-host |
| DeepEval | Open source (Apache 2.0) framework for testing AI agents; task completion scored over the full trajectory; component-level scoring of planners, retrievers and tool calls | You want evaluation in your own test pipeline |
| Confident AI | Per the DeepEval page, an optional companion platform that adds production trace, span and thread evaluation | You already use DeepEval and want a hosted production layer |
| Galileo | Evaluators for RAG, agents, safety and security, plus observability and guardrails that can govern agent actions | You want evaluation results to feed runtime guardrails |
| Microsoft Foundry | Built-in agent evaluators (tool call accuracy, task completion), tracing on OpenTelemetry standards, dashboards through Application Insights, CI/CD quality gates | Your agents already run on Azure |
Two naming notes. Microsoft's current documentation uses "Microsoft Foundry", where earlier material said "Azure AI Foundry". The framework this post previously called "OpenDeepeval" is named DeepEval on its own site.
How do you choose between them?
Start from where the gap is. If you cannot see what agents do, begin with tracing. If you cannot say whether a change made agents better, begin with evaluation. Most teams need both within a quarter, so prefer tools that share trace data rather than two disconnected stores. Whatever you choose, keep the evaluator that judges an agent separate from the model that powers it, and have people review a sample of judged cases.
How do dashboards and standards fit together?
The useful pattern is one view that overlays evaluation scores on runtime traces, so drift shows up as a gap between expected and actual behaviour. Microsoft documents this in Foundry with continuous evaluation on sampled production traffic and alerts when outputs miss quality thresholds. In Kubernetes estates, link agent metrics to infrastructure metrics so scaling decisions reflect agent workload.
Standards are still settling. The OpenTelemetry GenAI semantic conventions, which define spans, metrics and events for GenAI clients, have moved to their own repository, and that repository does not state a stability level. Use OpenTelemetry for transport, pin the convention version you adopt, and expect attribute names to change.
What has changed since this post was first written?
- Foundry naming: Microsoft now documents "Microsoft Foundry", with agent evaluators and OpenTelemetry-based tracing.
- OpenTelemetry GenAI conventions now live in a dedicated repository.
- Evaluation frameworks now score agent trajectories and individual components, not only final answers.
- Unsupported figures from the earlier version, such as fixed latency targets and example accuracy percentages, have been removed.
What is a sensible adoption sequence?
- Define what good means. Agree task success criteria and service levels with the business owner.
- Instrument. Emit traces for model calls, tool calls and retrieval from the first prototype.
- Build a test set. Draw cases from real tasks and failures, and re-run it after every prompt, tool or model change.
- Connect the two. Compare evaluation scores with production traces and alert on drift.
- Add controls. Route high-risk actions through policy checks and approvals, with a decision trail.
What are the trade-offs and when should you hold back?
- Traces contain prompts and outputs, so apply the same retention, masking and access rules as for any sensitive data.
- LLM judges add cost and can be wrong, so calibrate them against human review.
- Do not add a platform before you know which question it must answer. A small test set and basic tracing often come first.
- Observability shows what happened. It does not decide what an agent is allowed to do, which needs policy and approval controls.
For testing agents against realistic workflows and tracking quality over time, see AgentEvaluation, which tests and scores enterprise AI agents before and after launch. For decision traces and governed context above your agents, see ElixirData Context OS, which keeps governed context, versioned policy and decision traces in one decision layer above AI agents. To build and orchestrate the agents themselves, ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control. Related reading: DevOps automation tools.
To map one agent decision you need to evaluate, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is AI agent observability?
It is the practice of recording and analysing what an agent does in production, including model calls, tool calls, latency and cost, so failures can be traced to a cause.
How is evaluation different from monitoring?
Evaluation scores correctness against test cases or criteria, before release and on sampled live traffic. Monitoring watches operational signals continuously.
Do I need an LLM judge?
Often, for open-ended outputs. Deterministic checks suit structured results. Calibrate any judge against human review.
Which tool should we start with?
Start from your gap. Tracing tools such as Langfuse help when you cannot see behaviour. Evaluation frameworks such as DeepEval help when you cannot measure change.
Is OpenTelemetry enough for agent telemetry?
It is a sound transport and data model, but the GenAI conventions do not state a stability level, so pin versions and plan for change.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE