Key takeaway
- Apache Zeppelin explained: features, install and Docker steps for 0.12.1, interpreters, Shiro security and how ModelDB fits into model tracking.
What is Apache Zeppelin?
Apache Zeppelin is an open-source, web-based notebook for data analytics. According to its site, it supports SQL, Scala, Python, R and other languages, and one notebook can hold ingestion, exploration, visualisation and analysis steps side by side.
For enterprise teams, the draw is a shared workspace on top of engines such as Spark, Flink and JDBC sources. The catch is governance: a notebook is easy to share and just as easy to leave open. This guide covers features, installation, interpreters, security and where model tracking fits. If you are new to Spark, start with Spark RDD: What Is RDD and When to Use It in Spark 4.
What are the features of Apache Zeppelin?
The Zeppelin home page lists these capabilities, as read on 13 November 2026:
| Feature | What it means in practice |
|---|---|
| Interpreters | More than 20 interpreters, including Spark (Spark SQL, PySpark, SparkR), JDBC, Python, Flink, R, Markdown, Shell and Neo4j. |
| Built-in Spark integration | SparkContext and SQLContext are injected automatically. |
| Visualisation | Six built-in visualisations plus pivot charts with drag-and-drop aggregation. |
| Dynamic forms and sharing | Parameter forms in notes, real-time notebook sharing, and paragraph results that can be embedded as an iframe. |
| Multi-user support | Authentication through realms such as LDAP, set up in Apache Shiro. |
| Licence | Apache 2 licensed, open source. |
Ingestion, discovery and analysis all happen through interpreters, so the same notebook can query a Hive or PostgreSQL source through JDBC and then analyse the result in Spark or Python. For the pipeline stage that feeds a notebook, see Data Ingestion: Tools, Architecture and Pipelines.
Which Zeppelin version should you install?
The download page lists Apache Zeppelin 0.12.1, released on 12 June 2026, as the latest stable release. According to the project, 0.12.1 includes security fixes for JWT validation, path traversal hardening and a WebSocket memory leak. Older versions, such as the 0.7.2 image used in earlier guides, should not be used.
| Package | What it contains | When it fits |
|---|---|---|
| bin-all | All interpreters (about 706 MB) | Ready to use after unpacking. |
| bin-netinst | Spark interpreter and an install script for the others (about 515 MB) | Smaller install; add interpreters with bin/install-interpreter.sh. |
| Source | zeppelin-0.12.1.tgz (about 11 MB) | Building from source. |
| Docker | apache/zeppelin:0.12.1 on port 8080 | Quick trials and containerised deployment. |
Verify every download against the PGP or SHA-512 signatures and the KEYS file published on the download page.
How do you install Apache Zeppelin?
The install guide (written for 0.12.0) lists JDK 11 with JAVA_HOME set, on Mac OS X or Ubuntu. Confirm the Java version for your release on the current install page before you start.
- Download a binary package from the download page.
- Add interpreters if you chose the net-install package:
./bin/install-interpreter.sh --all. - Start the server with
bin/zeppelin-daemon.sh startand openhttp://localhost:8080. Stop it withbin/zeppelin-daemon.sh stop. - Check the logs in
ZEPPELIN_HOME/logs/zeppelin-server-*.logif the interface does not load.
Zeppelin listens on 127.0.0.1 by default. For remote access, set zeppelin.server.addr to 0.0.0.0 in conf/zeppelin-site.xml, and only after authentication is in place (see the security section below).
How do you run Zeppelin in Docker?
Start the container with docker run -p 8080:8080 --rm --name zeppelin apache/zeppelin:0.12.1, then open localhost:8080. Without volumes, notebooks stay inside the container and disappear with it. To keep them, mount the logs and notebook directories and set the matching environment variables:
docker run -u $(id -u) -p 8080:8080 --rm -v $PWD/logs:/logs -v $PWD/notebook:/notebook -e ZEPPELIN_LOG_DIR='/logs' -e ZEPPELIN_NOTEBOOK_DIR='/notebook' --name zeppelin apache/zeppelin:0.12.1
Interpreters such as Spark and Flink need their own distributions mounted, with SPARK_HOME and FLINK_HOME set. If the page does not load, the project suggests clearing the browser cache.
What is a Zeppelin interpreter?
An interpreter is a plug-in that lets Zeppelin use a specific language or data-processing backend. A paragraph chooses one with a prefix such as %spark for Scala or %spark.pyspark for PySpark. Interpreters in the same group, for example the Spark group, run in one JVM.
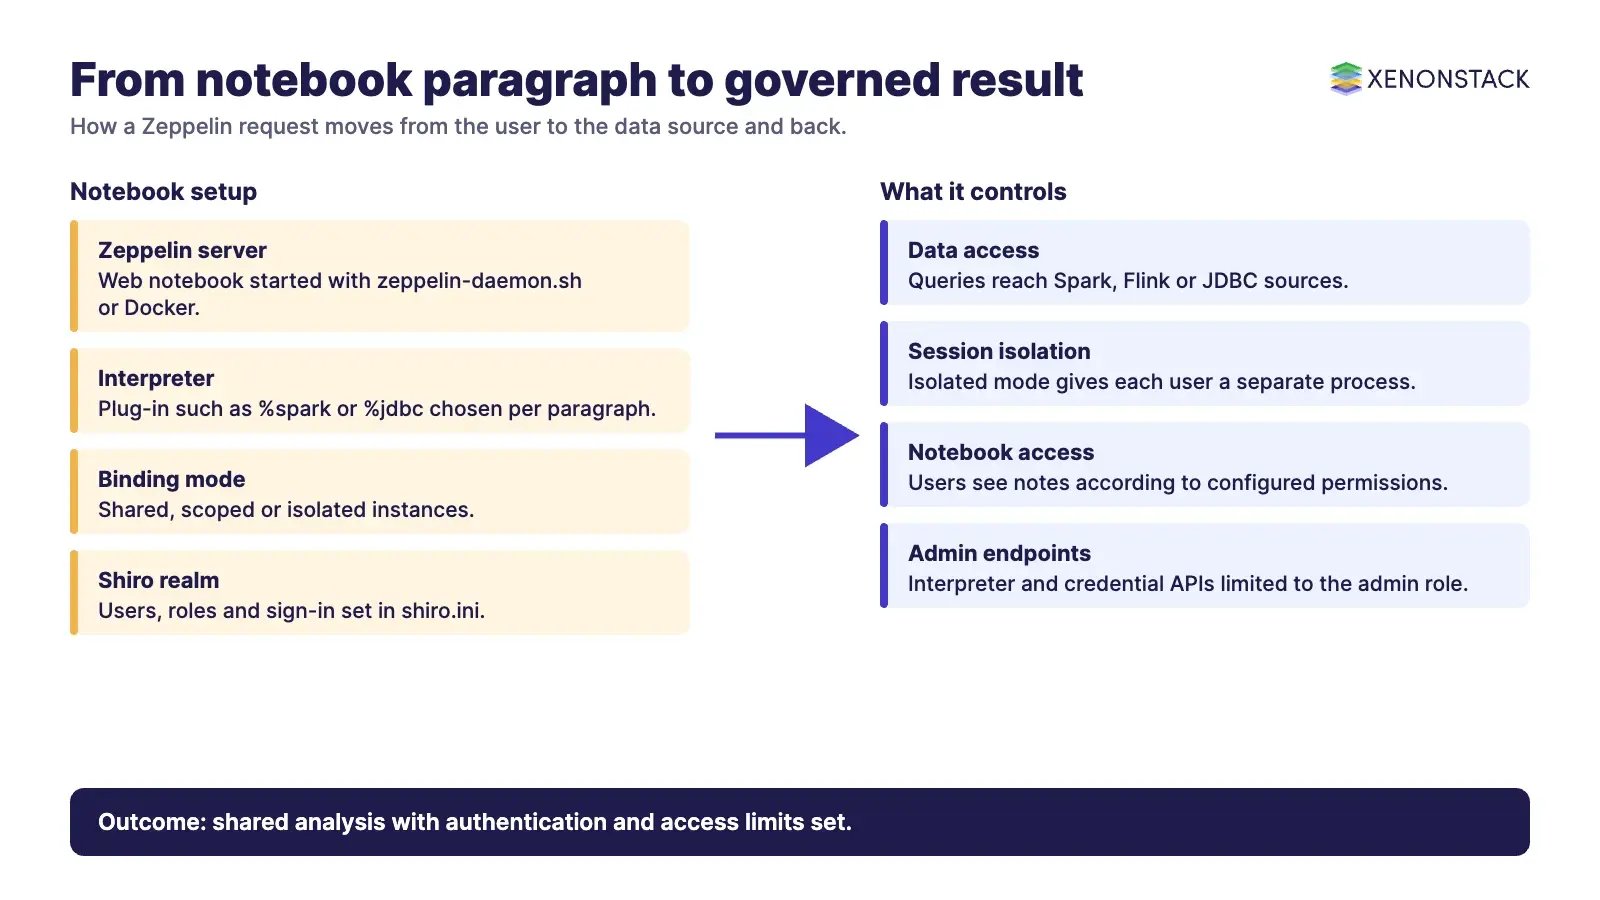
Interpreter settings hold the server-side configuration, such as the properties needed to reach a Hive server or a database. The binding mode decides how instances are shared:
| Binding mode | Behaviour | When it fits |
|---|---|---|
| Shared | All notes and users share one interpreter instance. | Single-user or trusted team work. |
| Scoped | Each user or note gets its own instance, in the same process. | Separate sessions without the cost of extra processes. |
| Isolated | Each user or note gets its own interpreter process. | Stronger separation between users or heavy jobs. |
How do you connect Zeppelin to PostgreSQL or other databases?
Open the interpreter page, press edit on the JDBC or PostgreSQL interpreter and fill in the connection properties, such as the URL, user and password. Zeppelin lists PostgreSQL/HAWQ as an available interpreter. Apache HAWQ itself was retired to the Apache Attic in July 2024, so use the PostgreSQL interpreter for PostgreSQL and choose a maintained engine for new analytics work.
How do you load, explore and visualise data in a notebook?
Use the Spark interpreter to read a CSV file into a data frame, inspect it with show, register it as a temporary view and query it with SQL in a separate paragraph. Zeppelin then lets you switch the same result between table, bar, line, pie, area and scatter views. For tool choices beyond notebooks, see Data Visualization Tools and Techniques, and for tuning heavy Spark jobs see Apache Spark Optimization Techniques.
How does ModelDB help manage models built in notebooks?
Once a notebook produces dozens of models with different parameters and datasets, results get lost. ModelDB is an open-source system, under the Apache 2.0 licence, for versioning machine learning models with their code, data, configuration and environment, and tracking their metadata. According to its GitHub page, it is now maintained by Verta.ai and has Python and Scala clients. It is a separate project, not part of Zeppelin.
| Need | What a registry gives you |
|---|---|
| Tracking experiments | Hyperparameters, data sources and metrics logged per run. |
| Versioning models | Models stored with the code, data and environment that produced them. |
| Reproducibility | Re-run a past result from its recorded configuration. |
| Collaboration | Dashboards for comparing runs across a team. |
Check the ModelDB repository for current activity before you adopt it, because the page gives no recent release dates. Teams that already use another experiment tracker can keep it and use Zeppelin only for exploration.
How do you secure Zeppelin for enterprise use?
According to the Zeppelin security documentation, anonymous access is allowed by default, and the project strongly recommends enabling Shiro authentication or deploying Zeppelin only where it is secured and trusted. Users, passwords and roles live in conf/shiro.ini (copy it from shiro.ini.template and restart). For enterprise sign-in, Shiro supports realms such as LDAP, Active Directory, PAM, Knox SSO and Kerberos SPNEGO, and the default password realm must be disabled when you use them.
| Control | What the documentation says | Action |
|---|---|---|
| Authentication | Anonymous access is the default. | Configure Shiro before any shared deployment. |
| Notebook access | Once logged in, a user can access all notes, including other users' notes, by default. | Review the notebook authorisation page before sharing sensitive notebooks. |
| Admin endpoints | The [urls] section can limit /api/interpreter/**, /api/configurations/** and /api/credential/** to the admin role. | Restrict these to administrators. |
| Cookies | The HttpOnly flag helps block client-side script access to cookies. | Enable it in shiro.ini. |
| Network | Zeppelin listens on 127.0.0.1 unless you change it. | Keep it behind a trusted network or gateway. |
Governed data access matters as much as notebook access. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents, and AgentAnalyst lets teams ask questions of enterprise data in plain language and get real-time insights.
When is Zeppelin the right choice, and when not?
| Situation | Fit |
|---|---|
| Shared exploration on Spark, Flink or JDBC sources with SQL and Python together | Good fit |
| Teams that need a self-hosted, Apache-licensed notebook | Good fit |
| Anonymous, internet-exposed notebook with sensitive data | Poor fit until authentication and network controls are in place |
| Experiment and model lifecycle tracking | Pair with a model registry rather than relying on notebooks alone |
| Running a notebook platform without in-house operations time | Consider managed services |
If you prefer not to run it yourself, see our Apache Zeppelin managed services.
To map one analytics decision your teams and agents make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
FAQ
What is Apache Zeppelin used for?
Apache Zeppelin is a web-based notebook for data analytics and collaborative documents. According to its site, it supports SQL, Scala, Python, R and other languages, so teams can ingest, explore, visualise and share data in one place.
Is Apache Zeppelin free?
Yes. According to its site, Zeppelin is open source under the Apache 2 licence.
What is a Zeppelin interpreter?
An interpreter is a plug-in that lets Zeppelin use a specific language or data-processing backend. A paragraph names its interpreter, for example %spark.pyspark, and the interpreter settings hold the server-side configuration such as connection properties.
Is Zeppelin secure by default?
No. The security documentation says Zeppelin allows anonymous access by default and strongly recommends setting up Apache Shiro authentication, or deploying it only where it is secured and trusted.
How do I keep notebooks when running Zeppelin in Docker?
Mount volumes for the logs and notebook directories and set ZEPPELIN_LOG_DIR and ZEPPELIN_NOTEBOOK_DIR. Without mounts, notebooks stay inside the container.
Does Zeppelin replace a model registry such as ModelDB?
No. Zeppelin is the notebook where you explore and model. ModelDB is a separate open-source system for versioning models and tracking their metadata, now maintained by Verta.ai according to its GitHub page.
Ready to put AI agents to work? See an ElixirClaw demo: the agentic OS to build, orchestrate and govern AI agents across your enterprise systems.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE