Key takeaway
- Edge AI architecture for architects: the five layers, how to pick a runtime, the cloud and edge split, security, trade-offs and a 3 to 5 year outlook.
Edge AI architecture is the set of layers that lets trained models run close to where data is produced: devices and sensors, edge gateways, a model runtime, an orchestration layer and a cloud back end for training and fleet management. It scales when each layer can be repeated, updated and monitored without hand work on every site. For a first view of the use cases, see Edge AI with Agentic AI for Distributed Intelligence.
This guide is for architects and platform leads who must move from one working pilot to many sites. It covers the layers, the choice of runtime, the cloud and edge split, security and governance, trade-offs, and what is likely to change over the next three to five years. It stays distinct from our guides to edge computing and cloud versus edge for vision workloads, which cover the wider topic and the hardware choice.
What is edge AI architecture, and how does it differ from cloud AI?
Edge computing places computation and storage close to the devices that produce the data. Edge AI adds trained models, so inference runs on a device, a gateway or a nearby server instead of a distant data centre. The architecture is the design that connects those pieces to the cloud, where training, fleet management and long-term storage usually stay.
The difference from a cloud-only design is where the decision is made and what travels over the network. A cloud design sends raw data out and waits for an answer. An edge design sends events, summaries or model updates, and keeps the time-critical decision local. According to the ONNX Runtime documentation, on-device inference can give faster inference, better privacy because data stays on the device, offline operation and lower cloud serving costs, and it also requires models small enough for less powerful hardware.
What are the layers of a scalable edge AI architecture?
A scalable design treats five layers as separate concerns, so one can change without rebuilding the others. The table gives the job of each layer and the scaling question it must answer.
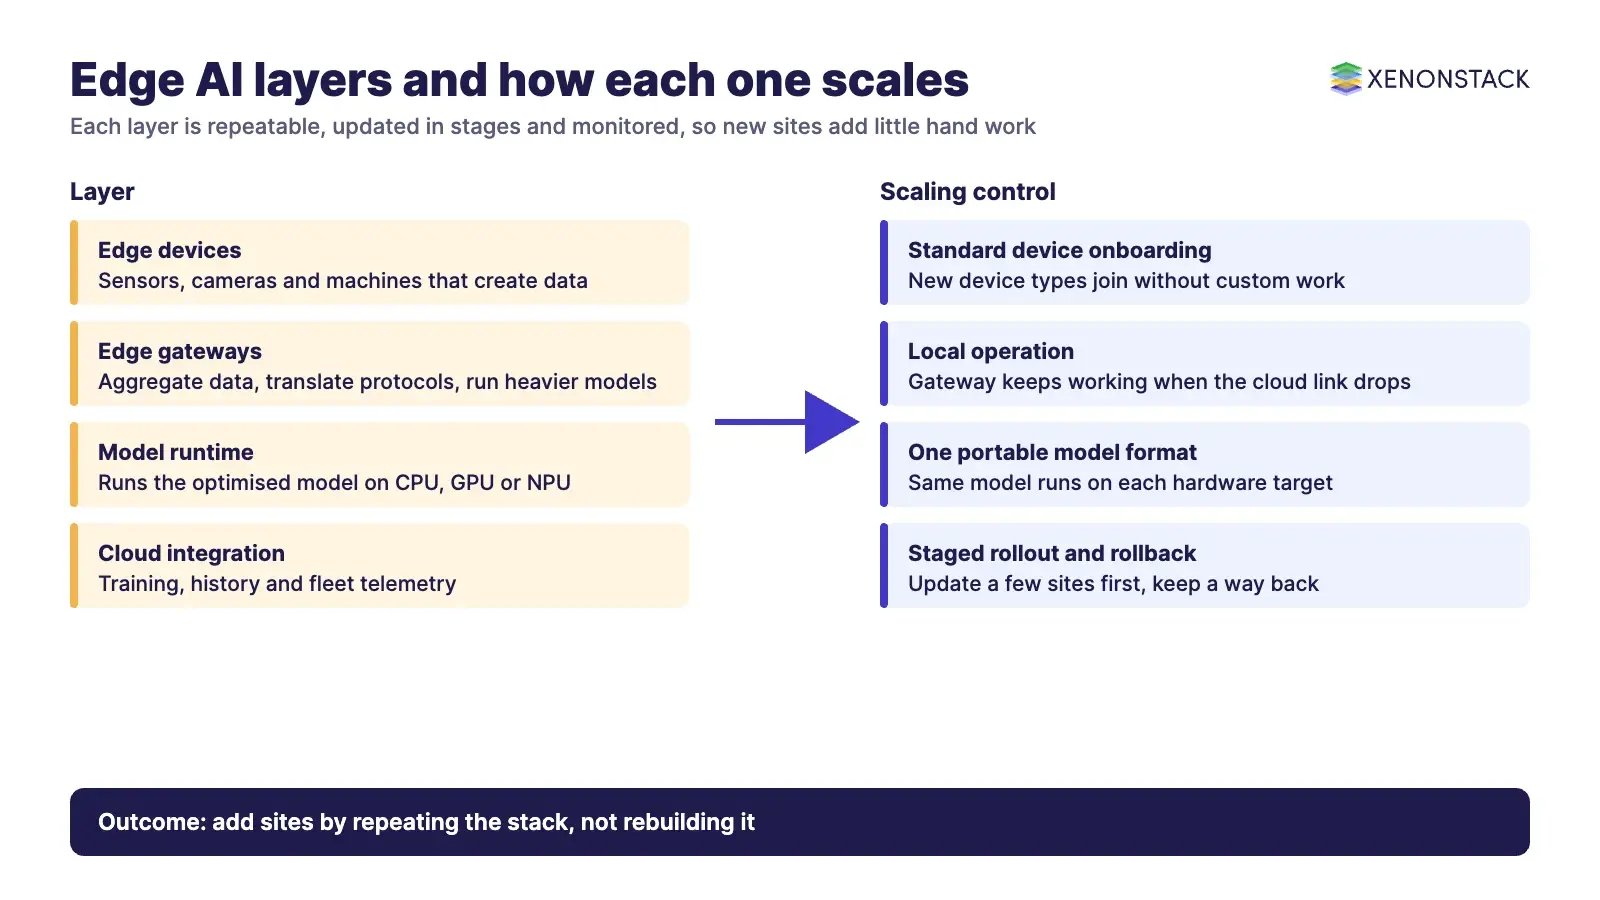
| Layer | What it does | Scaling question |
|---|---|---|
| Edge devices | Sensors, cameras, machines and phones that create data and sometimes run small models | Can a new device type join without a custom integration? |
| Edge gateways | Aggregate data, translate protocols, run heavier models and enforce local security | Can the gateway keep working when the link to the cloud drops? |
| Model runtime | Runs the optimised model on the available CPU, GPU or NPU | Does one model format run on every hardware target you buy? |
| Orchestration and management | Deploys models and software, tracks device health and applies updates in stages | Can you roll back a bad model on one site without touching the rest? |
| Cloud integration | Trains and evaluates models, stores history and collects fleet telemetry | Which data returns to the cloud, and which never leaves the site? |
Edge devices and gateways
Devices set the limits on compute, memory, power and connectivity, so they decide which models are practical. Gateways sit between devices and the cloud. They collect data from many devices, translate between protocols and apply security controls before data moves on. Keeping a heavier model on the gateway often avoids putting expensive hardware on every device.
Orchestration and the cloud
Orchestration decides which model version runs where, and reports whether it is healthy. Container platforms such as Kubernetes, described on its site as an open source platform for managing containerised workloads and services, are one way to do this on gateways and edge servers; smaller devices may need a lighter device-management agent. The pattern for packaging services is covered in our guide to microservices at the edge, and the operating model in platform engineering for edge computing.
Which runtime should run models at the edge?
The runtime converts a trained model into something a constrained device can run efficiently. The three runtimes below are documented by their own projects; check each page for the platforms and accelerators supported by the release you plan to use.
| Runtime | What its own page says | When it fits |
|---|---|---|
| LiteRT | Described as formerly TensorFlow Lite and as Google's framework for running ML and generative AI models on-device, with CPU, GPU and NPU acceleration; supported platforms listed as Android, iOS, Web, Linux, macOS and Windows | Teams that train in TensorFlow or Keras, or ship to Android and iOS |
| ExecuTorch | Described as PyTorch's solution for efficient AI inference on edge devices, from mobile phones to embedded systems, with acceleration on CPU, GPU, NPU and DSP | Teams that train in PyTorch and want one path to the device |
| ONNX Runtime | Described as able to deploy to many IoT and edge devices; examples include Raspberry Pi, Jetson Nano and an Intel VPU through OpenVINO | Mixed training frameworks or mixed hardware fleets |
Whichever you choose, plan model optimisation (for example quantisation) as part of the release pipeline, and test accuracy on the target hardware, not only on a workstation. Framework names and product status change, so confirm on each project page before you commit.
Which workloads belong at the edge and which in the cloud?
Place each workload by the constraint that matters most, not by habit. The table is a starting rule, and each row should be tested against your own latency, bandwidth and data-residency needs.
| Workload | Usually runs at | Why |
|---|---|---|
| Real-time inference for a local control decision | Device or gateway | The decision must not wait for a network round trip |
| Video or sensor pre-filtering | Gateway or edge server | Only events or summaries need to leave the site |
| Model training and large evaluation runs | Cloud | Needs elastic compute and the full history |
| Fleet analytics and model monitoring | Cloud | Needs data from every site in one place |
| Data that must stay in a site or country | Edge, with approved summaries only | Residency and privacy rules limit what may move |
The same split appears in IoT edge analytics, where the question is which analysis happens near the sensor and which is centralised.
How do you scale edge AI from one pilot to many sites?
Pilots fail to scale for operational reasons more often than model reasons. A workable adoption sequence is:
Fix the decision first. Name one decision, its latency need and the data it depends on.
Standardise the stack. Choose one runtime, one packaging format and one device-management approach.
Roll out in stages. Update a small group of devices first, watch the results, then widen.
Monitor the model, not only the device. Track input drift and decision quality, and keep a rollback path.
Record decisions. Keep the model version, inputs and policy that produced each action so it can be reviewed.
Edge decisions taken by AI agents need governed context as well as fast inference. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents, and ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control. For physical deployments, NexaStack is an agentic operating platform for physical AI that runs across on-premises, cloud and hybrid environments.
How do you secure and govern edge AI?
Edge devices sit outside the data centre, so they need their own controls. NIST SP 800-213, published by NIST in November 2021, helps organisations set device cybersecurity requirements by looking at security from the device's perspective. It is written for federal agencies, but the approach of stating what you expect from a device and its manufacturer applies to any fleet. Practical controls to ask for are:
Signed model and software updates, with a tested rollback.
A unique identity for each device, and revocation when a device is lost.
Encryption of data in transit, and of data at rest where devices can be stolen.
Logs of model version, input source and action, sent to a central store.
On regulation, the European Commission AI Act page states that the EU AI Act entered into force on 1 August 2024, applies generally from 2 August 2026 with some exceptions, and that high-risk obligations for Annex III use cases (such as biometrics and critical infrastructure) now apply from 2 December 2027, and for systems embedded in regulated products from 2 August 2028. This is not legal advice; confirm dates and your risk class on the official page. Agent actions that need policy checks and an audit trail can be kept inside policy with AgentGRC, which keeps autonomous agent actions inside policy with the audit trail risk teams need.
What are the trade-offs, and when should you not use edge AI?
| Trade-off | What to weigh |
|---|---|
| Latency and bandwidth versus fleet effort | Local inference removes the round trip, but every site adds devices to patch, monitor and replace |
| Privacy versus visibility | Data stays on site, but central teams see less unless summaries and logs are designed in |
| Model size versus accuracy | Smaller models fit the device, and may lose accuracy; test on target hardware |
| Hardware choice versus lock-in | Accelerators speed up inference, but model formats and toolchains differ between them |
Do not move a workload to the edge if a cloud round trip is fast enough, if the data is not sensitive, or if you cannot staff updates and monitoring for the fleet. A single site with relaxed latency needs is often better served by a nearby server than by intelligence in every device.
What will change in edge AI architecture over the next 3 to 5 years?
The sourced signals below point to standard interfaces, on-device runtimes that use NPUs, and firm regulatory dates. They are signals from the named pages, not forecasts of market size.
| Signal | Source and what it says | What it means for architecture |
|---|---|---|
| Standardised edge platforms | ETSI states its MEC group is standardising an open environment for integrating applications from infrastructure and edge providers, and announced its Phase 4 specifications on 31 October 2025 | Design for open interfaces so workloads can move between edge providers |
| Generative AI on device | LiteRT describes running ML and generative AI models on-device; ExecuTorch lists NPU and DSP acceleration | Plan for NPU-aware model packaging, and test each hardware target |
| Broader device coverage | ONNX Runtime describes deployment to many IoT and edge devices | Keep a portable model format to limit hardware lock-in |
| Fixed regulatory dates | The European Commission AI Act page lists 2 August 2026 for general application and 2 December 2027 and 2 August 2028 for high-risk systems | Build decision logging and risk classification into the platform now |
Our own related outlooks are in edge computing, edge AI in manufacturing and IoT edge analytics.
To map one edge decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is edge AI architecture?
Edge AI architecture is the design that lets trained models run near where data is produced. It connects devices, gateways, a model runtime, orchestration and a cloud back end, so inference happens locally while training and fleet management usually stay in the cloud.
Which runtimes can run models on edge devices?
LiteRT (formerly TensorFlow Lite), ExecuTorch and ONNX Runtime are three documented options. According to their own pages, LiteRT runs models on-device with CPU, GPU and NPU acceleration, ExecuTorch targets edge devices from phones to embedded systems, and ONNX Runtime deploys to many IoT and edge devices. Confirm platform support for your release.
How does edge AI scale across many sites?
It scales when each layer is repeatable: one runtime, one packaging format, staged rollouts, model monitoring and a rollback path. The effort per site depends on how well updates, device identity and logging are automated.
How do you secure edge AI devices?
Treat each device as outside the data centre. NIST SP 800-213 helps organisations set device cybersecurity requirements. Typical controls are signed updates, unique device identity, encryption and central logs of model version, input and action.
When should you not use edge AI?
Avoid it when a cloud round trip is fast enough, when the data is not sensitive, or when you cannot staff updates and monitoring for the fleet. In those cases a cloud or nearby-server design is simpler to run.
What will change in edge AI architecture over the next 3 to 5 years?
The sourced signals are standardised edge platforms (ETSI announced MEC Phase 4 specifications on 31 October 2025), on-device generative AI runtimes with NPU acceleration, and fixed EU AI Act dates (general application from 2 August 2026, with high-risk dates of 2 December 2027 and 2 August 2028). Confirm each on the official page.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE