Key takeaway
- Understand data discovery, its six stages, key use cases and how catalog, analytics and sensitive-data tools differ, plus how AI agents help.
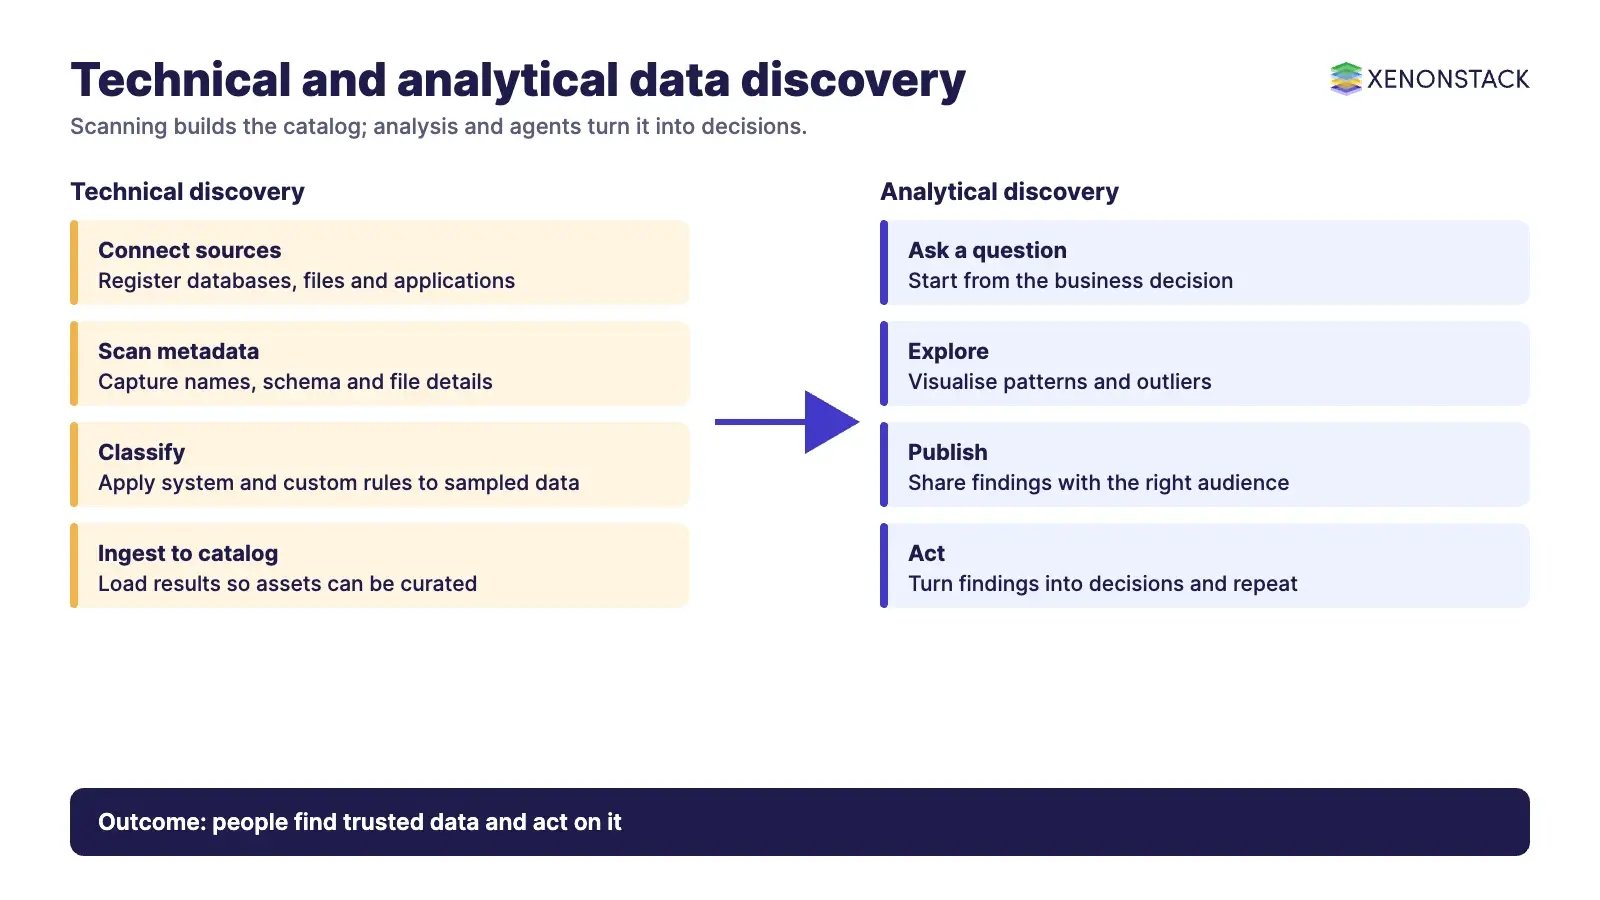
Data discovery is the process of finding, profiling and understanding the data an organisation holds, so people and systems know what exists, where it lives, what it means and who may use it. It covers two related jobs: technical discovery, which scans sources and records metadata, and analytical discovery, which lets people explore data visually to find patterns.
This guide is for data leaders, analysts and governance teams choosing an approach and tools. It covers the stages of discovery, the main use cases, how tool categories differ, how scanning works in practice, and how AI agents change the work. It sits alongside augmented data management solutions and data quality management.
Why does data discovery matter?
Teams cannot govern, secure or analyse data they cannot find. Discovery supports governance (knowing which data is sensitive), analytics (finding the right data fast), and risk work such as compliance monitoring and fraud checks. It is also the first step before master data management, where discovered records are matched and consolidated, as in master data management in the banking sector.
What are the stages of data discovery?
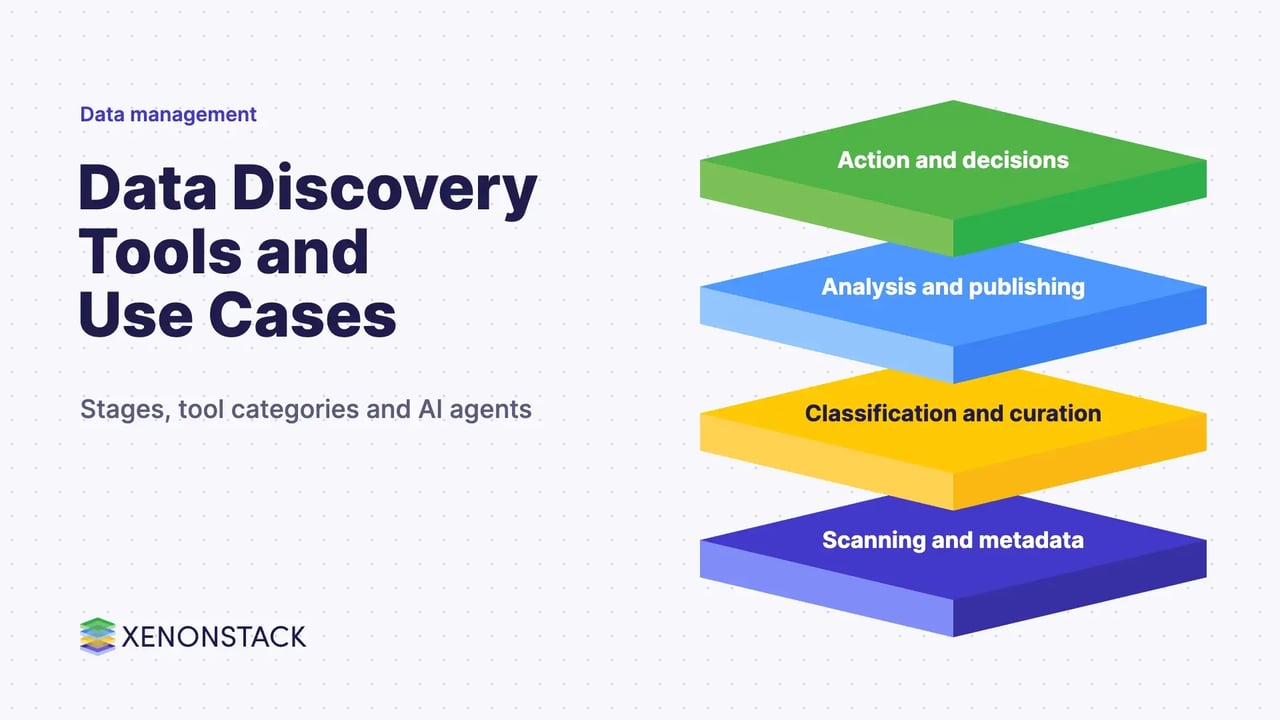
Discovery is iterative and works best when it starts from a business question. A Data Product Manager or equivalent owner usually keeps the purpose in view. Six stages are common:
- Ask questions. Define the decision or problem the data must serve.
- Acquire data. Identify and connect the relevant sources.
- Curate. Clean, classify and document the data, and record its owner.
- Visualise and analyse. Explore patterns, outliers and relationships.
- Publish results. Share findings and the data behind them with the right audience.
- Identify actions. Turn findings into decisions, and feed what you learn into the next round.
How does technical data discovery work in practice?
Cloud catalog services show the pattern. Microsoft's documentation on Purview scans and ingestion says a scan "connects to the data source and captures technical metadata like names, file size, columns, and more", extracts schema for structured sources and applies classifications. It describes three scan levels: L1 captures basic metadata, L2 adds schema, and L3 samples files and applies system and custom classification rules. Ingestion then loads the results into the catalog, and assets can only be discovered or curated after ingestion completes.
Google Cloud's documentation describes Knowledge Catalog, which it says was called Dataplex Universal Catalog until 10 April 2026. It states that the service "automatically crawls and indexes technical metadata across your data estate" without moving the underlying data, and that for Cloud Storage it runs discovery scans to parse PDFs and images. The Knowledge Catalog introduction also notes that some automated semantic extraction may be limited to built-in Google Cloud services. Product names and features change, so confirm them on the vendor documentation before you buy.
What are the top use cases of data discovery?
| Use case | What discovery provides |
|---|---|
| Data consolidation and holistic discovery | One view of what exists across systems, with duplicates and gaps visible |
| Fraud prevention | Finding data patterns and sources that feed detection rules |
| Compliance monitoring | Locating regulated and personal data and checking who can reach it |
| Insider threat detection | Understanding which sensitive data sits where, to watch access to it |
| Third-party risk | Seeing which partner data and shared datasets are in use |
| Customer churn and customer modelling | Finding and joining the data that describes customer behaviour |
| Self-service analytics | Letting business users find trusted data without waiting for a data team |
Which data discovery tools should you consider?
Tools fall into categories that solve different problems, and a single product rarely covers all of them. The names below are examples of each category, not a ranking, and the list will date, so check current capabilities.
| Category | Examples | Best for |
|---|---|---|
| Visual and self-service analytics | Tableau, Power BI, Qlik Sense, Looker, Spotfire, Domo, JMP, Phocas | Letting analysts explore data and publish findings |
| Sensitive data discovery | Spirion | Finding personal and regulated data across files and systems |
| Catalog and metadata platforms | Atlan, Microsoft Purview, Google Knowledge Catalog | Scanning sources, classifying assets and sharing a searchable catalog |
Judge any tool on the attributes that matter to you: the sources it connects to, how it classifies data, how it handles access control and lineage, how searchable it is for business users, and how it fits your existing stack.
How do AI agents change data discovery?
Traditional discovery is a project: scan, catalogue, review, repeat. Agents make it continuous. An agent can watch for new sources, propose classifications, flag unowned or sensitive data, answer a business user's question about where data lives and route exceptions to a data steward. The control point is still human: who approves a classification, and what an agent may read or change. See data management with intelligent data agents for the pattern, and the governed data lake guide for the storage side. XenonStack's ElixirData is XenonStack's Context OS, which supports mapping the data and policy behind agent decisions.
What should you do first?
- Write the business question that discovery must answer first.
- List the sources in scope and name an owner for each.
- Choose the category of tool that matches the question, then test it on one source.
- Define classification rules and who approves them.
- Review results with business users and widen scope in steps.
To map one decision your agents make, and the data and policy it depends on, book a Context Workshop. See what happens in the workshop.
To discuss your data estate, contact us or talk to a specialist.
Frequently asked questions
What is data discovery?
Data discovery is the process of finding, profiling and understanding the data an organisation holds, including where it lives, what it means and who may use it. It covers technical scanning and analytical exploration.
What is the difference between data discovery and a data catalog?
Discovery is the activity of finding and understanding data. A catalog is a system that stores and shares what discovery finds, such as schemas, classifications and owners.
How does automated scanning classify data?
Services such as Microsoft Purview scan a source, capture technical metadata and extract schema. At its highest scan level it samples files and applies system and custom classification rules.
Do I need one tool or several?
Usually several. Visual analytics tools, sensitive data discovery tools and catalog platforms solve different problems, so choose by category and test each against one real source.
How do AI agents help with data discovery?
Agents can monitor for new sources, propose classifications, flag sensitive or unowned data and answer questions about where data lives. A data steward should still approve classifications and set what an agent may read or change.
Ready to put AI agents to work? See an ElixirClaw demo: the agentic OS to build, orchestrate and govern AI agents across your enterprise systems.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE