

Key takeaway
- How agentic AI runs synthetic data generation: agent roles, human sign-off, privacy tests and model collapse risks for enterprise data leaders.
Synthetic data generation with agentic AI means using autonomous agents to plan, generate, test and release artificial datasets inside rules that your organisation sets. The agents do the repetitive work: profiling the source data, generating records, scoring quality and retrying. People keep the decisions that carry risk, such as what may leave the secure environment and which dataset a model may train on.
This guide looks at the operating model: which agent does what, where a human signs off, and what evidence you keep. This guide also covers the main generation methods, the privacy limits and the model-collapse risk.
What is synthetic data generation with agentic AI?
Synthetic data is artificial data made to resemble the structure and statistics of real data. NIST SP 800-188 (September 2023) lists generating synthetic data with models among its de-identification techniques, alongside publishing de-identified data and using query interfaces or protected enclaves. A generator on its own is a tool. An AI agent adds a loop around it: it reads a goal, chooses a method, checks the output against tests and decides whether to retry, stop or escalate to a person.
That loop is what makes the approach agentic. The same pattern appears in the research literature. In Self-Instruct (Wang et al., 2022), a language model generates instructions, inputs and outputs, and the samples are filtered to remove invalid and near-duplicate items before they are used for fine-tuning. The authors report a 33% absolute improvement on Super-NaturalInstructions for vanilla GPT-3. Generation, filtering and reuse in one controlled loop is the shape of an enterprise pipeline.
Which agents run a synthetic data pipeline, and who signs off?
A practical pipeline splits the work into narrow agents, each with a defined input, output and permission. Narrow roles are easier to test, log and switch off than one agent that does everything.
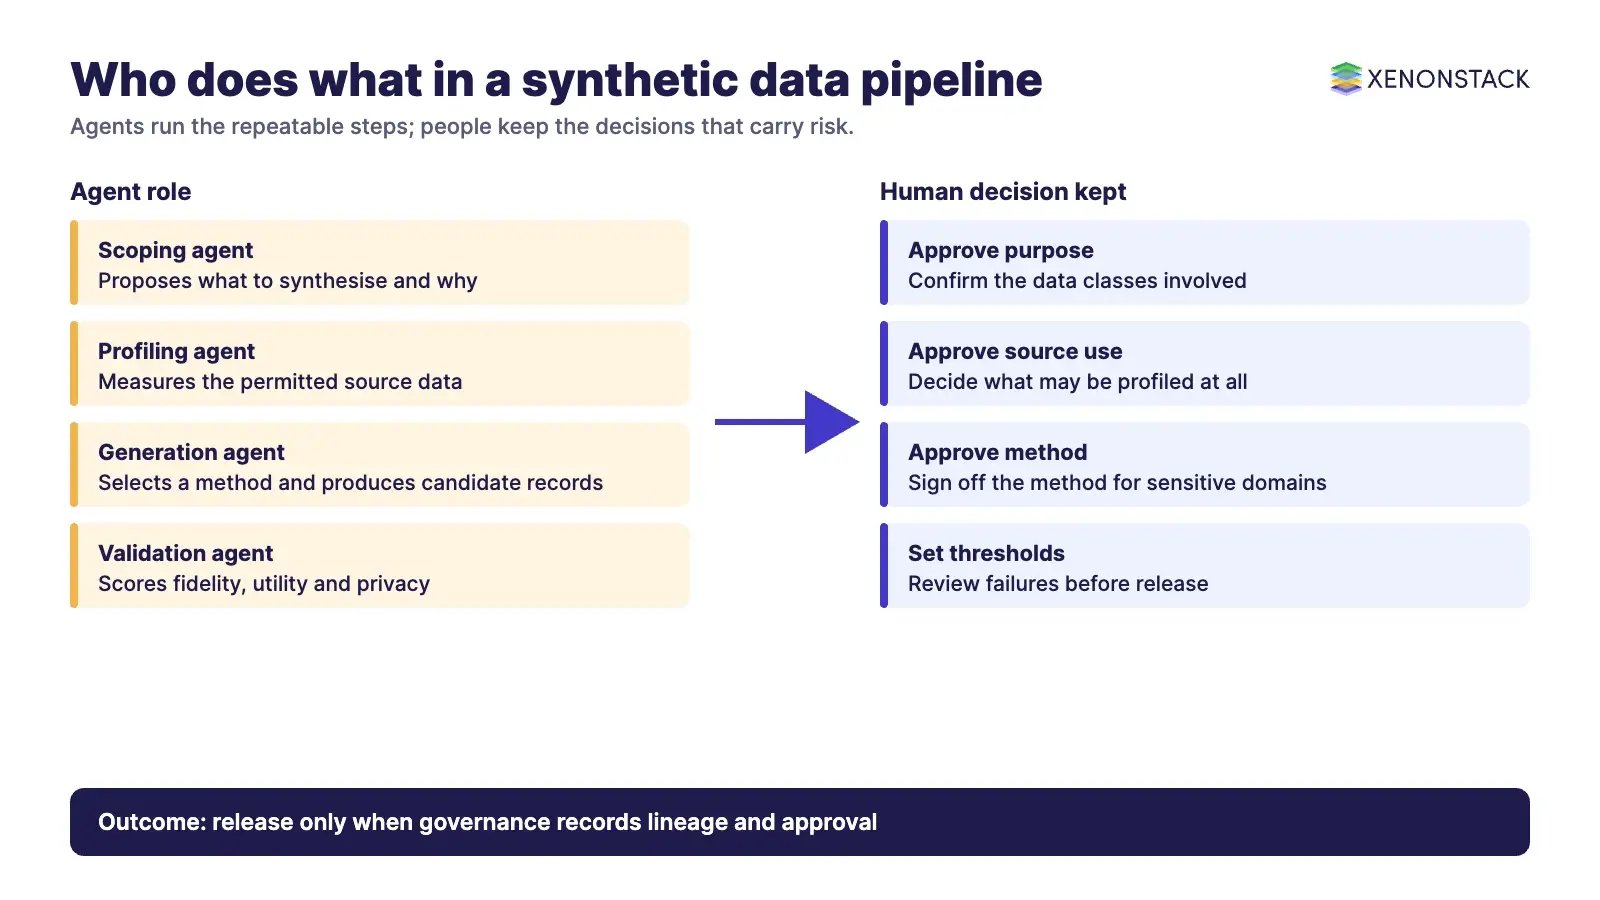
| Agent role | What it does | Human decision kept |
|---|---|---|
| Scoping agent | Reads the request, the source schema and the data classification, and proposes what must be synthesised and why | Approve the purpose and the data classes involved |
| Profiling agent | Measures distributions, keys, relationships and rare cases in the permitted source data | Confirm which source data may be profiled at all |
| Generation agent | Selects a method (rules, statistical, GAN, diffusion or LLM) and produces candidate records | Approve the method for sensitive domains |
| Validation agent | Scores fidelity and utility, runs privacy tests and flags drift or duplicates | Set the pass thresholds and review failures |
| Governance agent | Checks the release against policy, writes the lineage and decision record, and blocks or escalates | Release to non-production, partners or model training |
The governance role is the one most teams skip. Policy checks and decision records should run in the same pipeline as generation, not in a spreadsheet afterwards. ElixirData Context OS is built for this layer: it keeps governed context, versioned policy and decision traces in one decision layer above AI agents.
How does an agent loop differ from a one-off generator?
| Aspect | One-off generator | Agentic pipeline |
|---|---|---|
| Trigger | A person runs a script or tool | A request, schedule or upstream data change |
| Quality control | Checked by the person who ran it | Tests run automatically; failures trigger a retry or escalation |
| Privacy testing | Often skipped or manual | A required step before any release |
| Evidence | Little beyond the output file | Lineage, test scores and approver recorded for each dataset |
| Main risk | Unnoticed poor quality | Over-trusting the agent; needs thresholds and human gates |
The trade-off is effort. An agentic pipeline needs test sets, thresholds and logging to be designed up front. For a single, small, non-sensitive dataset, a plain generator is faster and perfectly adequate.
Where does an agentic pipeline fit best?
| Use case | Why synthetic data helps | Current status and caution |
|---|---|---|
| Non-production testing and demos | Teams can build and demonstrate without touching live records | Common practice; keep the data realistic enough to expose real edge cases |
| Agent evaluation sets | Versioned golden datasets, synthetic conversations and edge-case libraries let you test agent behaviour repeatedly | Needs review against real incidents so the set does not drift from reality |
| Instruction and fine-tuning data | Generated, validated and curated instruction data shapes model behaviour | Validate for duplicates and bias; do not train on unfiltered output |
| Regulated domains such as healthcare and finance | Avoids passing identified records to delivery teams | Not automatically anonymous; test for leakage and take legal advice |
| Rare-event simulation | Produces more examples of failures that real data rarely contains | Simulated events are only as good as the model of the failure |
In our own delivery work we see the same pattern. Some client engagements restrict delivery teams to synthetic or masked data, and any exception needs written approval from the client's security team. In an agent demonstration for a multi-plant manufacturer, synthetic datasets were used to populate a context graph and a relational database for two plants, so the agents could be validated before any real plant data was involved. Both cases depend on the synthetic data being good enough to expose real behaviour.
Does synthetic data remove the privacy and compliance problem?
No. This is the point most vendor material glosses over. Stadler, Oprisanu and Troncoso conclude that synthetic data does not provide a better privacy-utility trade-off than traditional anonymisation techniques, and that the trade-off is hard to predict. Treat privacy as something you test for each dataset, not a property you assume because the records are artificial.
For formal guarantees, differential privacy is the established framework. NIST SP 800-226 (March 2025) offers guidance for evaluating differential privacy guarantees and describes common implementation mistakes as "privacy hazards". Use it as a checklist when a vendor claims a privacy guarantee. Your governance agent should record which test was run, with what result, before each release. Our guide to data governance best practices covers the wider policy framework.
What can go wrong with synthetic data in model training?
The main risk is model collapse. Shumailov and colleagues show that training generative models recursively on generated data makes the rare, low-probability parts of the original distribution vanish, in variational autoencoders, Gaussian mixture models and large language models. A follow-up study by Gerstgrasser and colleagues finds that replacing real data with each generation of synthetic data leads towards collapse, while accumulating synthetic data alongside the original real data avoided it in their experiments.
For an enterprise pipeline the rule is simple. Keep a protected core of real, governed data, add synthetic data to it rather than swapping it out, and have the validation agent report how rare cases are represented. Instruction data deserves the same care. AgentInstruct creates, validates and curates instruction data for a given use case, and runs on the Context OS platform so its actions can be allowed, modified, escalated or blocked.
How should an enterprise adopt it, step by step?
- Choose one decision to govern. Pick a bounded use, such as test data for one application or an evaluation set for one agent.
- Classify the source data. Decide what may be profiled and who approves exceptions.
- Set thresholds before generating. Define fidelity, utility and privacy tests and the scores that count as a pass.
- Run in shadow mode. Let agents generate and score while people still produce the real release decision.
- Record lineage and approvals. Store the method, source version, test results and approver for every dataset.
- Add autonomy gradually. Allow agents to release to low-risk environments first, as the evidence supports it.
- Review for drift. Re-test against fresh real samples, and keep real data in the training mix.
AgentGRC keeps autonomous agent actions inside policy, with the audit trail risk teams need. For building and orchestrating the agents themselves, ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control. The pipeline also connects to your wider agentic data management estate.
When should you not use synthetic data?
| Situation | Why to avoid or limit it | Better option |
|---|---|---|
| The dataset is small and the real data is already cleared for use | Generation adds effort and risk with no gain | Use the real data under existing controls |
| You need to prove a real-world effect, such as a clinical outcome | Synthetic data reflects your model of the world, not the world | Use real, consented data |
| Rare cases matter most and you cannot describe them | The generator cannot create what it has not seen | Collect more real examples of those cases |
| A regulator or contract requires real-data validation | Synthetic data may not meet the requirement | Check the obligation before you design the pipeline |
| Models would train only on their own outputs | Risk of model collapse | Keep real data in the mix |
To map one synthetic data decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is synthetic data generation with agentic AI?
It is the use of autonomous agents to plan, generate, validate and release artificial datasets within policy. People keep the approval decisions that carry risk, and the pipeline records lineage and test results for each dataset.
Is synthetic data automatically anonymous?
No. Stadler, Oprisanu and Troncoso conclude that synthetic data does not give a better privacy-utility trade-off than traditional anonymisation, and that the trade-off is unpredictable. Test each dataset for leakage and record the result.
How do I evaluate differential privacy claims?
NIST SP 800-226 (March 2025) provides guidelines for evaluating differential privacy guarantees and describes common implementation mistakes. Ask vendors which of these checks they have applied.
What is model collapse and how do I avoid it?
Model collapse is the loss of rare parts of a data distribution when models are trained recursively on generated data (Shumailov et al.). Gerstgrasser et al. found that accumulating synthetic data alongside real data avoided it, whereas replacing real data did not.
Which decisions should stay with people?
Approving the purpose and data classes, setting pass thresholds and releasing data to partners or model training. Agents can run profiling, generation and testing, and escalate failures.
When is a simple generator enough?
For a single, small, non-sensitive dataset, a plain generator is faster. An agentic pipeline pays off when many datasets, repeat runs, sensitive sources or audit evidence are involved.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE


