Key takeaway
- Data fabric benefits, architecture and use cases for enterprise leaders: components, trade-offs, mesh and lakehouse differences, and where AI agents fit.
A data fabric is a data architecture that connects data across on-premises, cloud and edge systems through a shared, metadata-driven layer. People and applications can then discover, access and govern data where it already lives, instead of first copying everything into one store.
The main benefits are faster access to trusted data, consistent governance across systems, less manual integration work and a better base for AI. This guide covers how a data fabric works, where it pays off, where it does not, and how it differs from a data mesh, a lake and a warehouse.
What is a data fabric?
Gartner analyst Mark Beyer described a data fabric as "an integrated layer (fabric) of data and connecting processes" in an article for CDOTrends dated 25 August 2021 (CDOTrends). He called it a design concept that applies continuous analytics to existing metadata to support the design, deployment and use of reusable data across hybrid and multi-cloud environments.
IBM makes a similar point: according to its site, a data fabric is "not a piece of software, but rather a design approach" that gives a unified view of data across on-premises and multicloud environments (IBM). In practice, it means you buy or build several capabilities and join them with metadata, rather than installing one product.
How does a data fabric work?
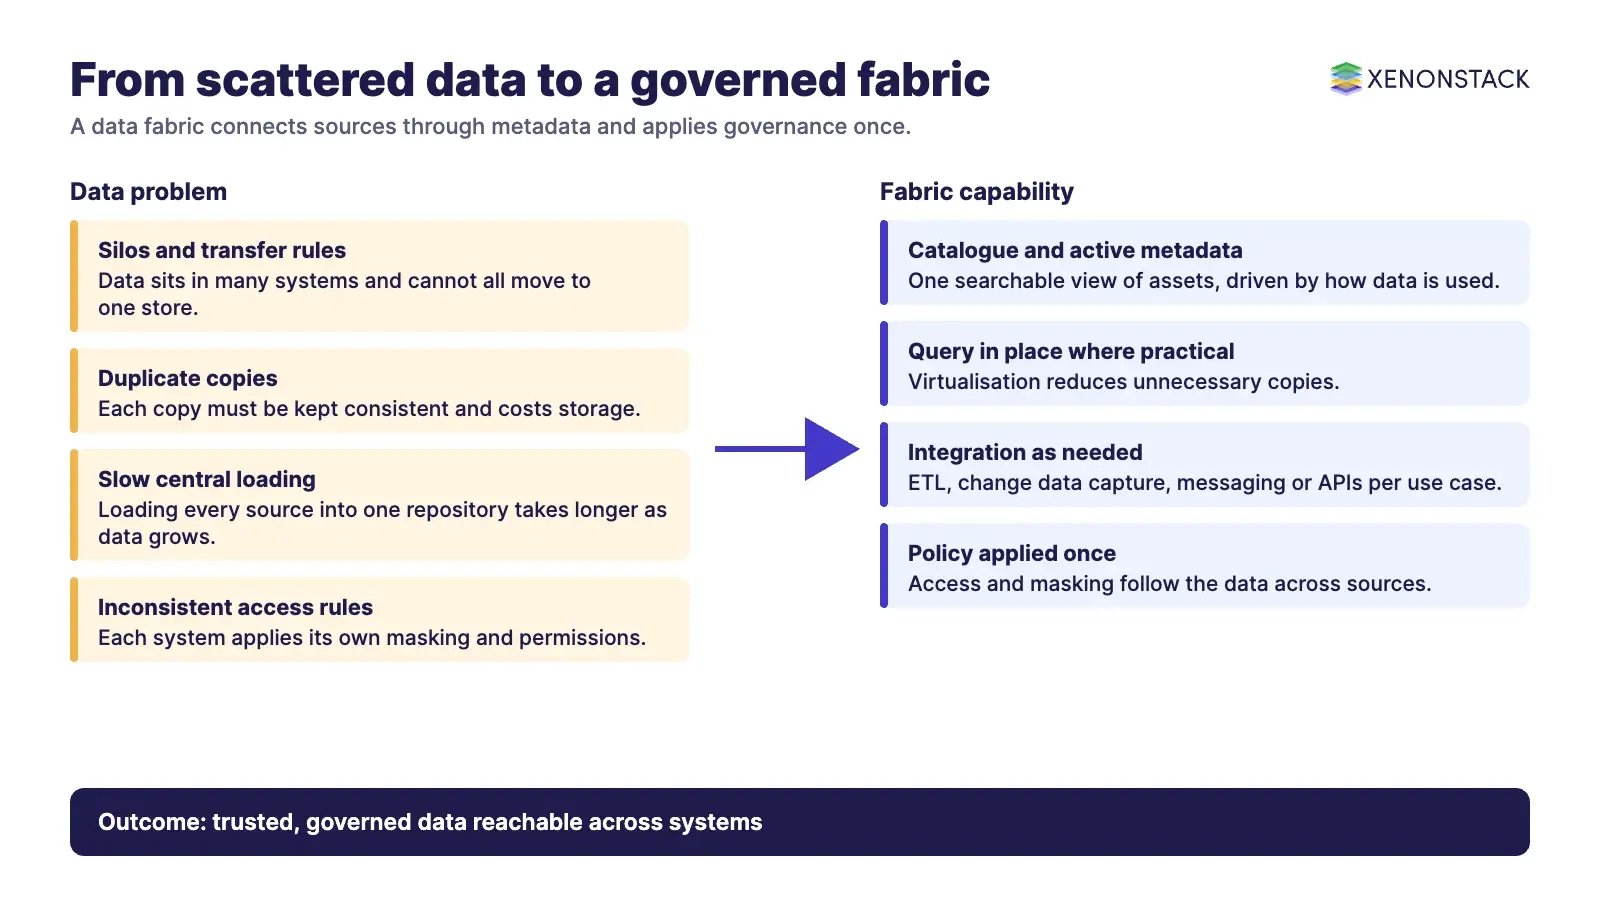
Centralised stores such as warehouses, lakes and lakehouses work well, but they struggle when data keeps growing and sits in many places. Three problems appear again and again:
- Silos and transfer rules: moving data to one place can be slowed by hosting, residency and privacy policies, so analysis waits.
- Replication: every copy must be kept consistent, and copies cost storage.
- Latency: as volumes grow, loading data from many sources into a central repository takes longer.
A data fabric reduces these problems by leaving data in place where it can and connecting it through metadata, virtualisation and integration services. It does not remove data movement altogether: batch loads, change data capture and replication still have a place when performance or resilience needs them. IBM lists data virtualisation, federated active metadata and machine learning as the three foundations of a fabric (IBM).
Microsoft Fabric gives one concrete example of access in place. According to Microsoft Learn, OneLake shortcuts "behave like symbolic links" to data stored elsewhere, including Amazon S3, Google Cloud Storage and ADLS Gen2, so engines can read it without copying it (Microsoft Learn). This is one vendor's approach, not the definition of a data fabric.
What does a data fabric include?
There is no single standard parts list. IBM, citing Forrester, says a fabric typically has six components: data management, ingestion, processing, orchestration, discovery and access. The table below uses the building blocks most enterprise teams ask about.
| Building block | What it does | What to check |
|---|---|---|
| Augmented data catalogue | Gives one searchable view of data assets and links them to business terms, using machine learning to suggest relationships. | Does it cover every platform you run, and is it kept current? |
| Active metadata | Records how data is actually used and feeds automation, instead of only describing data once. | Which signals are captured, and what actions do they trigger? |
| Knowledge graph | Shows how data assets, people and terms relate, with consistent identifiers. | Who maintains the model as sources change? |
| Persistence and virtualisation | Keeps data in relational and non-relational stores and lets users query it in place where that is practical. | Which workloads need a copy for speed or resilience? |
| Integration and delivery | Moves data by ETL, messaging, change data capture, virtualisation or APIs, as each use case needs. | Are batch and real-time paths both covered? |
| Orchestration and DataOps | Schedules pipelines and controls the data they produce. | Is there monitoring, lineage and rollback for pipelines? |
| Governance and security | Applies access rules, masking and policy consistently across sources. | Are policies tied to metadata such as data classification? |
What are the benefits of a data fabric?
The benefits below are the ones a data fabric is designed to deliver. How much you gain depends on your data estate and on how well the metadata is maintained, so measure each one against a baseline before you invest.
| Benefit | How the fabric helps | How to measure it |
|---|---|---|
| Faster access to data | Users find and request governed data through one catalogue and access layer, with less IT involvement. | Time from request to usable data |
| Less integration effort | Automation and reusable pipelines replace point-to-point integrations. | Engineer days per new data source |
| Consistent governance | Access, masking and policy rules follow the data across systems, driven by metadata. | Share of sources under one policy set |
| Fewer unnecessary copies | Data can be queried in place where performance allows, which reduces duplicate storage and reconciliation. | Number of duplicated datasets |
| Scalability | New sources and applications are added by connecting them to the fabric, not by rebuilding it. | Time to onboard a new source |
| Better base for AI | Models and agents draw on described, governed data. IBM's 2024 CXO study reports only 29% of tech leaders strongly agree their data is good enough to scale generative AI (as cited by IBM). | Share of AI use cases with approved data sources |
Where is a data fabric used?
Machine learning and AI data supply
Preparing data is one of the most time-consuming parts of training a model. A fabric can shorten that work by letting teams find, understand and reuse prepared data across models, and by giving controlled access to data that sits on-premises, in the cloud and at the edge.
A single view of the customer
A fabric can correlate data from the CRM, self-service portals, service chatbots, call-centre systems and field teams, so analysts see one customer across touchpoints without a new central copy of every source.
Self-service analytics
Business users can reach governed data through one catalogue and drill into performance, risk and budgets with less help from IT. The same layer can support big data architecture patterns, including lakehouses.
Data security and governance
Masking, encryption and fine-grained access control still do the protective work. A fabric adds a place to apply them consistently, driven by metadata such as classification. It helps with compliance work but does not replace it. See big data security for the controls themselves.
Data quality
Poor data costs money through wrong customer records, wrong credit decisions and payment errors. A fabric can apply quality checks and profiling continuously, using machine learning to flag anomalies, but someone must still own the rules and fix the sources.
Triggered actions and predictions
Teams can train predictive models on fabric data and trigger actions in enterprise applications, such as audit alerts, retention offers or cart-abandonment messages. Reusable data models help later projects start faster.
How is a data fabric different from a data warehouse, lake, lakehouse and mesh?
These terms describe different layers of the problem, so they are often combined. IBM says fabrics "coexist with data meshes" and describes a fabric as the next stage after lakehouses, adding integration, governance and self-service that storage alone does not provide (IBM).
| Approach | What it is | When it fits | Relationship to a fabric |
|---|---|---|---|
| Data warehouse | Central store of structured, modelled data for reporting. | Trusted reporting on structured data. | A fabric can connect to it and expose its data alongside other sources. |
| Data lake | Store for raw structured and unstructured data. | Large, varied data for data science. | A fabric catalogues and governs the lake to keep it from turning into a swamp. |
| Data lakehouse | Lake storage with warehouse-style analytics. | One platform for BI and AI on open formats. | A fabric spans the lakehouse and other systems. |
| Data mesh | Organisational model where domains own data as products. | Large organisations with strong domain teams. | A fabric can automate parts of a mesh, such as data products and global governance. |
For the full comparison, read Data Fabric vs Data Mesh, Data Warehouse vs Data Lake vs Data Mesh and Data Mesh Adoption.
What has changed in how enterprises think about data fabric?
- Passive to active metadata: Gartner's Mark Beyer names converting passive metadata into active metadata as a key pillar. The metadata is analysed continuously and used to drive automation.
- Platform bundling: in the same article he writes that a data management platform may provide "65-70% of the capabilities needed to stitch together a data fabric", with the rest built in-house. Check any vendor claim against your own requirements.
- AI demand: data that is described, governed and traceable matters more once AI agents act on it, which is why metadata and lineage get more attention than before.
Read more on the metadata layer in OpenMetadata Platform: Guide for Data Leaders and on tooling in Enterprise Data Catalog Tools.
What should leaders plan for on governance, security and cost?
- Governance: decide who owns each dataset, who approves access and how policies are written once and applied everywhere.
- Security: a fabric widens the reach of your data, so access control, masking and audit logging must be in place before you open it up.
- Cost: virtualising data can avoid duplicate storage, but cross-cloud queries can add network egress and compute cost. Test representative queries before you commit.
- Skills: metadata management and knowledge-graph modelling are specialist work and need named owners.
How should an enterprise adopt a data fabric?
- Pick two or three high-value use cases, such as a customer view or a governed AI data supply, instead of a whole-estate programme.
- Inventory sources and existing metadata and note where data cannot move for legal or performance reasons.
- Stand up the catalogue and active metadata first, because every later capability depends on them.
- Connect sources in priority order, using virtualisation where it performs and pipelines where it does not.
- Apply governance policies to those sources and test them with real users.
- Measure against a baseline and extend to the next use case.
When is a data fabric not the right choice?
- Your data already sits in one platform and your reporting needs are met. A lakehouse or warehouse may be enough.
- Source systems are very few, stable and well documented, so point integrations are cheaper.
- You have no one to own metadata. A fabric without maintained metadata becomes another catalogue nobody trusts.
- You expect one product to deliver the whole fabric. Treat it as an architecture made of several capabilities.
Where do AI agents fit?
The metadata layer of a data fabric gives AI agents context: what data means, where it lives and who may use it. ElixirData keeps governed context, versioned policy and decision traces in one decision layer above AI agents, and ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control. For plain-language questions over enterprise data, AgentAnalyst lets teams ask questions of enterprise data sources in plain language.
To map the data, context and policy your agents should rely on, book a Context Workshop. See what happens in the workshop. For the wider platform view, see Big Data Platform and Big Data Challenges and Solutions.
Frequently Asked Questions
How is a data fabric different from a data mesh?
A data fabric is a technology architecture driven by metadata and automation. A data mesh is an organisational model in which business domains own their data as products. IBM says the two coexist, and a fabric can automate parts of a mesh.
How is a data fabric different from a data lake?
A data lake is a store for raw data. A data fabric is a layer that connects many stores, including lakes and warehouses, and adds cataloguing, integration and governance.
What role does metadata play in a data fabric?
Metadata describes data assets and their relationships. Gartner's Mark Beyer argues that passive metadata should become active metadata, analysed continuously, so the fabric can automate discovery, integration and governance.
What are the main benefits of a data fabric?
Faster access to trusted data, consistent governance across systems, less manual integration work and fewer unnecessary copies. The size of each benefit depends on your data estate and metadata quality.
Is a data fabric a product I can buy?
Not on its own. IBM describes it as a design approach, not a piece of software. Most enterprises combine catalogue, integration, virtualisation and governance capabilities, from one or several vendors.
Does a data fabric mean data is never moved?
No. A fabric lets you leave data in place where that performs well, but batch loads, change data capture and replication are still used when speed, resilience or cost require them.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE