Key takeaway
- DevNetOps applies DevOps to network operations. Learn the pipeline, tooling, benefits, metrics and trade-offs, and where to start, for enterprise leaders.
What is DevNetOps?
DevNetOps is the practice of applying DevOps principles to network operations. Network changes are written as code, kept in version control, tested automatically and released through a pipeline, instead of being typed device by device. The term is used alongside NetDevOps and network automation, and it has no single formal standard, so teams define it by the practices they adopt.
For enterprise leaders the point is risk and speed together. Smaller, tested, reviewable network changes are easier to approve and easier to reverse than large manual ones. The role that carries this on the operations side is the network reliability engineer, covered in our guide to network reliability engineering.
How does DevNetOps relate to DevOps and CALMS?
DevOps is commonly summarised as CALMS: Culture, Automation, Lean, Measurement and Sharing. According to Atlassian, Jez Humble coined the acronym and it is used to assess how ready a company is to adopt DevOps. DevNetOps applies the same five ideas to routers, switches, firewalls, load balancers and the cloud networks around them.
| CALMS idea | What it means for the network |
|---|---|
| Culture | Network, security and application teams review changes together rather than hand them over. |
| Automation | Configuration, testing and deployment of network changes run from a pipeline, not from manual sessions. |
| Lean | Small, frequent changes with fast feedback replace large change windows. |
| Measurement | Lead time, change failure and recovery time are tracked for network changes as for software. |
| Sharing | Runbooks, templates and lessons from incidents live in shared repositories. |
The definitions of each letter come from the Atlassian page; the network column is our reading of how they apply.
What does a DevNetOps pipeline look like?
A DevNetOps pipeline follows the same stages as a software pipeline. The network tooling at each stage varies by vendor and team, so treat the examples below as common choices rather than requirements.
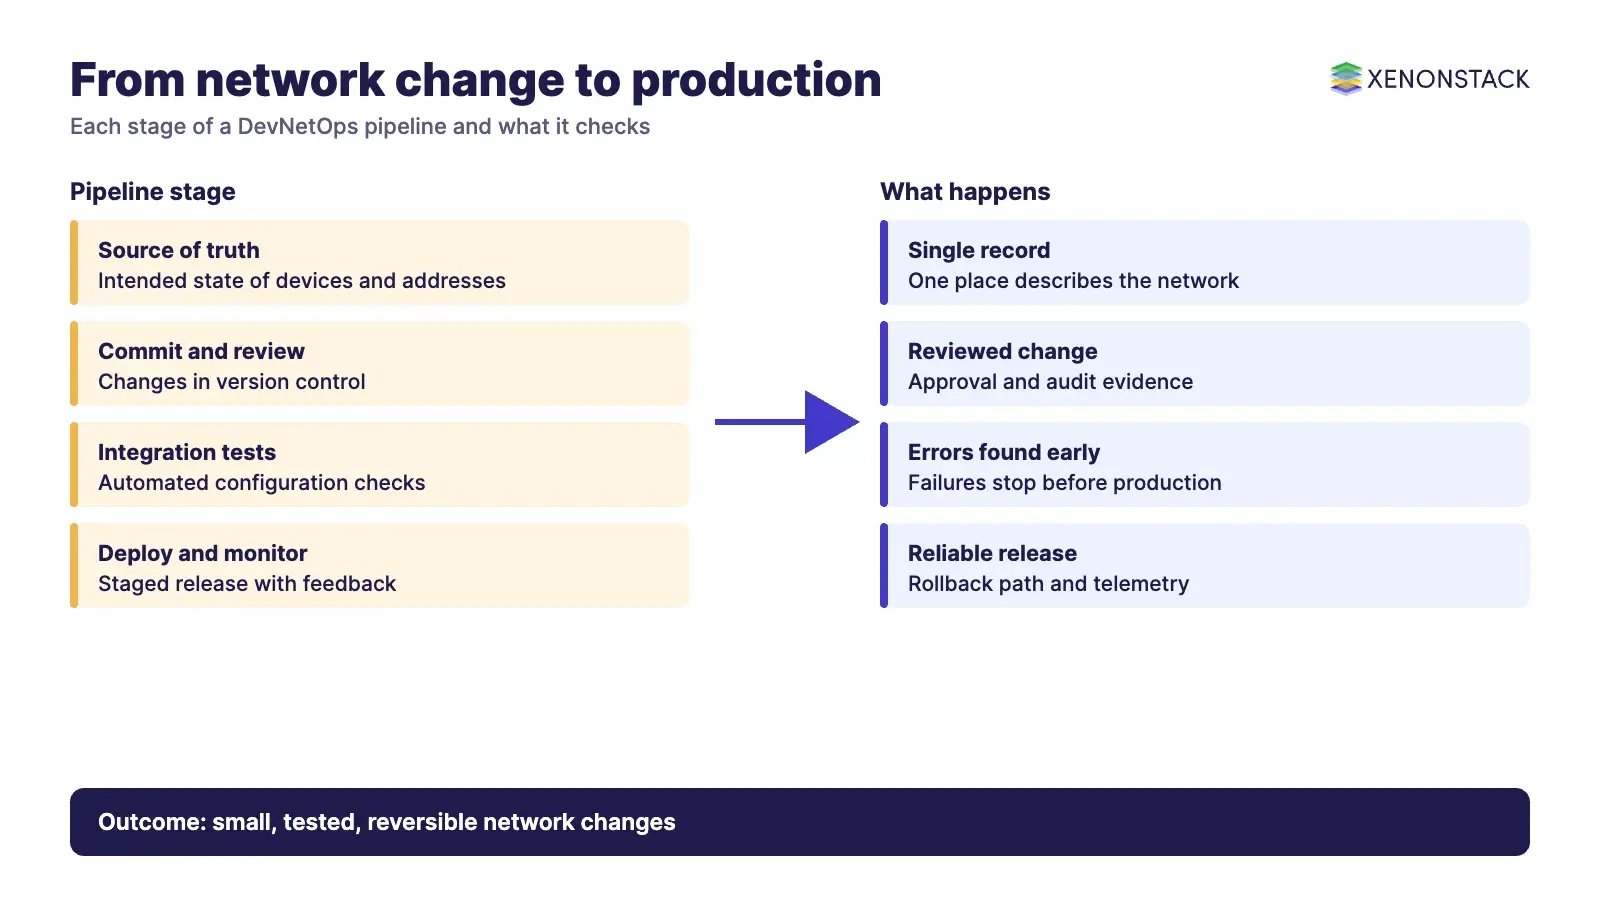
| Stage | What happens | Example tooling |
|---|---|---|
| Source of truth | Intended state of devices, addresses and links is recorded in one place. | NetBox describes itself as a network source of truth combining IP address management and data centre infrastructure management (NetBox). |
| Commit | Configuration or templates are changed in version control and reviewed. | Any Git-based workflow. |
| Continuous integration | The change is built and checked automatically, including syntax and policy checks. | Batfish is an open source tool that analyses network configurations to find errors (Batfish). |
| Continuous delivery | The tested change is kept in a deployable state and pushed to staging first. | Ansible says it automates routine network changes across mixed devices over SSH or HTTPS (Ansible network documentation). |
| Continuous deployment | An automatic or approved push to production, with a rollback path. | Pipeline runner of your choice. |
| Monitoring and response | Telemetry and incidents feed back into the code that defines the network. | Your existing monitoring and observability stack. |
Two principles matter more than the tool names. First, keep changes small, because large rigid changes are slower to validate and harder to reverse. Second, treat infrastructure as reproducible: if an engineer edits a deployed device by hand, the repository no longer describes production, and tests no longer predict what will happen.
What are the benefits of DevNetOps?
- Consistency. Every change follows the same reviewed path, which reduces configuration drift between devices.
- Smaller, safer changes. Frequent small releases are easier to test and to roll back than occasional large ones.
- Faster vendor software and patch adoption. Upgrades and patches can be tested in a pipeline before they reach production.
- Better audit evidence. Version control records who changed what, when and why.
- Less operational strain. Engineers spend less time on repetitive manual work and on stressful change windows.
These are the expected benefits of the approach, not guaranteed outcomes. Measure them for your own network before and after the change.
How do you measure DevNetOps success?
Use the same delivery measures as software teams. DORA publishes five software delivery metrics: change lead time, deployment frequency, failed deployment recovery time, change fail rate and deployment rework rate. Apply them to network changes, for example the time from a committed change to the change running in production. Our guide to DevOps metrics explains how to read them and what to add.
Pair delivery metrics with reliability goals. The Google SRE book describes SRE as what happens when you ask a software engineer to design an operations team, and says Google caps SRE operational work at 50% of time so the rest goes to engineering. Network reliability engineering borrows that idea; see our comparison of SRE and DevOps for the roles and error budgets.
What should leaders put in place first?
| Step | What to do | Decision it supports |
|---|---|---|
| 1. Inventory | Record devices, addresses and owners in one source of truth. | Where is the network described today, and is it accurate? |
| 2. Version control | Move configuration and templates into a repository with review. | Who may approve a change, and what is the evidence? |
| 3. Test | Add automated checks before any change reaches production. | Which failures must the pipeline stop? |
| 4. Automate one change type | Start with a low-risk, repeated change such as a VLAN or ACL update. | Is the team ready for a wider scope? |
| 5. Measure and extend | Track lead time and failures, then widen scope. | Is the approach paying back for this network? |
What are the trade-offs and when should you wait?
- Automation applied to a poorly understood network spreads mistakes faster. Document and clean up the current state first.
- Legacy devices without a usable API may need vendor-specific handling or may stay manual for now. Confirm support in each vendor's own documentation.
- Pipelines are a new attack surface. Protect credentials, restrict who can approve production changes, and apply the controls in our guide to continuous security.
- Culture takes longer than tooling. If network and application teams do not share goals, a pipeline alone will not change outcomes.
Where AI agents begin to propose or make network changes, the same governance question applies: which decisions may an agent take, under what policy, with what record. ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control, and AgentGRC keeps autonomous agent actions inside policy, with the audit trail risk teams need, according to their own sites.
To map one network change decision your pipeline or agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is DevNetOps in simple terms?
DevNetOps applies DevOps practices, such as version control, automated testing and pipelines, to network operations so that network changes are small, reviewed and repeatable.
Is DevNetOps the same as NetDevOps?
The terms are used for the same idea. Neither has a formal standard, so define it by the practices your team adopts.
What is the role of a network reliability engineer?
A network reliability engineer applies SRE-style engineering to the network, automating operational work and using measured reliability goals. See our guide to network reliability engineering for detail.
Which metrics should we track?
DORA publishes five software delivery metrics: change lead time, deployment frequency, failed deployment recovery time, change fail rate and deployment rework rate. Apply them to network changes.
Where should a team start?
Record the network in a source of truth, move configuration into version control, add automated checks, and automate one low-risk change type before widening scope.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE