Key takeaway
- Continuous ETL explained: architecture, current streaming tools (Kafka Connect, AWS Glue, Lakeflow) and when batch is still the better choice.
Continuous ETL is extract, transform and load run as an ongoing flow, so a change in a source reaches the lake or warehouse within seconds or minutes instead of waiting for the next nightly batch. It suits decisions that go stale quickly, such as alerts, fraud checks and operational dashboards, and it costs more to run and monitor than a batch job.
This guide is for architects and data platform leads choosing between managed streaming services and self-run pipelines. It covers the architecture, the current state of the main tools as their own documentation describes them, the trade-offs, and when batch is still the better answer. For scheduling and monitoring jobs, see our guide to Apache Airflow; for the engine side, see real-time streaming with Apache Spark and Kafka.
What is continuous ETL?
Continuous ETL reads data from one or many sources, cleanses, enriches and transforms it as it arrives, and writes it to a data lake or warehouse without waiting for a scheduled window. Latency depends on the tool and the settings. Databricks documents continuous pipelines for freshness from about 10 seconds to a few minutes, and AWS Glue streaming jobs process and write data in 100-second windows by default, which you can change (Databricks pipeline mode docs; AWS Glue streaming ETL docs).
How does continuous ETL work?
A continuous pipeline has the same three stages as batch ETL, but each stage keeps running and has to cope with late, duplicate and malformed records while the stream is live.
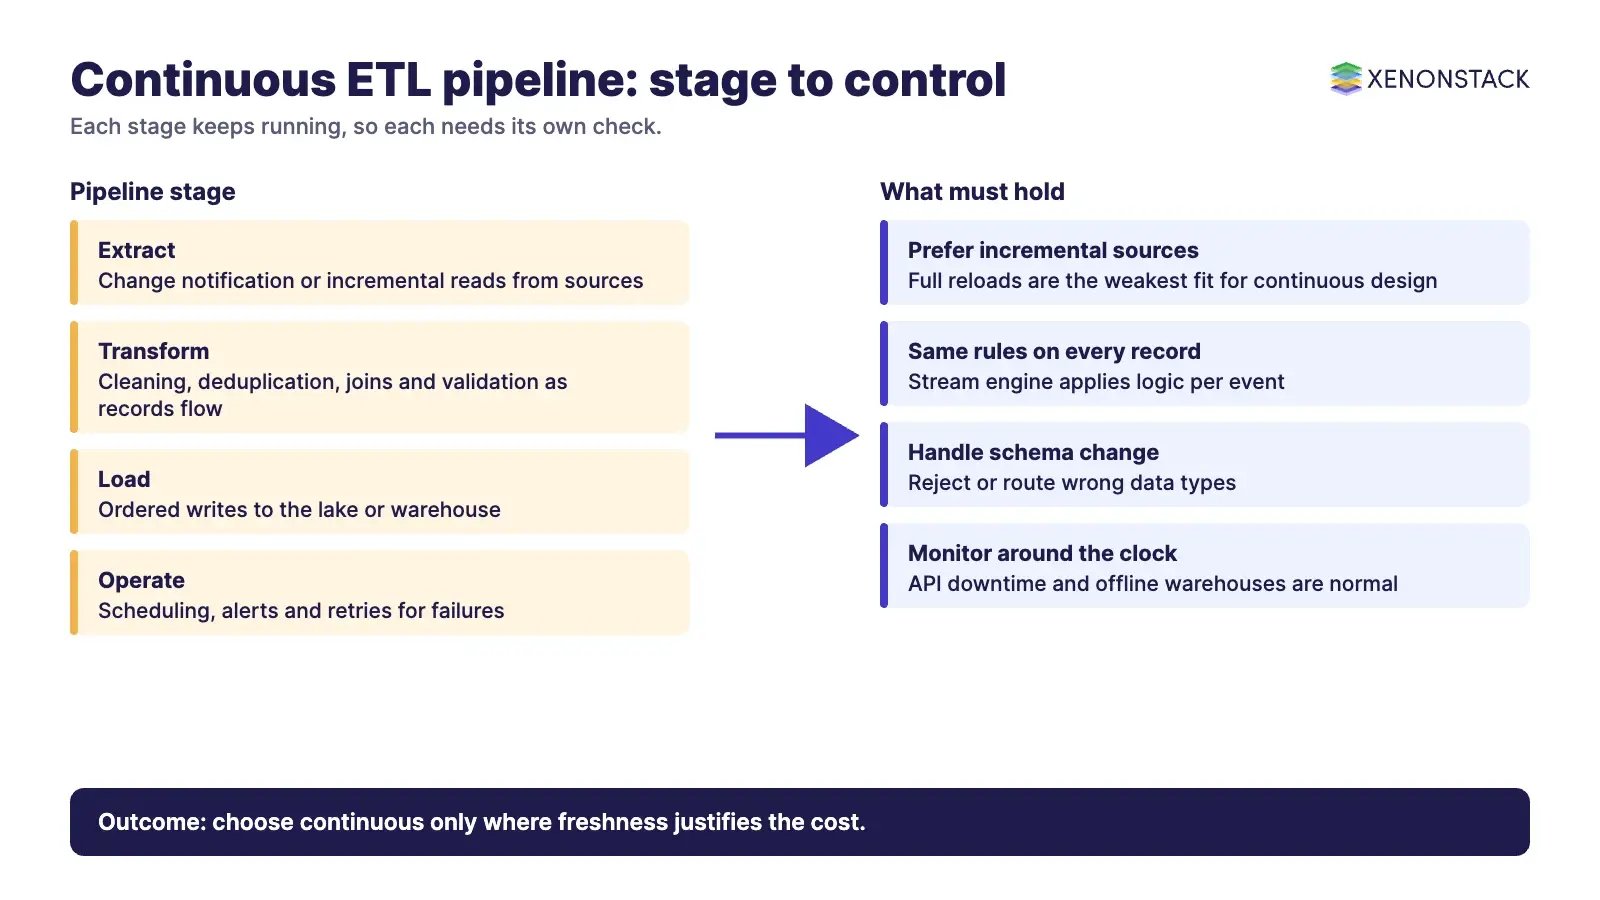
Extract: how do changes leave the source?
- Update notification. The source tells the pipeline when something changed, so extraction starts at once. Continuous pipelines need this kind of source.
- Incremental extraction. The source can say which records changed, so only unread records are pulled.
- Full extraction. The source cannot report changes, so all data is reloaded and the pipeline must track what it read last time. This is the weakest fit for a continuous design.
Transform: where does the logic run?
There are two common placements. In multistage transformation, records are changed in a staging area before they reach the warehouse. In in-warehouse transformation, raw data is loaded first and transformed inside the warehouse. Stream engines such as Apache Flink and Spark Structured Streaming apply the transformations as records flow, so the same rules run on every record.
| Group | Typical operations |
|---|---|
| Basic | Cleaning and format consistency, deduplication, unit and date conversions, restructuring keys across tables |
| Advanced | Deriving new fields from business rules, filtering rows and columns, joining streams, splitting columns, validation (for example rejecting rows with empty key columns), aggregation, and standardising names to one definition |
Load: what must the target guarantee?
- Ordering. Updates and deletes must reach the target in a safe order, or the target ends up wrong.
- Schema evolution. If a field that should be an integer starts arriving as text, the load must reject or route it instead of corrupting the table.
- Monitorability. With many sources, failures are normal: an API goes down or expires, the network congests, or the warehouse is offline. Alerting and retry paths belong in the design from the start.
Which tools run continuous ETL today?
Product names and support change, so this table reflects each vendor's own documentation as read on 13 November 2026. Confirm current status on the official page before you commit.
| Tool | Role in a continuous pipeline | What its documentation says |
|---|---|---|
| Apache Kafka and Kafka Connect | Messaging backbone and source or sink connectors | Connect streams data between Kafka and other systems. Source connectors bring data in, sink connectors deliver it out. Workers run in standalone mode (one process, no fault tolerance beyond your own monitoring) or distributed mode (a cluster that rebalances work). Single message transforms are for lightweight, per-record changes; for complex or stateful processing the docs point to ksqlDB and Kafka Streams (Confluent Platform docs). |
| AWS Glue streaming ETL | Managed streaming jobs on Spark Structured Streaming | Jobs run continuously, read from Amazon Kinesis Data Streams, Apache Kafka or Amazon MSK, and write to Amazon S3 or JDBC stores. They use checkpoints, not job bookmarks. Billing is hourly while a job runs, and a job must have a timeout under 7 days. |
| Amazon Data Firehose | Buffered delivery of streams to stores | Reads from producers or an existing Kinesis data stream and delivers to destinations including Amazon S3, Amazon Redshift, Amazon OpenSearch Service, Splunk and Apache Iceberg tables. It buffers by size or time before delivery and can transform data on the way. Older material may call it Kinesis Data Firehose; confirm on the official page. |
| Amazon Managed Service for Apache Flink | Stateful stream processing | Runs Apache Flink applications written in Java, Scala, Python or SQL, and handles provisioning, availability-zone failover, automatic scaling and checkpoint-based backups. Amazon Kinesis Data Analytics for SQL applications is no longer offered; AWS publishes a migration guide to Managed Service for Apache Flink and its Studio notebooks (confirm on the official AWS page). |
| Databricks Lakeflow pipelines | Declarative batch and streaming pipelines in SQL and Python | Documented as built on Apache Spark Declarative Pipelines and run on Databricks Runtime. Earlier material calls this service Delta Live Tables; confirm the current name on the Databricks page. |
| Apache Airflow | Scheduling, monitoring and failure handling of jobs | An orchestrator, not a streaming engine. It fits the batch and control side around a continuous pipeline. |
For a serverless approach to the surrounding platform, see our guide to serverless architecture for big data, and for the target store see modern data warehouses.
Should you run triggered or continuous pipelines?
The choice is mostly about freshness against cost. Databricks describes triggered mode as refreshing available data and stopping, which suits updates every 10 minutes, hourly or daily at lower cost. It describes continuous mode as processing new data as it arrives, for freshness between about 10 seconds and a few minutes, and notes that continuous pipelines need an always-running cluster, which is more expensive but reduces latency (Databricks pipeline mode docs). AWS Glue streaming jobs likewise bill while they run.
| If the business needs | Fits | Trade-off |
|---|---|---|
| Fresh data every few minutes to hours, with cost control | Triggered or micro-batch refresh | Higher latency, lower compute bill |
| Seconds to a few minutes freshness for alerts and live dashboards | Continuous streaming pipeline | Always-on compute and 24/7 monitoring |
| Per-event logic with state, such as windows and joins | A stream engine such as Apache Flink or Spark Structured Streaming | More engineering skill and state management |
| Simple movement of records between systems | Kafka Connect or a managed delivery service | Only lightweight per-record transforms |
What are the benefits of continuous ETL?
- Warehouses and lakes that stay up to date between batch runs.
- Real-time alerts and analytics, for example anomaly or security-threat detection on sensor and application data.
- Operations applied to data as it arrives, not in a nightly window.
- Low-latency data for time-sensitive analytics.
What can go wrong, and how do you govern it?
The vendor documentation lists limits that shape the design. Check each against your own stack.
- Failed tasks. Kafka Connect does not restart failed tasks on its own; they are restarted through the REST API, so alerting must watch task state. Dead letter queues apply to sink connectors only.
- Schema handling in AWS Glue. When schema detection is used, joins of streaming data are not possible. Glue streaming supports only the Avro format for Glue Schema Registry with schema inference set to false, and Kafka sources need TLS endpoints.
- Reprocessing. Glue streaming jobs track progress with checkpoints. To reprocess data you delete the checkpoint folder referenced in the script, so treat that as a controlled operation.
- Long-running cost. Always-on clusters and streaming jobs bill while they run. Set a freshness target per dataset instead of making everything continuous.
- Decisions made on streaming data. When agents or automated rules act on fresh data, the context, policy and decision trace behind each action need to be recorded. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents.
How do you adopt continuous ETL step by step?
- Choose the data that needs to be fresh. List datasets by the decision they feed and the freshness that decision needs.
- Check the sources. Prefer sources that can notify you of change or report incremental updates.
- Model and partition. Decide the data model and partitioning strategy first, so queries read only the relevant fraction of the data.
- Fix issues at the source. Errors left at the source will reach every system downstream.
- Pick one source-of-truth pipeline. It should feed all destinations and act as the real-time messaging bus, with stateful stream processing where needed.
- Pick tools to match the use case. Use the table above, then pilot on one dataset.
- Schedule, audit and monitor. Plan for scalability, auditing and failure handling before go-live. For agent-driven automation on top of the pipeline, ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control.
When should you not use continuous ETL?
Stay with batch or triggered refresh when reports are read daily or weekly, when the source can only be fully reloaded, or when the team cannot yet monitor a pipeline around the clock. Triggered refresh is documented as the lower-cost option, and a pipeline nobody watches is a risk rather than an advantage.
To map one data decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
FAQ
What is continuous ETL?
It is extract, transform and load run as an ongoing flow, so data reaches the lake or warehouse within seconds or minutes of changing in the source.
How is continuous ETL different from batch ETL?
Batch ETL runs on a schedule and processes what has accumulated. Continuous ETL processes data as it arrives. Databricks describes triggered mode as lower cost and higher latency, and continuous mode as lower latency on an always-running cluster.
Which tools support continuous ETL?
Apache Kafka with Kafka Connect, AWS Glue streaming jobs, Amazon Data Firehose, Amazon Managed Service for Apache Flink and Databricks Lakeflow pipelines all document continuous or streaming use. Confirm current product names and status on each vendor page.
Does continuous ETL cost more than batch?
Usually yes for compute, because streaming jobs and continuous pipelines keep running. AWS Glue bills streaming ETL jobs hourly while they run, and Databricks says continuous pipelines need an always-running cluster.
When should I avoid continuous ETL?
Avoid it when data is consumed daily or weekly, when the source supports only full reloads, or when you cannot monitor failures such as API downtime, network congestion or an offline warehouse.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE