Key takeaway
- NLP in AI explained for enterprise leaders: how it works step by step, rules to transformers, key tasks, challenges and EU AI Act transparency duties.
What is NLP in AI?
Natural language processing (NLP) is the part of AI that lets software read, interpret and produce human language in text or speech. IBM describes it as a subfield of computer science and artificial intelligence that uses machine learning to help computers process and produce human language. The phrase "natural processing language" is a common search variant; the field is called natural language processing. For leaders, the practical point is that NLP turns unstructured text, such as emails, tickets, contracts and call transcripts, into structured signals that a team or a workflow can act on.
This guide covers the foundations: what NLP is, how it works step by step, which tasks matter in business, and what goes wrong. For techniques such as RAG and how NLP differs from large language models, read our natural language processing guide. For the split between understanding and generation, see NLP vs NLU vs NLG.
NLP sits inside AI alongside machine learning and deep learning. Rule-based systems, statistical models and neural networks are all used to handle language, and modern systems mostly use deep learning. If your team needs help choosing a starting point, our natural language processing services page describes how we work.
How does NLP work, step by step?
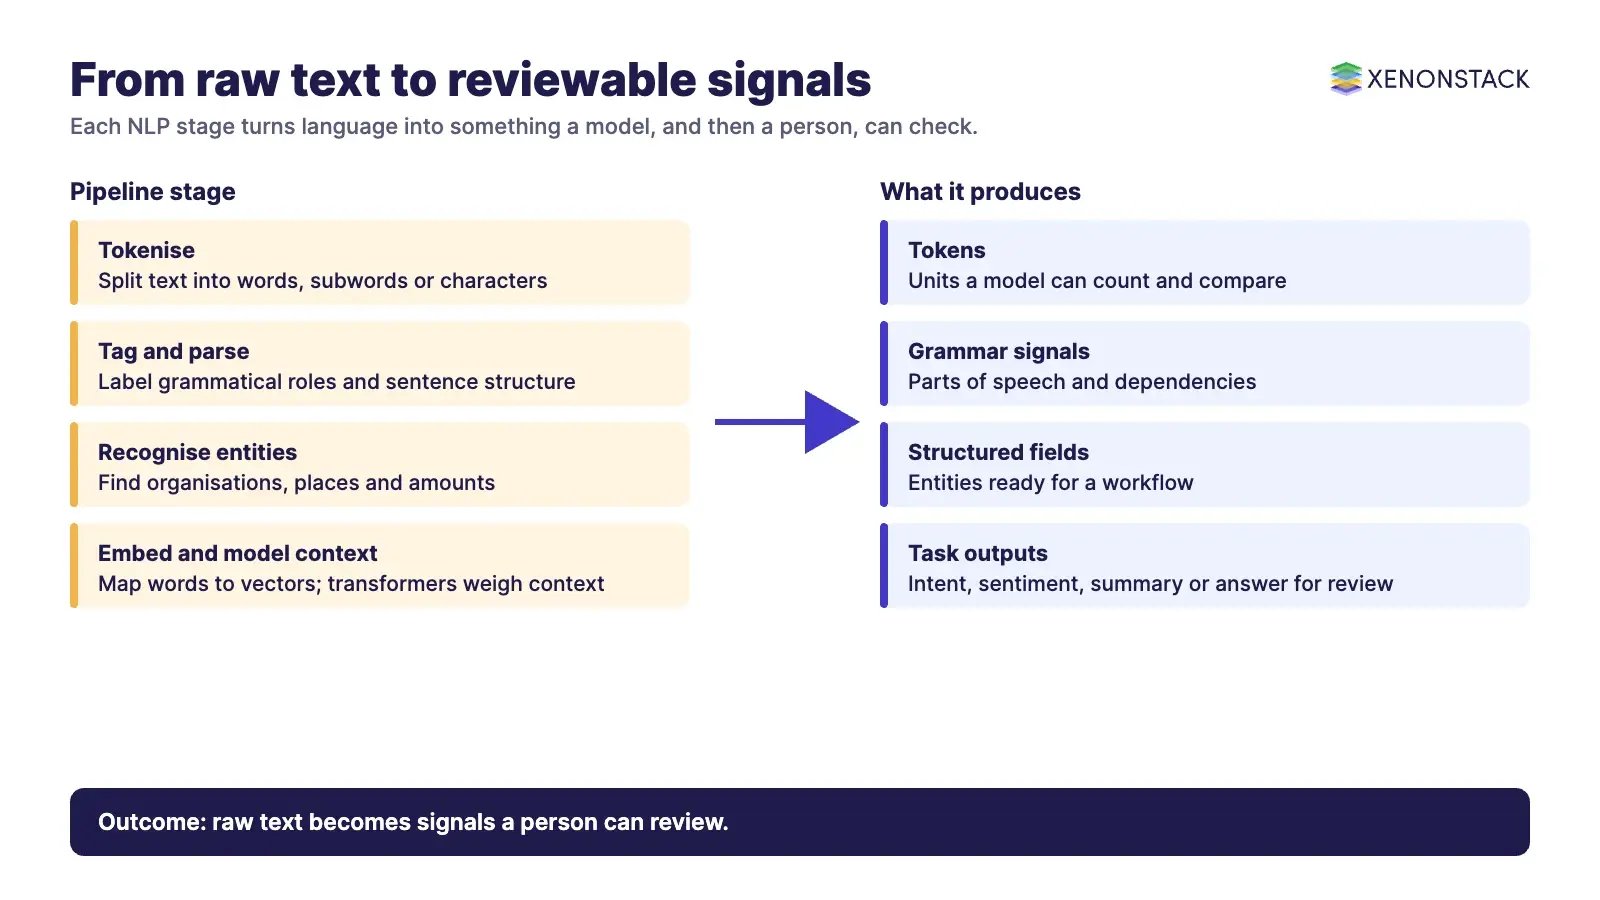
Most NLP systems pass text through a sequence of stages. Each stage turns raw characters into something a model can reason about. The table lists the stages in the order a typical pipeline applies them. Libraries such as spaCy expose most of these as documented features.
| Stage | What happens | Where to read more |
|---|---|---|
| Tokenisation | Text is split into tokens (words, subwords or characters) using language-specific rules. spaCy describes its tokenisation as non-destructive, so the original text can be rebuilt. | spaCy linguistic features |
| Part-of-speech tagging | Each token is labelled with its grammatical role, such as noun or verb, using the surrounding context. | IBM, what is NLP |
| Dependency parsing | Tokens are linked to the words they depend on, which shows how a sentence is built and supports noun-phrase extraction. | spaCy linguistic features |
| Named entity recognition | Spans of text are labelled as entities such as organisations, places and amounts of money. | Jurafsky and Martin, Speech and Language Processing |
| Word embeddings | Words are mapped to numeric vectors so that related words sit close together. Word2vec (Mikolov et al., arXiv, January 2013) made this efficient on very large text collections. | Efficient Estimation of Word Representations |
| Contextual models | Transformer models weigh every word against the others in a passage, so the same word can have a different representation in different sentences. | Attention Is All You Need |
The third edition draft of Jurafsky and Martin, Speech and Language Processing, is a free university-level reference. Its chapters cover tokenisation, embeddings, transformers and sequence labelling for parts of speech and named entities.
How did NLP move from rules to transformers?
IBM groups NLP into three approaches. Rules-based systems were the earliest and use if-then logic written by people. Statistical systems use machine learning to assign likelihoods to possible meanings. Deep learning systems learn from very large volumes of raw text and are, per IBM, the dominant approach today.
| Approach | How it works | When it fits | Limit |
|---|---|---|---|
| Rules-based | Hand-written patterns and if-then logic | Narrow, stable formats such as fixed-form documents | IBM notes these are limited and do not scale to varied language |
| Statistical | Machine learning on labelled text | Classification and tagging where labelled data exists | Needs labelled examples and feature design |
| Deep learning and transformers | Neural networks pre-trained on large text, then adapted | Open-ended language, many tasks, transfer to new domains | Needs governance, evaluation and human review |
Two papers mark the shift. The Transformer, introduced in "Attention Is All You Need" (Vaswani et al., 12 June 2017), reported 28.4 BLEU on WMT 2014 English-to-German translation. BERT (Devlin et al., 11 October 2018) showed that a model pre-trained on unlabelled text could be adapted to tasks such as question answering by adding a single output layer, and reported state-of-the-art results on eleven NLP benchmarks. You can read both on arXiv: Transformer and BERT.
Which NLP tasks matter to the business?
The same building blocks power many tasks. The table links each task to the signal it produces and where to go deeper in our other guides.
| Task | What it does | Typical enterprise use |
|---|---|---|
| Speech recognition | Converts spoken audio to text | Call transcripts, voice assistants, meeting notes |
| Named entity recognition | Finds people, organisations, places and amounts | Contract review, KYC, claims triage |
| Sentiment analysis | Classifies opinion in text | Customer feedback and social media monitoring; see NLP for sentiment analysis |
| Chatbots and voice assistants | Interpret a request and respond in language | Service desks and support; see NLP applications by function and industry |
| Summarisation and translation | Condense or convert text | Case notes, reports, multilingual support |
| Spelling and grammar correction | Detects errors and suggests fixes | Writing tools, form input checks |
To compare libraries and cloud APIs for these tasks, see our NLP tools guide. For working practices once a model is in use, read NLP best practices.
What are the main challenges of NLP?
Language is ambiguous, and most failures trace back to that. IBM lists four recurring problems, and two more come from everyday enterprise text.
| Challenge | What goes wrong | What helps |
|---|---|---|
| Multiple intentions in one message | A message such as "cancel my order and change my card" holds two requests, and a system that finds only one answers half of it | Intent detection that allows more than one intent, plus a human route when confidence is low |
| Misspellings and slang | Unclear or non-standard spelling, slang and accents break recognition, which IBM sums up as garbage in, garbage out | Normalisation, domain vocabulary and test sets drawn from real messages |
| Sarcasm and tone | Sarcasm, emphasis and exaggeration can change meaning in ways a model misreads | Human review for sensitive sentiment decisions |
| New vocabulary | New words and changing grammar leave a model unsure whether to guess or admit uncertainty | Regular re-evaluation and a clear "not sure" output |
| Biased training data | IBM notes that biased training data skews answers, which matters most for diverse user groups | Representative evaluation data and bias checks before release |
| Training effort | Large models need compute and labelled data to build; pre-trained models shorten this but still need adaptation and testing | Start from a pre-trained model and measure on your own text |
What does NLP governance need to cover?
Language systems talk to customers, staff and regulators, so governance matters from the first pilot. The EU AI Act, in Article 50 as published by the European Commission AI Act Service Desk, sets transparency duties. Providers must design AI systems that interact with people so that those people are informed they are dealing with AI, unless that is obvious. Providers of systems that generate synthetic text must mark outputs in a machine-readable way, with exceptions such as assistive editing. This is not legal advice; confirm the current text and dates on the official Article 50 page.
| Control | Why it matters | Practical step |
|---|---|---|
| Disclosure | Users should know when they are talking to AI | Label chatbots and generated text |
| Human review | Misread tone or intent can cause wrong decisions | Route low-confidence and high-impact cases to a person |
| Evaluation on your own data | Public benchmarks do not reflect your documents or customers | Keep a labelled test set and re-run it on each model change |
| Decision record | Teams need to explain why a system acted | Log inputs, outputs, model version and the policy applied |
Where language models feed agents that act, governed context matters. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents. AgentAnalyst lets teams ask questions of enterprise data in plain language and get real-time insights, and ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control.
How should an enterprise adopt NLP, and when is it the wrong choice?
Start with one text-heavy process where the answer can be checked, such as ticket routing or document triage. Collect a few hundred real examples and label them. Test a pre-trained model against that set before building anything custom. Add human review for low-confidence cases, then widen the scope. Our agentic AI for NLP guide covers the next step, where models plan and call tools.
NLP is the wrong tool when the data is already structured and a query or rule answers the question, when you cannot review errors, or when the text is too sparse or sensitive to process lawfully. In those cases a plain rule or a database query is cheaper and easier to audit.
To map one language-based decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What does NLP stand for in AI?
NLP stands for natural language processing. It is the part of AI that helps computers process and produce human language in text and speech. "Natural processing language" is a common mis-ordering of the same term.
How does NLP work?
A typical pipeline splits text into tokens, tags grammatical roles, parses sentence structure, finds entities and turns words into numeric vectors. Modern systems use transformer models that weigh each word against the others in a passage.
What is the difference between rules-based, statistical and deep learning NLP?
IBM describes rules-based NLP as hand-written if-then logic, statistical NLP as machine learning that assigns likelihoods to meanings, and deep learning NLP as neural networks trained on very large volumes of raw text, which is the dominant approach today.
What are the main challenges of NLP?
Messages with several intentions, misspellings and slang, sarcasm, new vocabulary and biased training data. Each can be reduced with better test data, human review for low-confidence cases and regular re-evaluation.
Does the EU AI Act affect NLP systems?
Article 50 sets transparency duties, including informing people when they interact with an AI system and marking synthetic text in a machine-readable way, with exceptions. This is not legal advice; confirm the current text on the official page.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE