Key takeaway
- LLM security explained for CISOs and architects: the OWASP 2025 risks, a layered control map, agent risks and a six-step adoption plan for enterprises.
LLM security is the set of controls that stop a large language model, and the applications and agents built around it, from leaking data, being manipulated or taking actions it should not. The reference most security teams start from is the OWASP Top 10 for LLM Applications, whose 2025 edition lists ten risks, from prompt injection to unbounded consumption. Most of them are failures of the application around the model, not of the model itself.
This guide is for CISOs, CTOs and architects who need a practical control set. It covers the main risks, a control map, what changes when LLMs become agents, and a sequence for adoption. For the technology background, see our guide to large language models, and for runtime visibility see LLM observability.
What are the main security risks of LLM applications?
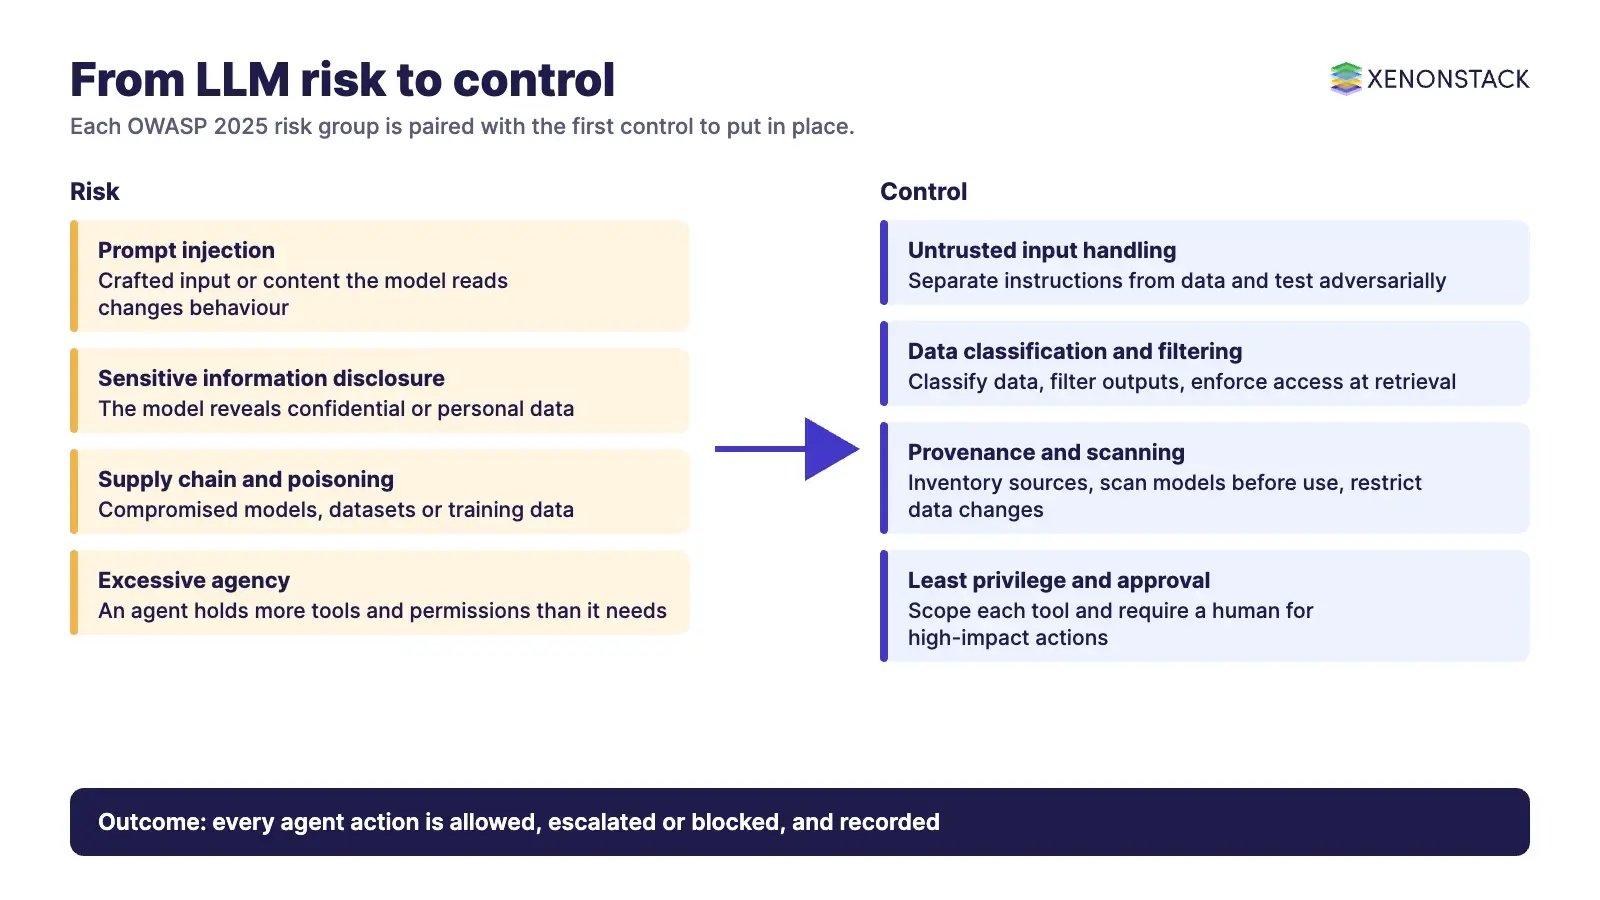
The OWASP Top 10 for LLM Applications (2025 edition) names ten risks. The table groups them by what a leader needs to decide, with the practical control for each. The control column is our guidance, not OWASP wording.
| OWASP 2025 risk | What it means in practice | First control to put in place |
|---|---|---|
| LLM01 Prompt Injection | Crafted input, or content the model reads, changes its behaviour | Treat all model input as untrusted; separate instructions from data; test with adversarial prompts |
| LLM02 Sensitive Information Disclosure | The model reveals personal, confidential or proprietary data | Classify data before it reaches the model; filter outputs; enforce access at retrieval |
| LLM03 Supply Chain | Compromised models, datasets or dependencies | Keep an inventory of models and sources; verify provenance; scan artefacts before use |
| LLM04 Data and Model Poisoning | Tampered training, fine-tuning or embedding data | Restrict and log who can change training data; review data sources |
| LLM05 Improper Output Handling | Model output is passed to other systems without checks | Validate and encode output before it reaches browsers, databases or tools |
| LLM06 Excessive Agency | The model or agent has more tools, permissions or autonomy than needed | Least privilege per tool; human approval for high-impact actions |
| LLM07 System Prompt Leakage | Hidden instructions or secrets are exposed | Keep secrets and authorisation logic out of prompts |
| LLM08 Vector and Embedding Weaknesses | Retrieval stores leak or are manipulated | Apply access control at document level in the vector store |
| LLM09 Misinformation | Confident but wrong output is acted on | Ground answers in sources; evaluate; keep a human in the loop for decisions |
| LLM10 Unbounded Consumption | Abuse drives cost, denial of service or model extraction | Rate limits, quotas and spend alerts per user and per key |
How do these risks change when LLMs become agents?
An assistant that only answers questions can leak or mislead. An agent that can call tools can also change records, send messages and move money. That is why excessive agency (LLM06) and prompt injection (LLM01) combine into the highest-impact scenario: an injected instruction arrives in an email or document, and the agent acts on it with its own permissions.
For agent platforms the controls shift from filtering text to governing actions. Give each agent a narrow identity, scope every tool to the minimum permission, isolate tenants, and require a human decision for high-severity actions. Our own security work for LLM and agent systems follows this pattern: adversarial testing, prompt-injection assessment, tool-misuse testing and remediation.
Governing actions needs a decision layer that records what the agent was allowed to do and why. AgentGRC maps policies and approval rules to agent actions before they reach business systems, so each action can be allowed, changed, escalated or blocked and the decision is recorded. It runs on ElixirData Context OS, which keeps governed context and decision traces together. For building and governing agents with humans in control, see ElixirClaw.
Which controls protect an LLM application end to end?
Think in layers. No single filter stops prompt injection, so defence in depth and zero trust apply: assume any layer can fail and limit what a failure can reach.
| Layer | Control | Why it matters |
|---|---|---|
| Identity and access | Strong authentication including multi-factor, role-based access, least privilege for models, data and tools | Limits who can query, change or export the model and its data |
| Data | Encryption in transit and at rest, key management, classification, retention limits | Reduces exposure if storage or a pipeline is breached |
| Model supply chain | Authenticated model registry, scanning before retraining, fine-tuning, evaluation or inference, checksums and signatures | Protects integrity and authenticity of model files |
| Input and output | Input validation, output filtering and encoding, content policies | Reduces injection and improper output handling |
| Runtime | Logging of prompts, tool calls and decisions; anomaly alerts; rate limits | Detects abuse and supports investigation |
| Process | Secure coding, code review, patching, vendor assessment, incident response and backup | Keeps the surrounding software and third parties in check |
Evidence matters as much as prevention. Keep an audit trail of what each model and agent did, under which policy and who approved it. The Audit Agent assembles the history, policy version and approvals for a past decision, but only for decisions made through Context OS and within the retention policy. Our guide to generative AI data security risks covers the data side in more depth.
How should an enterprise adopt LLM security step by step?
The NIST AI Risk Management Framework is voluntary guidance for managing AI risk, and NIST published a Generative AI Profile (NIST-AI-600-1) as a companion in July 2024. It is a useful frame for governance. The sequence below is our suggested order of work.
| Step | Action | Owner |
|---|---|---|
| 1. Inventory | List every model, prompt, data source, tool and vendor in use, including shadow use | Security and platform |
| 2. Classify | Rate each use case by data sensitivity and by what actions it can take | CISO and risk |
| 3. Baseline controls | Access control, encryption, logging, rate limits and secret handling | Platform and engineering |
| 4. Test | Adversarial and prompt-injection testing before launch and after each major change | Security and QA |
| 5. Govern actions | Approval rules for high-impact agent actions, with recorded decisions | Risk and product |
| 6. Monitor and respond | Runtime monitoring, incident playbooks, regular review of logs | Security operations |
Related reading: AI in cyber security, dynamic application security testing and insider threats.
What are the trade-offs, and when are controls not enough?
Filters block some attacks and also some legitimate use, so measure false positives. Human approval slows agents, so reserve it for high-severity actions. Open-source and third-party models cut cost but widen the supply chain, so verify provenance. Embedded and edge deployments have fewer resources for scanning and monitoring, so decide up front what must run locally. None of these controls makes a model correct, so evaluation and human review stay in place for consequential decisions.
To map one decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is LLM security?
LLM security is the set of controls that protect a large language model, its data and the applications and agents around it from leakage, manipulation and misuse. The OWASP Top 10 for LLM Applications 2025 is a common reference list.
What is prompt injection?
Prompt injection is the first risk on the OWASP 2025 list (LLM01). Crafted input, or content the model reads, changes the model's behaviour. Treat all model input as untrusted and test with adversarial prompts.
Why is excessive agency a concern?
OWASP lists excessive agency as LLM06. When a model or agent has more tools, permissions or autonomy than it needs, an injected or mistaken instruction can cause real actions. Use least privilege and human approval for high-impact actions.
How do we protect models in storage and transit?
Store models in an authenticated registry, scan them before use, encrypt them at rest and in transit, and verify checksums and signatures to confirm integrity and authenticity.
Does NIST cover generative AI?
Yes. NIST released the Generative AI Profile (NIST-AI-600-1) on 26 July 2024 as a companion to the AI Risk Management Framework. Both are voluntary guidance.
Where should a team start?
Start with an inventory of models, data sources, tools and vendors, classify each use case by risk, put baseline access, encryption and logging controls in place, then test adversarially before launch.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE