Key takeaway
- Foundation models are large AI models trained on broad data and adapted to many tasks. Learn types, API vs RAG vs fine-tuning, EU AI Act and evaluation.
A foundation model is a large AI model trained on broad data, usually with self-supervision at scale, that can then be adapted to many different tasks. Stanford's Center for Research on Foundation Models (CRFM) coined the term in 2021 for exactly this pattern: one expensive pre-trained model, reused across hundreds of downstream uses through prompting, retrieval or fine-tuning. Large language models are the best-known example, but the same approach now covers images, video, audio and time-series data.
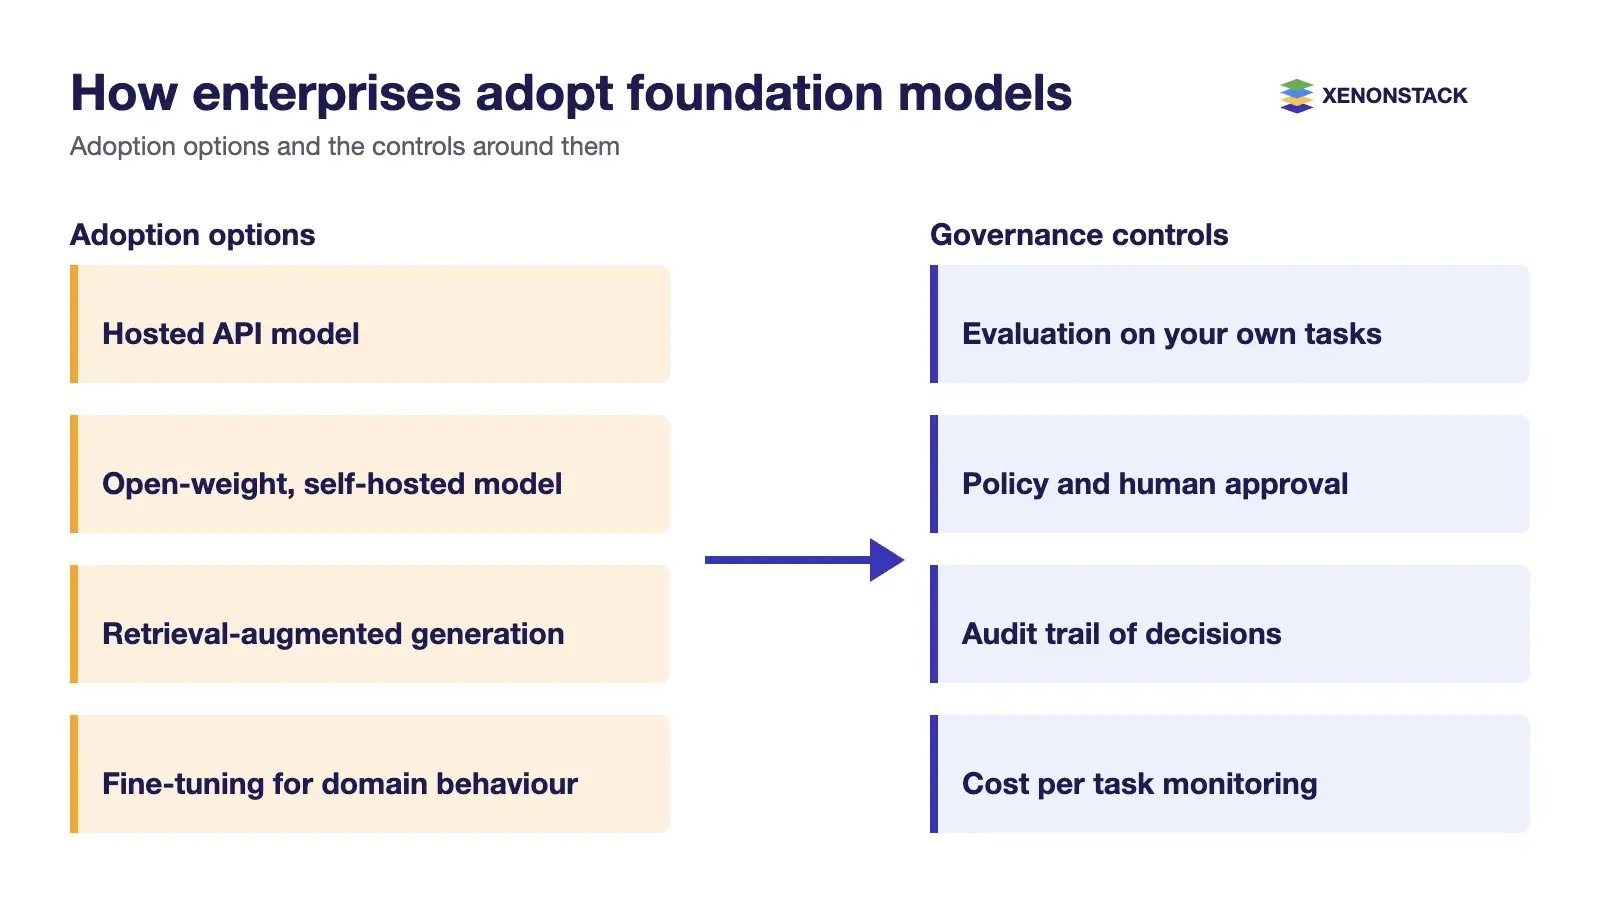
For an enterprise, the real question is not what a foundation model is, but how to use one safely and economically. That means choosing between a hosted API, an open-weight model, fine-tuning or retrieval-augmented generation (RAG); budgeting for inference rather than training; meeting new obligations such as the EU AI Act rules for general-purpose AI; and evaluating models on your own tasks rather than on public leaderboards. This guide covers each of those decisions.
What is a foundation model?
The Stanford CRFM report On the Opportunities and Risks of Foundation Models (Bommasani et al., 2021) defines a foundation model as any model trained on broad data, generally using self-supervision at scale, that can be adapted to a wide range of downstream tasks (Stanford CRFM). Two ideas sit inside that definition.
- Scale and self-supervision. The model learns from large volumes of unlabelled data, for example by predicting the next token in text, so it does not need a hand-labelled dataset for every task.
- Adaptation. The same base model is specialised later, through prompts, retrieved context, fine-tuning or tool use. The value comes from reuse, not from the base model on its own.
This is a shift from the older pattern of one model per task. A single foundation model can summarise contracts, classify support tickets, draft code and answer questions over policy documents. The flip side is that any weakness in the base model, such as a bias, a gap in knowledge or a security flaw, is inherited by every application built on it. CRFM calls this homogenisation, and it is the main reason governance matters more than it did for narrow models.
Why do foundation models matter to enterprise leaders now?
Foundation models change the economics of AI. Training a frontier model costs a great deal, but almost no enterprise needs to do it. The work moves from building models to integrating them: connecting a model to governed data, policies and workflows, and controlling what it is allowed to decide. Three consequences follow for leadership.
- Time to first use is short. A team can prototype on a hosted model in days. The long pole is data access, security review and evaluation, not modelling.
- Cost shifts to inference. Spend grows with usage: tokens, images or forecasts served. Architecture choices such as model size, caching and retrieval decide the bill.
- Accountability does not move to the vendor. If a model gives a wrong answer inside your process, the decision is still yours. Regulators increasingly expect records of which model, data and policy produced an outcome.
What does a foundation model architecture look like in the enterprise?
The model is one layer in a larger stack. Most production failures happen in the layers around it, not inside the model itself.
| Layer | What it does | Where it breaks |
|---|---|---|
| Foundation model | Pre-trained LLM, multimodal, vision or time-series model, hosted or self-run | Hallucination, outdated knowledge, version changes by the provider |
| Adaptation | Prompts, retrieval (RAG), fine-tuning, adapters such as LoRA | Poor retrieval quality, overfitting on small fine-tuning sets |
| Context and data | Governed access to documents, records and features, with lineage and permissions | Stale or ungoverned data, permission leaks across users |
| Orchestration and agents | Tool calls, workflows and multi-step agents that act on systems | Unbounded actions, no human approval for high-impact steps |
| Governance and evaluation | Policy checks, evaluation suites, monitoring, audit trails, cost controls | Missing records of which model and data produced a decision |
Two trade-offs dominate the design. The first is latency versus quality: larger models answer harder questions but are slower and dearer, so many teams route simple requests to a small model and escalate only when needed. The second is control versus convenience: hosted APIs are easy to start with, while self-hosted open-weight models give data residency and version control at the price of running GPU infrastructure. A layer that keeps governed context, versioned policy and decision traces above the models, such as ElixirData's decision layer, lets you change models without rebuilding your controls.
What types of foundation models are there?
Foundation models are usually grouped by the data they learn from and produce. The boundaries are blurring, as more models accept several input types at once.
| Type | Learns from | Typical enterprise uses |
|---|---|---|
| Large language models (LLMs) | Text and code | Search and question answering over documents, drafting, summarisation, code assistance, agent reasoning |
| Multimodal models | Text with images, audio or video | Document and form understanding, visual inspection with explanations, meeting and call analysis |
| Vision models | Images and video | Defect detection, image classification and segmentation, video analytics |
| Time-series models | Sequences of measurements over time | Demand and capacity forecasting, sensor and telemetry anomaly detection |
Large language models
LLMs are transformer models trained to predict text. They are the default engine for assistants and agents because language is the interface to most business knowledge. Our guide to large language models covers how they are trained and served.
Multimodal and vision models
Multimodal models combine text with images, audio or video, so a single model can read a scanned invoice or describe a fault in a photo. Pure vision foundation models remain useful where only images matter and latency is tight, for example on a production line. See multimodal AI agents in the enterprise for patterns that combine both.
Time-series foundation models
A newer group applies the same idea to forecasting. Google Research introduced TimesFM in 2024, and its TimesFM-3 release is pre-trained on more than one trillion time points and supports multivariate forecasting with covariates (Google Research). Amazon's Chronos family, including Chronos-2, takes a similar approach (arXiv). These models can give a reasonable zero-shot forecast for a new series, which helps when history is short. They do not remove the need for sound time-series analysis and backtesting on your own data.
Should you use an API, an open-weight model, fine-tuning or RAG?
These are not exclusive options. Most enterprise systems combine a model source (API or open-weight) with an adaptation method (prompting, RAG or fine-tuning). Choose each based on data sensitivity, how often knowledge changes and how specialised the behaviour must be.
| Choose | When | Watch out for |
|---|---|---|
| Hosted API model | You need top capability quickly, volumes are moderate and data can leave your boundary under contract | Provider version changes, data residency, per-token cost at scale |
| Open-weight model, self-hosted | Data must stay on-premises or in your cloud, you need fixed versions or predictable cost at high volume | GPU capacity, patching, licence terms, in-house serving skills |
| Retrieval-augmented generation (RAG) | Answers must reflect current, private documents and cite sources; knowledge changes often | Retrieval quality, document permissions, chunking and freshness |
| Fine-tuning | You need a consistent format, tone or domain behaviour that prompting cannot reach, or a smaller model to match a larger one on a narrow task | Labelled data quality, retraining when the base model changes, possible provider obligations under the EU AI Act if the modification is significant |
A practical default is to start with a hosted or open-weight model plus RAG, measure where it fails, and fine-tune only for the gaps that remain. Retrieval alone is not always enough for multi-step decisions; we explain why in why RAG isn't enough for enterprise AI.
What do foundation models cost, and how do you control it?
For most enterprises, the cost is in using models, not training them. The main drivers are the size of the model, the number of tokens (or images, or forecasts) processed per request, request volume, and the hidden work of evaluation and monitoring.
- Right-size the model. Route routine requests to a smaller model and reserve the largest model for hard cases.
- Trim the context. Better retrieval sends fewer, more relevant passages, which cuts tokens and often improves accuracy.
- Cache repeated work. Reuse answers and embeddings for common queries and documents.
- Budget per use case. Track cost per completed task, not cost per token, so you can compare AI against the current process.
How does the EU AI Act regulate foundation models?
The EU AI Act uses the term general-purpose AI (GPAI) model rather than foundation model. According to the European Commission, GPAI obligations entered into application on 2 August 2025 (European Commission).
| Who | Obligations |
|---|---|
| All GPAI model providers | Draw up technical documentation, put in place a copyright policy, publish a summary of the content used for training |
| Providers of GPAI models with systemic risk | Also notify the Commission, assess and mitigate risks, report serious incidents and maintain cybersecurity protections |
The Commission's guidelines treat a model trained with more than 1023 FLOP that can generate language as an indicative GPAI model, and presume systemic risk above 1025 FLOP, a threshold the Commission notes is under review. The Commission's enforcement powers apply from 2 August 2026, and models placed on the market before 2 August 2025 have until 2 August 2027 to comply (Commission GPAI guidelines). The voluntary GPAI Code of Practice has been confirmed by the Commission and Member States as an adequate way to demonstrate compliance.
Most enterprises are deployers, not providers. The guidelines say only those making significant modifications to a model take on provider obligations, so routine prompting and RAG do not. Your obligations still arise from what you build: a model used in a high-risk use case brings the AI Act's high-risk system rules into play. Outside the EU, the NIST Generative AI Profile (AI 600-1) is a useful companion for risk management. Agents such as AgentGRC can help map controls to these frameworks, and governance as code keeps those controls versioned and testable.
How should you evaluate a foundation model?
Public benchmarks are a starting filter, not a decision. Stanford CRFM's HELM project showed the value of measuring several dimensions at once, such as accuracy, robustness, fairness and efficiency, rather than a single score. Apply the same thinking to your own use cases.
- Build a task set. Collect real examples from the process, with expected answers agreed by domain experts.
- Measure more than accuracy. Include groundedness against sources, refusal behaviour, safety, latency and cost per task.
- Test the whole system. Evaluate model plus retrieval plus tools, because that is what users see.
- Re-run on every change. A new model version, prompt or index can shift results; treat evaluation as regression testing.
- Monitor in production. Sample live outputs for review and track drift over time.
Tools such as AgentEvaluation help run these suites repeatably. Our overview of generative AI model types, training and evaluation goes deeper on metrics.
How do you adopt foundation models, and what should you measure?
- Pick one decision-heavy process with clear owners and measurable outcomes, not a general chatbot.
- Govern the data first: permissions, lineage and freshness for the documents and records the model will use.
- Prototype with two or three models against the same task set, then choose on quality, cost and control.
- Add policy and human approval for high-impact actions before widening access.
- Scale with a shared platform so the next use case reuses evaluation, guardrails and audit trails.
Useful metrics include task accuracy against expert answers, share of answers grounded in cited sources, escalation and override rate, cycle time compared with the current process, cost per completed task, and the number of incidents or policy violations.
When is a foundation model not the answer?
- When a deterministic rule or SQL query already gives the right answer reliably and cheaply.
- When decisions must be exactly reproducible and fully explainable, and you cannot add a review step.
- When you lack the data access or ownership to ground the model, so it would rely on guesswork.
- When a small, task-specific model trained on your labelled data meets the target at a fraction of the cost and latency.
In these cases, a foundation model may still help around the edges, for example drafting rules or explaining results, while the core decision stays with conventional software.
To map one decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is a foundation model in simple terms?
A foundation model is a large AI model trained on broad data, usually with self-supervision at scale, that can be adapted to many downstream tasks through prompting, retrieval or fine-tuning. Stanford CRFM introduced the term in 2021.
What are the main types of foundation models?
The main types are large language models for text and code, multimodal models that combine text with images, audio or video, vision models for images and video, and time-series models such as Google's TimesFM and Amazon's Chronos for forecasting.
Is a foundation model the same as a large language model?
No. A large language model is one type of foundation model. Foundation models also include multimodal, vision and time-series models that are pre-trained on broad data and adapted to many tasks.
Should we use RAG or fine-tuning?
Use RAG when answers must reflect current, private documents and cite sources. Use fine-tuning when you need consistent format, tone or domain behaviour that prompting and retrieval cannot reach. Many teams start with RAG and fine-tune only for remaining gaps.
What does the EU AI Act require for foundation models?
The EU AI Act calls them general-purpose AI models. Since 2 August 2025, providers must keep technical documentation, have a copyright policy and publish a training content summary. Models with systemic risk also need risk assessment, incident reporting and cybersecurity. Commission enforcement powers apply from 2 August 2026.
Do enterprises that only use foundation models become GPAI providers?
Generally not. The Commission's guidelines say only those making significant modifications to a model take on GPAI provider obligations. Obligations can still arise from the use case, for example if the model is part of a high-risk AI system.
How should we evaluate a foundation model?
Build a task set from real examples, measure accuracy, groundedness, safety, latency and cost per task, test the whole system including retrieval and tools, and re-run the suite on every model, prompt or index change.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE