Key takeaway
- Learn how to run data reliability in production: the dimensions to measure, SLOs for data, pipeline controls and which tools still fit in 2027.
What is data reliability, and why does it matter to leaders?
Data reliability is the degree to which people and systems can depend on a dataset being complete, accurate, unique, current and consistent every time it is used, not only on the day it was checked. For a CTO or chief data officer, the practical test is simple: can a dashboard, model or AI agent act on this data today without a person double-checking it first?
This guide treats reliability as an operating practice with owners, targets and alerts. For the fundamentals and the benefits, read our companion post on data reliability benefits and framework; here we cover how to run it in production, which tools still fit in 2026, and when to stop adding checks.
What are the dimensions of reliable data?
Reliability is not one property. Treat each dimension below as something you measure, then agree a target for the datasets that feed decisions.
| Dimension | What to measure | Typical failure | Where to check it |
|---|---|---|---|
| Validity | Share of values in the expected type, format and range | A negative water volume, or a date stored as text | At ingestion |
| Completeness | Share of required fields and expected records present | Missing email addresses; a sensor that stops reporting | At ingestion and after each load |
| Uniqueness | Share of records with no duplicates on the business key | A pipeline restart that loads the same batch twice | After each load |
| Freshness | Age of the newest record against the expected cadence | A nightly job that silently stops | On a schedule, with alerting |
| Lineage | Whether each field can be traced to its source and transformations | A metric changes and no one can say why | Across the pipeline |
| Access integrity | Who can change the data, and whether changes are logged | An unreviewed edit alters a reported figure | At the storage layer |
Validity and reliability are not the same thing. A dataset can pass every format check and still be unreliable because rows are missing or duplicated. For example, an employee file with correctly formatted records but several blank email fields is valid and still fails the mailing it was meant to support.
How do you turn data reliability into an SLO?
Site reliability engineering already gives a vocabulary for this. Google's SRE book defines a service level indicator (SLI) as "a carefully defined quantitative measure of some aspect of the level of service that is provided" and a service level objective (SLO) as "a target value or range of values for a service level that is measured by an SLI" (source: Google SRE book). Applied to data, the SLI might be the percentage of orders loaded with no null customer key, and the SLO the level that percentage must reach each day.
Start with the five to ten datasets that feed revenue, risk or regulatory reports. Give each one an owner, one to three SLIs and a target agreed with its consumers. Keep the number of SLOs small: an SLO nobody acts on is noise.
How do you make data reliable across the pipeline?
Check at ingestion
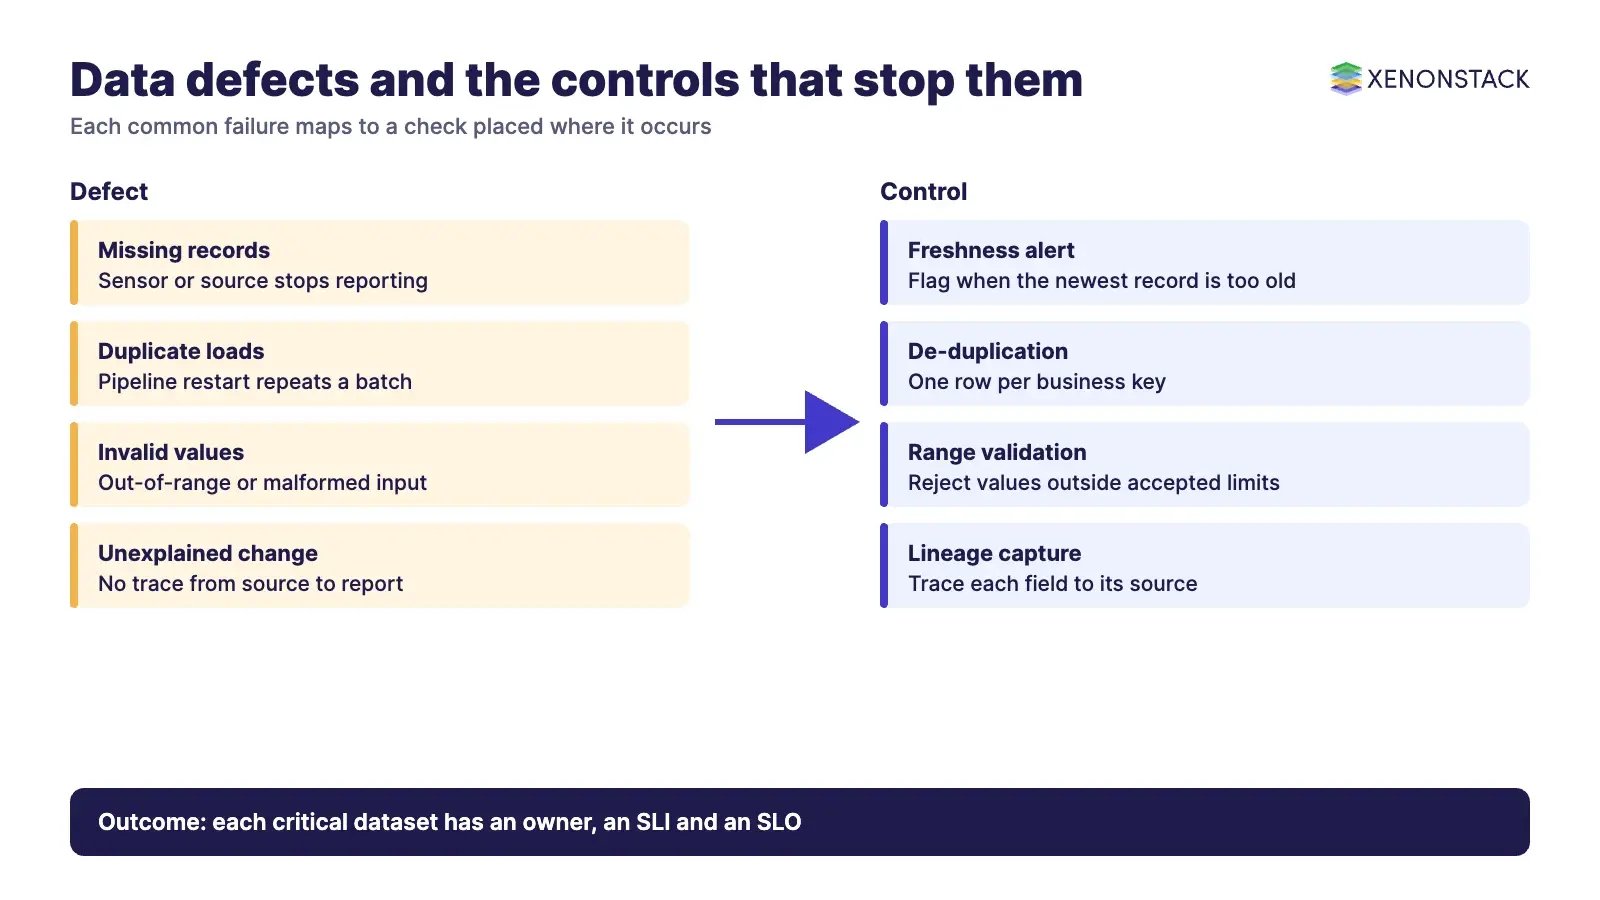
Reject or quarantine nulls, out-of-range values and malformed records as data enters, and ingest only what a use case needs. Catching a defect here is cheaper than repairing it after it has been loaded and used downstream.
Trace through transformation
Record lineage so that every change between source and destination is visible. OpenLineage describes itself as "an open platform for collection and analysis of data lineage" and offers a standard API for capturing events about datasets, jobs and runs. See our guide to data lineage tools for options.
Validate before storage
Map each record to the target schema and run constraint checks before it reaches the warehouse or lake. Our post on data validation methods covers the techniques in more detail.
Monitor continuously
Data that was reliable at load can degrade as sources, schemas and volumes change. Track freshness, volume and constraint pass rates over time, and alert the dataset owner when an SLO is at risk.
Which tools still fit a data reliability programme?
No single tool delivers reliability. Teams combine validation, lineage and monitoring components, and the open-source landscape has changed since many older guides were written.
| Tool | What it does | When it fits | Current status (read 11 Nov 2026) |
|---|---|---|---|
| Deequ (AWS Labs) | Defines "unit tests for data" as constraints and runs them as Spark jobs, with profiling and anomaly detection on metrics | Spark-based pipelines | Active repository; Deequ 2.x covers Spark 3.1 to 3.5 and 1.x covers Spark 3.0 and earlier |
| Apache Atlas | A "data governance and metadata framework for Hadoop" | Hadoop-centred estates that need a metadata catalogue | Listed on atlas.apache.org; check the project page for the release that suits your stack |
| OpenLineage | Open standard and client libraries for lineage events | Estates with several schedulers, warehouses and engines | Open specification with a technical steering committee |
| Apache Griffin | Batch and streaming data quality measurement | Not recommended for new work | Project page states 'This project has retired' |
| Great Expectations (GX Core) | Open-source Python library for declaring checks on data | Python-based pipelines | Documentation live; see docs.greatexpectations.io |
The change worth noting is Apache Griffin. Older guides, including the earlier version of this one, list it as a data quality tool. Its project page now says it has retired, so choose a maintained alternative for new work. See the Apache Griffin page for details.
Sources: Deequ repository, Apache Atlas, OpenLineage, Great Expectations documentation.
What does an unreliable pipeline look like in practice?
Consider an illustrative farm analytics pipeline. IoT sensors send readings, through a pipeline, to a database that feeds a yield forecast. Two ordinary events break it: a sensor goes offline and leaves gaps, and a pipeline restart loads a batch twice. The forecast then rests on incomplete and duplicated data, and nobody notices until the numbers look wrong.
| Stage | Control | Example rule |
|---|---|---|
| Sensor and collection | Reliable hardware and a heartbeat check | Alert if a sensor sends no reading for the agreed interval |
| Stream filter | Range validation on accepted values | Water volume must be an integer between 0 and the tank capacity (2,000 in this example) |
| Load | Schema mapping and de-duplication | One row per sensor and timestamp |
| Database | Lineage and freshness monitoring | Alert if the newest record is older than the expected cadence |
Complete reliability cannot be achieved in one step. Apply controls where the defects actually occur, then widen coverage as the first controls prove their value.
What do reliable data and AI agents have in common?
As teams let AI agents act on enterprise data, unreliable inputs turn into unreliable actions. Two things help: a clear record of the context and policy behind each decision, and a way to ask questions of governed data and check the answer. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents. AgentAnalyst lets teams ask questions of enterprise data in plain language and get real-time insights, and the Audit Agent assembles audit evidence for past decisions, although its full lineage covers only decisions made through the platform.
When is a reliability programme not worth it?
Not every dataset needs an SLO. A one-off analysis, a prototype or a low-impact internal report may need only basic validation. Reserve owners, targets and alerting for data that drives money, risk or compliance. Over-instrumenting low-value data adds alert fatigue and cost without improving decisions.
How should you sequence adoption?
| Step | Action | Outcome |
|---|---|---|
| 1 | List the datasets behind key decisions and name an owner for each | Clear accountability |
| 2 | Add validity, completeness and uniqueness checks at ingestion | Defects stopped early |
| 3 | Capture lineage for those datasets | Faster root-cause analysis |
| 4 | Define one to three SLIs and an SLO per dataset | Shared definition of 'reliable' |
| 5 | Add freshness and volume monitoring with alerts | Problems found before consumers find them |
| 6 | Review SLO misses monthly and retire checks that never fire | A programme that stays lean |
To map one data-dependent decision your agents or analysts make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
What should you plan for in 2027?
If your checks run as Spark jobs, the Spark release you depend on matters for the year ahead.
- November 2027: the Apache Spark versioning policy states that the Spark 3.5 extended long term support period will end in November 2027.
- The same page says that period covers security fixes only, so pipelines still on Spark 3.5 for Deequ checks should have an upgrade plan before then.
- Keep each dataset owner, SLO and freshness alert under review as engines change, and retire checks that never fire.
Treat the upgrade as a reliability project in its own right and run your validity, completeness and uniqueness checks again afterwards.
FAQs on data reliability
What is the difference between data reliability and data validity?
Validity asks whether data is stored and formatted correctly. Reliability asks whether the data can be trusted: complete, unique, current and traceable. A dataset can be valid and still unreliable if records are missing or duplicated.
How do you measure data reliability?
Choose indicators for each dimension, such as the share of records passing validity checks, the share of required fields present, duplicate rate and the age of the newest record. Then set a target for each indicator on the datasets that matter most.
What is an SLO for data?
It applies the SRE idea of a service level objective: a target value or range for a service level measured by an indicator. For data, it might be the share of daily loads that finish with no null key by a set time.
Is Apache Griffin still maintained?
No. The Apache Griffin project page states that the project has retired, so use a maintained alternative for new work.
Which tools help with data reliability?
Deequ runs constraint checks as Spark jobs, OpenLineage standardises lineage events, and Great Expectations offers a Python library for data checks. Most teams combine several tools rather than relying on one.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE