Key takeaway
- Five data integration patterns explained: migration, broadcast, bi-directional sync, correlation and aggregation, with how to choose and govern them.
What is a data integration pattern?
A data integration pattern is a repeatable way to move or combine data between systems so that each system sees what it needs. The five patterns most teams use are data migration, broadcast, bi-directional sync, correlation and aggregation. You choose by asking how many systems are involved, which way the data flows and how fresh it must be.
This guide defines each pattern with an example, shows how to choose between them, and covers the controls that keep integrated data trustworthy. For tooling, see our guide to data integration tools; for the collection step that feeds most patterns, see data ingestion.
What are the five data integration patterns?
The five-way split below is a common practitioner classification used by integration platform vendors. It is not a formal standard. The formal reference for messaging-based integration is the catalogue of Enterprise Integration Patterns by Gregor Hohpe and Bobby Woolf, which describes four integration styles: File Transfer, Shared Database, Remote Procedure Invocation and Messaging (source: enterpriseintegrationpatterns.com, read 13 Nov 2026).
| Pattern | What it does | Typical trigger | Direction |
|---|---|---|---|
| Data migration | Moves a defined set of data from one system to another | Replacing a system, or loading a warehouse | One way, scheduled or one-off |
| Broadcast | Sends each change from one source to many destinations | A record changes in the system of record | One to many, near real time |
| Bi-directional sync | Keeps two systems consistent, each able to change data | Two apps share the same customer or order | Two way, event or schedule |
| Correlation | Syncs only the records that exist in both systems | Matching customers or employees across systems | Two way, on match |
| Aggregation | Collects data from many sources into one view | Reporting, analytics, a single customer view | Many to one |
How does the data migration pattern work?
Migration moves a defined set of records from a source to a target. Use it when you retire a system, consolidate databases or load a warehouse. A typical design has five steps:
- Define the source and the target.
- Choose the schedule: one-off, scheduled or continuous.
- Set the selection criteria, for example only applications received since the last run.
- Transform and enrich the data into the target format.
- Report the status, including counts of records moved and rejected.
Example: candidate records in a job portal database must appear in a recruitment application. A scheduled job selects new applications, maps fields and loads them, then reports row counts.
When should you use the broadcast pattern?
Broadcast sends each change from one source to one or many destinations, usually only the data changed since the last send. It suits cases where a source of truth feeds several consumers, such as a job portal publishing every new application to HR, analytics and notification systems. In messaging terms this is close to the Publish-Subscribe Channel, which the Enterprise Integration Patterns catalogue describes as one that "delivers a copy of a particular event to each receiver".
There are three ways to trigger it: the source sends the change with its data, the source sends a notification and the integration layer fetches the data, or the integration layer polls the source for changes. The trade-off is delivery assurance. If the source does not learn whether a destination received the data, a failure can lose changes unless you add retries, a durable queue and monitoring. Because retries can deliver a message twice, design receivers as an Idempotent Receiver, which the same catalogue defines as one that "can safely receive the same message multiple times".
For database sources, change data capture (CDC) is a common trigger. Debezium, an open-source CDC platform, describes itself as "a distributed platform that converts information from your existing databases into event streams", using Kafka Connect-compatible connectors that read the database log (source: debezium.io tutorial, read 13 Nov 2026). Confirm connector support for your database on the official Debezium page. For streaming, see our guide to real-time streaming.
What is bi-directional sync, and how does correlation differ?
Bi-directional sync lets two systems work towards one business goal, each reading and writing the other. Example: a job portal sends student data to an analytics application, which returns a report to the portal. The portal gains analysis without building it. The main risk is conflicting edits, so define which system wins for each field and how conflicts are logged.
Correlation is similar but narrower. It syncs a record only when it exists in both systems, or when one system needs a copy. Example: when an employee transfers from office A to office B, the correlation pattern carries the employee record across instead of re-keying it. Match rules (which keys identify the same person or order) are the design decision that matters here.
How does the aggregation pattern create a unified view?
Aggregation collects data from several sources into one place for analysis and applications. In messaging terms, the Aggregator is described as a stateful filter that collects individual messages until a complete set of related messages has arrived, then publishes a single message. Rules to hold to when you build it:
- No duplicate records in the aggregate store.
- Changes in one source reach the aggregate without manual work.
- The aggregate is not hand-managed; it is rebuilt or updated by the pipeline.
Aggregation is where data silos are removed, but it is also where data quality problems show up first. See our guide to the big data platform for the storage and governance layers that usually sit behind it.
How do you choose by source, destination and transfer type?
Three questions narrow the options before you pick a tool.
| Question | Options | Design implication |
|---|---|---|
| What is the source? | APIs, usually returning JSON; file systems or object stores such as Hadoop or S3 | APIs need rate limits and pagination handling; files need schema and format agreements |
| What is the destination? | Analytical store (organised, queryable) or data store (backup, minimal structure) | Analytical targets need modelling and quality checks; backups need retention rules |
| How fast must data move? | Real time, near real time or batch | Real time needs streaming or CDC and idempotent receivers; batch needs scheduling and reruns |
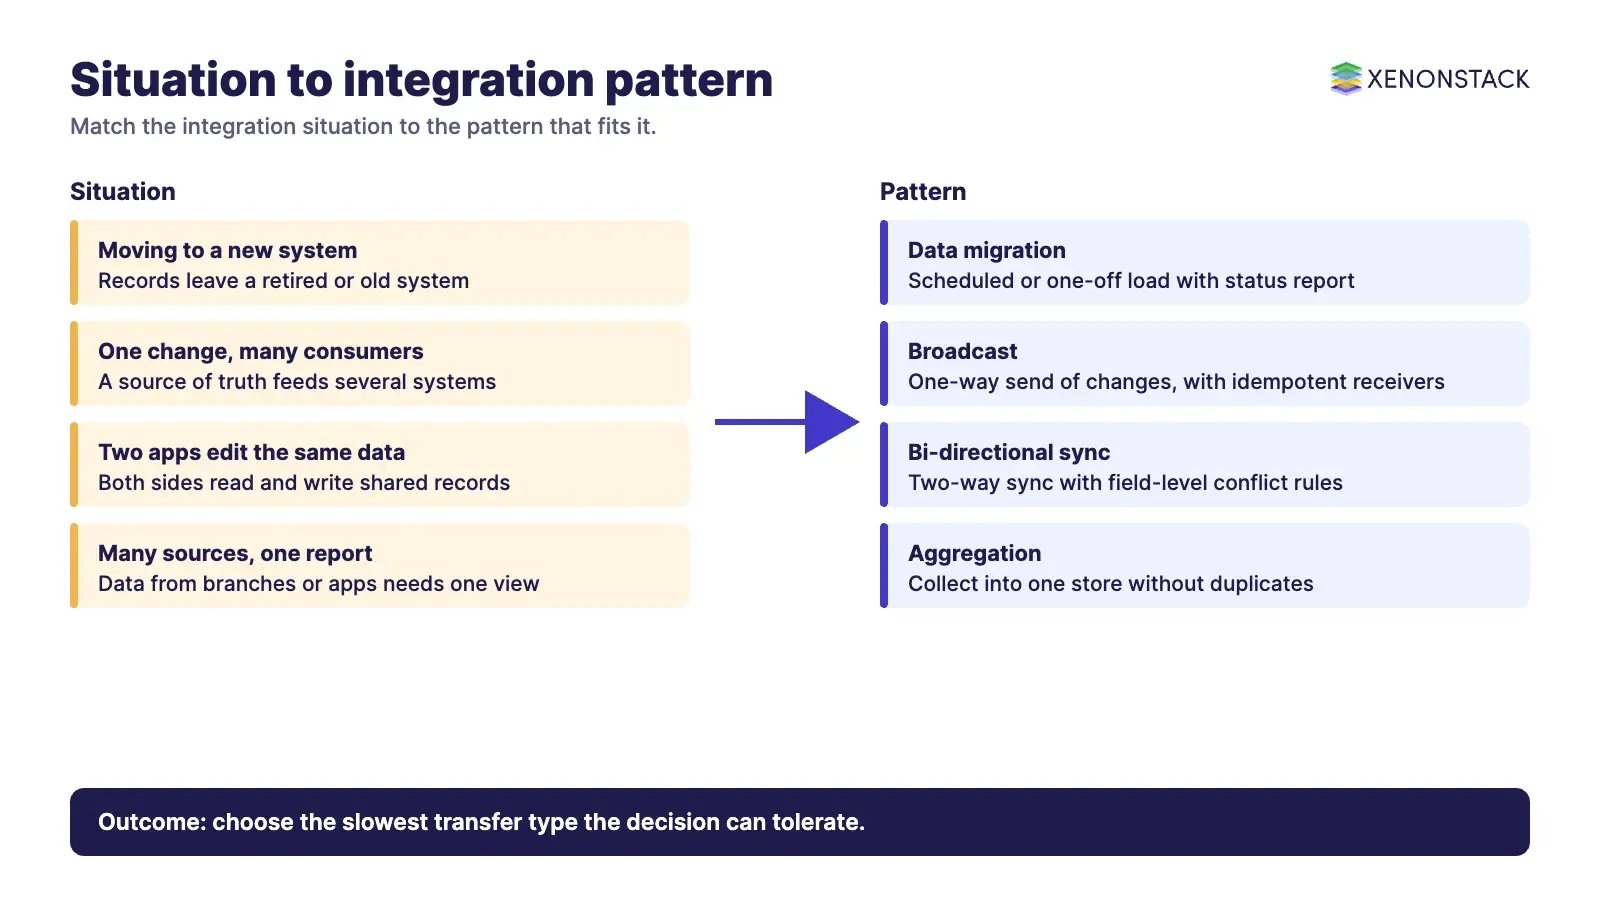
As a guide: payments or fraud checks need real time; monitoring and sensor processing usually tolerate near real time; payroll and periodic reporting suit batch. Choose the slowest transfer type the business decision can tolerate, because it is cheaper to run and easier to recover.
Which pattern fits which situation?
| Situation | Pattern | Watch for |
|---|---|---|
| Replacing or consolidating a system | Data migration | Reconciliation of record counts and rejected rows |
| One change must reach several systems | Broadcast | Lost or duplicated messages; idempotent receivers |
| Two applications edit the same entity | Bi-directional sync | Conflict rules and loops |
| Same person or order lives in two systems | Correlation | Match keys and false matches |
| One reporting or analytics view from many sources | Aggregation | Duplicates, late data and quality |
What does a governed integration pattern need?
Patterns move data; governance decides whether the result can be trusted and used. The barriers teams meet most often are slow adoption of new technology, poor data quality and unwanted access to data. Treat these as design requirements:
- Quality gates: validate schema, nulls and duplicates at the boundary, and quarantine failures rather than loading them.
- Access control: give each pipeline a least-privilege identity and mask personal data before it reaches wide-access stores.
- Lineage and audit: record which source, rule and run produced each target record, so a wrong number can be traced.
- Redundancy by design: replicas are sometimes useful, for example to run queries against a copy rather than the operational database, but each replica needs a defined owner and a sync rule, or sales and marketing will hold different addresses for the same customer.
- Monitoring: alert on volume, latency and failure, not only on job completion.
When AI agents consume integrated data, the same controls matter more, because an agent acts on what it reads. ElixirData's Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents, and AgentAnalyst lets teams ask questions of enterprise data in plain language and get real-time insights.
What are the trade-offs, and when should you not build a custom pattern?
- Point-to-point links multiply. Each new pair of systems adds integrations to maintain. Prefer a shared messaging or streaming layer once more than a few systems exchange data.
- Real time costs more. Streaming and CDC add infrastructure and on-call load. Do not use them where a nightly batch meets the decision need.
- Bi-directional sync is the hardest pattern to keep correct. If one system can be the system of record, use one-way broadcast instead.
- Do not hand-build what a platform already provides. Check the options in our data integration tools guide first.
How should you adopt integration patterns?
- List the systems of record and the consumers for one business process.
- Pick the pattern from the table above and the slowest acceptable transfer type.
- Define owners, match keys and conflict rules before writing any pipeline.
- Build one pipeline with quality gates, lineage and monitoring, and prove it on real volumes.
- Reuse the pattern as a template for the next process, and review it each quarter.
To map one integration decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
FAQ
What is a data integration pattern?
A data integration pattern is a repeatable method for moving or combining data between systems. The five common ones are data migration, broadcast, bi-directional sync, correlation and aggregation.
What is the difference between broadcast and bi-directional sync?
Broadcast sends changes one way from a source to one or many destinations. Bi-directional sync lets two systems both change shared data, so it needs conflict rules.
When is batch integration better than real time?
Batch suits activities on a long cycle, such as monthly payroll or periodic analysis. Real time suits cases where speed is critical, such as card transactions. Choose the slowest option the decision can tolerate.
What is change data capture?
Change data capture reads changes from a database log and publishes them as events. Debezium, for example, describes itself as a platform that converts information from existing databases into event streams.
How do you avoid duplicate records when integrating data?
Define match keys, quarantine failed records, and design receivers to be idempotent so that a message delivered twice has the same effect as one delivered once.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE