Key takeaway
- Google BigQuery in 2027: how it works, on-demand vs edition pricing, BigQuery ML, Gemini, Iceberg managed tables, governance and when not to use it.
Google BigQuery is Google Cloud's serverless data warehouse and, in Google's own words, "a fully managed, AI-ready data platform that helps you manage and analyze your data". Storage and compute are separate layers that scale independently, so teams run SQL, Python and machine learning on large datasets without provisioning or manually scaling infrastructure.
In 2026 the choice is less about whether BigQuery can scale and more about how you pay for it (on-demand or one of three editions), how much AI you run inside it (BigQuery ML and Gemini in BigQuery), and whether your tables stay open (Apache Iceberg managed tables and the Lakehouse runtime catalog). This guide covers each decision for data and platform leaders.
What is Google BigQuery?
BigQuery is an analytical database, not a transactional one. Google describes a storage layer that ingests, stores and optimises data in a columnar format designed for analytical queries, with ACID transaction semantics and replication across multiple locations, and a compute layer for analytics. The two are connected by Google's petabit-scale network, and Google states that "BigQuery's separation of compute and storage layers lets each layer dynamically allocate resources without impacting the performance or availability of the other" (Google Cloud, BigQuery overview).
That makes BigQuery a fit for reporting, large scans and joins, and ML over historical data, and a poor fit for high-rate single-row updates of the kind an application database handles. If you are still choosing between database families, our guides to types of databases and SQL vs NoSQL vs NewSQL explain where an analytical warehouse sits.
What does BigQuery include going into 2027?
| Capability | What it does | When it fits |
| BigQuery Studio | SQL editor with code completion, validation and bytes-processed estimates, plus Python notebooks built on Colab Enterprise and version control for notebooks and saved queries | Analysts and data scientists working in one workspace |
| BigQuery ML | Create and run ML models with GoogleSQL; models are stored in datasets like tables and views | Forecasting, classification and clustering where the data already lives in BigQuery |
| Gemini in BigQuery | AI help for SQL and Python, data insights, data canvas, data preparation, conversational analytics and a Data Engineering Agent | Speeding up analysis and pipeline work, with review |
| Continuous queries | SQL statements that run continuously to analyse incoming data in real time | Event-driven logic; needs an Enterprise or Enterprise Plus reservation |
| Open table formats and external data | Apache Iceberg managed tables, plus support for Iceberg, Delta and Apache Hudi, and federated queries over Cloud Storage, Bigtable, Spanner and Google Sheets | Lakehouse designs and data that must stay outside BigQuery storage |
| BI integration | BI Engine, Looker, Connected Sheets and third-party tools such as Tableau and Power BI | Dashboards and self-service reporting |
How does BigQuery pricing work?
BigQuery charges separately for compute and storage. For compute you choose between on-demand pricing per data scanned and capacity pricing per slot-hour through an edition. The figures below are the US prices listed on Google's BigQuery pricing page when checked on 11 November 2026; prices vary by region and change over time.
| Item | Listed price (US) | Notes |
| On-demand queries | $6.25 per TiB scanned | First 1 TiB of query data processed per month is free |
| Standard edition | $0.04 per slot-hour, pay as you go | Autoscaling only |
| Enterprise edition | $0.06 per slot-hour pay as you go; $0.054 with a 1-year and $0.048 with a 3-year commitment | Commitments start at 50 slots, in steps of 50 |
| Enterprise Plus edition | $0.10 per slot-hour pay as you go; $0.09 with a 1-year and $0.08 with a 3-year commitment | Commitments are regional and renew automatically unless cancelled |
| Active logical storage | $0.000031507 per GiB-hour (Google's example: about $23.55 for 1 TiB for a full month) | First 10 GiB per month free |
| Long-term logical storage | $0.000021918 per GiB-hour | Applies to tables or partitions not modified for 90 consecutive days |
Capacity billing is per second with a one-minute minimum by default. On-demand suits spiky or exploratory use where you can control bytes scanned; editions suit steady workloads where predictable slot spend matters more than per-query cost.
Which BigQuery edition should you choose?
Google offers three editions for reservations and capacity commitments, alongside on-demand (Google Cloud, editions introduction).
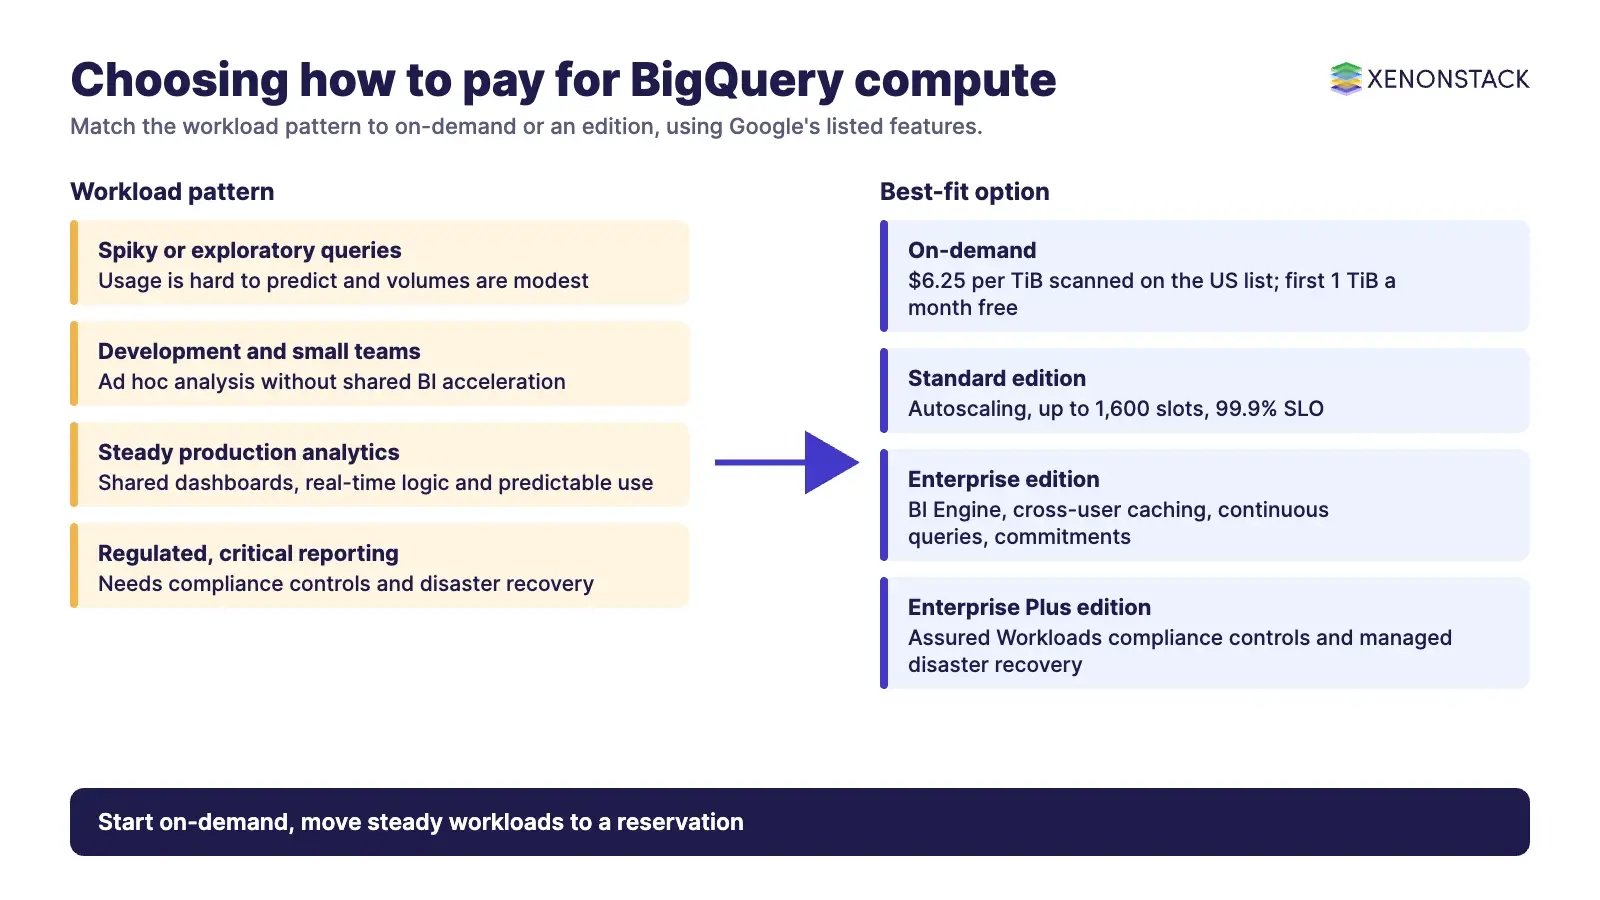
| Option | What you get | When it fits |
| Standard | Autoscaling, a 1,600-slot maximum reservation size, project-level assignments only, 99.9% monthly SLO, single-user cached results, no BI Engine acceleration | Development, small teams and ad hoc analysis |
| Enterprise | Autoscaling plus baseline slots, BI Engine acceleration, advanced workload management, cross-user caching, continuous queries, 99.99% SLO, optional commitments | Most production analytics and shared BI |
| Enterprise Plus | Everything in Enterprise plus compliance controls through Assured Workloads and managed disaster recovery | Regulated workloads and critical reporting that needs cross-region recovery |
| On-demand | Pay per TiB scanned with a free tier; no reservations or commitments; 99.99% SLO | Unpredictable or low-volume query patterns |
How do BigQuery ML and Gemini in BigQuery work?
BigQuery ML
BigQuery ML lets you create and run ML models with GoogleSQL, stored in BigQuery datasets. Built-in models include linear and logistic regression, k-means and ARIMA_PLUS. For forecasting without managing a model, Google documents the AI.FORECAST function with BigQuery ML's built-in TimesFM time series model. You can import models trained elsewhere in ONNX, TensorFlow, TensorFlow Lite and XGBoost formats, and create remote models that use models deployed to Agent Platform, part of Gemini Enterprise Agent Platform (Google Cloud, BigQuery ML introduction).
Gemini in BigQuery
Gemini in BigQuery is part of the Gemini for Google Cloud product suite. Its documented features are data insights, conversational analytics, data canvas, SQL and Python code assistance (generate, complete and explain), AI-generated data preparation recommendations, a Data Engineering Agent for building and modifying pipelines, and SQL translation rules in preview (Google Cloud, Gemini in BigQuery overview). Google points to Gemini for Google Cloud pricing for costs, so check that page before enabling it widely.
Conversational analytics lets users create data agents with custom instructions and verified queries. The same pattern, plain-language questions answered from governed data, is what AgentAnalyst provides: it lets teams ask questions of enterprise data in plain language and get real-time insights.
Video: how natural language query turns a business question into an answer from enterprise data.
How does BigQuery work with Apache Iceberg and the lakehouse?
Apache Iceberg managed tables (the feature earlier documented as BigLake tables for Apache Iceberg in BigQuery; Google's old URL now redirects to the new page) store data in Cloud Storage buckets that you own. BigQuery supports GoogleSQL DML on them, high-throughput streaming through the Storage Write API, schema evolution, automatic storage optimisation, time travel, and row- and column-level security. Google warns that changing the data files outside BigQuery can cause query failures or data loss (Google Cloud, Apache Iceberg managed tables).
For catalogues, Google states that "BigLake metastore is now called the Lakehouse runtime catalog" and that BigLake is now called Lakehouse as of 20 April 2026, while APIs, client libraries, CLI commands and IAM names still reference BigLake. The catalogue implements the Apache Iceberg REST Catalog API and works with engines including Apache Spark, Apache Flink, Apache Hive and Trino. The classic BigLake metastore is described as a legacy feature that is no longer recommended (Google Cloud, Lakehouse runtime catalog).
What has changed since this guide was first written?
| Earlier name or approach | Current position (checked 11 November 2026) |
| Cloud Datalab for notebooks on BigQuery | Its documentation URL now redirects to Agent Platform Workbench, so plan on current notebook tools instead. BigQuery Studio now includes Python notebooks built on Colab Enterprise |
| Cloud Machine Learning Engine and Vertex AI links | Vertex AI documentation now redirects to Gemini Enterprise Agent Platform; BigQuery ML remote models use Agent Platform |
| BigLake and BigLake metastore | Renamed Lakehouse and Lakehouse runtime catalog (20 April 2026); API and IAM names unchanged |
| BigLake tables for Apache Iceberg in BigQuery | Apache Iceberg managed tables |
| Pay-per-use pricing, as this post first described it | On-demand plus Standard, Enterprise and Enterprise Plus editions |
| Querying through the web UI, as this post first described it | BigQuery Studio with SQL and Python, plus Gemini assistance and conversational analytics |
How should you govern, secure and control BigQuery cost?
Cost. On-demand spend follows bytes scanned, so partitioning, clustering and selecting only the columns you need matter. Use the SQL editor's bytes-processed estimate before running large queries. For steady workloads, compare an Enterprise reservation with baseline slots against your on-demand bill. Keep data that is rarely modified so it moves to long-term storage pricing after 90 days.
Security and compliance. Apply row- and column-level security to sensitive tables, including Iceberg managed tables. If you need compliance controls through Assured Workloads or managed disaster recovery, those sit in Enterprise Plus.
AI governance. Gemini and conversational analytics make it easy to generate queries and answers. Review generated SQL, use verified queries for data agents, and record which data and logic produced each answer that drives a decision. When AI agents start acting on BigQuery data, ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents.
How should an enterprise adopt BigQuery?
- Start on-demand. Load one domain, run real queries and measure bytes scanned per workload.
- Model the data. Partition and cluster large tables, and decide which data should stay in open Iceberg tables.
- Pick an edition. Move steady workloads to a reservation once usage is predictable; keep exploratory work on-demand if that is cheaper.
- Add ML and AI in steps. Begin with BigQuery ML for forecasting or classification, then enable Gemini features with review rules.
- Operationalise. Automate pipelines and deployment; our guide to DevOps on Google Cloud Platform covers the delivery side, and XenonStack Google Cloud managed services can run the platform for you.
What are the trade-offs, and when is BigQuery not the right choice?
- Transactional workloads. BigQuery is built for analytics. Use an operational database for high-rate single-row reads and writes.
- Unbounded on-demand spend. Poorly filtered queries scan large volumes and cost more; set quotas and review heavy users.
- Cloud concentration. Teams committed to another cloud or a multi-engine lakehouse should weigh open Iceberg tables and the Iceberg REST catalogue to keep data portable.
- Edition limits. Features such as BI Engine acceleration and continuous queries are not in Standard edition.
For a wider view of the tools that sit around a warehouse, see our big data tools and technologies guide.
To map one analytics decision your agents should make from BigQuery data, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
What should you plan for in 2027?
Treat 2027 as the year to turn the choices in this guide into settled policy instead of reopening them every quarter. Three planning points follow from what Google documents today.
- Fix your pricing model. Measure bytes scanned per workload, then decide which steady workloads move from on demand to a Standard, Enterprise or Enterprise Plus reservation.
- Keep tables open. Decide which data belongs in Apache Iceberg managed tables and use the Lakehouse runtime catalog, so engines other than BigQuery can still read it.
- Add AI with review rules. Start with BigQuery ML for forecasting, enable Gemini features in stages, and check generated SQL before it drives a decision.
Check Google's pricing page again before you commit to slot capacity, because listed prices vary by region and change over time.
Frequently asked questions about Google BigQuery
What is Google BigQuery used for?
It is a serverless data warehouse for analytics: running SQL and Python over large datasets, building ML models with BigQuery ML, and feeding BI tools, without managing infrastructure.
How much does BigQuery cost?
On Google's US price list, on-demand queries cost $6.25 per TiB scanned after the first free 1 TiB each month, and editions cost from $0.04 per slot-hour for Standard. Storage is billed separately, with the first 10 GiB per month free.
What are the BigQuery editions?
Standard, Enterprise and Enterprise Plus. Enterprise adds BI Engine, cross-user caching and continuous queries; Enterprise Plus adds compliance controls through Assured Workloads and managed disaster recovery.
Is Google Datalab still available?
Not as a separate product page. The Cloud Datalab documentation now redirects to Agent Platform Workbench, and BigQuery Studio includes Python notebooks built on Colab Enterprise.
Does BigQuery support Apache Iceberg?
Yes. Apache Iceberg managed tables store data in your own Cloud Storage buckets with DML, streaming and time travel, and the Lakehouse runtime catalog, formerly BigLake metastore, exposes an Iceberg REST catalogue to engines such as Spark, Flink and Trino.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE