Key takeaway
- Performance profiling finds the code that costs CPU, memory and wait time. Learn profile types, Go pprof commands, tools and safe production use.
Performance profiling measures where a running program spends its CPU time, memory and waiting time, so that you fix the code that actually causes a slowdown instead of guessing. A profile is a set of sampled call stacks. It tells you which functions are hot, which allocate most, and which block on locks. It does not tell you whether the system meets a target, which is the job of performance testing.
This guide uses Go's pprof tooling for the worked commands and compares it with other profilers. It is written for engineering leads and architects who need a repeatable way to find bottlenecks, decide how much profiling is safe in production, and prove that a fix worked. For the neighbouring practices, see performance monitoring, benchmarking and performance tuning.
What is the difference between profiling, monitoring, benchmarking and tuning?
They answer different questions and work best in sequence. Monitoring tells you that something is slow, a benchmark gives you a repeatable measurement, a profile shows why, and tuning is the change you make afterwards.
| Practice | Question it answers | Typical output | Where to read more |
|---|---|---|---|
| Monitoring | Is the system slow right now? | Metrics and alerts over time | Performance monitoring |
| Benchmarking | How fast is this code under a fixed test? | Repeatable timings and allocations | Benchmarking |
| Profiling | Which code causes the time or memory use? | Sampled call stacks, flat and cumulative cost | This post |
| Tuning | What change removes the cost? | A code or configuration change, then a re-measure | Performance tuning |
| Performance testing | Does the system meet its target under load? | Pass or fail against a service level | Performance testing |
What kinds of profile can you collect?
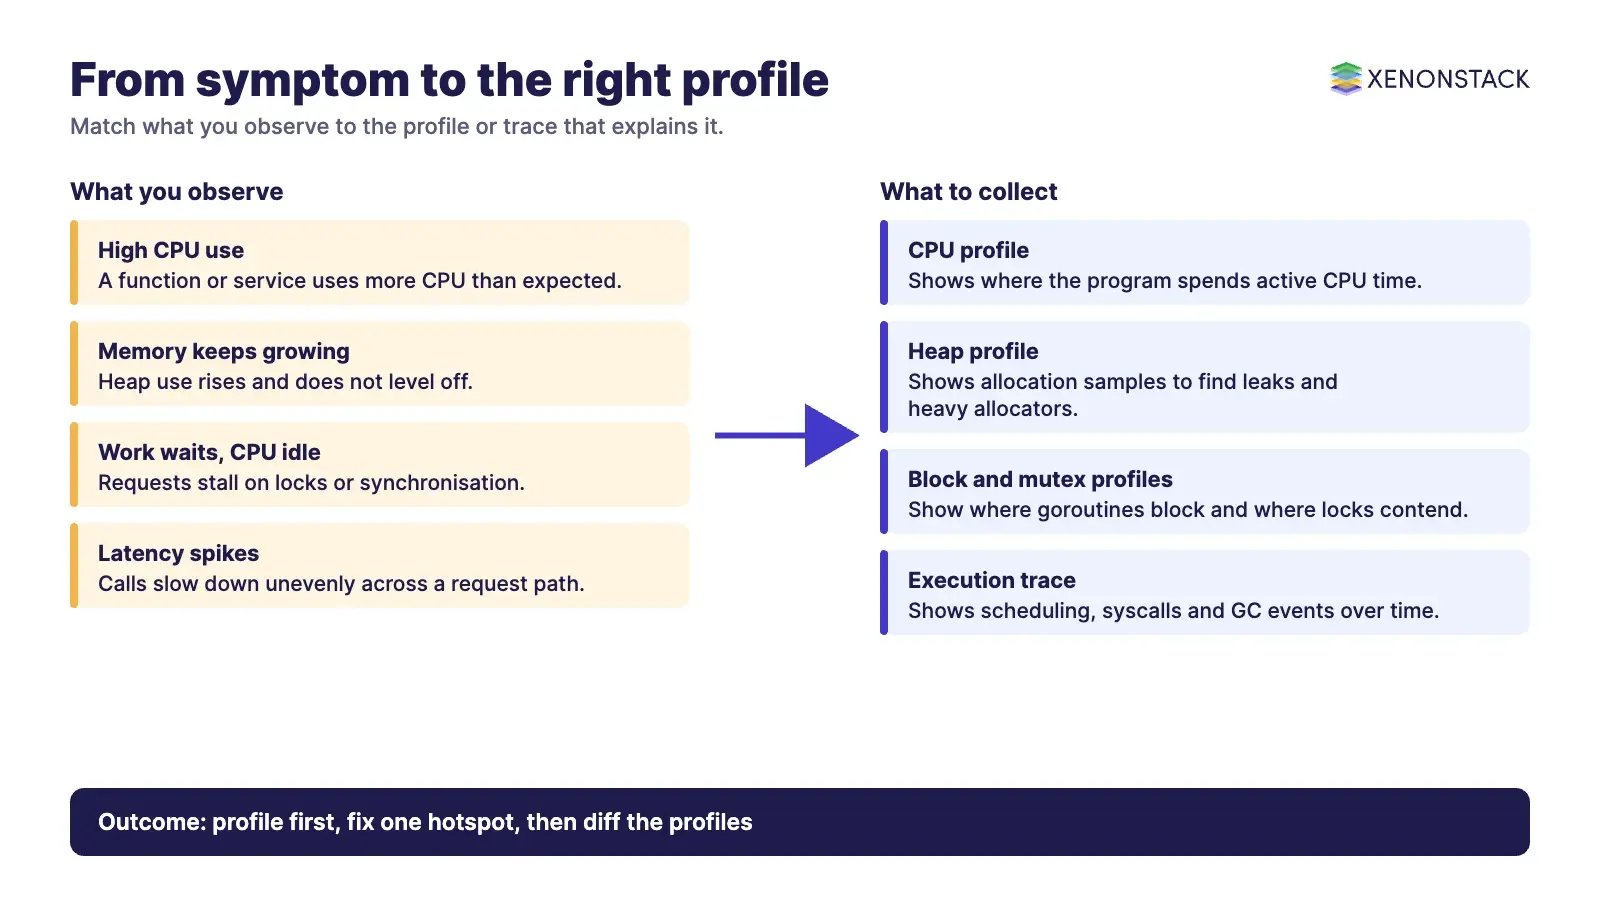
According to the Go diagnostics documentation (go.dev/doc/diagnostics), the runtime provides several predefined profiles. Other languages and tools have equivalents under different names.
| Profile | What it shows | Use it when |
|---|---|---|
| CPU | Where the program spends time actively using the CPU, not sleeping or waiting for I/O | CPU use is high or a function is slow |
| Heap | Memory allocation samples, for current and historical memory use | Memory grows or you suspect a leak |
| Goroutine | Stack traces of all current goroutines | Goroutine counts keep rising |
| Block | Where goroutines block on synchronisation primitives (enable with runtime.SetBlockProfileRate) | Work is waiting but the CPU is idle |
| Mutex | Lock contention (enable with runtime.SetMutexProfileFraction) | CPU is underused because of lock contention |
| Threadcreate | Parts of the program that create new OS threads | Thread counts are unexpectedly high |
The same page adds that the execution tracer, viewed with go tool trace, is better for latency and parallelism problems, while profiling tools are better for hot spots.
How does performance profiling work in Go?
Go ships the profiler with the toolchain. You collect a profile file, then read it with go tool pprof. The Go blog post on profiling (go.dev/blog/pprof) describes three ways to switch it on: flags in a standalone program, the standard flags of go test, and the net/http/pprof package for servers.
Profile a benchmark with go test
Write a benchmark function in a file ending in _test.go, then run it with the profile flags. The -run=^$ pattern skips ordinary tests so that only the benchmark is measured.
go test -run=^$ -bench=. -benchmem -cpuprofile=cpu.out -memprofile=mem.outThis writes the CPU profile to cpu.out and the memory profile to mem.out. Open either with go tool pprof:
go tool pprof cpu.out
go tool pprof mem.out
Profile a running service
According to the net/http/pprof documentation (pkg.go.dev/net/http/pprof), importing the package for its side effect registers handlers under /debug/pprof/, and the seconds parameter sets how long a CPU profile runs. The example below collects a 30-second CPU profile from a service listening on localhost:6060.
import _ "net/http/pprof"

go tool pprof "http://localhost:6060/debug/pprof/profile?seconds=30"
Explore the result
Inside the pprof prompt, the commands described in the Go blog post are the ones you will use most:
- top N lists the N most expensive functions, and top N -cum sorts them by cumulative cost.
- list FUNC shows the source lines of a function annotated with their cost.
- web writes an SVG call graph and opens it.
- --inuse_objects on a memory profile reports object counts instead of sizes.
The pprof project documentation (github.com/google/pprof) adds a browser interface. Running pprof with the -http flag starts a local web server with graph, flame graph, top, source and peek views.
How do you read flat and cumulative columns?
Per the Go blog post, the first two columns of top output (flat and flat%) show the number of samples in which the function itself was running, as a count and a percentage. The third column (sum%) is the running total of the listing. The last two columns (cum and cum%) count samples in which the function appeared on the stack, either running or waiting for a function it called to return.
| Column | Meaning | What a large value tells you |
|---|---|---|
| flat, flat% | Samples where this function was the one running | The function's own code is the cost |
| sum% | Running total down the listing | How few functions account for most of the samples |
| cum, cum% | Samples where the function was on the stack at all | The function, or something it calls, is the cost |
A function with high cum but low flat is usually a caller. Follow it down to the callee with high flat. A function with high flat is where to read the source first.
How do you prove a fix worked?
Profile, change one thing, then profile again under the same conditions. The Go blog post follows this loop through a worked example. The pprof documentation describes the -diff_base option for comparing two profiles, where percentages are relative to the total of the base profile and some entries may be negative. Collect both profiles with the same duration and workload, otherwise the comparison misleads.
The Go diagnostics page also warns that some diagnostic tools interfere with each other. Its example is that precise memory profiling skews CPU profiles. Collect one profile type at a time.
Which performance profiling tools should you consider?
The right tool depends on the language and on whether you need CPU, memory or lock data. The descriptions below come from each project's own pages.
| Tool | What it does (per its own page) | Fits | Status or caution |
|---|---|---|---|
| Go pprof | Reads CPU, heap, block, mutex and other profiles from Go programs (Go diagnostics) | Go services and benchmarks | Part of the Go toolchain |
| Valgrind (Callgrind, Cachegrind, Massif, DHAT) | Callgrind adds call-graph information to cache simulation, Massif samples heap use over time, DHAT analyses heap allocations (valgrind.org) | C and C++ programs | Its page gives roughly 20 to 100 times slowdown for Cachegrind and about 20 times for Massif, so use it in test, not production |
| OProfile | A statistical profiler for Linux that profiles running code at low overhead (oprofile.sourceforge.io) | System-wide Linux profiling | Its page says the legacy profiler was removed in version 1.0.0 in favour of the Linux Kernel Performance Events Subsystem |
| gprof | The GNU profiler, which reports a flat profile and a call graph (GNU binutils manual) | C and C++ programs built with GNU tools | Confirm usage steps in the manual for your binutils version |
| Linux perf | The Go diagnostics page notes that perf can profile Go programs, including cgo and kernel code | Mixed native and Go workloads | Needs Linux kernel support |
Is it safe to profile in production?
Mostly yes, with limits. The Go diagnostics page states that it is safe to profile programs in production, but that enabling some profiles, such as the CPU profile, adds cost, so you should expect a performance downgrade and measure the profiler's overhead before enabling it. It suggests profiling a randomly selected replica periodically, and collecting one profile at a time.
There is also a governance point. The pprof endpoints expose internals of the running program. The net/http/pprof page does not discuss access control, so we recommend binding them to localhost or an internal network, restricting who can call them, and reviewing profile files before sharing them, since stack traces can include function and package names. Treat that as a house rule to confirm with your security team, not as a vendor claim.
Can profiles also improve the build itself?
Yes. According to the Go profile-guided optimisation guide (go.dev/doc/pgo), the compiler can use a CPU pprof profile from representative runs to make better optimisation decisions, such as inlining frequently called functions. PGO is supported starting in Go 1.20, a profile named default.pgo in the main package directory is picked up automatically by go build from Go 1.21 (the default is -pgo=auto), and the guide reports around 2 to 14 per cent improvement on a representative set of programs as of Go 1.22. It stresses that the profile must be representative of production, and that microbenchmarks are usually poor candidates. Confirm the current figure and behaviour on the guide before you rely on it.
How should an enterprise adopt performance profiling?
- Start from a symptom. Use monitoring and load tests to name the slow endpoint or job before profiling.
- Make a benchmark. A repeatable benchmark gives you a before and after.
- Profile in test first. Collect CPU and heap profiles on a representative build.
- Add production profiling carefully. Sample one replica, one profile type at a time, with internal-only access.
- Fix one hotspot, then re-profile. Record the diff and keep the profile files with the change.
- Keep the evidence. Store profiles and benchmark results next to the pull request so reviewers can see the effect.
Teams that run AI agents on top of these services should profile the services the agents call, because slow tools and retrieval steps show up as slow agent runs. ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control, and AgentQA provides quality assurance for agent workflows and regressions, according to its own page.
When is profiling not the right tool?
| Situation | Why profiling is not enough | Better first step |
|---|---|---|
| You do not yet know which request is slow | A profile of the whole process is noisy | Monitoring and tracing |
| The system must meet a target under load | A profile shows cost, not whether the target is met | Performance testing |
| Code is fast but the wait is on a database or network call | CPU profiles hide time spent waiting | Block profiles and the execution tracer, or tracing |
| Benchmarks run a tiny part of the application | Results may not match production behaviour | Profile a representative workload |
To map one performance decision your teams and agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
FAQ
What is performance profiling?
Performance profiling measures where a running program spends CPU time, memory and waiting time, using sampled call stacks, so you can find the functions that cause a slowdown.
What do flat and cum mean in pprof?
Per the Go blog, flat counts samples in which the function itself was running. Cum counts samples in which the function was on the stack, either running or waiting for a called function to return.
Is it safe to profile in production?
According to the Go diagnostics page, it is safe to profile programs in production, but some profiles, such as the CPU profile, add cost. Measure the overhead first and profile one replica at a time.
How is profiling different from benchmarking?
A benchmark gives a repeatable measurement of how fast code runs. A profile shows where inside that code the time or memory goes. Use a benchmark to prove a fix and a profile to find it.
Which profiling tool should I use?
Use pprof for Go, Valgrind tools such as Callgrind or Massif for C and C++ in test, and system-wide tools such as perf on Linux. Check each tool's own documentation for current status.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE