Key takeaway
- Network Reliability Engineering (NRE) applies SRE practice to networks: code, automation, testing and SLOs. Answers, a fit table and an adoption sequence.
What is Network Reliability Engineering (NRE)?
Network Reliability Engineering (NRE) applies site reliability engineering (SRE) practice to the network: engineers treat the network as software, define it as code, automate changes, test them continuously and measure reliability against explicit targets. In this post NRE means Network Reliability Engineering, the discipline for running networks reliably at speed, and nothing else.
For enterprise leaders the question is not the job title. It is whether network change can move as fast as the applications and site reliability engineering teams that depend on it, without raising the risk of an outage. NRE is the operating model that answers that, and DevNetOps is the delivery pipeline it runs on.
Where does NRE come from?
NRE borrows its logic from SRE. The Google SRE book summarises SRE as "what happens when you ask a software engineer to design an operations team", and states that Google caps operational work for SREs at 50% of their time so that engineering effort stays on automation. NRE asks the same of network teams: replace repeated manual change with code, and spend the saved time on design and reliability. The SRE and DevOps split is covered in SRE vs DevOps.
The history of the NRE title is less important than the pattern. Sysadmins became site reliability engineers; network administrators and operators are following the same path as networks become programmable and are consumed through APIs by cloud and platform teams.
What principles does an NRE team work to?
NRE principles are derived from DevOps and carry over directly from SRE practice:
- Enable automation. Provisioning and change happen through pipelines and APIs, not manual sessions on devices.
- Keep workflows transparent. Every change is visible in version control and reviewable before it runs.
- Measure with metrics. Monitoring and alerts give the evidence for decisions and for improvement.
- Design for failure. Assume links, devices and changes will fail and build recovery in advance.
- Evolve continuously. Review incidents and feed the lessons back into design and tests.
NRE culture puts reliability first while still delivering security, agility and performance. The aim is not to avoid change but to change safely and quickly.
How does an NRE team work day to day?
The working loop has six steps, each of which replaces a manual habit:
| Step | What the team does | What it replaces |
|---|---|---|
| Code | Codify network infrastructure and keep all of it in a version control repository | Configuration held on devices or in personal files |
| Automate | Use DevNetOps concepts to provision and change the network dynamically | Manual, device-by-device change |
| Test | Run continuous automatic tests against the service level agreements | Checks after a change has gone live |
| Monitor | Watch alerts and unusual events; monitoring is the source of insight | Reacting after users report faults |
| Measure | Rate the design and measure performance for transparency and improvement | Opinions about how the network is doing |
| Respond | Respond continuously so the network recovers quickly; network configuration lives in a repository and is deployed through programmatic APIs | Ad hoc fixes with no record |
How should reliability targets be set?
NRE inherits the SRE habit of explicit targets. According to the Google SRE book, Embracing Risk, a service level objective (SLO) sets the expected uptime for a period, and the error budget is the unreliability that remains allowed. The same chapter says 100% is probably never the right reliability target, and that past a certain point extra reliability costs far more than users can notice. For a network team this turns arguments about "stable versus fast" into a budget: while the budget remains, changes ship; when it is spent, effort goes to reliability work.
What does NRE change for the network and its consumers?
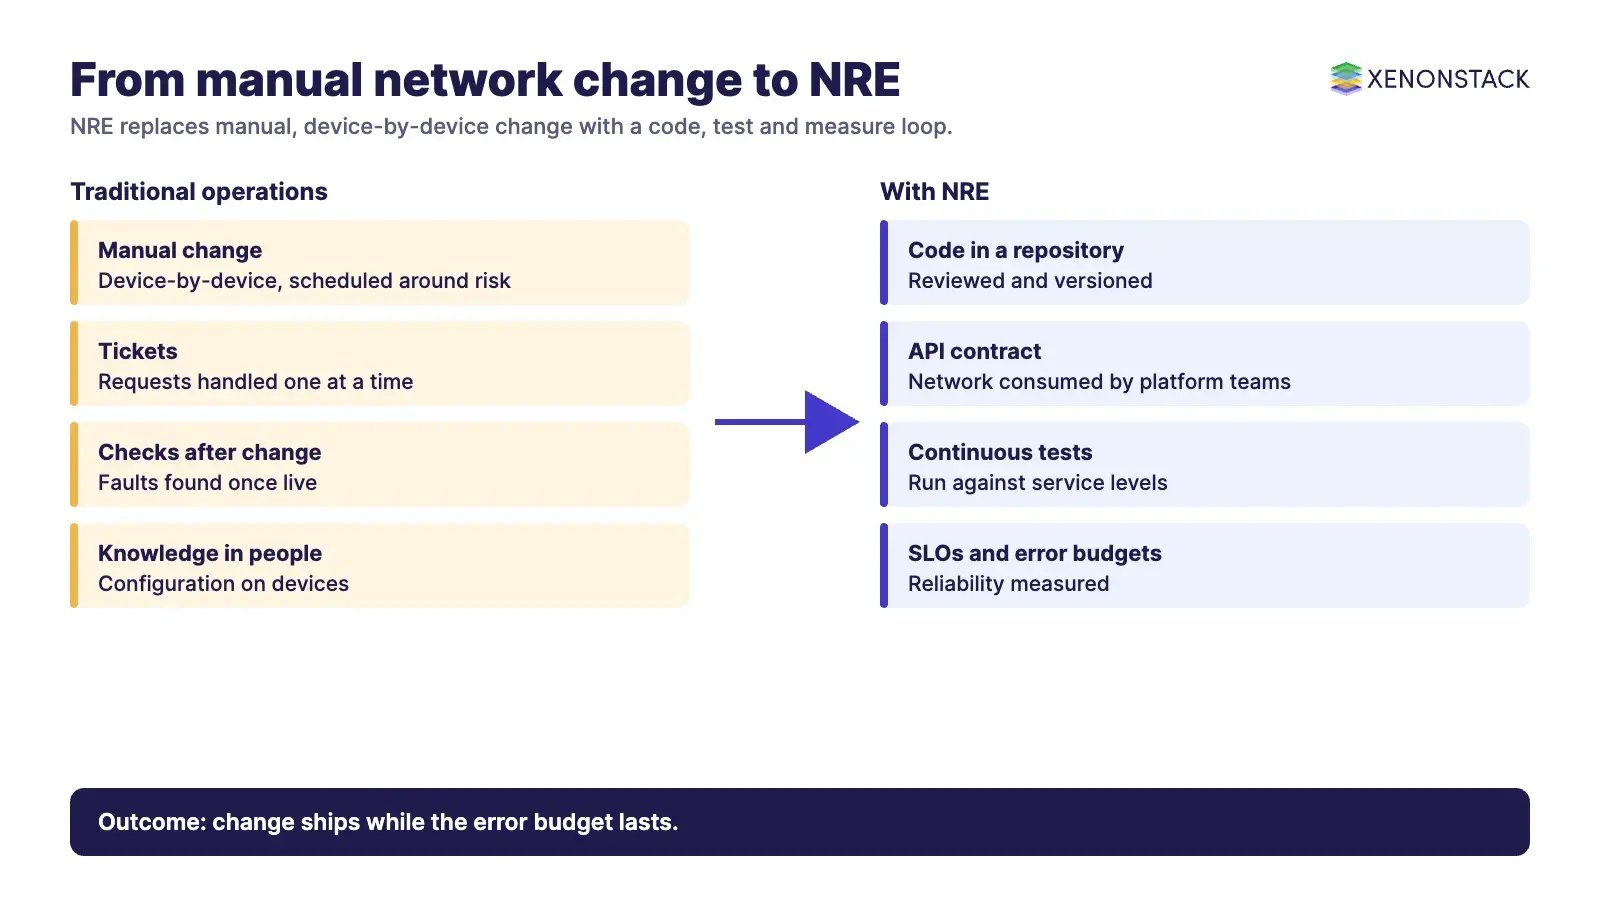
| Area | Traditional network operations | With NRE |
|---|---|---|
| Change | Manual, scheduled around risk | Code reviewed, tested and deployed through APIs |
| Interface to consumers | Tickets and requests | An API contract for the network, consumed by IaaS and cluster SRE teams |
| Reliability | Judged by absence of change | Measured against SLOs and error budgets |
| Knowledge | In individuals and device configurations | In repositories, tests and runbooks |
| Failure | Handled when it happens | Designed for in advance |
How do AI agents fit into NRE?
Intent-based networking is the standards-side view of the same direction. RFC 9315 (October 2022, Informational, from the IRTF Network Management Research Group) defines intent as high-level, declarative network goals that leave implementation details to the system. NRE supplies the discipline around that idea: code, tests, metrics and review. Agents add a further layer, in which software diagnoses faults and carries out pre-approved fixes. The practical pattern is described in Agentic AI for Network Operations.
The governance question for a network is the same as for any change: who approved it, under what policy, and can it be reviewed afterwards. ElixirClaw, according to its site, runs agents under configurable autonomy levels and policy limits, with human approval for higher-impact actions and every decision and action logged. The Decision Review Agent, according to its site, analyses decision lineage and patterns after the fact and recommends policy or process improvements; humans define what counts as correct. For a network this means agent actions can be reviewed against the same SLOs the NRE team already owns.
When does NRE fit, and when does it not?
| Situation | Fit | Comment |
|---|---|---|
| Large, frequently changing network with cloud or platform consumers | Strong | Change volume justifies code, tests and pipelines |
| Small, stable network with rare change | Partial | Adopt version control and monitoring first; full pipelines may cost more than they save |
| Heavy dependence on devices with no API | Limited | Automation depends on programmatic interfaces; plan hardware refresh or an abstraction layer |
| No agreed service levels | Not yet | Agree SLOs first; without them there is nothing to test or budget against |
What is a sensible adoption sequence?
- Put network configuration in version control and agree who may change it.
- Define two or three SLOs for the services the network supports.
- Add monitoring that reports against those SLOs.
- Automate the most repeated, lowest-risk change first, with automatic tests.
- Review incidents, update tests and runbooks, then widen automation.
- Introduce agent assistance only for pre-approved actions with audit trails and a way to roll back.
Related reading: Overview of Challenges and Solutions for SRE Team and the DevNetOps guide.
To map one network change decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What does NRE stand for?
In this post NRE stands for Network Reliability Engineering: applying SRE practice, such as code, automation, testing, metrics and error budgets, to network operations.
How is NRE different from SRE?
SRE, as described in the Google SRE book, asks software engineers to design operations. NRE applies the same approach to the network, so the network is defined as code, changed through APIs and measured against service level objectives.
What is DevNetOps and how does it relate to NRE?
DevNetOps applies DevOps principles to network operations through a pipeline of integration, testing, delivery and monitoring. NRE is the role and operating model that runs on it.
Should a network aim for 100% reliability?
No. The Google SRE book says 100% is probably never the right target, because past a certain point extra reliability costs far more than users can notice. Set an SLO and use the error budget to balance change and stability.
Where do AI agents fit in network reliability engineering?
They can diagnose faults and carry out pre-approved fixes, but they should work inside policy limits, with human approval for higher-impact actions and a full audit trail. Intent-based networking, defined in RFC 9315, describes the goal-driven direction.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE