Key takeaway
- Run Spark, Flink, Kafka and HDFS on Kubernetes: which workloads fit, StatefulSets, security, cost trade-offs and an adoption sequence for enterprise teams.
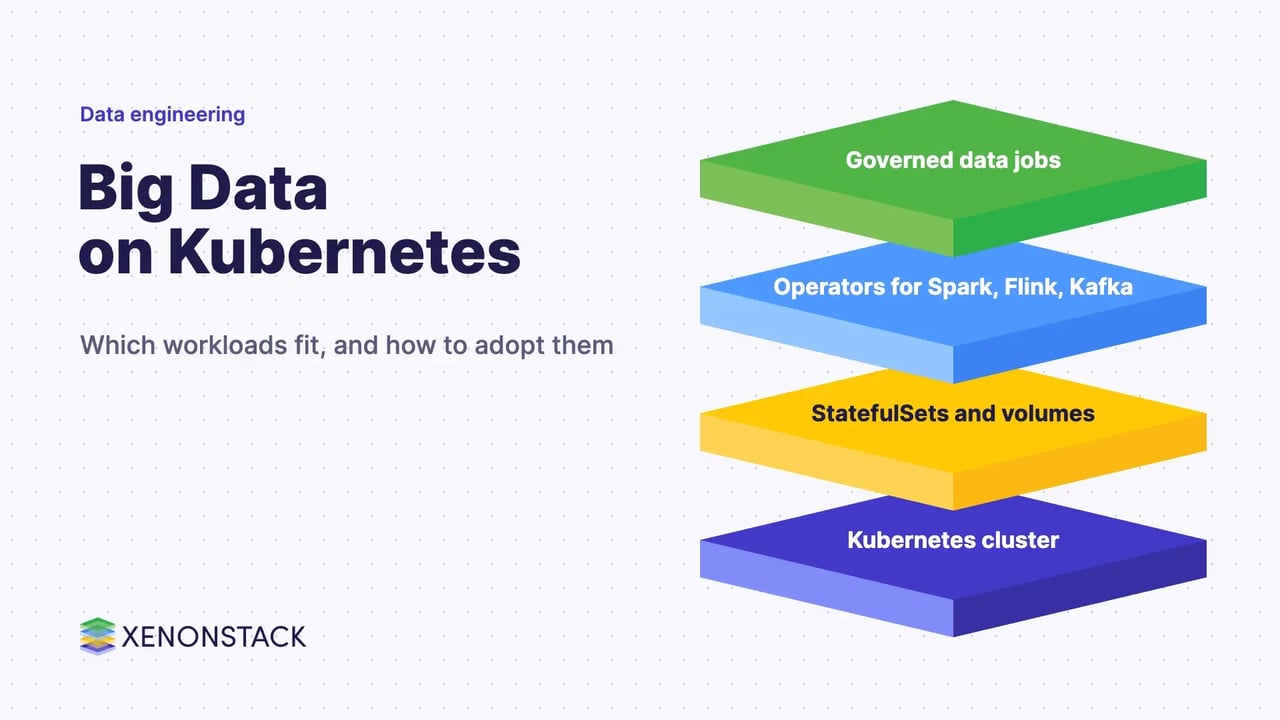
Big data on Kubernetes means running the engines of a data platform (Apache Spark, Apache Flink, Apache Kafka and, where you still need it, Apache Hadoop HDFS) as containers scheduled by Kubernetes, instead of on a fixed cluster. Spark and Flink now have first-class Kubernetes support, so batch and streaming compute fit naturally. Stateful storage and brokers need more care, because they depend on stable identity and durable volumes.
For enterprise architects the real question is which workloads belong on Kubernetes and which should stay on managed or object storage. This guide gives a decision table, the Kubernetes building blocks involved, security and cost controls, and an adoption sequence. It builds on our overview of the big data platform and on Kubernetes architecture components.
Which big data workloads fit on Kubernetes?
The table below separates workloads by how much state they hold. The status column reflects each project's own documentation, read in November 2026; confirm versions on the official pages before you plan.
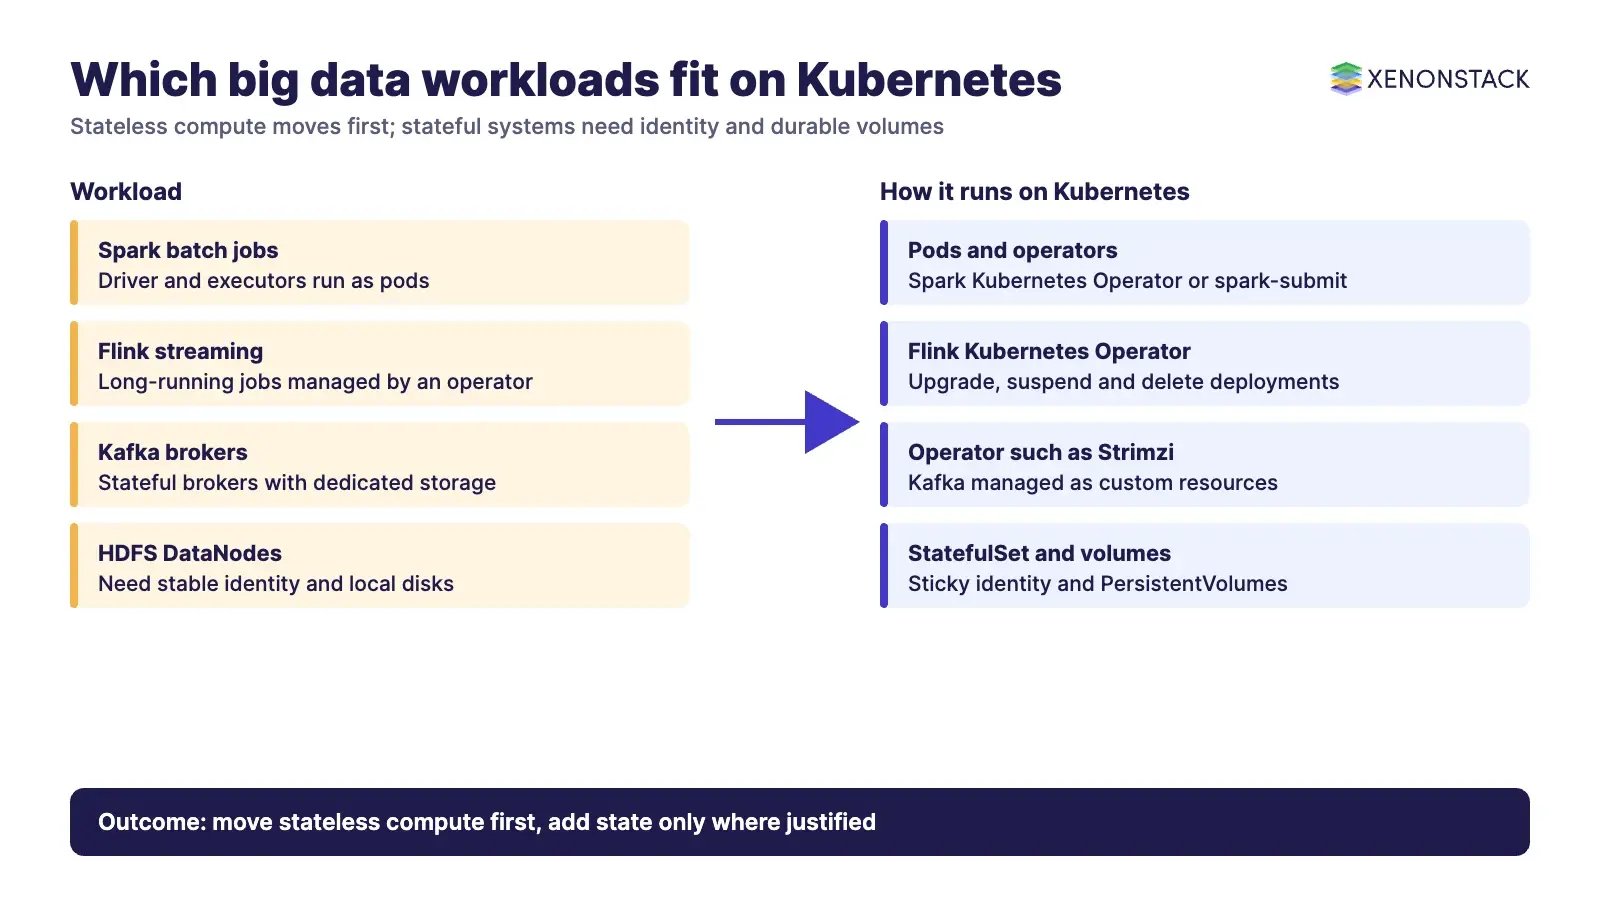
| Workload | Fit on Kubernetes | Current status, per the project's own site |
|---|---|---|
| Apache Spark batch jobs | Strong. Short-lived pods suit elastic batch compute. | Spark 4.3.0 docs describe a driver pod that creates executor pods and require a Kubernetes cluster at version 1.34 or later. |
| Apache Flink streaming | Strong with an operator, because long-running jobs need upgrade and savepoint handling. | The Flink Kubernetes Operator manages Application and Session deployments, including upgrade, suspend and delete. |
| Apache Kafka | Good with an operator and dedicated storage and nodes. | Strimzi describes itself as a way to run a Kafka cluster on Kubernetes and is a CNCF incubating project. |
| HDFS (NameNodes and DataNodes) | Possible, but demanding. It needs stable identity and local disks. | Hadoop 3.5.0 was listed as the latest release on hadoop.apache.org, dated 2 April 2026. |
| Object storage and lakehouse tables | Usually kept outside the cluster as a managed service. | Depends on your cloud or storage vendor; check its own documentation. |
Our architectural judgement is to move stateless compute first (Spark and Flink), keep durable data in object storage or a managed service where you can, and move brokers and HDFS only when you have a clear reason such as data residency or an on-premises estate.
How does Spark run on Kubernetes?
According to the Apache Spark documentation, Spark creates a driver that runs inside a Kubernetes pod. The driver then creates executors, which also run in pods, connects to them and runs the application code. When the application completes, the executor pods terminate and are cleaned up, while the driver pod remains in a completed state so you can read its logs.
What do you need in place first?
- A Kubernetes cluster at the version the Spark docs require (version 1.34 or later for Spark 4.3.0), with kubectl access and Kubernetes DNS configured.
- A service account that lets the driver create pods, services and config maps.
- A container image that holds Spark and your application, referenced through
spark.kubernetes.container.image.
Should you use spark-submit or the Spark Kubernetes Operator?
The Spark docs describe a separate Apache project, the Apache Spark Kubernetes Operator, with SparkApp and SparkCluster resources. The docs call the two approaches complementary, because the operator runs Spark applications on the same native Kubernetes scheduler backend. Use spark-submit for simple pipelines and the operator when platform teams want applications declared as Kubernetes resources and managed through GitOps.
How do you handle shuffle data and scheduling?
Per the Spark docs, an external shuffle service is listed under future work, while shuffle data recovery is available through a Kubernetes local-disk plugin that needs PVC-backed local directories. Pod templates let you set node selectors and other pod settings for drivers and executors, and Spark documents Volcano and Apache YuniKorn as custom schedulers. Check the current page for setup details before relying on either.
How do stateful systems like HDFS and Kafka work on Kubernetes?
Kubernetes describes a StatefulSet as running a group of pods and keeping a sticky identity for each of them, which suits applications that need persistent storage or a stable, unique network identity. This is the building block behind most database, broker and HDFS deployments.
Storage is a separate object. Kubernetes defines a PersistentVolume as a piece of storage that an administrator or a storage class has provisioned, with a lifecycle independent of any pod that uses it. In practice, the pattern for HDFS is as follows (a design approach, not a Hadoop-documented procedure):
- Expose the NameNode through a Service so clients and DataNodes find a stable address, and label the pods so the Service selects them.
- Run DataNodes as a StatefulSet, so each pod keeps its name, hostname and volume when it is rescheduled.
- Give DataNodes dedicated disks through persistent volumes and test node failure before you trust the setup.
For Kafka, an operator removes most of this manual work. Strimzi, for example, says it supports rack awareness for high availability, scheduling Kafka onto dedicated nodes, several options for external access, and TLS, and that topics, users, MirrorMaker and Kafka Connect can be managed as custom resources. Our guide on Kafka security with Kerberos on Kubernetes covers the authentication side, and real-time streaming with Spark and Kafka covers the pipeline design.
Why is HDFS still part of the conversation?
The Apache Hadoop erasure coding documentation states that the default 3x replication scheme in HDFS has 200% storage overhead, while typical erasure coding setups have no more than 50% overhead. The default system policy is named RS-6-3-1024k. For a large on-premises estate, that difference changes cost, which is one reason teams keep HDFS even as compute moves to Kubernetes. For Hadoop access control, see our guide on Apache Hadoop security.
What are the best practices for big data on Kubernetes?
- Keep images small and single purpose. Use a trusted base image, run one main process per container, and rebuild images when the base is patched.
- Use namespaces and labels. Separate teams, environments and workloads, and attach resource quotas to each namespace.
- Run as a non-root user. The Spark docs note that project images run as UID 185 and that security-conscious deployments should provide custom images with a USER directive or set the user in a pod template.
- Apply least-privilege RBAC. The Spark docs say the driver service account needs, at minimum, a Role or ClusterRole that lets it create pods and services.
- Restrict pod specifications. The Spark docs advise cluster administrators to use the Pod Security Admission controller and to be careful with hostPath volumes.
- Treat defaults as unsafe. Per the Spark docs, security features such as authentication are not enabled by default.
- Automate deployment. Build, scan and deploy through a pipeline; see Kubernetes deployment tools and best practices.
How do you adopt big data on Kubernetes step by step?
| Stage | What you do | Exit check |
|---|---|---|
| 1. Containerise | Build and scan images for one Spark job; use Kubernetes terms such as cluster, node, namespace, deployment, pod and service consistently. | The job runs end to end on a test cluster. |
| 2. Isolate | Create namespaces, quotas, service accounts and pod security rules. | A job cannot read another team's data or exceed its quota. |
| 3. Operate | Adopt operators for Spark, Flink or Kafka and deploy through a pipeline. | Upgrades and rollbacks work without manual edits. |
| 4. Add state | Move brokers or HDFS with StatefulSets and persistent volumes only where justified. | Node-failure tests pass and restore times are known. |
| 5. Govern | Record who may run which jobs on which data, and keep an audit trail. | Every pipeline run is traceable to an owner and a policy. |
When should you not run big data on Kubernetes?
- You have a small, steady workload that a managed service already handles well.
- Your team has no Kubernetes operations skills and no platform team to support them.
- The workload needs tightly tuned local disks and network, and you cannot test failure modes.
- Your data platform rules require capabilities that the Kubernetes distribution you use does not support. Check the vendor's own documentation.
What does governance look like once data jobs run on Kubernetes?
Running pipelines as pods makes them easy to launch, so governance has to travel with them. Teams need to know which job read which dataset, under which policy, and who approved it. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents, and AgentAnalyst lets teams ask questions of enterprise data in plain language and get real-time insights.
To map one data platform decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Related reading: Kotlin application deployment with Docker and Kubernetes, big data consulting services, Kubernetes consulting services and big data analytics on Kubernetes.
Frequently asked questions
Can Apache Spark run on Kubernetes?
Yes. According to the Spark documentation, Spark creates a driver in a pod, and the driver creates executors that also run in pods. Check the docs for the Kubernetes version your Spark release requires.
Why use a StatefulSet for HDFS or Kafka?
Kubernetes says a StatefulSet maintains a sticky identity for each pod, which suits applications that need persistent storage or a stable, unique network identity.
Is there a Kubernetes operator for Spark, Flink and Kafka?
Yes, each has one. Apache publishes a Spark Kubernetes Operator and a Flink Kubernetes Operator, and Strimzi, a CNCF incubating project, runs Kafka on Kubernetes. Confirm current versions on each project's site.
How much storage does HDFS erasure coding save?
The Hadoop documentation says default 3x replication has 200% storage overhead and typical erasure coding has no more than 50% overhead.
Is Spark on Kubernetes secure by default?
No. The Spark documentation says features such as authentication are not enabled by default, and recommends RBAC, custom images that do not run as root and the Pod Security Admission controller.
Ready to put AI agents to work? See an ElixirClaw demo: the agentic OS to build, orchestrate and govern AI agents across your enterprise systems.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE