Key takeaway
- SRE vs DevOps explained: how the roles differ, what SLOs and error budgets do, and when enterprises should use each, with sourced Google SRE guidance.
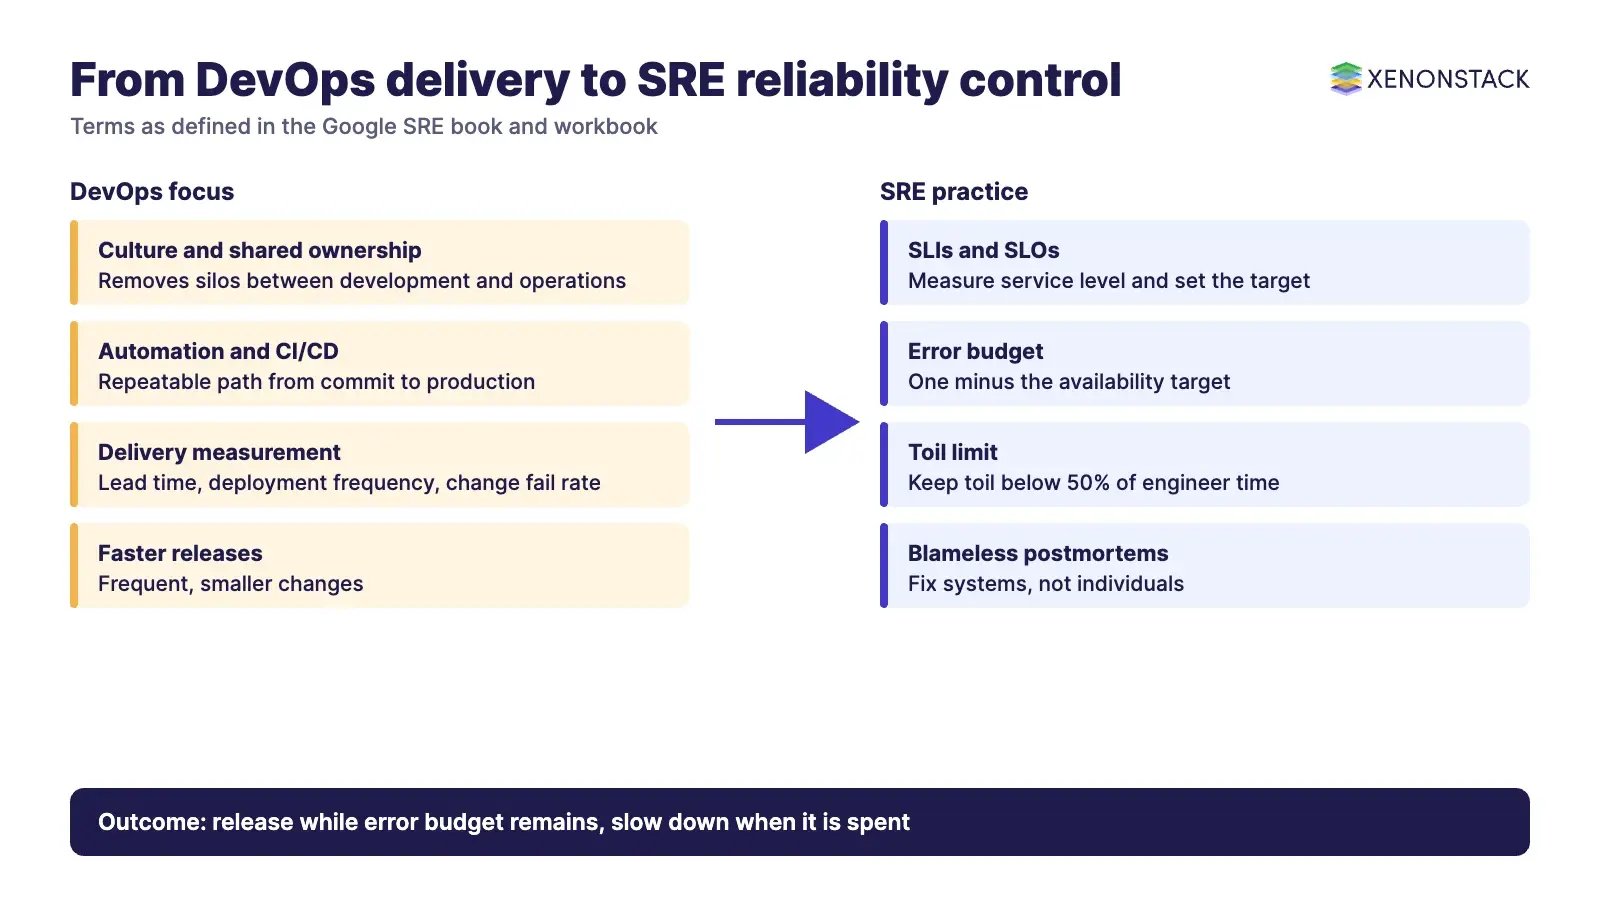
DevOps is a philosophy for how development and operations teams work together to ship software. Site reliability engineering (SRE) is a concrete way of running production, in which software engineers own reliability and measure it against service level objectives. Google's own guidance puts it as class SRE implements interface DevOps: SRE is one practical implementation of DevOps ideas, not a rival to them.
For an enterprise leader the choice is rarely either/or. DevOps sets the delivery culture and automation; SRE adds an explicit reliability contract (SLOs and error budgets) that decides when to release and when to stop. This guide sets out the differences, the roles, the core SRE concepts and a sequence for adopting both. For the delivery side, see our guides to DevOps metrics and DevOps trends in 2026.
What is the difference between SRE and DevOps?
The two share goals: faster delivery, automation and shared ownership of production. They differ in what they are. DevOps is, in Google's words, a philosophy and approach to working; SRE is closer to a definition of a job or role with specific practices. The table below compares them for decision makers.
| Dimension | DevOps | SRE | Where they meet |
|---|---|---|---|
| What it is | A culture and set of practices that removes silos between development and operations | An engineering discipline that applies software engineering to operations, founded at Google by Benjamin Treynor Sloss | SRE implements many DevOps ideas in a defined role |
| Primary question | How do we deliver change faster and more safely? | How reliable must this service be, and how do we stay within that target? | Both want frequent releases without avoidable outages |
| Key mechanism | CI/CD, automation, shared ownership, measurement | SLIs, SLOs, error budgets, toil limits, blameless postmortems | SLO data can gate releases in pipelines |
| Who owns it | Whole delivery organisation | SRE team with engineering skills, partnered with product teams | Joint ownership of production |
| Typical metrics | Lead time, deployment frequency, change fail rate (see DORA) | Availability, latency, error budget burn, toil | Delivery and reliability metrics read together |
| Main risk | Culture change without reliability targets | Reliability gating without delivery speed | Misaligned incentives between teams |
A common myth is that DevOps handles pre-failure and SRE only post-failure. That is not how Google describes it. SRE teams own monitoring, change management, emergency response and capacity planning, so they work before, during and after incidents.
What does a DevOps engineer do?
A DevOps engineer builds and runs the delivery system: CI/CD pipelines, infrastructure as code, configuration management, environments and release automation. The role also plans delivery work with developers, reduces the effort of maintaining infrastructure and helps troubleshoot problems between development and operations. The outcome is a repeatable path from commit to production. Our guide to enterprise DevOps adoption covers the operating model.
What is site reliability engineering (SRE)?
Benjamin Treynor Sloss, who founded Google's SRE team after joining Google in 2003, describes SRE as what happens when you ask a software engineer to design an operations team. SREs are mainly software engineers who automate operational work. Google caps operational work such as tickets and on-call at 50% of an SRE's time so the rest goes to engineering. SRE teams are responsible for availability, latency, performance, efficiency, change management, monitoring, emergency response and capacity planning. Source: Google SRE book, Introduction
What are the core SRE concepts: SLI, SLO, SLA and error budgets?
Google's SRE book defines the terms as follows. Getting them distinct matters because contracts, targets and measurements belong to different owners.
| Term | Definition (Google SRE book) | Who typically owns it | Example |
|---|---|---|---|
| SLI | A carefully defined quantitative measure of some aspect of the level of service provided | Engineering and SRE | Share of requests served successfully |
| SLO | A target value or range of values for a service level, measured by an SLI | Product and SRE agree it | 99.9% of requests succeed over a quarter |
| SLA | An explicit or implicit contract with users that includes consequences of meeting or missing the SLOs it contains | Business and legal | A service credit or rebate if the target is missed |
| Error budget | One minus the availability target; the allowed unreliability | Shared by product and SRE | A 99.99% target leaves a 0.01% budget |
Source: Service Level Objectives chapter and Introduction. Consequences of an SLA are most easily recognised when financial, such as a rebate or penalty, but can take other forms.
How do error budgets settle the speed versus stability argument?
Product development is judged on velocity and SRE on reliability, so they naturally pull in opposite directions. Google's answer is the error budget, a shared, objective measure. As long as error budget remains, new releases can be pushed; as it nears exhaustion, releases slow or stop and the product team becomes self-policing. If innovation stalls, the team may loosen the SLO to enlarge the budget. Google notes that the budget aligns incentives and emphasises joint ownership between SRE and product development. Source: Embracing Risk chapter
What are toil and blameless postmortems?
Toil
Google defines toil as operational work tied to running a production service that is manual, repetitive, automatable, reactive, without lasting value, and that grows with the service. SRE aims to keep toil below 50% of each engineer's time, with at least half spent on engineering project work. Source: Eliminating Toil
Blameless postmortems
A postmortem is blameless when it focuses on the contributing causes of an incident without indicting any individual or team. The aim is for people to raise problems without fear, so the system and process can be fixed rather than hidden. Source: Postmortem Culture
When should an enterprise choose SRE, DevOps or both?
| Situation | What fits | Why | Current status of the practice |
|---|---|---|---|
| Slow, siloed releases and manual deployment | Start with DevOps practices | Fix the delivery path before adding reliability targets | Widely adopted; see DORA-based measurement |
| Customer-facing services with frequent incidents | Add SRE practices (SLOs, error budgets) | Gives an agreed reliability target and a release rule | Well documented in Google's SRE book and workbook |
| Many teams, inconsistent tooling | Both, plus a shared platform | Consistent pipelines and SLO tooling reduce toil | Often delivered through platform engineering |
| Small team, low-risk internal tools | DevOps basics only | A dedicated SRE function may cost more than the risk | Apply SLOs informally if needed |
Trade-offs and when not to use SRE
SRE needs engineers who can code and operate, and it needs product owners willing to agree reliability targets and honour the error budget. Without that agreement, SLOs become reports nobody acts on. A dedicated SRE function is also hard to justify for services where an outage has low business impact.
How should leaders adopt SRE alongside DevOps?
A practical sequence is below. It follows Google's guidance; adjust it to your estate.
- Stabilise delivery first: automated builds, tests and deployments, measured with the DORA metrics (see our DevOps metrics guide).
- Pick two or three user-facing services and define SLIs that reflect user experience.
- Agree SLOs with product owners, then compute the error budget and decide in advance what happens when it is spent.
- Build observability so SLIs can be measured reliably; see cloud native observability tools and full-stack observability.
- Track toil, automate the biggest sources and hold the 50% limit.
- Run blameless postmortems and feed actions back into the backlog.
How is AI changing SRE and DevOps work?
AI agents are being applied to incident triage, change review and runbook execution. The governance question is the same one SRE already asks: what may an automated actor change, and who can see why it did? ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control, and AgentGRC keeps autonomous agent actions inside policy, with the audit trail risk teams need.
To map one reliability or release decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
Is SRE the same as DevOps?
No. DevOps is a philosophy and approach to working, while SRE is closer to a concrete definition of a role with specific practices. Google describes the relationship as class SRE implements interface DevOps.
Who founded SRE?
Benjamin Treynor Sloss, a Google Vice President of Engineering, founded Google's SRE team after joining Google in 2003.
What is an error budget?
It is one minus the availability target. A service with a 99.99% target has a 0.01% error budget, which teams spend on releases and risk.
What is the difference between SLI, SLO and SLA?
An SLI is a measurement, an SLO is a target for that measurement, and an SLA is a contract with consequences if SLOs are missed.
What is toil in SRE?
Toil is manual, repetitive, automatable operational work that grows with the service. Google aims to keep it below 50% of an SRE's time.
Do we need both SRE and DevOps?
Most enterprises benefit from both: DevOps for the delivery path and SRE for explicit reliability targets. Small teams with low-risk services may only need DevOps basics.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE