

Key takeaway
- Real-time analytics architecture for CTOs and architects: six layers, Lambda vs Kappa, serving stores, governance, cost and a step-by-step adoption plan.
A real-time analytics architecture is the set of layers that moves an event from its source to a decision while the event is still useful: capture, a durable log, stream processing, a serving store that answers queries quickly, and a governance layer that says who may see and act on the result. The design choice that matters most is where you accept delay and where you do not, because each step towards lower latency adds cost and operating effort.
This guide is about the architecture, not the product shortlist. If you are choosing engines and managed services, read our streaming analytics tools buyer's guide; if you are deciding what to build around them, the sections below cover the layers, the patterns, the serving store, governance and a staged adoption plan for CTOs, CDOs and platform architects.
What layers make up a real-time analytics architecture?
Most production designs have the same six layers. The names of the tools change; the responsibilities do not.
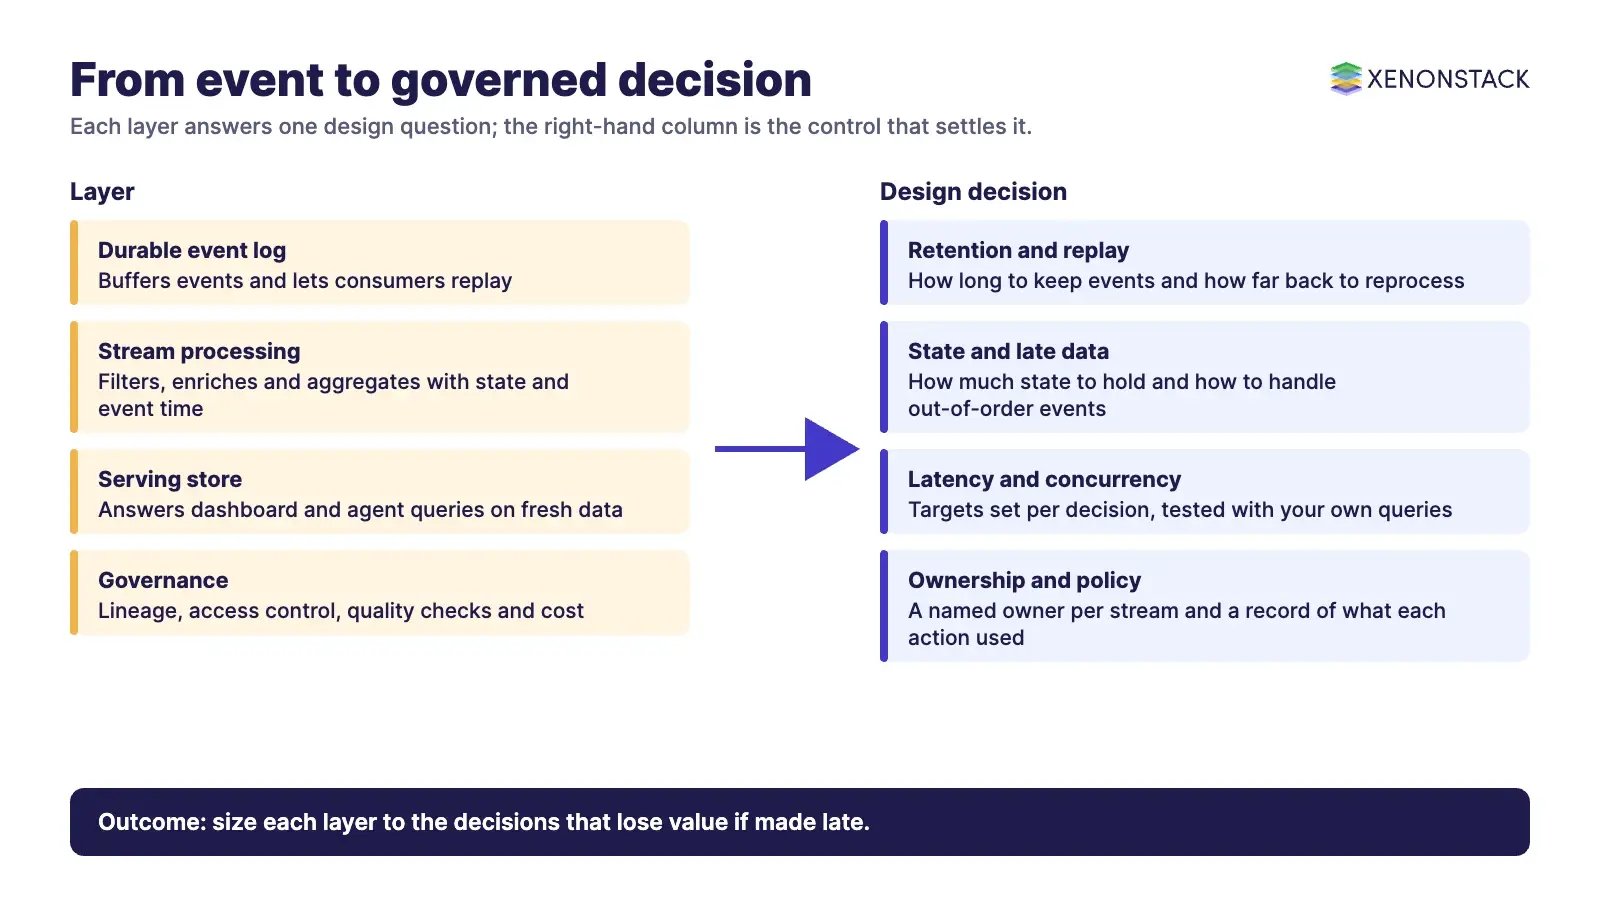
| Layer | What it does | Typical options | Decision to make |
|---|---|---|---|
| Sources and capture | Collects events from applications, logs, sensors, databases (change data capture) and partner feeds | Application events, CDC, IoT gateways | Which sources justify streaming at all |
| Durable event log | Buffers events, keeps order within a partition and lets consumers replay | Apache Kafka, managed cloud streams | Retention period and replay needs |
| Stream processing | Filters, enriches, joins and aggregates events, often with state and event-time rules | Apache Flink, Spark Structured Streaming, managed Flink services | How much state and how late-data tolerant |
| Serving store | Answers user-facing and agent-facing queries on fresh data | Real-time OLAP stores such as Apache Pinot or Apache Druid; open table formats such as Apache Iceberg for history | Query latency, concurrency and freshness targets |
| Consumption | Dashboards, alerts, APIs and AI agents that act on results | BI tools, alerting, natural-language analytics | Who or what is allowed to act automatically |
| Governance and operations | Lineage, access control, data quality checks, cost and incident monitoring | Catalogues, policy engines, observability | Who owns each stream and its quality |
Start from the decision, not the data. List the three to five decisions that lose value if they are made late, such as blocking a fraudulent payment or rerouting a delivery, and size each layer to those decisions only. Our guide to real-time analytics use cases shows where that value appears by industry.
Which pattern fits: Lambda, Kappa or streaming with a lakehouse?
Three patterns cover most enterprise designs. They are general architecture styles, so judge them by your team's skills and your accuracy requirements rather than by fashion.
| Pattern | How it works | When it fits | Trade-off |
|---|---|---|---|
| Lambda | A batch layer recomputes accurate results from full history while a speed layer gives quick approximate ones; a serving layer merges both | Existing batch estate you cannot replace yet, and a need for a fast view alongside it | Two code paths to build, test and keep consistent |
| Kappa | One stream processing path handles live and reprocessed data, replaying the log when logic changes | Event-centric products and teams that can run a replayable log | Replay at scale needs retention capacity and careful state handling |
| Streaming into a lakehouse | Streams land continuously in open table formats, with a low-latency store for hot queries | Need for both fresh operational answers and governed history for analysts and models | More moving parts to govern; table maintenance becomes an operational task |
Apache Flink describes state as a first-class part of its model and says its checkpointing keeps application state consistent after failures, which is what makes the single-path Kappa style practical for stateful logic (source: Apache Flink applications). Apache Kafka is the common choice for the log, and Apache Iceberg lets several engines work on the same tables at once, which suits the lakehouse pattern.
How do you choose the serving layer?
The serving store is where architectures often fail. A stream processor can compute results quickly, but dashboards and agents need a store that handles many concurrent queries on fresh data. Compare stores against your own latency and concurrency targets, using vendor figures only as a starting point.
| Option | What its own site says | When it fits | Current status |
|---|---|---|---|
| Apache Pinot | An open-source distributed OLAP database for user-facing and agent-facing real-time analytics, with sub-second queries on fresh data (vendor-published, varies with hardware and schema) | High-concurrency, customer-facing or agent-facing queries | Active Apache project |
| Apache Druid | A real-time analytics database with sub-second queries on streaming and batch data and native streaming ingestion | Event and time-series exploration with streaming ingestion | Active Apache project |
| Apache Iceberg tables | A high-performance format for huge analytic tables that several engines can use safely at once | Governed history, backfills and model training data | Active Apache project |
| Warehouse or lakehouse engine | Depends on the platform you already run | Minute-level freshness where sub-second answers are not required | Check your vendor's streaming ingestion limits |
If a business user or an AI agent needs a plain-language answer from this layer, AgentAnalyst lets teams ask questions of enterprise data in plain language and get real-time insights, working on top of the stores you already run.
Video: real-time analytics in practice.
What has changed in real-time architecture design?
| Change | What it means for the design | Source |
|---|---|---|
| Amazon Kinesis Data Analytics for SQL applications is discontinued: no new applications from 15 October 2025, deletion from 27 January 2026; Amazon Managed Service for Apache Flink is the successor | Do not design new pipelines on the SQL service; plan migration for existing ones | AWS documentation |
| Spark Streaming with DStreams is legacy and receives no updates; Structured Streaming is the recommended API | Choose Structured Streaming for new Spark work | Apache Spark guide |
| Serving stores now position themselves for agent-facing queries as well as dashboards | Plan for machine query volume and for policy on what an agent may read or do | Apache Pinot |
| Event time and watermarks are standard in modern engines | Design for late and out-of-order events instead of assuming clean arrival | Apache Flink |
How do you govern and secure a real-time pipeline?
Real-time pipelines move personal and commercial data faster than review cycles can follow, so controls must be built in rather than added later.
Ownership: name an owner for each stream, with a data contract that fixes schema, quality checks and retention.
Access: classify data at the source, apply least-privilege access at the log and the serving store, and mask sensitive fields early.
Privacy: map streams that carry personal data to the rules that apply to you, such as GDPR or CCPA, and set retention and deletion accordingly.
Automated actions: where results trigger actions, record what context and policy the decision used. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents.
Cost: the main drivers are retention, partition count, state size, always-on compute and query concurrency. Set a budget per stream and review it with the business owner.
How should you adopt it, step by step?
Pick one decision and its latency target. Write down the value of acting early and the cost of a wrong answer.
Run a proof of concept on one source. Use real data, measure end-to-end delay and note what breaks.
Fix data quality at the edge. Validate schema, duplicates and late events before they reach the serving store.
Add the serving store and one consumer. Load test for peak concurrency, not average.
Test resilience. Replay from the log, kill a node and confirm results stay correct.
Scale by stream, not by platform. Add sources one at a time, each with an owner and a budget.
Related reading: batch and real-time data ingestion with Apache NiFi, real-time streaming data visualisation and continuous intelligence with real-time analytics.
When is a real-time architecture the wrong choice?
Skip it when the decision is made daily or weekly, when source systems cannot emit events reliably, or when nobody can act on an answer within seconds. A well-run batch or micro-batch pipeline is cheaper and easier to audit. Build real-time layers only for the decisions that justify them, and keep the rest on batch.
Our streaming data platform page describes how we approach the build, and the streaming analytics architecture guide goes deeper on tooling.
To map one real-time decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is a real-time analytics architecture?
It is the set of layers that captures events, keeps them in a durable log, processes them as streams, serves fast queries and governs access, so decisions use data while it is still fresh.
What is the difference between Lambda and Kappa architecture?
Lambda runs a batch layer and a speed layer and merges their results. Kappa uses one stream path and replays the event log when logic changes, which removes the second code path but needs replayable retention.
Do I need Kafka and Flink for real-time analytics?
Not always. Kafka is a common event log and Flink a common engine for stateful processing, but managed cloud services or Spark Structured Streaming can meet many needs. Match the choice to your latency target and skills.
What serving store should I use for real-time dashboards?
Real-time OLAP stores such as Apache Pinot and Apache Druid are built for sub-second queries on fresh data at high concurrency. Test them with your own queries, because published figures vary with hardware and schema.
What has changed for AWS streaming analytics?
Amazon Kinesis Data Analytics for SQL applications is discontinued, with no new applications from 15 October 2025 and deletion from 27 January 2026. Amazon Managed Service for Apache Flink is the successor.
When should I use batch instead of real-time?
Use batch when decisions are made daily or weekly, when sources cannot emit reliable events or when no one can act within seconds. It is cheaper and simpler to audit.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE


