Key takeaway
- Machine learning pipeline guide: stages, MLOps maturity levels, Kubeflow, TFX, SageMaker, Azure ML and MLflow compared, plus governance and adoption steps.
A machine learning pipeline is an automated, versioned workflow that takes data from ingestion through validation, feature engineering, training, evaluation and deployment, then monitors the model and retrains it when data or performance changes. Each step runs as a separate, testable component, so the whole path from raw data to a served model can be rerun, audited and rolled back.
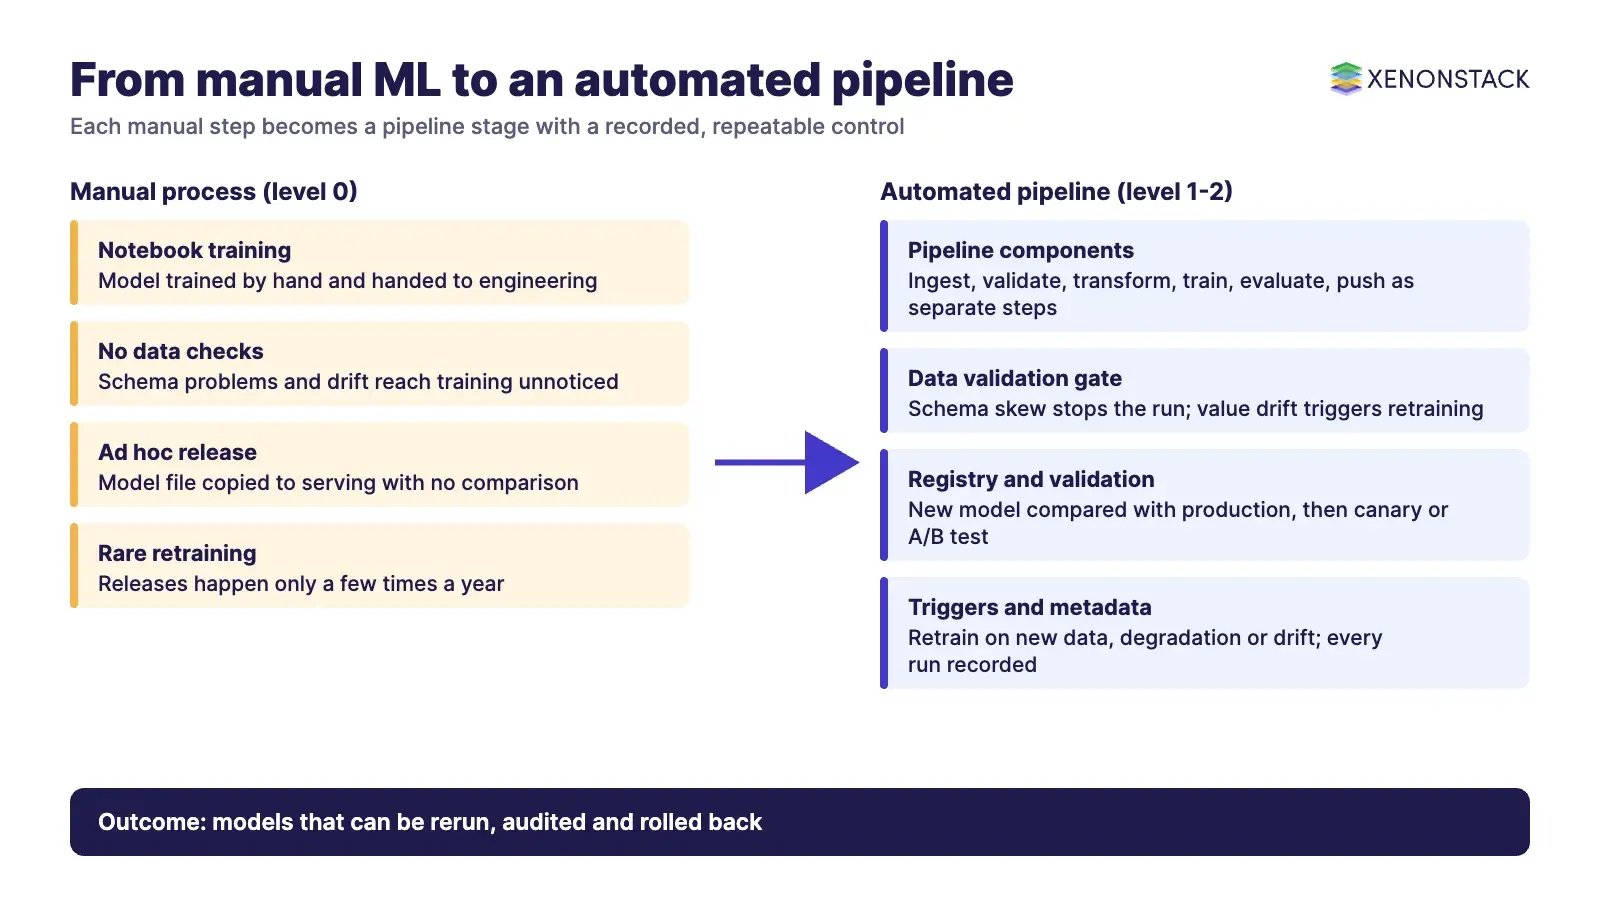
For enterprise teams the pipeline, not the model, is the unit you ship. Google Cloud's MLOps guidance describes the shift as moving from a manual process (level 0) to automated continuous training (level 1) and then to CI/CD for the pipelines themselves (level 2). Mature teams use orchestrators such as Kubeflow Pipelines, TFX, Amazon SageMaker Pipelines, Azure Machine Learning pipelines or Google Cloud's managed pipelines service, with MLflow or a similar registry tracking experiments and models.
What is a machine learning pipeline?
A machine learning pipeline breaks the ML workflow into connected steps, where each step consumes the outputs of the one before it. Microsoft defines an Azure Machine Learning pipeline as "a workflow that automates a complete machine learning task", and the Kubeflow Pipelines documentation describes a pipeline as components combined into a directed acyclic graph (DAG), where each component execution corresponds to a single container execution.
The older four-stage view (pre-processing, learning, evaluation, prediction) is still a useful mental model, but production pipelines add steps around it: data validation before training, model validation before release, a model registry for approved versions, and monitoring that can trigger the next run. Without those steps a pipeline trains models; with them it keeps models correct in production.
What are the stages of a machine learning pipeline?
The stages below follow the components that TensorFlow Extended (TFX) ships as standard and the validation steps in Google Cloud's MLOps architecture guide. Other orchestrators use different names for the same jobs.
| Stage | What happens | Example component (TFX naming) |
| Data ingestion | Read the input data and split it into training and evaluation sets | ExampleGen |
| Data validation | Compute statistics, infer a schema and flag anomalies or missing values before training | StatisticsGen, SchemaGen, ExampleValidator |
| Feature engineering | Transform raw fields into model features, ideally with the same code for training and serving | Transform |
| Training and tuning | Train candidate models and tune hyperparameters | Trainer, Tuner |
| Model evaluation | Compare the new model with the current production model, including performance on data segments | Evaluator |
| Infrastructure validation | Check that the model can actually be served before it is released | InfraValidator |
| Deployment | Push the approved model to serving, often behind a canary or A/B test | Pusher |
| Monitoring and retraining | Watch live performance and data drift, and trigger a new pipeline run when needed | Orchestrator triggers, model monitoring |
Training data quality decides how far the rest of the pipeline can go. Noisy labels or too little data cannot be fixed by tuning, which is why labelling and review belong inside the pipeline rather than before it. AgentLabel combines AI-assisted annotation with human review to label text, images and more at scale.
What does a production machine learning pipeline architecture look like?
Google Cloud's guide to MLOps continuous delivery and automation pipelines describes three maturity levels. They are a practical way to see where your architecture sits today.
| Level | What it means | When it fits |
| Level 0: manual process | Model building and deployment are manual; data scientists hand a trained model to engineering | Early experiments and models that rarely change |
| Level 1: ML pipeline automation | The whole training pipeline is deployed and retrains the model on fresh data (continuous training), with automated data and model validation and metadata for every run | Models whose data changes regularly and that need retraining without manual work |
| Level 2: CI/CD pipeline automation | Pipeline code itself is built, tested and deployed through CI/CD, with source control, a model registry, a feature store, an ML metadata store and a pipeline orchestrator | Many models, many teams, or frequent changes to features and pipeline code |
Which architecture components matter most?
Orchestrator: runs the DAG, handles retries and schedules, and passes artefacts between steps.
Metadata store: Google's guide says each run should record versions, timings, parameters, artefact locations and evaluation metrics, which is what makes lineage, reproducibility and rollback possible.
Feature store (optional): a central place to define, store and serve features for both training and serving, which helps avoid training-serving skew.
Model registry: holds approved model versions and their stage, so deployment pulls a known version rather than a file from a notebook.
Triggers: retraining can run on demand, on a schedule, when new training data arrives, when model performance degrades, or when data drift is significant.
Which machine learning pipeline tools fit which team?
The right tool depends mostly on where your data and compute already live. The table lists what each tool is, based on its own documentation, and where it tends to fit.
| Tool | What it is | When it fits | Current status (checked November 2026) |
| Kubeflow Pipelines | "A platform for building and deploying portable and scalable machine learning (ML) workflows" on Kubernetes; pipelines are written with a Python SDK and compiled to a platform-neutral IR YAML | Teams that run Kubernetes and want portability across clouds and on-premises | KFP v2 is current; v1 is documented as legacy |
| TensorFlow Extended (TFX) | A production ML platform based on TensorFlow with standard components for validation, training, evaluation and deployment | TensorFlow-centred teams that want built-in data and model validation | Runs on Apache Airflow, Apache Beam and Kubeflow Pipelines |
| Amazon SageMaker Pipelines | "A purpose-built workflow orchestration service to automate machine learning (ML) development" with serverless orchestration, a visual editor and lineage tracking | AWS-first organisations | Documented under Amazon SageMaker AI |
| Azure Machine Learning pipelines | Component-based pipelines built with the CLI, Python SDK or Designer, reusing outputs from unchanged steps | Azure-first organisations | CLI v1 support ended 30 September 2025 and SDK v1 support ended 30 June 2026; use v2 |
| Google Cloud pipelines (Vertex AI Pipelines) | Serverless runs of pipelines defined with Kubeflow Pipelines or TFX, with a lineage graph and managed ML metadata for every run | Google Cloud-first organisations, or Kubeflow users who want a managed backend | Google now documents the service as Agent Platform Pipelines in Gemini Enterprise Agent Platform |
| MLflow | An open-source platform for experiment tracking, model registry, evaluation and, for LLM and agent work, tracing and prompt management | Any team that needs tracking and a registry alongside its orchestrator | MLflow 3.x is the current release line (3.16.0 listed as latest on GitHub) |
Many enterprises combine an orchestrator with MLflow for tracking and a cloud service for serving. For a wider view of how these tools fit into operations, see our guide to MLOps processes and tools, and for training at scale across machines, our overview of distributed machine learning frameworks.
What has changed in machine learning pipelines?
Pipelines now cover LLMs and agents. MLflow now describes itself as an open-source AI platform for agents, LLMs and models, with tracing and agent evaluation alongside classic experiment tracking.
Older SDKs are retiring. Microsoft ended support for Azure ML CLI v1 on 30 September 2025 and gave 30 June 2026 as the end of support for SDK v1. Pipelines still on v1 should move to v2.
Product names keep moving. Amazon documents its service as SageMaker AI, and Google now documents its managed pipelines service as Agent Platform Pipelines. Check names and SDK versions before you standardise.
Record-keeping is becoming a legal duty. Under Article 12 of the EU AI Act, high-risk AI systems "shall technically allow for the automatic recording of events (logs) over the lifetime of the system". Pipeline metadata and lineage are the natural source of that evidence.
For models that must respond to events as they happen, see our guide to real-time machine learning.
How do governance, security and cost apply to ML pipelines?
Governance. Treat every pipeline run as evidence: which data version, which code, which parameters, which evaluation results, and who approved the release. Schema problems should stop the pipeline for investigation, while statistical drift in data values should trigger retraining, as Google's architecture guide recommends. Keep approval of high-impact models as a named human step. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents.
Audit. Lineage only helps if it can be retrieved when an auditor asks. Store run metadata centrally, link it to the model registry and keep it for as long as the model is in use. The Audit Agent gathers records of past decisions, including their reasoning, policy versions and sign-offs, into a single evidence package for decisions made through Context OS.
Security. Pipelines touch production data and push artefacts to serving, so run each step with least-privilege identities, keep secrets out of pipeline definitions, and pin container images and dependencies.
Cost. Microsoft notes that pipelines can reuse outputs from unchanged steps and run each step on the compute best suited to it. Caching, right-sized compute per step, and retraining on real triggers rather than a fixed daily schedule are the main levers.
How should an enterprise adopt machine learning pipelines?
Pick one model that matters. Choose a model with a clear business owner and a measurable outcome.
Version everything. Put data references, feature code, training code and configuration in source control.
Split the notebook into components. Ingestion, validation, features, training, evaluation and deployment each become a separate step.
Add validation gates. Data validation before training and model validation against the current production model before release.
Track runs and register models. Record metadata for every run and deploy only from the registry.
Monitor and set retraining triggers. Retrain on new data, performance degradation or drift, not only on a calendar.
Move the pipeline code into CI/CD. Once several models share the pattern, test and deploy pipeline changes the same way you ship application code.
When is a full ML pipeline not worth it?
A full level 2 setup costs engineering time and platform spend. It is rarely worth it for a one-off analysis, a model that is retrained once a year, or a proof of concept that has not yet shown business value. In those cases a scripted, versioned training run with a manual review is enough. The trade-off changes once a model drives decisions every day, its data shifts, or several teams depend on it: then the cost of manual retraining and untraceable releases quickly exceeds the cost of the pipeline.
Managed cloud services reduce operational work but tie the pipeline to one provider. Kubeflow Pipelines compiles to a platform-neutral format and runs on any conformant backend, which helps portability but means running Kubernetes yourself unless you use a managed backend.
To map one model-driven decision your pipeline feeds, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is the difference between an ML pipeline and MLOps?
An ML pipeline is the automated workflow that turns data into a deployed model. MLOps is the wider practice around it, including CI/CD for pipeline code, a model registry, metadata, monitoring and team processes.
What are the main stages of a machine learning pipeline?
Data ingestion, data validation, feature engineering, training and tuning, model evaluation, infrastructure validation, deployment, and monitoring with retraining.
What triggers a machine learning pipeline to retrain a model?
Google Cloud's MLOps guide lists on-demand runs, a schedule, the arrival of new training data, model performance degradation and significant data drift.
Which tools are used to build ML pipelines?
Common choices are Kubeflow Pipelines, TensorFlow Extended, Amazon SageMaker Pipelines, Azure Machine Learning pipelines and Google Cloud's managed pipelines service, usually with MLflow or a similar tool for tracking and the model registry.
Does the EU AI Act affect machine learning pipelines?
For high-risk AI systems, Article 12 requires that the system technically allows automatic recording of events (logs) over its lifetime. Pipeline metadata and lineage help provide that record.
Is Azure Machine Learning SDK v1 still supported?
No. Microsoft states that SDK v1 was deprecated on 31 March 2025 with support ending on 30 June 2026, and that CLI v1 support ended on 30 September 2025. Existing v1 workflows keep running but may be exposed to security risks or breaking changes, so Microsoft recommends v2.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE