Key takeaway
- LLM data annotation explained for enterprise leaders: how LLMs label data, how to assess quality, where humans review, plus the risks and controls.
LLM data annotation means using a large language model to propose labels, which people then review, so that models are trained on labelled data faster than manual labelling alone allows. A recent survey, Large Language Models for Data Annotation and Synthesis: A Survey (Tan et al., arXiv, version 3 dated 2 December 2024), organises the field into three parts: generating annotations, assessing them and using them to train models. This post follows that structure and adds the enterprise controls it leaves implicit.
For a CTO or Chief Data Officer the practical question is not whether an LLM can label data, but where it can be trusted, who reviews it and how the labels are governed once they feed a model. The short answer: use the LLM for pre-annotation and scale, keep humans on uncertain and high-impact items, measure against a gold set, and record how every label was produced. The same labelling skills sit behind natural language processing and building LLMs and foundation models.
What is LLM data annotation, and why are enterprises adopting it?
Data annotation is the step where raw text, images or audio receive the labels a supervised model learns from. LLM-based annotation replaces the first pass of that work with a model prompted to produce the label, an explanation or a confidence signal. The survey covers three areas: LLM-based annotation generation, assessment of LLM-generated annotations, and use of those annotations to train or improve models.
The evidence for the cost argument comes from a 2023 study, ChatGPT Outperforms Crowd-Workers for Text-Annotation Tasks (Gilardi, Alizadeh and Kubli, later published in PNAS). On 2,382 tweets covering relevance, stance, topic and frame detection, zero-shot ChatGPT beat crowd-workers on four of five tasks and showed higher intercoder agreement than both crowd-workers and trained annotators. The authors put the cost at under $0.003 per annotation, about twenty times cheaper than Amazon Mechanical Turk. That result is for short social-media text in 2023, so treat it as a signal to run your own pilot, not as a benchmark for your data.
Why does conventional data annotation not scale?
Manual annotation still sets the ground truth, but three limits push teams to add automation:
- Cost and time. Labelling large corpora needs many people and trained reviewers, which creates a bottleneck before model work can start.
- Inconsistency. Different annotators judge the same item differently, and that variation can carry bias into the model.
- Limited scale. As volume and the number of label types grow, manual processes become impractical to extend.
LLMs address the first and third limits well. They do not remove the need for a defined label scheme, a gold set and human review, which is why the rest of this post focuses on controls.
How do LLMs generate annotations?
How do zero-shot and few-shot prompts differ?
Manually written prompts are the starting point. Zero-shot prompts give the instruction and no examples. Few-shot prompts add demonstrations, usually through in-context learning (ICL), where examples are sampled from a small labelled set. Which examples you show matters, so teams test random selection against selection by expected usefulness.
A related line of work is ZeroGen (Ye et al., 2022), which has a pre-trained language model generate a training dataset with no human annotation, then trains a much smaller task model on it. The authors report experiments on text classification, question answering and natural language inference.
How do human and automated feedback align a model?
Aligning a model with attributes such as helpfulness and honesty needs preference data. Human feedback is the established route and is resource-intensive. Automated feedback uses an LLM to annotate or rank outputs, often as a reward model informed by human preference data. The survey notes that synthetic pairwise feedback is widely used for reward modelling and for direct preference optimisation (DPO), and that reward models can filter low-quality synthetic data.
How should you assess LLM-generated annotations?
How is annotation quality evaluated?
The survey describes methods from human-led to automated. They include a Turking Test, which checks adherence to annotation guidelines, manual review of originality, accuracy and variety, and comparison of LLM labels with human labels. Task-specific metrics apply where relevant, such as Self-BLEU for counterfactual diversity and Pass@k for code generation. For very large datasets, a common pattern is to compare LLM labels with gold labels on a small labelled subset. LLM-as-a-judge is a widely used automatic method, so keep a human-labelled sample to check the judge itself.
How do you choose which items humans should label?
Selection is where human effort pays most. Route low-confidence, ambiguous and high-impact items to people, and let the LLM handle clear cases. The survey cites CoAnnotating (Li et al., 2023), which allocates work between humans and LLMs by uncertainty, as a way to limit the reliability problems that come from hallucination. In practice, set a confidence threshold, sample accepted labels for audit, and track the human override rate as a quality signal.
How are LLM-generated annotations used downstream?
| Use | What happens | When it fits | Status |
|---|---|---|---|
| Direct supervision | LLM labels train or test a task model | Clear label scheme, a gold set to verify against | Common, needs sampling audits |
| Knowledge distillation | A large LLM produces data for a smaller, cheaper model | High volume inference where latency and cost matter | Covered in the survey, section 5.1 |
| In-context learning and chain-of-thought | LLM-generated examples or reasoning steps are placed in prompts | Reasoning tasks with little labelled data | Established prompting techniques |
| Instruction tuning | A model is fine-tuned on LLM-generated instruction data | Shaping behaviour to policy and tone | Common, quality of seed data decides outcome |
| Alignment tuning | Preference data trains reward models and policies (RLHF, DPO) | Models that must follow human expectations | Widely used, see survey section 5.2 |
Where instruction data is the goal, ElixirData's AgentInstruct is described on its own page as producing, checking and selecting varied instruction data for a customer's use case, and as pairing with labels that can be defended.
Which annotation tasks do LLMs handle, and what should humans check?
LLMs are strongest on text tasks where the label can be read from the language itself. The table lists the common ones and the review focus we would set.
| Task | What the LLM labels | Human review focus |
|---|---|---|
| Named entity recognition | People, organisations, locations and dates in text | Domain-specific names and boundary errors |
| Sentiment analysis | Positive, negative or neutral tone | Sarcasm, mixed opinions, domain language |
| Intent detection | Questions, requests or commands | Overlapping intent classes |
| Part-of-speech tagging | Grammatical role of each word | Rare constructions and specialist text |
| Semantic role labelling | Who did what to whom in a sentence | Complex or nested sentences |
| Event extraction | Events, participants, times and places | Missing participants and implied events |
| Topic categorisation | Document class from a fixed list | Items that fit two categories |
| Relation extraction | Links such as ownership or affiliation between entities | Direction and strength of the relation |
| Temporal expression recognition | Dates, durations and frequencies | Relative dates such as next quarter |
| Emotion detection | Joy, anger, sadness or surprise | Cultural and context differences |
LLM, rule-based or human annotation: which fits?
| Approach | Best for | Main limit | Choose it when |
|---|---|---|---|
| Rule-based labelling | Stable patterns with exact rules | Cannot cope with wording it was not written for | The pattern is fixed and auditable |
| LLM pre-annotation with human review | Text at volume with a defined label scheme | Bias, hallucination and overconfidence need review | Speed matters and you can sample for quality |
| Human-only annotation | High-stakes, specialist or ambiguous items | Cost and consistency | Errors are costly or no gold set exists yet |
A hybrid is usually the right design. The LLM pre-annotates and augments data, which cuts the volume humans see. Experts then review and correct, bringing domain judgement and keeping labels consistent. The balance moves toward humans as the cost of a wrong label rises.
What are the risks of LLM data labelling, and what controls reduce them?
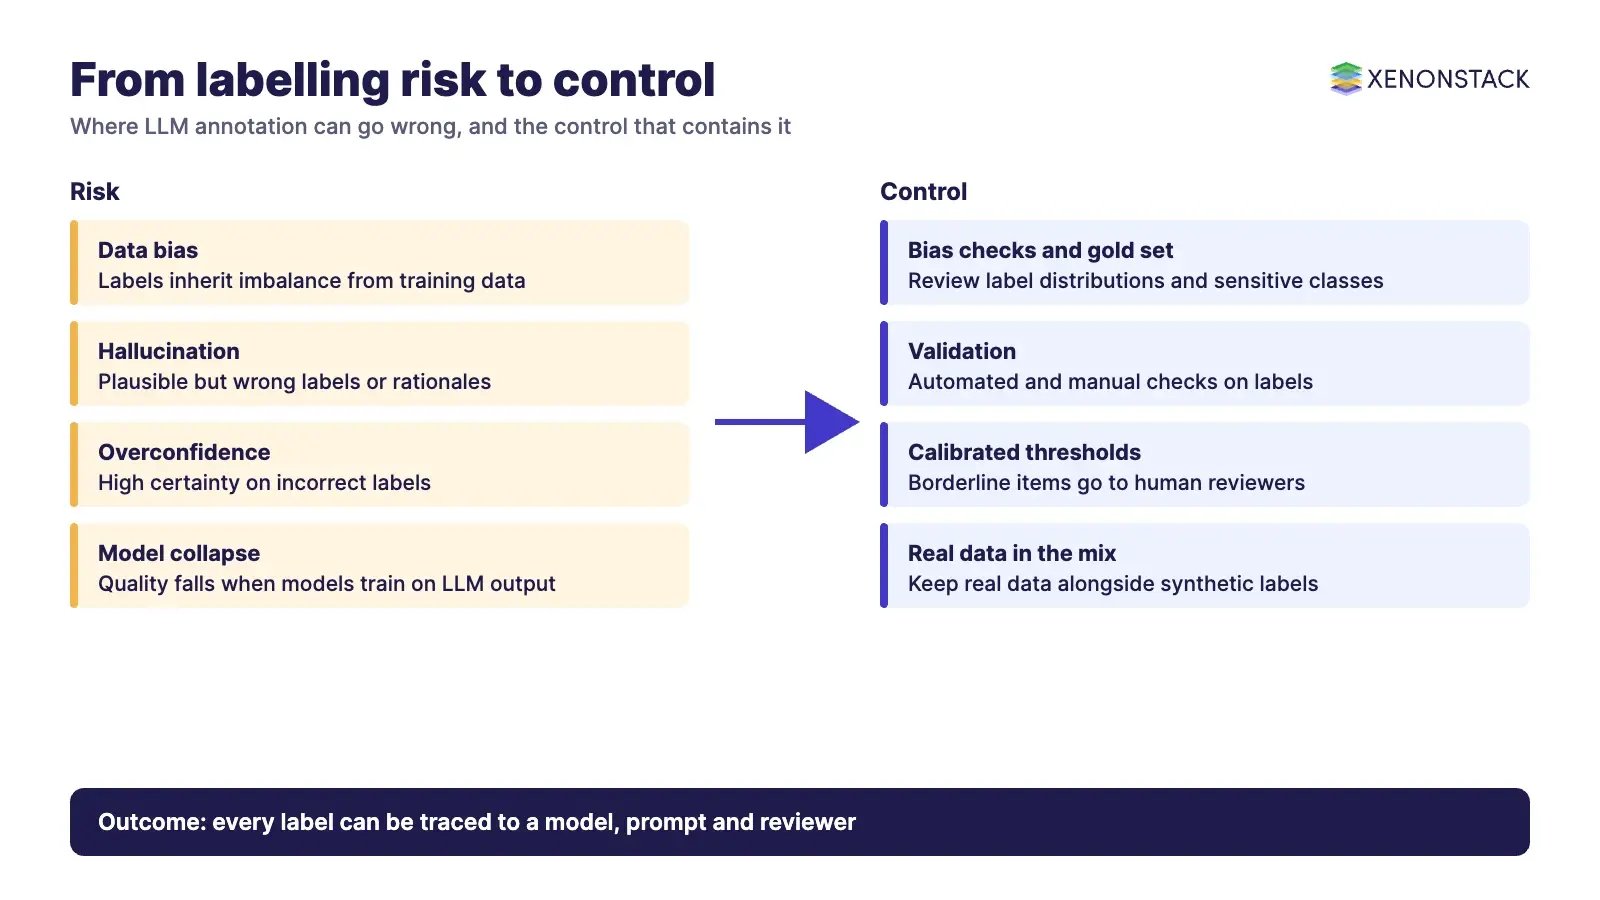
The survey states that without human insight LLM annotation may lead to biased and unfair results, and lists hallucination, model collapse and text-only scope among its limits. The table maps each risk to a control.
| Risk | What it looks like | Control |
|---|---|---|
| Data bias | Labels inherit prejudice or imbalance from training data | Bias checks on label distributions by group, diverse gold set, human review of sensitive classes |
| Hallucination | Plausible but wrong labels or rationales | Automated and manual validation, such as the Reverse Validation approach the survey cites |
| Overconfidence | High certainty on incorrect labels | Calibrate thresholds against gold data and send borderline items to people |
| Model collapse | Quality degrades when models train on other LLMs' output | The survey points to accumulating real data alongside synthetic data |
| Text-only scope | Weak fit for images, video or audio | The survey focuses on language models and does not cover multimodal LLMs in depth, so test multimodal labelling separately |
| Drift | Labels degrade as data changes | Re-run the gold set on a schedule and track prompt and model versions |
Treat labelling as a governed process, not a one-off script. Record which model, prompt version and reviewer produced each label so that a training set can be traced and defended. ElixirData's AgentLabel describes this on its own page as combining AI-assisted annotation with human review, flagging inconsistent labels before they reach training sets and recording how training data is approved, running on ElixirData Context OS, which keeps governed context, versioned policy and decision traces in one decision layer above AI agents. For ongoing monitoring of the models that consume these labels, see LLM observability.
What has changed since the first LLM annotation studies?
- Evidence base. The 2023 crowd-worker comparison was later published in PNAS, and the annotation survey reached version 3 in December 2024.
- Evaluation is central. LLM-as-a-judge is now a common automatic method, which makes human-labelled check sets more important, not less.
- Labels feed agents. Annotation data increasingly shapes agent behaviour through instruction and alignment tuning, so label provenance and policy matter as much as accuracy. See generative AI in the enterprise for the wider context.
What is a sensible adoption sequence?
- 1. Define the label scheme and write guidelines with edge cases.
- 2. Build a gold set labelled by experts, large enough to test each class.
- 3. Pilot zero-shot, then few-shot prompts and compare against the gold set.
- 4. Add routing so low-confidence and high-impact items go to people.
- 5. Audit a sample of accepted labels and track the override rate.
- 6. Record provenance for model, prompt version and reviewer, then retrain or distil.
When should you not use LLMs for annotation?
Avoid LLM-first labelling when the data is not text, when a wrong label carries safety, legal or financial consequences, when no gold set exists, or when the label scheme is still changing. In those cases start with human annotation, build the gold set, and bring the LLM in later as a pre-annotator.
Related reading: top generative AI use cases and applications and machine learning tools and use cases.
To map one labelling or training-data decision your agents depend on, and the context and policy behind it, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
Can an LLM replace human data annotators?
Not entirely. A 2023 study found zero-shot ChatGPT beat crowd-workers on four of five text-annotation tasks, but the annotation survey warns that without human insight LLM annotation may produce biased and unfair results. A hybrid design with human review is the safer default.
How much cheaper is LLM annotation?
The 2023 study by Gilardi, Alizadeh and Kubli reported under $0.003 per annotation, about twenty times cheaper than Amazon Mechanical Turk, on 2,382 tweets. Costs for your data and model will differ, so run a pilot.
How do you measure the quality of LLM-generated labels?
Compare them with expert gold labels on a small labelled subset, use task-specific metrics where they exist, and sample accepted labels for human audit. If you use an LLM as a judge, check the judge against human labels too.
What is the main risk of training on LLM-generated labels?
The survey lists bias, hallucination and model collapse. Controls include validation, calibrated confidence thresholds, human review of uncertain items and keeping real data in the training mix.
Do LLMs label images and audio?
The annotation survey concentrates on language models and does not cover multimodal LLMs in depth. Test multimodal labelling on its own gold set before relying on it.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE