Key takeaway
- Inception architecture explained for enterprise teams: v1 to v4 compared, how it ranks against newer models, and what changes in computer vision by 2030.
What is the Inception architecture, and is it still worth using?
The Inception architecture is a family of convolutional neural networks from Google researchers that runs filters of several sizes in parallel inside one module, so a network can read an image at more than one scale without a large parameter bill. GoogLeNet, the first version, was a 22-layer network used in the ILSVRC 2014 submission, and the paper reports it set a new state of the art for classification and detection at that challenge (Going Deeper with Convolutions, arXiv, September 2014).
For an enterprise team the practical answer is narrower than the history. Inception-v3 is still a sound, well-documented transfer-learning backbone of about 24 million parameters, but newer designs score higher at similar size, and for edge and regulated deployments the model choice matters less than how you evidence it. This post covers the versions, what each one fixed, how they compare today, and what to expect over the next 3 to 5 years. For the wider picture of how a vision system is built around a model like this, read our guide to the workflow of computer vision, and for a newer architecture family see graph neural networks in computer vision.
How did the Inception architecture evolve from v1 to v4?
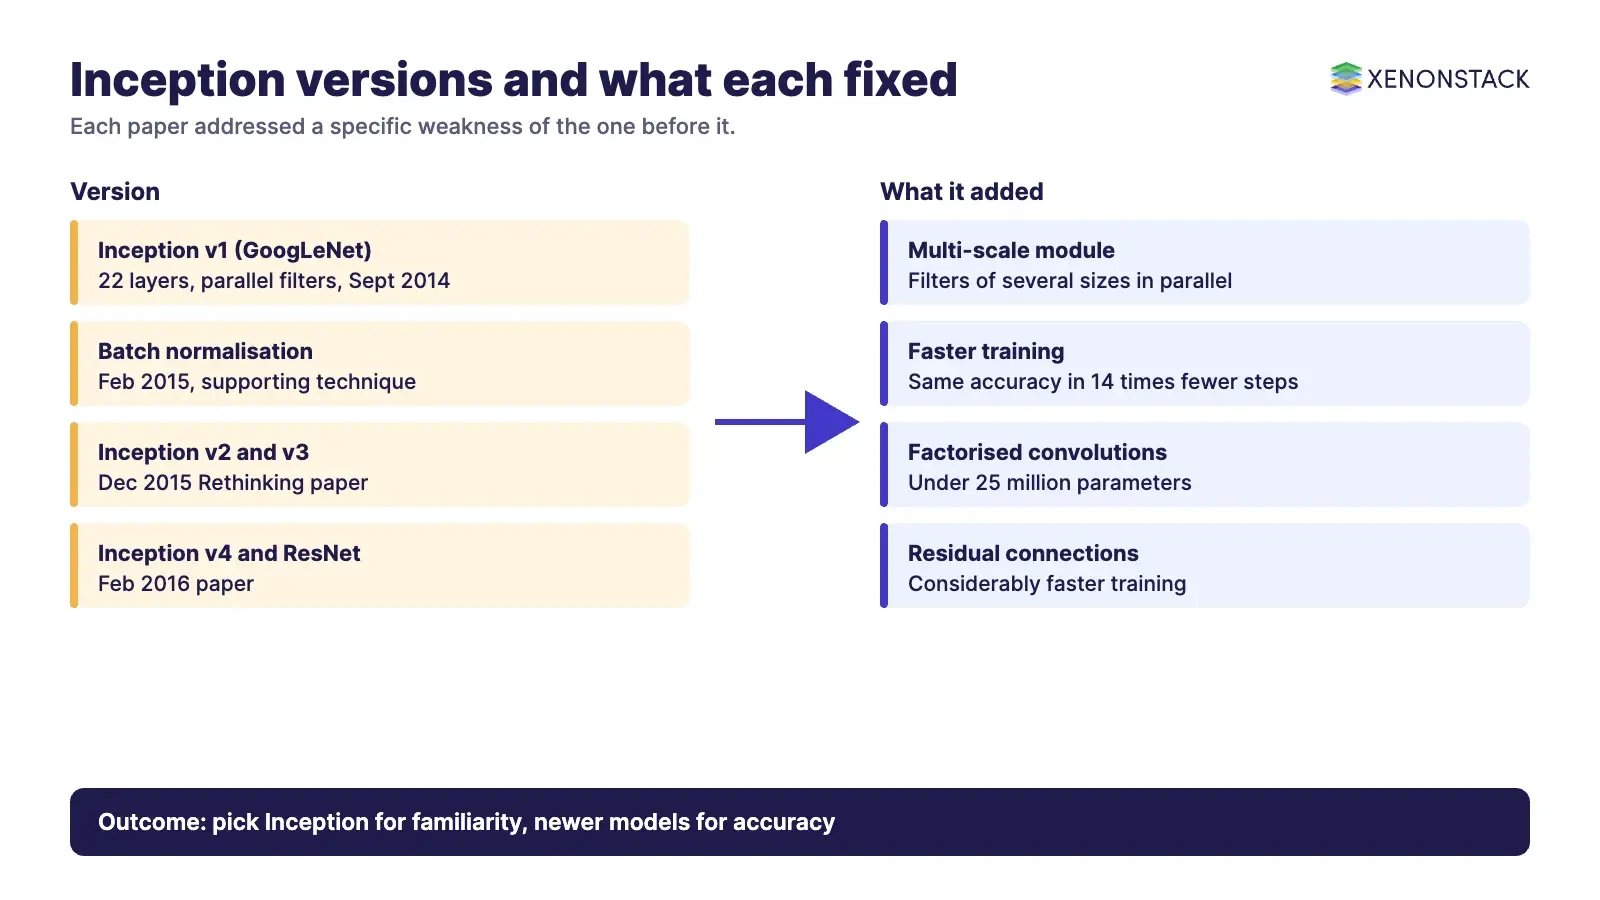
Each release fixed a specific weakness of the one before. The dates below come from the original papers on arXiv.
| Version | Paper and date | What changed | Reported result |
|---|---|---|---|
| Inception v1 (GoogLeNet) | Going Deeper with Convolutions, Sept 2014 | Parallel filter branches in an Inception module; 22 layers deep | New state of the art for classification and detection at ILSVRC 2014 |
| Batch normalisation (supporting technique) | Batch Normalization, Feb 2015 (Ioffe and Szegedy) | Normalises layer inputs during training | Same accuracy as a state-of-the-art model in 14 times fewer training steps; ensemble reached 4.9% top-5 validation error |
| Inception v2 and v3 | Rethinking the Inception Architecture for Computer Vision, Dec 2015 | Factorised convolutions and aggressive regularisation | Single frame: 21.2% top-1 and 5.6% top-5 error, about 5 billion multiply-adds, under 25 million parameters |
| Inception v4 and Inception-ResNet | Inception-v4, Inception-ResNet and the Impact of Residual Connections on Learning, Feb 2016 | Streamlined Inception networks; residual connections added to some variants | Ensemble of three residual models and one Inception-v4: 3.08% top-5 error on the ImageNet test set |
Two corrections to what is often repeated. The v2 and v3 changes were published together in the December 2015 paper, and Inception-v4 and the Inception-ResNet variants were published together in February 2016, not in separate years. The residual-connection finding is also more modest than it is usually told: the authors report clear evidence that residual connections speed up training considerably, and only some evidence that residual Inception networks slightly outperform similar-cost networks without them.
How does Inception compare with newer image models today?
Keras publishes pretrained weights and ImageNet validation figures for several families, which gives a like-for-like view. These are Keras's own numbers, so treat them as a guide for shortlisting, not a benchmark for your data.
| Model | Parameters | Top-1 | Top-5 | When it fits |
|---|---|---|---|---|
| InceptionV3 | 23.9M | 77.9% | 93.7% | Established transfer-learning baseline with wide tooling support |
| InceptionResNetV2 | 55.9M | 80.3% | 95.3% | When accuracy matters more than size and latency |
| Xception | 22.9M | 79.0% | 94.5% | Similar size to InceptionV3 with higher reported accuracy |
| EfficientNetV2S | 21.6M | 83.9% | 96.7% | Better accuracy at a comparable parameter count |
| ConvNeXtTiny | 28.6M | 81.3% | not listed | Modern convolutional design; larger variants score higher |
Source: Keras Applications (read 11 Nov 2026). The reading for a decision maker is simple: Inception-v3 is no longer the accuracy leader at its size, so choose it for ecosystem and familiarity, not for performance.
What were the limits of the original Inception design?
The shortcomings that drove later versions are worth knowing because they recur in any vision model you put into production.
Cost and scale
Large filters and wide modules raised compute and memory. Factorising convolutions, the central idea of the 2015 Rethinking paper, was the response: it reached under 25 million parameters at about 5 billion multiply-adds per inference.
Training stability
Deep networks were slow and fragile to train. Batch normalisation and, later, residual connections addressed this, as the two papers above report.
Fit for other tasks
Inception was designed for classification. Detection, segmentation and video work usually use it as a feature extractor inside a larger system, not as the whole model.
How do you adapt an Inception model for real-world use?
Most enterprise projects do not train Inception from scratch. They start from pretrained weights and adapt them. For a deeper treatment of finding unusual items in images, see our post on anomaly detection in images and videos.
| Technique | What it does | When it fits | Trade-off |
|---|---|---|---|
| Transfer learning and fine-tuning | Reuses pretrained features; retrains the last layers on your data | Small labelled datasets | Inherits biases of the source data |
| Quantisation | Stores weights and activations at lower precision, such as 8-bit integers | Edge devices, latency limits | Accuracy must be re-tested after conversion |
| Pruning | Removes redundant weights or filters | Memory-bound deployments | Needs retraining to recover accuracy |
| Knowledge distillation | Trains a smaller model to mimic a larger one | When a compact model is required | Extra training effort |
| Data augmentation | Creates variants by rotation, scaling or cropping | Limited or uneven data | Cannot fix mislabelled data |
| Regularisation and early stopping | Dropout, weight decay, stop when validation loss stops improving | Any fine-tuning run | Needs a clean validation set |
When should you not choose Inception?
Do not start with Inception when you need the highest accuracy at a small size (the table above shows newer models ahead), when the task is dense prediction such as segmentation and a purpose-built architecture exists, or when your team has no reason to maintain a 2015-era backbone. Do choose it when you have an existing, validated Inception pipeline, tooling that expects it, or a teaching and baseline role where its documentation is an advantage.
How should an enterprise govern and secure an image classifier?
A classifier is a decision component, so it needs the controls any decision system needs. Record the model version, training data source and evaluation results for each release. Re-test after any quantisation or pruning. Keep human review for decisions that affect people. Robustness to adversarial inputs is a security question as well as an accuracy one, so test for it where the output drives an action. When a model output triggers a workflow, ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control. For policy checks on those actions, AgentGRC keeps autonomous agent actions inside policy, with the audit trail risk teams need.
What will change in Inception-style computer vision over the next 3 to 5 years?
Vision model design is moving towards edge deployment, domain-specific models and stricter regulation. The table separates dated or published forecasts from our own view. Analyst figures are quoted as reported by the cited outlet.
| Prediction | Why we expect it (evidence) | Timeframe | What leaders should do now |
|---|---|---|---|
| More vision inference will run on devices and edge nodes | Gartner predicts more than two-thirds of enterprises will deploy edge AI by 2029, up from 10% in 2025, and that more than two-thirds of enterprise-managed data will be created and processed outside the data centre or cloud by 2028 (as reported by Network World, 14 Sep 2026). IDC predicts half of enterprise AI inference will run on endpoints or edge nodes by 2030 (same source). | 2028 to 2030 | Budget for compact models and test quantised accuracy before committing to hardware |
| Domain-specific models will replace general ones in many enterprise uses | Gartner predicts that by 2028 over half of the GenAI models enterprises use will be domain-specific (Gartner, 20 Oct 2025). Gartner's figure covers GenAI; applying it to vision is XenonStack's view. | By 2028 | Keep a small, well-evidenced model per task rather than one general model for all |
| Transformer and modern convolutional designs will stay ahead of Inception-class backbones | Vision Transformer (arXiv, Oct 2020) showed a pure transformer can be competitive with leading CNNs; ConvNeXt (arXiv, Jan 2022) reports 87.8% ImageNet top-1 and outperforming Swin Transformers on COCO detection and ADE20K segmentation. This is a trend in published results; our forecast that Inception stays a legacy baseline is XenonStack's view. | Through 2030 | Treat Inception as a baseline, and plan migration where accuracy or size limits bite |
| Regulation will require evidence for vision systems used in high-risk settings | The EU AI Act became generally applicable on 2 August 2026, with Annex III high-risk obligations from 2 December 2027 and Annex I product obligations from 2 August 2028, as stated on the European Commission AI Act page. Real-time remote biometric identification for law enforcement in public spaces is prohibited from February 2025, and remote biometric identification systems are listed as high-risk. | 2027 to 2028 | Map each vision use case to a risk class and keep model, data and decision records ready |
| Vision models will increasingly feed agents that act, not just dashboards | XenonStack's view, based on our delivery work: a detection model is the eyes, agentic reasoning is the brain and system integrations are the hands, so value moves from flagging a defect to resolving it. Gartner also names physical AI, machines that sense, decide and act, as a 2026 strategic trend (same Gartner page as above). This would be proved wrong if enterprises keep vision output as alerts for people only. | 2027 to 2030 | Define which vision-triggered actions an agent may take, and which need a human |
What this means for you: if you run a vision pipeline on an Inception backbone, plan a deliberate review within the next 12 to 24 months, because the likeliest pressures are smaller devices and regulatory evidence, not a new Inception release. NexaStack runs on-premises, cloud and hybrid; its page describes it as an agentic operating platform for physical AI with vision and edge capabilities.
To map one vision-driven decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is the Inception architecture?
It is a family of convolutional networks that apply filters of several sizes in parallel inside one module. The first version, GoogLeNet, was 22 layers deep and set a new state of the art for classification and detection at ILSVRC 2014, as reported in the 2014 paper.
Which Inception version should I use?
For transfer learning, Inception-v3 is the common choice at about 23.9 million parameters and 77.9% top-1 on ImageNet validation per Keras. InceptionResNetV2 reaches 80.3% top-1 but has 55.9 million parameters.
Is Inception still competitive with newer models?
On Keras's published figures, EfficientNetV2S reaches 83.9% top-1 at 21.6 million parameters, ahead of InceptionV3. Inception remains useful as an established baseline.
What did batch normalisation change for image classifiers?
The 2015 paper reports reaching the same accuracy as a state-of-the-art image classification model in 14 times fewer training steps.
Can Inception run on edge devices?
Techniques such as quantisation, pruning and distillation reduce size and compute, but accuracy must be re-tested after each. Gartner expects edge AI deployment to spread widely by 2029, as reported by Network World.
What will change in Inception-style computer vision over the next 3 to 5 years?
Expect more inference at the edge, domain-specific models, continued displacement of Inception-class backbones by newer designs, and evidence requirements under the EU AI Act, with high-risk obligations from 2 December 2027 and 2 August 2028. Treat these as planning assumptions, not guarantees.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE