Key takeaway
- Graph neural network applications proven in production, which GNN task fits each business question, current tools, limits and governance for enterprises.
Graph neural network (GNN) applications are the problems where the answer depends on how things are connected, not only on what each thing looks like: recommendations, travel-time estimates, fraud rings, molecules and materials, and links missing from a knowledge graph. A GNN learns a vector for every node by passing messages along the edges, then uses those vectors to classify nodes, predict links or score whole graphs. For an enterprise, the question is not whether GNNs work, because published production systems exist, but whether your data and your decision justify the cost over simpler graph queries or tabular models.
This guide takes the decision view. For the architecture, read our graph convolutional network guide. For the platforms that store and query graphs, read graph analytics tools. Here you will find where GNNs have been shown to pay off, what each case needed, how to choose between a GNN and a simpler method, which tooling is current in 2026, and how to govern a model that is hard to explain.
How does a GNN turn connections into predictions?
A graph is a set of nodes and the edges between them, directed or undirected. In the message passing view described by message passing neural networks, each layer lets a node collect information from its neighbours and update its own vector, so after two layers a node reflects its two-hop neighbourhood. Variants differ in how they aggregate: GraphSAGE samples and aggregates a local neighbourhood and is inductive, so it can embed nodes it never saw in training, while graph attention networks learn how much weight each neighbour deserves. R-GCN extends the idea to graphs with many edge types, such as knowledge graphs.
Which graph neural network applications are proven in production?
The table lists applications backed by a primary source. Treat the reported figures as the authors' own results on their own data, not as a benchmark you will reproduce.
| Application | What the graph is | What the source reports | Source |
|---|---|---|---|
| Web-scale recommendation | Pins and boards as nodes, saves as edges | PinSage ran at Pinterest on a graph of about 3 billion nodes and 18 billion edges, trained on 7.5 billion examples; the authors report better recommendations in offline metrics, user studies and A/B tests | Ying et al., 2018 |
| Travel-time (ETA) prediction | Road segments and their connections | A GNN estimator deployed in Google Maps; the authors report a significant cut in negative ETA outcomes, with 40% or more in cities such as Sydney | Derrow-Pinion et al., 2021 |
| Materials discovery | Atoms and bonds in candidate crystals | GNoME used graph networks with active learning and DFT checks; the authors report 2.2 million structures stable relative to prior work, with 736 matching experimentally known structures | Merchant et al., Nature, 2023 |
| Fraud, credit and recommendation on enterprise graphs | Customers, accounts, products and transactions | Amazon Neptune ML names product recommendation, credit-worthiness prediction and fraud detection as uses, and builds its GNN models on the Deep Graph Library | Amazon Neptune ML documentation |
| Missing links in knowledge graphs | Entities and typed relations | Neptune ML supports link prediction, for example predicting what an entity such as a drug is related to through a given edge type | Amazon Neptune ML documentation |
Two points follow. First, every case has a rich, connected dataset and a prediction that is hard to express as a fixed rule. Second, the large deployments needed neighbourhood sampling or distributed inference to run at scale, so engineering effort, not model theory, was the main cost.
Which GNN task fits which business question?
| Business question | GNN task | Typical output | When it fits |
|---|---|---|---|
| Which account or device is risky? | Node classification | A label or score per node | Labels exist for some nodes and neighbours carry signal |
| Which product or person should we connect next? | Link prediction | A ranked list of likely edges | You hold a large interaction graph and need ranked candidates |
| Is this transaction or relationship unusual? | Edge classification | A label per edge | The relationship itself carries the risk, not only its endpoints |
| Is this molecule, material or network a good candidate? | Graph classification or regression | A score per whole graph | Each case is its own small graph with a measurable property |
| What value should we forecast for each node? | Node regression | A number per node | A numeric target such as popularity or demand is available |
These five task types match those listed in the Amazon Neptune ML documentation, which is a useful checklist when you scope a pilot.
Do you need a GNN, or will a simpler method do?
Start with the cheapest method that answers the question. A graph query or a centrality or community algorithm (see graph analytics and knowledge graphs) needs no training and is easy to audit. A GNN earns its place when the signal is spread across neighbourhoods and node attributes together, and when you must score nodes the system has not seen.
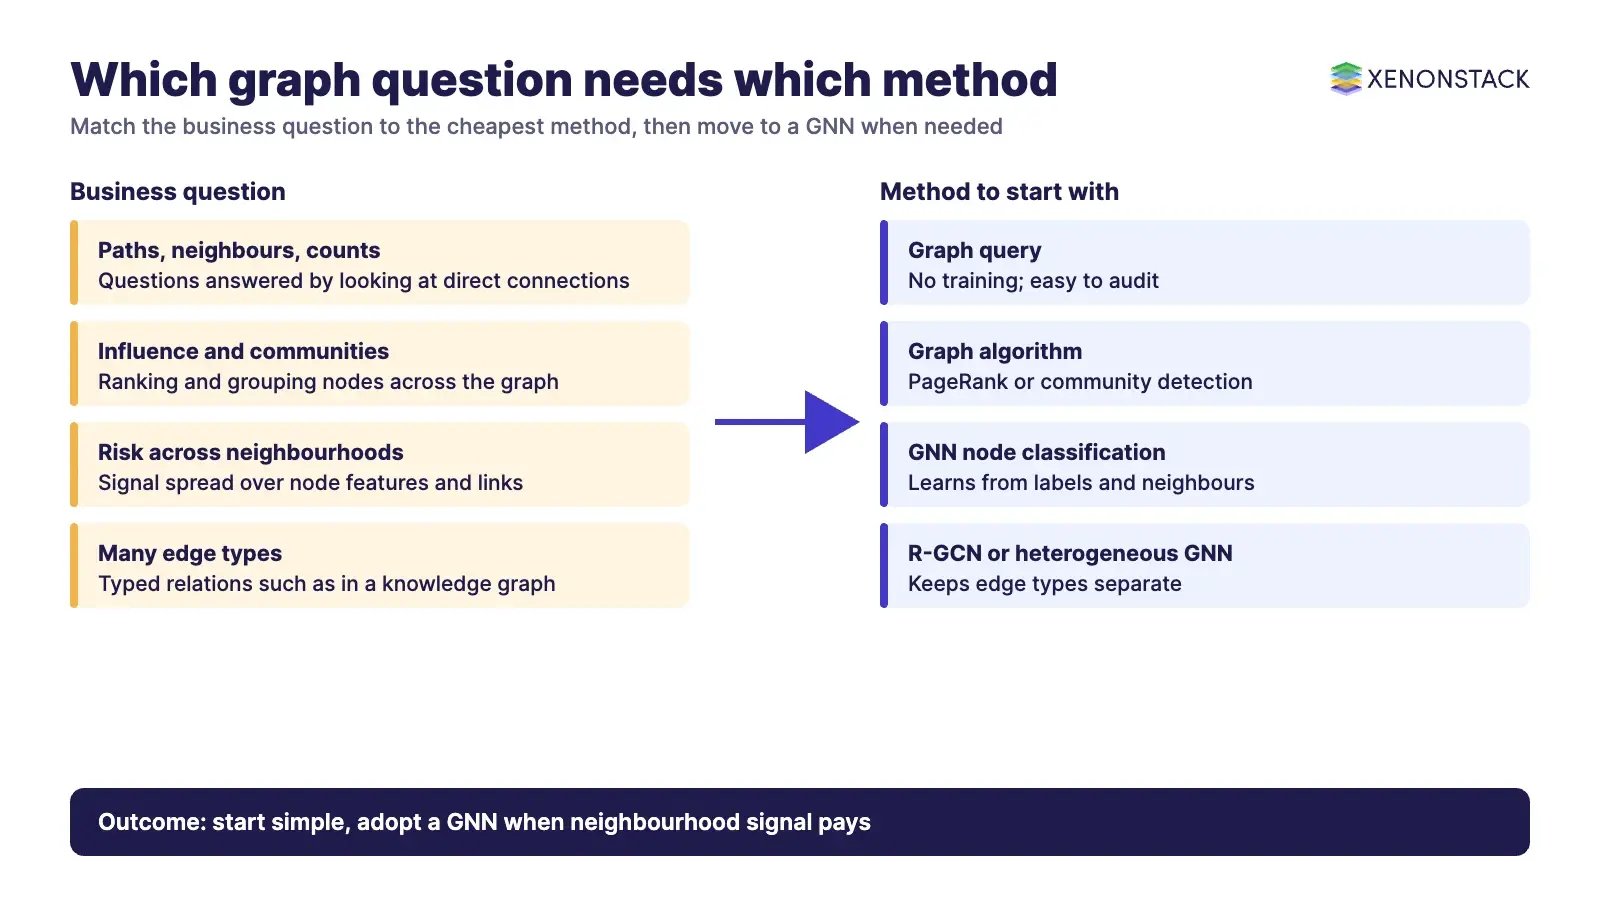
| Situation | Better first choice | Move to a GNN when | Current status of the approach |
|---|---|---|---|
| You need paths, neighbours or counts | Graph query on a graph database | Rules and counts stop separating good from bad cases | Mature; see our graph databases guide |
| You need influence, communities or ranking | Graph algorithms such as PageRank or community detection | You also need to use node features and learn from labels | Mature; see graph analytics tools |
| You have labels and mostly independent rows | Standard tabular model | Features built from neighbours add measurable lift | Mature |
| New nodes arrive constantly | Inductive GNN such as GraphSAGE | Retraining for every new node is too slow | Documented in the original paper |
| The graph has many edge types | R-GCN or a heterogeneous GNN | One edge type loses too much meaning | Used in Neptune ML |
Not every project should use a GNN. Avoid it when the graph is small enough to reason about by hand, when you cannot explain a score to a regulator and no explanation method is acceptable, or when the edges themselves are low quality. A GNN amplifies poor edges.
Which tools are current for GNN projects in 2026?
| Tool | What it is for | What its own page says | When it fits |
|---|---|---|---|
| PyTorch Geometric | Writing and training GNNs on PyTorch | Version 2.9.0; mini-batch loaders, neighbourhood sampling, multi-GPU and distributed training | Research and custom models; start here for most teams |
| GraphStorm | Enterprise graph machine learning at scale | Apache-2.0; targets graphs with billions of nodes and edges; no-code command line and a Python interface; recommends Amazon SageMaker AI for distributed runs | Large graphs on AWS where a managed path matters |
| Amazon Neptune ML | GNN predictions on a Neptune graph | Built on the Deep Graph Library with Amazon SageMaker AI; supports node and edge classification and regression, and link prediction | Data already in Neptune |
Sources: PyTorch Geometric documentation, the GraphStorm repository and the Amazon Neptune ML documentation. Older write-ups claim that Neptune uses GNNs to index and query data or that SageMaker has a built-in GNN algorithm. We could not confirm either on current AWS pages, so we have removed them; Neptune ML trains GNN models for predictions.
What are the limits and risks of GNNs?
Depth is not free. Research on the graph convolutional network shows that its convolution is a form of Laplacian smoothing, so stacking many layers risks over-smoothing, where node vectors become too alike to separate. Scale is the second limit: PinSage needed random-walk-based neighbourhood selection and a MapReduce inference step to run on billions of nodes. The third is explainability. Methods such as GNNExplainer identify a small subgraph and feature set behind a single prediction, which gives reviewers something concrete to inspect.
How should a GNN be governed in a regulated decision?
A score from a GNN becomes a business decision when an agent or an analyst acts on it. Keep the graph version, the model version, the policy applied and the explanation with every decision. ElixirData Context OS is described on its own site as a governance layer that checks policy and permissions before an agent acts and keeps a record of each decision, and AgentGRC keeps autonomous agent actions inside policy with an audit trail for risk teams. To let analysts ask questions of the scored data in plain language, AgentAnalyst does this and writes decision traces back to Context OS.
What is a sensible adoption sequence?
- Pick one decision with a measurable cost, such as a fraud review queue or a recommendation slot.
- Build the graph from existing systems and check edge quality before any modelling.
- Set a baseline with a graph query, a graph algorithm and a tabular model.
- Train a small GNN, with neighbourhood sampling if the graph is large, and compare it with the baseline on the same holdout.
- Add an explanation method and a review step for high-impact scores.
- Deploy with versioned graph, model and policy, and monitor drift before extending to a second use case.
To map one decision your graph models should inform, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What are the main applications of graph neural networks?
Published production examples include web-scale recommendation at Pinterest, travel-time estimation in Google Maps, and materials discovery with GNoME. Amazon Neptune ML also names product recommendation, credit-worthiness prediction and fraud detection as uses.
Is a GNN the same as a graph convolutional network?
No. A graph convolutional network is one type of GNN. Others include GraphSAGE, graph attention networks and R-GCN, which differ in how each node aggregates information from its neighbours.
When should I use a GNN instead of a graph query or tabular model?
Use a GNN when the signal is spread across neighbourhoods and node attributes together, and when you must score nodes unseen in training. Use a graph query or algorithm for counts, paths and rankings, which need no training.
Which tools should a team start with?
PyTorch Geometric suits custom models and research. GraphStorm targets graphs with billions of nodes and edges, and Amazon Neptune ML suits data already in Neptune.
Can GNN predictions be explained?
Partly. GNNExplainer identifies a compact subgraph and a small set of features that most influence a single prediction, which helps reviewers, though it does not make the model fully transparent.
What goes wrong with deep GNNs?
Stacking many layers risks over-smoothing, where node vectors become too similar. Large graphs also need neighbourhood sampling or distributed inference to run at scale.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE