Key takeaway
- Graph analytics and knowledge graph use cases for enterprises: centrality, community and path algorithms, RDF, ISO GQL, GraphRAG, governance and adoption.
Graph analytics is the set of algorithms that analyse how entities are connected: who or what is most central, which groups form communities, and what the shortest or riskiest path between two points is. A knowledge graph is the data layer that makes those connections meaningful by describing real-world entities, their relationships and the business vocabulary behind them, so that people, applications and AI systems can query them consistently.
Used together, they answer questions that row-and-column analytics struggles with, such as which customers share hidden links to a sanctioned party, which supplier failure would stop the most production lines, or which facts a generative AI assistant should be grounded on. This guide explains the algorithms, the standards (RDF, SPARQL and the ISO GQL standard published in 2024), GraphRAG, and the enterprise use cases where graphs earn their place.
What is the difference between graph analytics, a knowledge graph and a graph database?
The three terms are often used interchangeably, but they describe different layers. A graph database stores and queries connected data. A knowledge graph adds shared meaning (an ontology or schema) on top of that data. Graph analytics runs algorithms over either to produce scores, groups and paths that feed decisions.
| Layer | What it is | When it fits | Typical tooling |
|---|---|---|---|
| Graph database | Storage and query engine for nodes and relationships | Operational queries that hop across many relationships, where SQL joins become deep and hard to maintain | Property graph databases queried with Cypher or GQL; RDF triple stores queried with SPARQL |
| Knowledge graph | Connected data plus an ontology that defines entity types, relationships and rules | Integrating data from many systems under one business vocabulary; grounding search and AI on agreed definitions | RDF and OWL ontologies, or a governed property graph schema |
| Graph analytics | Algorithms over the graph: centrality, community detection, path finding, similarity | Ranking, grouping and routing questions where the answer depends on the structure of the network | Libraries such as Neo4j Graph Data Science and NetworkX, or graph features in data platforms |
For a deeper look at the storage layer, see our guide to the role of graph databases in big data analytics.
Which graph analytics algorithms matter for enterprise decisions?
Most enterprise graph work uses four algorithm families. The Neo4j Graph Data Science documentation describes centrality algorithms as measuring "the importance of distinct nodes in a network", community detection algorithms as evaluating "how groups of nodes are clustered or partitioned", and path finding algorithms as finding "the path between two or more nodes" or evaluating "the availability and quality of paths". The open-source NetworkX library (documentation version 3.7) groups its algorithms in a similar way.
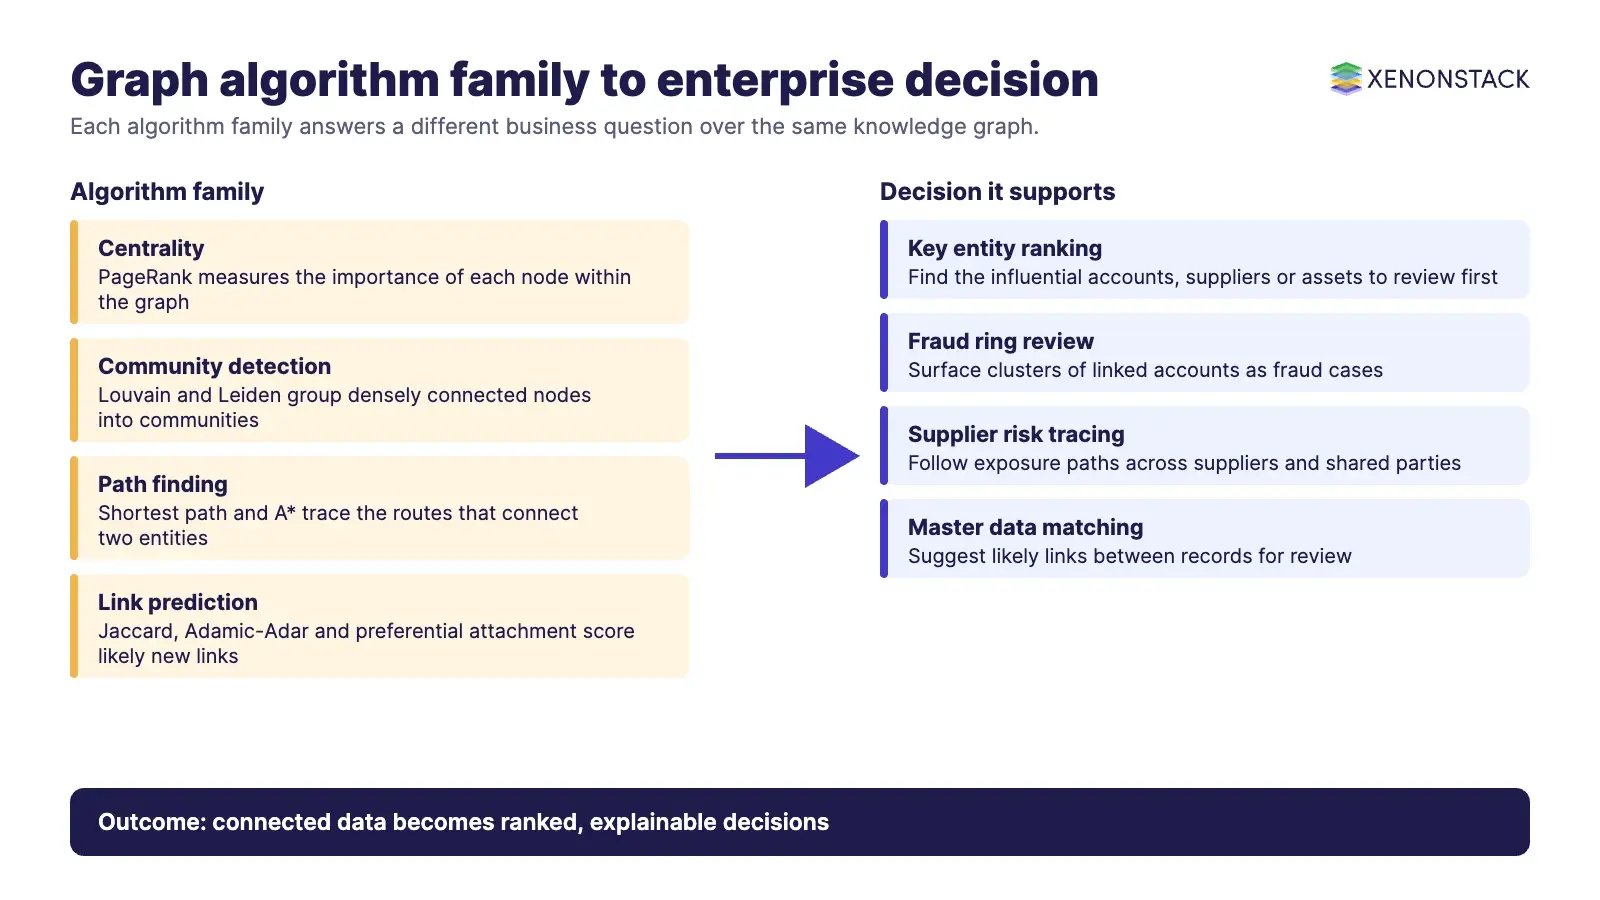
| Algorithm family | Business question it answers | Example algorithms | Where it is used |
|---|---|---|---|
| Centrality | Which nodes matter most to the network? | PageRank, betweenness, degree, closeness, eigenvector | Key accounts, critical suppliers, influential devices or users, single points of failure |
| Community detection | Which nodes cluster together more than chance suggests? | Louvain, Leiden, label propagation | Fraud rings, customer segments, collusion, duplicate entity clusters |
| Path finding | What is the shortest, cheapest or riskiest route between two nodes? | Dijkstra, A*, all-pairs shortest path | Logistics routing, impact analysis, tracing exposure to a sanctioned party |
| Similarity and link prediction | Which nodes look alike, and which links are likely to exist? | Jaccard, Adamic-Adar, preferential attachment | Recommendations, entity resolution, next-best-action |
Two details are worth knowing. PageRank, as Neo4j documents it, "measures the importance of each node within the graph", so a node scores higher when important nodes point to it, not just when many do. Leiden "modifies the Louvain algorithm to address some of its shortcomings", because Louvain can return communities that are not well connected internally. For pattern-heavy tasks, graph features or embeddings can also feed machine learning models, including graph convolutional neural networks that learn directly from graph structure. Our overview of graph analytics tools and techniques covers the tooling in more detail.
How does a knowledge graph work?
A knowledge graph combines three things: a data model for nodes and relationships, an ontology that gives those nodes and relationships agreed meaning, and a query layer that applications and analysts use. Google popularised the term in May 2012, describing its Knowledge Graph as a model that "understands real-world entities and their relationships to one another: things, not strings", and stating that it held more than 500 million objects and more than 3.5 billion facts at launch.
Which data models are used: RDF or property graphs?
The W3C RDF 1.1 Recommendation (February 2014) defines an RDF triple as a subject, a predicate and an object, and "an RDF graph is a set of RDF triples". RDF suits open, standards-based integration and reasoning with ontologies. Property graphs instead store key-value properties directly on nodes and relationships, which many engineering teams find easier for operational applications and analytics. RDF 1.2 narrows the gap: its Concepts document, a W3C Candidate Recommendation Snapshot dated 7 April 2026, adds the ability to use a triple as a "triple term" so that statements can be made about other statements, similar to properties on a relationship.
What role does the ontology play?
The ontology defines entity types (Customer, Supplier, Product), allowed relationships and rules. When two systems use different labels for the same thing, for example "Top Account" in one CRM and "Prospect" in another, the ontology can declare both as types of Company so that inference and queries treat them consistently. This is what turns a graph of data into a graph of shared business knowledge. When AI agents act on that shared knowledge, ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above those agents.
Which query languages are used: SPARQL, Cypher or GQL?
SPARQL 1.1 (W3C Recommendation, March 2013) defines "the syntax and semantics of the SPARQL query language for RDF". For property graphs, ISO/IEC 39075:2024, known as GQL, was published by ISO in April 2024. According to ISO, it "defines data structures and basic operations on property graphs" and provides capabilities for "creating, accessing, querying, maintaining, and controlling property graphs". Neo4j states that "GQL has adopted much of Cypher's query construction semantics" and that Cypher now covers most mandatory GQL features. ISO lists a 2026 corrigendum and shows the standard at stage 90.92 (to be revised), so expect further updates.
What has changed in graph analytics and knowledge graphs since 2023?
| Change | Current status | What it means for enterprises |
|---|---|---|
| ISO GQL standard | ISO/IEC 39075:2024 published April 2024 (edition 1, 610 pages); 2026 corrigendum; marked for revision | A vendor-neutral query language for property graphs reduces lock-in; check each vendor's conformance notes |
| RDF 1.2 | Concepts document is a W3C Candidate Recommendation Snapshot (7 April 2026) | Statements about statements become a standard feature, easing provenance and confidence modelling |
| GraphRAG | Microsoft Research paper first submitted April 2024, revised February 2025; open-source repository described as a demonstration | Knowledge graphs become a grounding layer for generative AI, not only for analytics |
| Library maturity | NetworkX documentation at version 3.7; Neo4j GDS documents Leiden alongside Louvain | Better community detection and a wider choice of open and commercial tooling |
How does GraphRAG use a knowledge graph?
GraphRAG was introduced in the Microsoft Research paper "From Local to Global: A Graph RAG Approach to Query-Focused Summarization" (Edge et al., arXiv 2404.16130). The authors note that conventional retrieval-augmented generation "fails on global questions directed at an entire text corpus". GraphRAG uses a large language model to "derive an entity knowledge graph from the source documents", then to "pregenerate community summaries for all groups of closely related entities". Each community summary produces a partial answer, and these are combined into a final response. On datasets of around one million tokens, the paper reports substantial improvements over a conventional RAG baseline in the comprehensiveness and diversity of answers.
The Microsoft GraphRAG documentation describes four query modes: Global Search for whole-corpus questions using community summaries, Local Search for questions about specific entities, DRIFT Search, which adds community context to local search, and Basic Search using standard top-k vector retrieval. Two cautions from the project itself matter for budgeting: its README says "GraphRAG indexing can be an expensive operation" and that the code "serves as a demonstration and is not an officially supported Microsoft offering". Treat it as a pattern to evaluate, not a finished product. For enterprise AI search and retrieval across your own documents and data, see AgentSearch.
What are the main graph analytics and knowledge graph use cases?
| Use case | Graph technique | When it fits | What to watch |
|---|---|---|---|
| Fraud and financial crime | Community detection, centrality, shared-attribute links | Fraud rings that share devices, addresses, accounts or beneficiaries | Explainability for investigators and regulators; false positives from common shared attributes |
| Sanctions and beneficial ownership | Path finding across ownership and control chains | Screening customers and counterparties for indirect links to listed parties | Data quality of corporate registries; refresh frequency of lists |
| Supply chain risk | Centrality, path finding, impact analysis | Multi-tier supplier networks where one failure cascades | Visibility beyond tier one suppliers is often incomplete |
| Master data and entity resolution | Similarity, community detection, ontology alignment | The same customer, product or supplier appears in many systems under different identifiers | Agreed match rules and data stewardship ownership |
| IT operations and data lineage | Path finding and dependency analysis | Root cause and change impact across applications, infrastructure and data pipelines | Keeping the dependency graph current as systems change |
| Recommendations and search | Similarity, link prediction, knowledge graph entities | Products, content or experts linked by behaviour and attributes | Cold-start items and popularity bias |
| Generative AI grounding | Knowledge graph plus GraphRAG-style retrieval | Questions that span many documents or need entity relationships, not just similar passages | Indexing cost, extraction errors and access control on the graph |
Fraud is the most common starting point. Our credit card fraud detection use case shows the machine learning side, and visual link analysis with graph databases shows how investigators explore the resulting networks. Investigative journalism offers a public example of relationship-centric analysis at scale: the ICIJ's Panama Papers investigation, published in April 2016, drew on more than 11.5 million financial and legal records to trace offshore ownership.
Knowledge graph vs graph database: which do you need?
You need a graph database when the main problem is querying connected data quickly and flexibly. You need a knowledge graph when the main problem is meaning: many systems, conflicting definitions and a need for people and AI to share one vocabulary. Most enterprise knowledge graphs run on a graph database, but a graph database without an ontology is not a knowledge graph. If your questions are mostly aggregations over a stable schema, a relational warehouse remains the simpler choice. Where business users mainly need answers from enterprise data, AgentAnalyst lets teams ask questions in plain language and get real-time insights.
What governance, security and cost questions should leaders ask?
Ownership: who owns the ontology, and how are changes to entity types and relationships approved?
Access control: graphs make it easy to infer sensitive links, so permissions must apply to relationships and properties, not only to nodes. This is critical when a graph feeds a generative AI assistant.
Provenance: record where each fact came from and how confident you are. RDF 1.2 triple terms and relationship properties in property graphs both support this.
Cost: graph algorithms over large graphs can be memory-intensive, and LLM-based extraction for GraphRAG adds model costs at indexing time. Pilot on a bounded subgraph first.
Portability: prefer standards (RDF, SPARQL, GQL) and document any vendor-specific extensions you rely on.
What adoption sequence works?
Pick one decision that depends on relationships, such as fraud ring detection or supplier impact analysis, and agree how success will be measured.
Model a minimal ontology covering only the entities and relationships that decision needs.
Load and resolve entities from two or three source systems, with lineage back to each source.
Run one or two algorithm families and validate the results with domain experts before automating.
Integrate the outputs into the workflow where the decision is made: case management, planning or an AI assistant.
Expand the graph to new domains only once governance, access control and refresh processes are working.
When should you not use graph analytics or a knowledge graph?
Graphs add modelling and operational effort. They are a poor fit when relationships are shallow and stable, when questions are mostly sums and averages over large tables, or when there is no team to own the ontology. A knowledge graph without stewardship goes stale and loses trust. GraphRAG is not needed when questions are answered well by a few retrieved passages; Microsoft's own documentation keeps a Basic Search mode for exactly those cases.
What are examples of public knowledge graphs?
Google Knowledge Graph: announced in 2012 to improve search with entities and relationships.
DBpedia: a community project that extracts structured content from Wikipedia into a reusable knowledge graph, often used to bootstrap internal graphs.
WordNet: a lexical database of English words and their relationships, used in search and natural language processing.
GeoNames: a geographical database of place names and features, useful for location entities.
To map one relationship-heavy decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Related on XenonStack
- ElixirData: governed context for enterprise AI agents.
- RAG and LLM development services: grounded answers that cite their sources.
- OpenMetadata platform guide: metadata as context for agents.
Frequently asked questions
What is graph analytics in simple terms?
It is the analysis of connections. Algorithms such as PageRank, Louvain, Leiden and Dijkstra find important nodes, natural groups and best paths in a network of entities and relationships.
Is a knowledge graph the same as a graph database?
No. A graph database is the storage and query engine. A knowledge graph adds an ontology that gives the data shared business meaning, and it usually runs on a graph database.
What is GQL?
GQL is ISO/IEC 39075:2024, the ISO standard query language for property graphs, published in April 2024. Neo4j states that it adopted much of Cypher's query construction semantics.
How is GraphRAG different from standard RAG?
Standard RAG retrieves similar passages. GraphRAG builds an entity knowledge graph and community summaries from the source documents, which the Microsoft Research paper shows helps with global questions about a whole corpus.
What are the most common knowledge graph use cases?
Fraud and financial crime, sanctions and ownership screening, supply chain risk, master data and entity resolution, IT dependency and lineage analysis, recommendations, and grounding generative AI.
What should enterprise leaders do next?
Start with one relationship-heavy decision, model only what it needs, and use standard languages where you can. Graph analytics gives you the scores, groups and paths; the knowledge graph makes them trustworthy and reusable across teams and AI systems. Treat GraphRAG as an evaluated pattern with a clear budget for indexing, and put ontology ownership and relationship-level access control in place before the graph grows. For real-time monitoring of graph outputs, see our guide to real-time streaming data visualisation.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE