Key takeaway
- Distributed deep learning explained: data, model and sharded parallelism, PyTorch and TensorFlow approaches, costs, and how AI agents fit in.
Distributed deep learning is the practice of training one neural network across several processors or machines at the same time, by splitting the data, the model, or both. It shortens training for large datasets and makes models trainable that do not fit in a single device's memory.
This guide is for ML engineers, data scientists and platform leads deciding how to scale training. It covers why teams distribute training, the main parallelism strategies, how PyTorch and TensorFlow implement them, what it costs, and how AI agents change the surrounding workflow. For the wider lifecycle, see the machine learning pipeline and MLOps platform guides.
Why do teams distribute deep learning training?
Two limits push teams past a single device. Training on a large dataset can take too long on one machine, and a large model can exceed the memory of one accelerator. Spreading the work over more devices addresses the first by processing more data per step, and the second by dividing the model's state. It also lets teams add machines as workloads grow, though the coordination adds complexity and cost, covered below.
What are data, model and sharded parallelism?
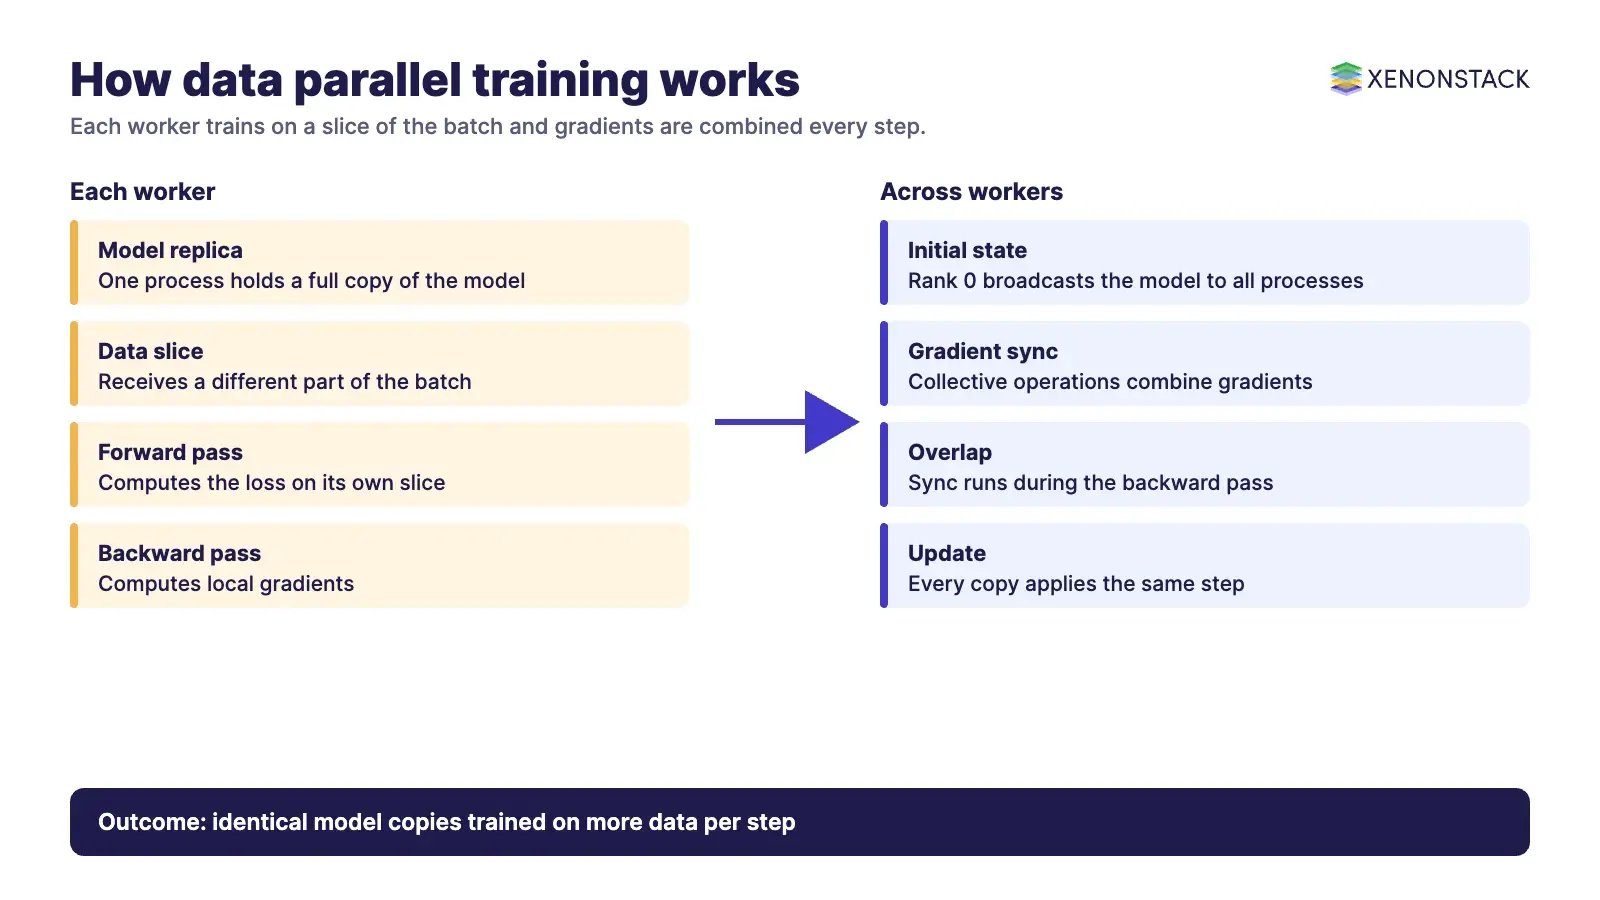
Data parallelism keeps a full copy of the model on each worker and gives each a different slice of every batch. Gradients are then combined so all copies stay identical. Model parallelism places different parts of the model on different devices, which helps when the parameters do not fit in one device. The PyTorch DDP tutorial notes that its DistributedDataParallel can be combined with model parallelism: each process uses model parallelism internally and all processes together use data parallelism.
Sharded data parallelism sits between the two. In the PyTorch FSDP tutorial, each GPU stores only a slice of the parameters, gradients and optimiser state, and gathers a layer's full parameters just before that layer runs. The tutorial describes it as a decomposition of the DDP all-reduce into reduce-scatter and all-gather operations. Note that it documents the newer fully_shard API and states that the earlier FSDP1 is deprecated, so older guides may describe an API that has been superseded.
| Approach | What is split | Memory per device | Typical use |
|---|---|---|---|
| Data parallel | The batch; each worker holds a full model | Full model on every device | Model fits on one device, data is large |
| Model parallel | Layers or tensors across devices | Part of the model | Model too large for one device |
| Sharded data parallel | Parameters, gradients and optimiser state | A slice of each | Large models that still train data-parallel |
How do synchronous and asynchronous updates differ?
The TensorFlow distributed training guide describes the two common ways to distribute data-parallel training. In synchronous training, all workers train on different slices of the input and aggregate gradients at each step. In asynchronous training, workers train independently and update variables asynchronously. The guide adds that synchronous training is typically supported through all-reduce and asynchronous training through a parameter server architecture.
Synchronous updates keep every copy consistent but wait for the slowest worker. Asynchronous updates avoid that wait at the cost of stale parameters, which can affect convergence. The same TensorFlow guide lists strategies for each setting, including MirroredStrategy for multiple GPUs on one machine, MultiWorkerMirroredStrategy for synchronous training across workers, and ParameterServerStrategy for parameter server training.
How does PyTorch implement data parallel training?
According to the PyTorch DDP tutorial, the recommended pattern is one process per model replica. DDP uses collective communications from the torch.distributed package to synchronise gradients and buffers, registers an autograd hook for each parameter, and overlaps gradient synchronisation with the backward pass. Rank 0 broadcasts its model state when DDP is constructed so every process starts identical. The tutorial also states that DataParallel works only on a single machine and is usually slower than DDP, so DDP is the route for multi-machine work.
What are the costs and trade-offs?
| Trade-off | What to plan for |
|---|---|
| Communication | Gradient or parameter exchange between devices can become the bottleneck as workers are added |
| Complexity | Process launch, failure handling and debugging across many machines need distributed-systems skill |
| Cost | Clusters and fast interconnects are expensive to build; cloud capacity trades capital cost for running cost |
| Reproducibility | Different worker counts and update modes can change training behaviour, so record the configuration |
Distribution is not a free speed-up. Measure single-device throughput first, and add workers only when the profile shows the device, not the input pipeline, is the limit. Related guides cover machine learning model training and testing, MLOps tools, natural language processing, auto indexing with machine learning and machine learning in security. For delivery support, see XenonStack's machine learning development services.
How do AI agents change distributed training?
Training jobs generate a lot of operational decisions: which configuration to launch, when to restart a failed worker, when to stop a run that is not converging, and which checkpoint to promote. AI agents can watch metrics and logs, propose or apply those actions within set limits, and record why. Human review should remain for decisions that spend significant budget or change what reaches production.
An agent needs the same controls as an engineer: scoped credentials, budget limits and an audit trail. XenonStack's ElixirClaw is the AI agents computing platform for building and running such agents; keep the agent's authority narrow and explicit.
What should you do first?
- Profile one training run on a single device and find the real bottleneck.
- Pick the simplest strategy that fits: data parallel first, sharding only if memory forces it.
- Run a small multi-device test and compare throughput and results against the single-device baseline.
- Add checkpointing, failure handling and logging before scaling out.
- Record configurations so runs can be reproduced and reviewed.
To map one decision your agents make, and the data and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is distributed deep learning?
It is training one neural network across several processors or machines at once by splitting the data, the model, or both.
What is the difference between data and model parallelism?
Data parallelism copies the whole model to each worker and splits the batch. Model parallelism splits the model itself across devices.
When should I use synchronous instead of asynchronous training?
Synchronous training keeps every copy consistent and is typically done with all-reduce. Asynchronous training avoids waiting for slow workers, typically through a parameter server, but can affect convergence.
Is FSDP1 still recommended in PyTorch?
The current PyTorch FSDP tutorial documents the newer fully_shard API and states that FSDP1 is deprecated.
Does distributing training always make it faster?
No. Communication, input pipelines and coordination can limit gains, so profile a single device first and compare results as you add workers.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE