Key takeaway
- Amazon Kendra is in maintenance mode and closed to new customers. See how an S3 index works, the cost and governance points, and when to move to Bedrock.
Amazon Kendra is a managed intelligent search service, but it is no longer a safe default for a new build. AWS states that it put Kendra into maintenance mode from 30 June 2026 and that the service is no longer open to new customers from 30 July 2026. Existing customers keep bug fixes and security updates, and AWS recommends Amazon Bedrock Managed Knowledge Base for new search applications (AWS availability change notice, checked on 12 November 2026).
This guide is for teams that already run, or inherit, a Kendra index. It explains what Kendra does, how an S3-based implementation is put together, what the governance and cost points are, and how to decide between staying and moving. For the product overview see Amazon Kendra benefits for businesses, and for retrieval with agents see Amazon Kendra with AI agents.
What is the status of Amazon Kendra in 2026?
We read the AWS documentation on 12 November 2026 for service changes, retirement notes and any mention of the GenAI Index. The table records what AWS actually says.
| Question | What the AWS documentation says | Source |
|---|---|---|
| Is Kendra still supported? | Yes. The service remains fully supported, with bug fixes and security updates for existing customers. New feature requests are no longer considered. | Availability change |
| Can new customers start? | No. The overview gives 30 July 2026 as the date from which the service is no longer open to new customers, and the page banner says the same without a date. | Availability change |
| Is there a retirement date? | No end-of-support date is given on the availability page. | Availability change |
| What does AWS recommend instead? | Amazon Bedrock Managed Knowledge Base, with a Retrieve and Generate API and an Agentic Retrieval API. The banner also points to Amazon Bedrock Knowledge Bases. | Availability change |
| What about the GenAI Index? | The availability page does not mention it. The Kendra overview still lists GenAI Enterprise Edition as an index type, described as suited to retrieval augmented generation (RAG) and usable with Amazon Q Business and Amazon Bedrock knowledge bases. | What is Kendra |
| What about Amazon Q Business? | Its documentation says it is also no longer open to new customers and points to Amazon Quick for similar capabilities. | Q Business overview |
The banner and the overview on the availability page are worded differently, so confirm the position for your own account with AWS Support before you commit budget either way.
What does Amazon Kendra do and which questions can it answer?
Amazon Kendra is a managed information retrieval service that uses natural language processing and deep learning to judge whether a passage or document is relevant to a query, instead of matching keywords alone. AWS lists three query types it supports: factoid questions (who, what, when, where), descriptive questions that need a passage or longer answer, and keyword or natural language queries where it infers the intended meaning. Factoid answers can come from a FAQ or from indexed documents.
Which Kendra index types exist?
| Index type | What AWS says | When it fits |
|---|---|---|
| GenAI Enterprise Edition | Highest accuracy, high availability, built for production | Production RAG and enterprise search on an existing estate |
| Basic Enterprise Edition | Semantic search with high availability, suitable for production | Production search without generative AI needs |
| Basic Developer Edition | Semantic search for proof of concept, not recommended for production | Testing only |
Source: AWS, What is Amazon Kendra. AWS also notes that search results can reflect your organisation's security model and be filtered by user or group access.
How does an Amazon Kendra implementation work?
A Kendra implementation has four parts: documents held in a source repository, a data source connector that syncs them, an index that serves search, and a client application that calls the search API. For many teams the source is an Amazon S3 bucket.
What do you need before you start?
- An AWS account with permission to create the resources you need.
- An Amazon S3 bucket in the same region as the index, holding the documents or FAQ content.
- An IAM role the connector uses to read the bucket. AWS says the console can create it, and that a role used for an index cannot be reused for a data source.
- A decision on access control: supply an access control list file in JSON if users should see only the documents they are allowed to open.
Source: AWS, Amazon S3 data source connector.
What is the setup sequence?
- Create the bucket and upload the documents.
- Create the index and choose the index type. Use a developer index only for testing.
- Add an S3 data source, point it at the bucket, attach the IAM role and set the sync schedule.
- Run the first sync. The first sync crawls everything.
- Optionally add FAQ content, then test queries in the search console.
- Call the search API from your website, chatbot or agent-assist tool.
Console labels change between releases, so follow the current AWS guide for each click. Two connector details matter in practice: the S3 connector supports full syncs and syncs of new, modified and deleted files only, and AWS sets a 50 MB file size limit for the connector. Metadata can sit in a separate metadata folder, one file per document, and is mapped to index fields.
Should you stay on Kendra or move to a Bedrock knowledge base?
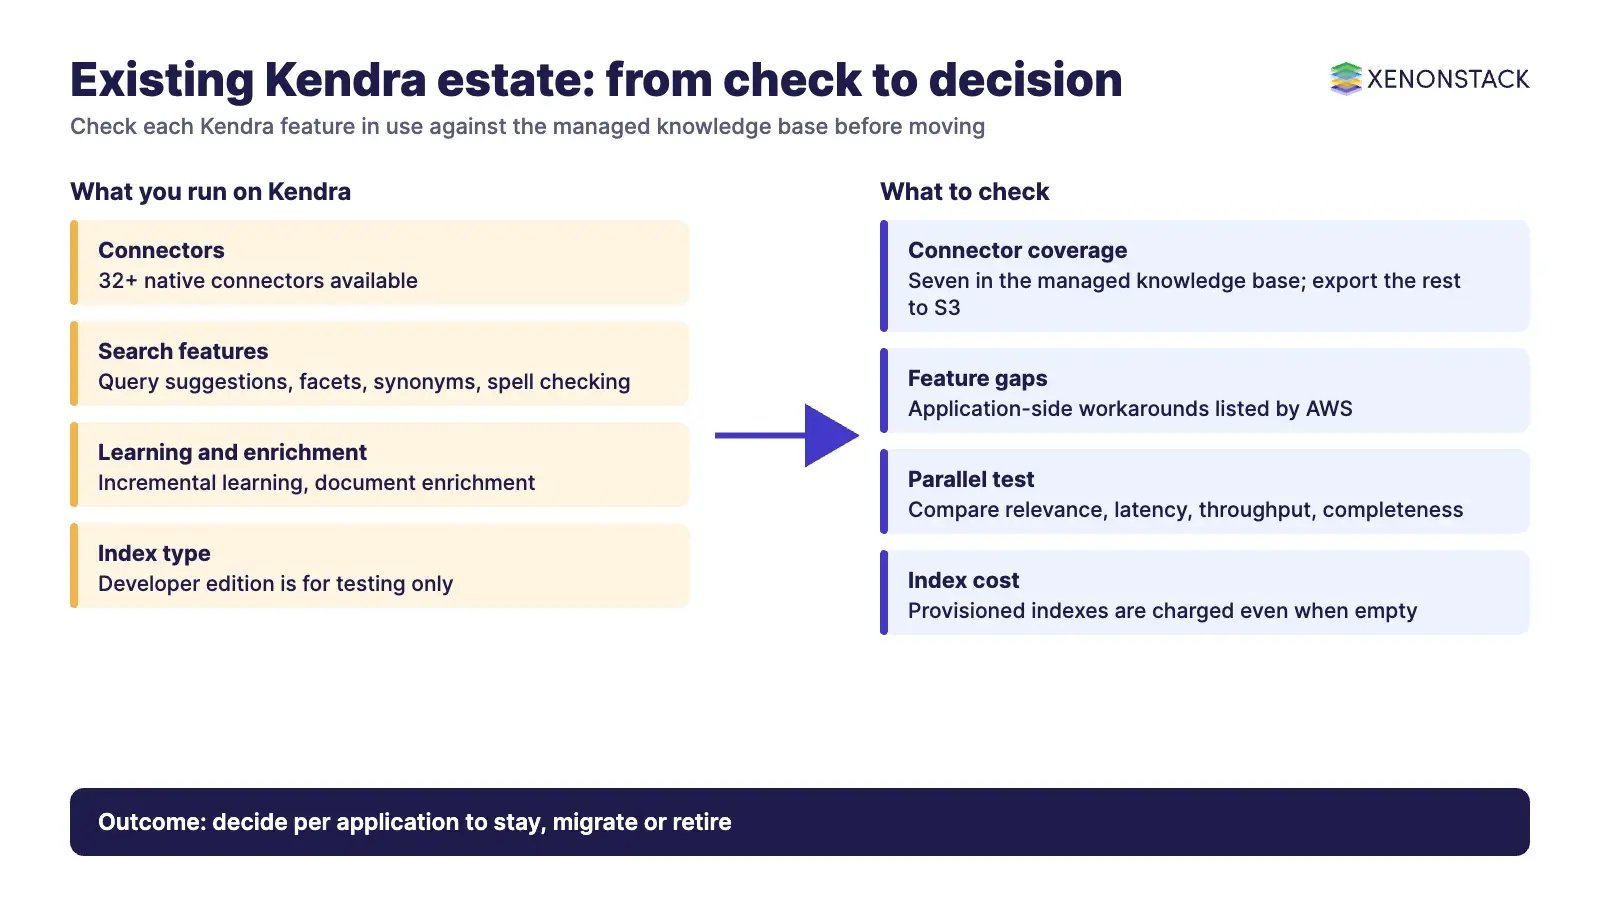
AWS publishes a migration guide on the availability page. It says to run Kendra and the managed knowledge base in parallel and compare relevance (NDCG or MRR), latency, throughput and completeness. The table lists differences it names.
| Area | Kendra | Bedrock Managed Knowledge Base |
|---|---|---|
| Connectors | 32+ native connectors | 7: Amazon S3, Confluence, Microsoft SharePoint, Web Crawler, Google Drive, Microsoft OneDrive and a custom connector |
| Search mode | Semantic search available | Always hybrid (keyword plus semantic); no semantic-only mode |
| Chunking | Not specified in the AWS guide | No semantic chunking; AWS suggests fixed-size, 200 tokens, 30% overlap as a start |
| Query suggestions, faceted search, custom synonyms, spell checking | Built in | No direct equivalent; AWS lists application-side workarounds |
| Incremental learning, document enrichment | Built in | No direct equivalent; AWS suggests external feedback signals and a Lambda or Step Functions pipeline |
Source: AWS availability change and migration guide. A simple rule: stay on Kendra while an existing index meets its relevance targets and relies on features with no direct equivalent, and plan the move for any workload that depends on connectors outside the seven above or that you are about to extend.
What are the governance, security and cost points?
- Access: results can be filtered by user or group, but customers are responsible for authenticating and authorising users.
- Cost: after the free trial (up to 750 hours in the first 30 days on a GenAI Enterprise Edition or Developer Edition index), AWS charges for all provisioned indexes, even empty ones with no queries, plus data source scanning and syncing. Connector usage does not qualify for the free tier. Delete unused test indexes.
- Evidence: keep a record of which documents each connector syncs and who can see them, so an answer can be traced back to its source.
Source: AWS, What is Amazon Kendra. For agents that act on retrieved content, govern the retrieval layer as well as the model. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents, and AgentSearch offers context-aware enterprise search across unstructured knowledge bases. See also our guide to AI agents and our knowledge graph services.
What are the trade-offs, and when should you not use Kendra?
- Do not choose Kendra for a new programme, because new customers can no longer sign up.
- Do not leave a developer index running as a production service, because AWS does not recommend it.
- Do not assume a move is a lift and shift: connectors, filters and metadata rules differ, as the table above shows.
- Do not plan around a retirement date, because AWS has not published one. Plan around the maintenance mode position instead.
What adoption sequence is sensible for an existing Kendra estate?
- List every index, data source and the applications that call it.
- Record which Kendra-only features each application uses.
- Check connector coverage against the seven in the managed knowledge base, and plan an export to S3 for the rest, which is the pattern AWS recommends.
- Build a test set of real questions and run both services in parallel.
- Decide per application: stay, migrate, or retire.
- Document the decision and review it when AWS updates the notice.
If you run agents on top of retrieval, ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control.
To map one search or retrieval decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
What should you plan for in 2027?
Plan around the position the guide describes: Kendra is in maintenance mode, existing indexes keep working, and no retirement date has been published. These points keep an existing estate under control.
- Know what you run. List every index, data source and calling application, and record which Kendra only features each one uses.
- Decide per application. Stay, migrate or retire, based on a parallel test of real questions against the Bedrock managed knowledge base.
- Control cost and access. Delete unused test indexes, keep the record of what each connector syncs and who can see it, and review the decision whenever AWS updates its notice.
Frequently asked questions about Amazon Kendra
Is Amazon Kendra still available?
Existing customers can keep using it. AWS put Kendra into maintenance mode from 30 June 2026 and states it is no longer open to new customers from 30 July 2026. Bug fixes and security updates continue.
Has AWS announced a retirement date for Amazon Kendra?
The AWS availability page gives no end-of-support date. It describes maintenance mode, with bug fixes and security updates for existing customers.
What does AWS recommend instead of Amazon Kendra?
AWS recommends Amazon Bedrock Managed Knowledge Base for new search applications and for migrating existing Kendra applications.
What is the Amazon Kendra GenAI Index?
AWS lists GenAI Enterprise Edition as an index type with the highest accuracy, suited to retrieval augmented generation and usable with Amazon Q Business and Amazon Bedrock knowledge bases. The availability change page does not mention it.
How does Amazon Kendra connect to documents in Amazon S3?
Through the S3 data source connector. The bucket must be in the same region as the index, the connector uses an IAM role, and it supports full syncs and syncs of new, modified and deleted files.
How is Amazon Kendra priced?
After a free trial of up to 750 hours in the first 30 days on eligible indexes, AWS charges for every provisioned index, even an empty one, plus data source scanning and syncing. Connector usage does not qualify for the free tier.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE