Key takeaway
- Run ArangoDB, a multi-model database for documents, graphs and key-value data, on Kubernetes with persistent storage and the ArangoDB operator.
A multi-model database stores and queries more than one kind of data, such as documents, key-value pairs and graphs, in a single database engine. This use case shows how to run one, ArangoDB, on a Kubernetes cluster with persistent storage so it can be scaled as demand changes.
It is for platform and data engineers who want to avoid running a separate database for every data shape. It covers the problem, the cluster design, the operator-based deployment steps, where AI agents fit and what to check before you start.
What is a multi-model database?
A multi-model database supports several data models in one system. Teams can serve different application needs without deploying a separate database for each, which simplifies operations. Benefits that apply to this design include:
- ACID capabilities and security in one place.
- Simpler performance scaling.
- Strong data consistency.
- Less operational overhead than running several database systems.
ArangoDB is a multi-model database that supports key-value pairs, graph models and a document store. Its graph model represents many-to-many relationships between documents, held in edge collections that link document collections. The ArangoDB documentation refers to its data model as, rather, multiple data models.
What problem does it solve on Kubernetes?
- A multi-model database must be containerised and scaled as requirements change.
- Document, key-value and graph models must run together on Kubernetes.
- Containers are not persistent by default, so a database needs persistent storage to keep its data.
- ArangoDB itself must be scaled using Kubernetes.
How is the cluster built?
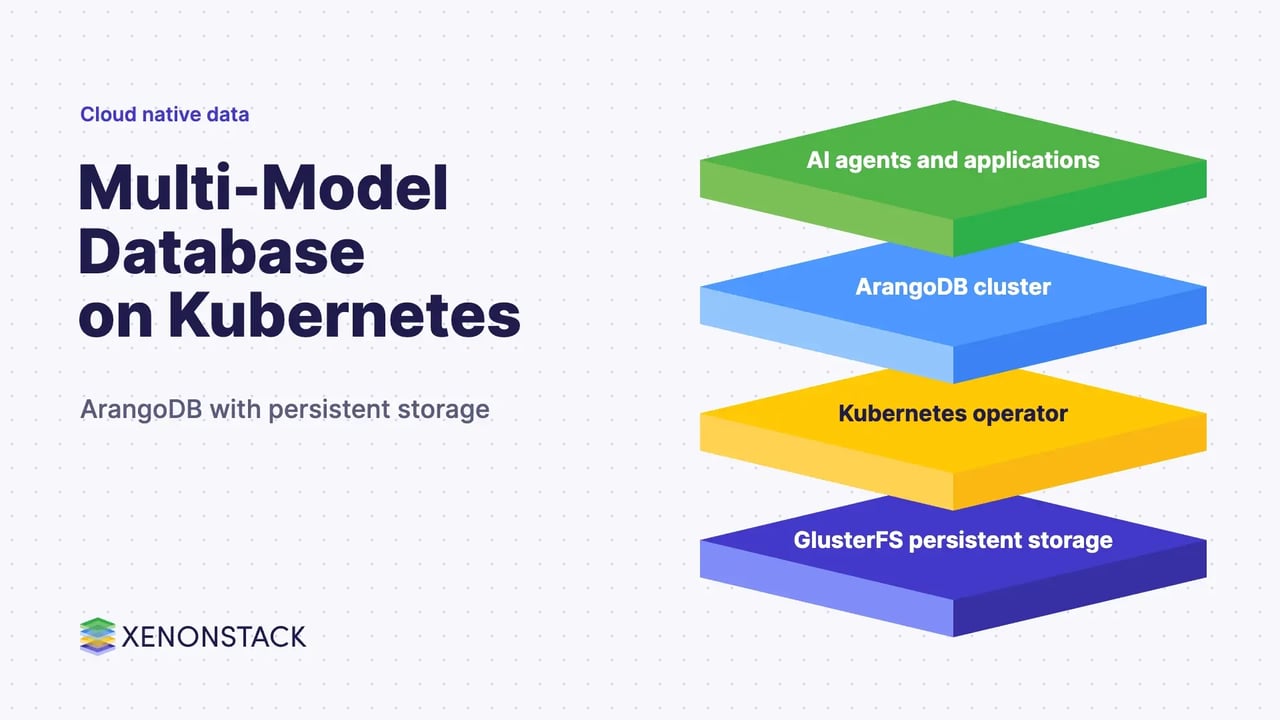
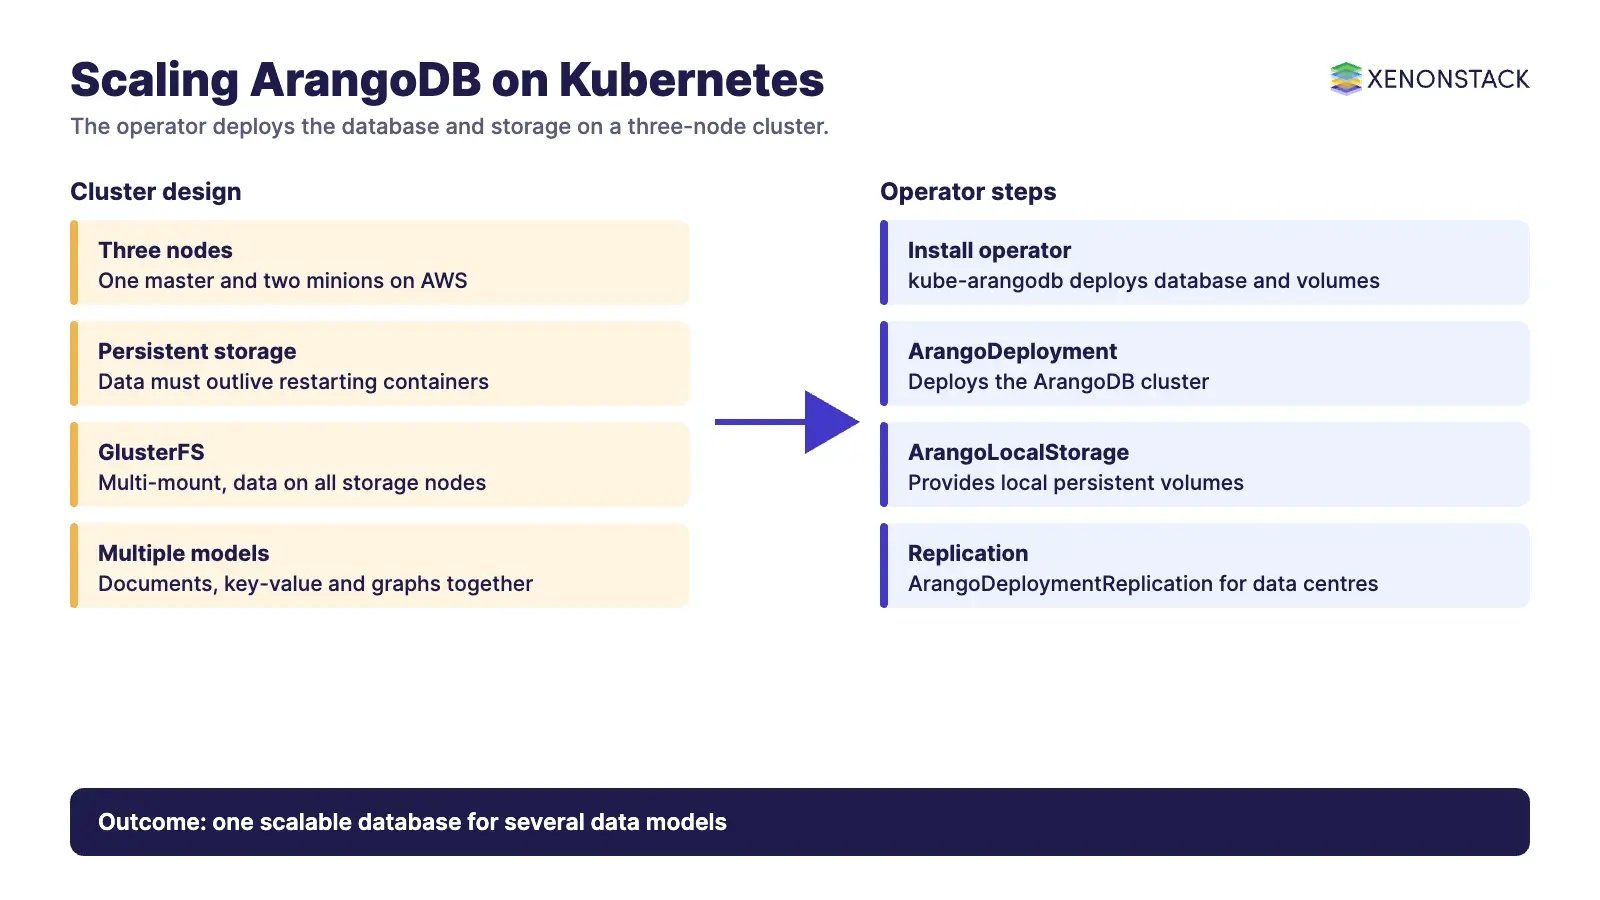
The design uses a three-node Kubernetes cluster on AWS, with one node as master and two as minions. Because containers can die and restart at any time while the data must remain, the database uses persistent storage. GlusterFS is selected as the storage solution because it supports multi-mount, so data remains available on all GlusterFS nodes.
How do you scale ArangoDB with the Kubernetes operator?
The ArangoDB Kubernetes Operator is a set of operators deployed in the cluster. It manages deployments of the database, manages backups and provides PersistentVolumes on the local storage of your nodes for storage performance. The steps are:
- Install kube-arangodb to deploy the database and local persistent volumes.
- Connect to the database.
- Deploy the ArangoDB cluster using the ArangoDeployment resource.
- Use the ArangoLocalStorage resource to provide local persistent volumes.
- Use the ArangoDeploymentReplication resource to configure data centre to data centre replication.
- To clean up, remove the deployment, which deletes all its data, and then remove the operator.
Features of ArangoDB used in this design include ArangoSearch, geo index support, a binary storage format, RocksDB as the default storage engine, load balancing support and AQL query profiling.
How do the storage options compare?
| Question | Shared storage (GlusterFS) | Local persistent volumes |
|---|---|---|
| Data availability | Multi-mount, data on all storage nodes | Tied to the node that holds the volume |
| Provided by | A storage layer you run | The operator, on node local storage |
| Fit | Pods that may restart on any node | Storage performance on each node |
| Check first | Operating the storage layer | Replication across nodes or data centres |
Where do AI agents fit?
AI agents often need documents, relationships and lookups together, for example a graph of entities beside the records that describe them. A multi-model database gives them one place to query. ElixirData is XenonStack's Context OS, the product to read for governed data and context behind agent decisions.
What should you check before you deploy?
- Decide which data models your applications really need.
- Choose the persistent storage approach before the first deployment.
- Plan backups and how a deployment is removed, since removal deletes its data.
- Test scaling and node failure on a small cluster first.
- Define who owns upgrades of the operator and the database.
To map one decision your agents make from this data, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is a multi-model database?
It is a database that supports several data models, such as documents, key-value pairs and graphs, in one engine, so teams avoid running a separate database for each.
Why does a database on Kubernetes need persistent storage?
Containers can die and restart at any time and are not persistent by default, so the data must live on storage that outlives the container.
What does the ArangoDB Kubernetes Operator do?
It manages deployments of the database, manages backups and provides PersistentVolumes on the local storage of your nodes.
Why was GlusterFS chosen in this design?
It supports multi-mount, so the data remains available on all GlusterFS nodes.
Where do AI agents fit with a multi-model database?
Agents can query documents, relationships and key-value lookups from one place, with governed data behind their decisions.
Ready to put AI agents to work? See an ElixirClaw demo: the agentic OS to build, orchestrate and govern AI agents across your enterprise systems.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE