Key takeaway
- Case study: agentic RAG and multi-agent WhatsApp engagement platform on AWS, with architecture, models, trade-offs and governance for enterprise leaders.
What did an agentic RAG engagement platform on AWS deliver for a data services company?
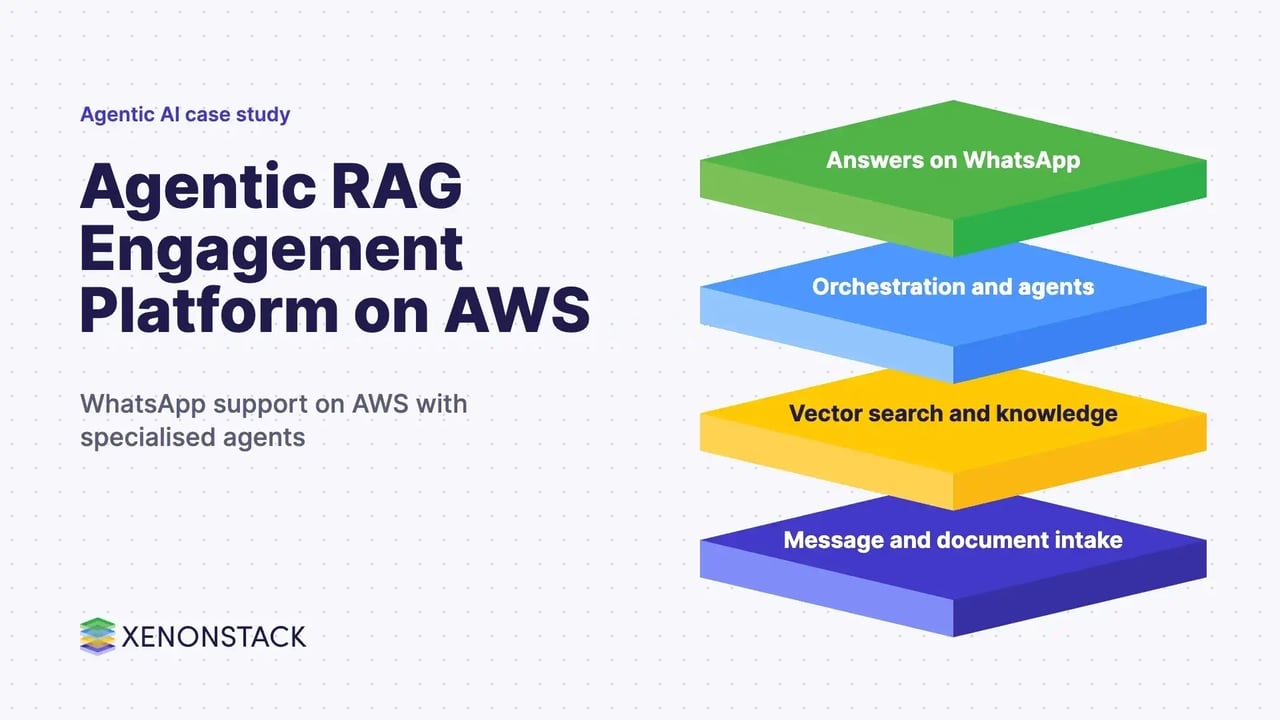
A data services company in Italy with a multi-region support team asked XenonStack to replace a ticket-based support process with a WhatsApp-first engagement platform. The result is a four-layer AWS architecture in which an orchestration agent, a knowledge agent and a response agent answer customers from the company's own documents, using retrieval augmented generation (RAG) and open-source models served through Amazon Bedrock.
This case study is for CTOs, heads of customer operations and solution architects weighing a multi-agent design against a single chatbot. It covers the problem, the architecture, the trade-offs and the governance controls. For the wider pattern, see agentic workflows and LLM-based AI agents.
What problem was the client trying to solve?
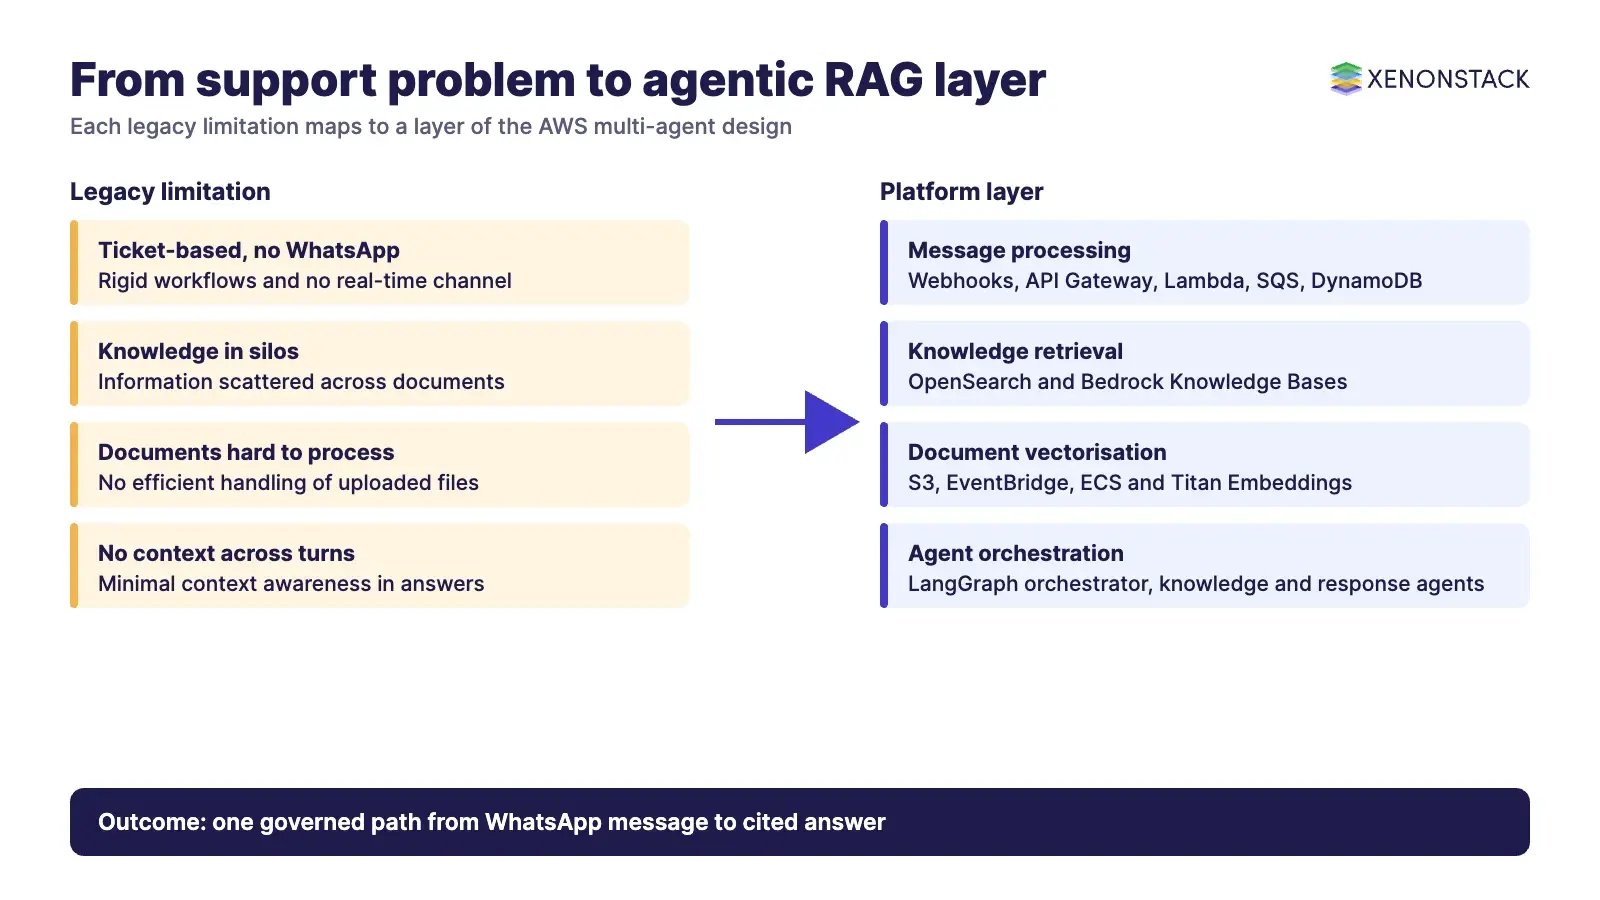
The client's support relied on a rigid ticket system. Knowledge sat in documents and departmental silos, customers could not send documents or rich media easily, and the tools could not connect to WhatsApp. Support leaders described the baseline as an average wait of 15 to 20 minutes, and set a target of responses in under 2 minutes.
| Area | Starting position | Requirement |
|---|---|---|
| Volume | Many repetitive enquiries handled by people | Automated resolution, with people kept for complex cases |
| Knowledge | Scattered across documents and departments | Central semantic retrieval |
| Channel | Ticket-based, no WhatsApp support | Real-time WhatsApp conversations |
| Compliance | Multi-region data privacy duties | Encryption, secure document handling, regional data protection |
How is the multi-agent RAG architecture built?
The platform has four layers. Each layer has one job, so a failure or change in one does not force a redesign of the others.
1. Message processing layer
Meta webhooks pass WhatsApp messages to Amazon API Gateway, which routes them to AWS Lambda. Message processor functions prepare each message, Amazon SQS queues absorb peaks, and Amazon DynamoDB keeps conversation history so context survives across turns. According to Meta's documentation, a webhook endpoint must use HTTPS with a valid certificate, and if it does not return a 200 status, delivery is retried for up to seven days, which can create duplicate notifications. Design the message processor to be idempotent for that reason.
2. Document processing and vectorisation layer
Customer documents land in Amazon S3, with metadata in DynamoDB. Amazon EventBridge triggers Amazon ECS jobs that extract content and create embeddings with Amazon Titan Embeddings, and the vectors are indexed in Amazon OpenSearch Service. According to the AWS documentation, Titan Text Embeddings V2 accepts up to 8,192 tokens, returns 1,024 dimensions by default (512 and 256 are also available) and is recommended for retrieval use cases such as RAG; AWS also advises splitting documents into logical units such as paragraphs or sections.
3. Agent orchestration layer
An orchestration agent built in LangGraph controls the conversation and hands work to specialists. A knowledge agent (DeepSeek-R1) retrieves and synthesises information from the vector store. A response agent (Llama 3.3) writes the reply for the customer's profile. A prompt library holds prompts for each scenario. According to the LangGraph documentation, it is a low-level runtime for long-running, stateful agents, with durable execution, human-in-the-loop pauses and memory. Amazon EKS hosts the containerised agents that Lambda calls. For a broader orchestration option, see orchestrating multi-agent systems with AWS Step Functions.
4. Knowledge storage and retrieval layer
OpenSearch provides vector search and Amazon Bedrock Knowledge Bases holds structured information for common questions. According to AWS, Bedrock Knowledge Bases is a managed RAG capability whose responses can include citations pointing to the original source. The Meta callback API returns the answer to the customer on WhatsApp. Teams that need enterprise-wide retrieval with access rules can compare this design with AgentSearch, which ElixirData describes as finding information in unstructured company documents and knowledge bases while respecting access rules.
Which AWS services did the solution use, and why?
| Service | Role in the platform |
|---|---|
| Amazon API Gateway | Receives WhatsApp webhooks, protected by AWS WAF |
| AWS Lambda | Processes messages and starts agent workflows |
| Amazon SQS | Queues messages during high traffic |
| Amazon DynamoDB | Conversation history and document metadata |
| Amazon S3 | Stores uploaded documents |
| Amazon EventBridge | Detects uploads and triggers processing |
| Amazon ECS | Runs extraction and embedding jobs |
| Amazon EKS | Hosts the containerised agents |
| Amazon OpenSearch Service | Vector search for semantic matching |
| Amazon Bedrock Knowledge Bases | Structured information for common queries |
| Amazon Titan Embeddings | Turns extracted text into vectors |
How was the platform delivered and migrated?
XenonStack began with stakeholder workshops to identify the main conversation flows and knowledge needs, then worked in agile sprints with GitOps deployment pipelines and AWS CDK for infrastructure as code. Integration and load testing used automated suites, with monitoring in Amazon CloudWatch.
The legacy ticket system was replaced in phases: first knowledge vectorisation, then agent development, then WhatsApp integration. This kept support running while the new path was proven.
Why split the work across specialised agents?
The design assigns each model a job instead of asking one model to do everything. DeepSeek-R1 handles reasoning-heavy retrieval and synthesis; Llama 3.3 handles orchestration and response writing. This also lets a team swap one agent, for example after a model release, without rebuilding retrieval.
| Option | When it fits | Trade-off |
|---|---|---|
| Single chatbot with one model | Narrow, low-risk question set | One prompt and model carry every task, so tuning one behaviour can affect another |
| Multi-agent RAG (this design) | Several knowledge sources, uploaded documents, multi-turn conversations | More components, handoffs and monitoring to run |
| Human-only queue | Sensitive or complex cases | Does not scale for repetitive enquiries |
The choice of models needs a lifecycle check. According to the Amazon Bedrock documentation, models move through Active, Legacy and End-of-Life states, and the model card shows the dates. Confirm the availability and status of DeepSeek-R1 and Llama 3.3 in your Region on the model card before you commit.
What went wrong early, and how was it fixed?
| Challenge | Response |
|---|---|
| Multi-turn conversations were hard to keep consistent across agent handoffs | Better conversation state in DynamoDB and tighter context window management in the orchestration agent |
| Document processing latency during first uploads | Asynchronous processing with customer notifications |
| Occasional hallucination | Improved embeddings and a "citations required" rule for the knowledge agent |
| Uneven quality across languages | Language-specific embeddings and language detection |
How are governance, security and cost controlled?
The platform used end-to-end encryption, secure document handling, access controls and monitoring at each layer, and regional data protection requirements shaped the design. Serverless components (Lambda, SQS, API Gateway) were chosen for scalability and cost efficiency, and open-source models were used to manage model cost. The team mapped the work to the AWS Well-Architected pillars of operational excellence, reliability, performance efficiency and cost optimisation.
For agents that act on customer data, add decision traces and policy checks above the model layer. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents. See also agentic AI in governance and compliance.
What is the adoption sequence and what comes next?
- Vectorise the existing knowledge base and test retrieval with citations.
- Build the orchestration and knowledge agents and test conversation flows.
- Add the response agent and prompt library with version control.
- Connect WhatsApp through the Business API and release in stages.
The roadmap includes specialised agents for technical support and billing, predictive support based on usage patterns, more messaging platforms, Amazon Kendra for enterprise search, fine-tuning of the open-source models, richer agent collaboration, and regular evaluation of new open-source releases. A related AWS pattern is described in customer engagement with contact center AI on AWS.
To map one customer-facing decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
FAQ
What is agentic RAG?
It is retrieval augmented generation in which specialised agents decide what to retrieve and how to answer, instead of one model following a fixed prompt. In this case an orchestration agent coordinates a knowledge agent and a response agent.
Which models did the platform use?
DeepSeek-R1 for knowledge retrieval and synthesis, and Llama 3.3 for orchestration and response generation, with Titan Embeddings for vectors. Confirm current availability on the Amazon Bedrock model card.
How did the platform keep context across a conversation?
Conversation history is stored in DynamoDB and the orchestration agent manages the context window across handoffs.
How were hallucinations reduced?
By improving embeddings and requiring the knowledge agent to cite its sources.
How were uploaded documents handled?
Files go to Amazon S3, EventBridge triggers ECS jobs that extract and embed the content, and OpenSearch indexes the vectors. Customers are notified while processing runs asynchronously.
Ready to put AI agents to work? See an ElixirClaw demo: the agentic OS to build, orchestrate and govern AI agents across your enterprise systems.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE