Key takeaway
- Learn what chaos engineering is, its five principles, how to run a safe experiment, which tools to use and how AI agents change resilience testing.
Chaos engineering is the discipline of experimenting on a distributed system to build confidence that it can withstand turbulent conditions in production. Instead of waiting for a disk to fill or a dependency to time out, a team injects that failure on purpose, in a controlled way, and watches whether the system keeps behaving as expected.
This guide is for platform, DevOps and reliability engineers who run microservices or other distributed systems and want a safe way to start. It covers the principles, how one experiment works, what to break first, how tools fit in and how AI agents change the practice.
What is chaos engineering and why does it matter?
In a microservice system each service can be tested and look healthy, yet an unusual combination of timeouts, retries and traffic can still cause an outage. No single person can predict every interaction, so the practice treats resilience as something to be measured by experiment rather than assumed from design. It is a close partner of Site Reliability Engineering and of Network Reliability Engineering, which both aim to keep services dependable as they scale.
The aim is not to cause damage. It is to find weaknesses such as missing fallbacks, badly tuned timeouts or hidden single points of failure while the impact is small and a team is watching, rather than during a real incident.
What are the principles of chaos engineering?
The Principles of Chaos Engineering describe five advanced principles. The table summarises each one.
| Principle | What it means in practice |
|---|---|
| Build a hypothesis around steady state | Measure outputs such as throughput, error rates and latency percentiles, not internal implementation details. |
| Vary real-world events | Inject events that mirror reality, such as hardware failures, malformed responses or traffic spikes, prioritised by impact or frequency. |
| Run experiments in production | Real production traffic is the reliable way to capture actual request paths. |
| Automate experiments to run continuously | Manual experimentation does not scale, so automate both the execution and the analysis. |
| Minimise blast radius | Contain the fallout so customers experience as little harm as possible. |
How does a chaos experiment work?
The same source lays out the shape of an experiment. Follow it in order and keep a way back at every stage.
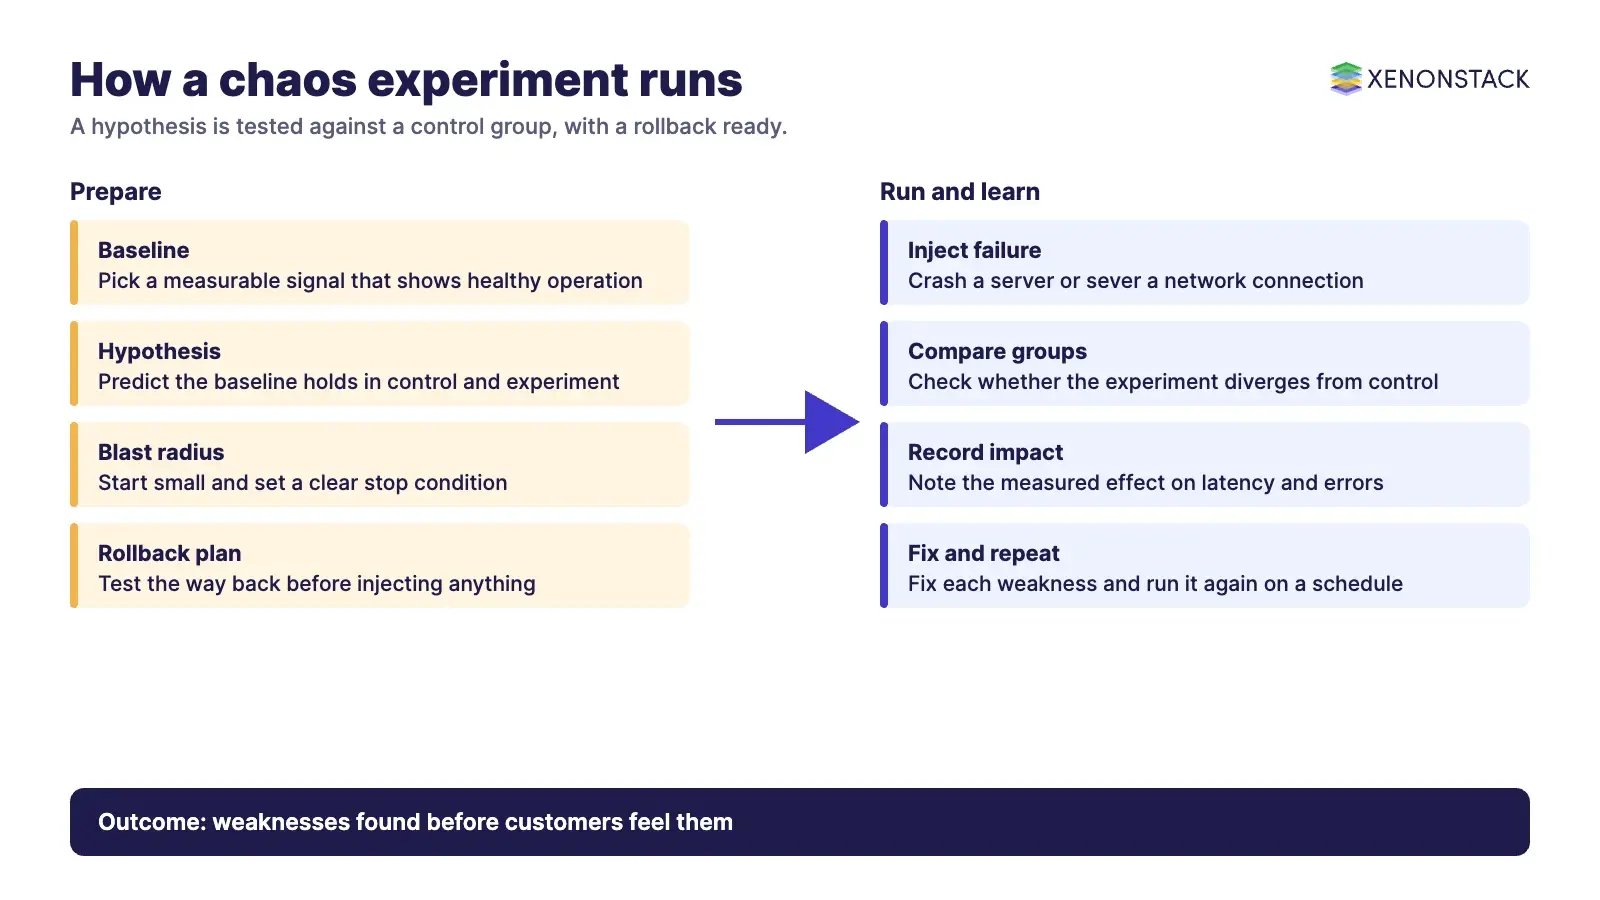
- Establish a baseline. Pick a measurable signal that shows what healthy operation looks like.
- Write the hypothesis. Predict that the baseline will hold in both a control group and an experimental group.
- Inject a disruption. Mimic a real failure, such as a crashed server or a severed network connection.
- Try to prove the hypothesis wrong. Check whether the experimental group diverges from the control.
- Roll back and record. Have a tested rollback plan before you start, note the measured impact, and fix every weakness you find.
Both outcomes are useful: either confidence grows because the system coped, or you have found a flaw before customers did.
What should you break first?
Start small, in a narrow part of the system, and widen the blast radius only after each experiment passes. The table shows common starting points by layer.
| Layer | Example failure | What to watch |
|---|---|---|
| Application | Kill a worker process | Error rate, restarts, queue depth |
| API and network | Add latency or cut access to a dependency | Timeouts, retries, fallback behaviour |
| Compute and cloud | Terminate one instance | Latency percentiles, recovery time |
| Data | Make a replica unavailable | Failover, data freshness, alerts |
Which tools support chaos engineering?
Netflix's Chaos Monkey is the best-known example. Its documentation says it is responsible for randomly terminating instances in production, so engineers build services that can withstand instance failures. Choose tooling by where your workloads run, check each project's current documentation before adopting it, and make sure your monitoring can show the baseline signal the tool will disturb. Teams that want the wider engineering context can read about Engineering DevOps for the enterprise, the release engineering and infrastructure automation that experiments run on, and the product design engineering team behind it.
The same thinking applies to connected systems. Device fleets that report to the cloud, such as those covered in IoT engineering and consulting, depend on networks that fail in ways worth rehearsing, and data platforms that sit behind them, such as those in big data consulting services, deserve the same experiments.
How do AI agents change chaos engineering?
Agents can take on the repetitive parts of the practice: drafting a hypothesis from a service's recent metrics, running an approved experiment from a runbook, comparing the control and experimental groups, and writing up the result for review. That supports the principle of automating experiments so they run continuously. Agents also become a subject of the experiments, because an agent that calls tools and models has its own failure modes, such as a tool that times out or a model that returns a malformed answer. Keep a person approving the scope and the stop condition of every experiment an agent proposes. XenonStack's ElixirClaw is the AI agents computing platform for building and running agents of this kind.
What should you do first?
- Choose one service and define its steady state with two or three output metrics.
- Write a single hypothesis and a stop condition.
- Run it in a staging environment, then in production with the smallest possible blast radius.
- Record the result, fix what you found and repeat on a schedule.
To map one decision your agents make, and the data and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
Is chaos engineering the same as testing?
No. Tests check known behaviour against expected results. Chaos experiments explore how a running system behaves under real-world events, using a hypothesis about steady state.
Do you have to run chaos experiments in production?
The Principles of Chaos Engineering recommend production because it carries real traffic. Teams usually begin in staging and move to production once they can contain the blast radius.
What is blast radius?
It is the amount of the system and the number of customers an experiment can affect. You minimise it by starting with small experiments and a clear stop condition.
What is Chaos Monkey?
It is a Netflix tool that randomly terminates instances in production so that engineers build services able to withstand instance failures.
How do AI agents fit in?
They can draft, run and summarise experiments under human approval, and they should be included as a system under test because tools and models can fail too.
Ready to put AI agents to work? See an ElixirClaw demo: the agentic OS to build, orchestrate and govern AI agents across your enterprise systems.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE