Key takeaway
- AIOps with agentic AI for IT operations: how it works, where it fits in DevOps, cloud and incidents, the barriers, tools and governance controls to set.
AIOps applies machine learning, big data analytics and automation to IT operations data so that teams detect, diagnose and resolve incidents faster. Agentic AI extends this from alerting to action: agents that plan a response, call tools such as ticketing, deployment and cloud APIs, and act within limits that people set. The decision for a CIO or head of platform is therefore not whether to buy AIOps, but how much authority to hand to automation and how to govern it.
This guide comes from XenonStack, which designs and runs agentic AIOps and SRE automation for enterprise IT operations. It draws on what XenonStack teams see when AIOps moves from dashboards to agents that act.
This guide covers what AIOps depends on, where agentic AI changes the picture, which IT domains benefit first, the barriers, an adoption sequence, the open-source tooling underneath, and when not to automate. For the wider agent landscape, see our guide to agentic AI frameworks, tools and use cases, and for the operating model see autonomous IT operations with agentic workflows.
What is AIOps, and what does agentic AI add?
Gartner's glossary definition, as reproduced by AITopics, states that "AIOps combines big data and machine learning to automate IT operations processes", including correlating events, detecting anomalies and determining cause and effect. Traditional AIOps stops at insight: it reduces alert noise and points engineers to a probable cause. Agentic AIOps adds a decision and action layer on top of that insight.
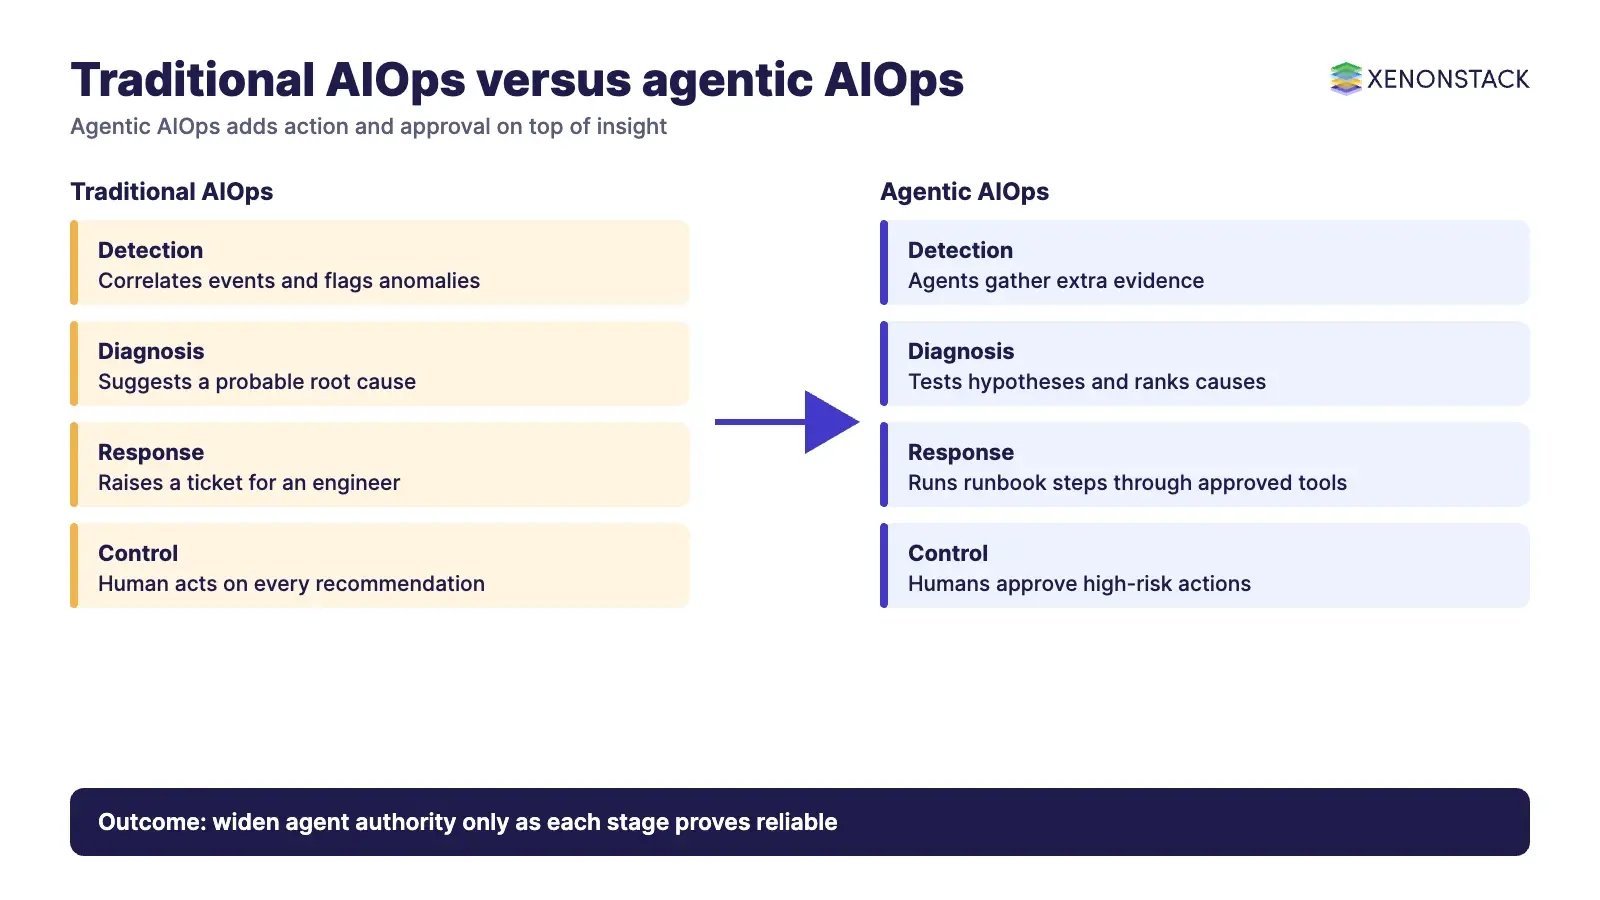
| Capability | Traditional AIOps | Agentic AIOps |
|---|---|---|
| Detection | Correlates events and flags anomalies | Same, plus agents that gather extra evidence from logs, metrics and traces |
| Diagnosis | Suggests a probable root cause | Tests hypotheses by querying systems and ranks causes with supporting evidence |
| Response | Raises a ticket or alert for an engineer | Proposes or runs a runbook step through approved tools |
| Control | Human acts on every recommendation | Humans approve high-risk actions; low-risk actions run within set limits |
| Learning | Models retrained on historical data | Past incidents and resolutions feed future decisions, with an audit trail |
The practical difference is accountability. When software can restart a service, scale a cluster or roll back a release, you need to know which actions it may take alone, which need approval, and how each decision is recorded. Platforms such as ElixirClaw describe themselves as an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control, which is the pattern to look for.
What data and technologies does AIOps depend on?
AIOps quality is capped by data quality. Platforms ingest logs, metrics, events and traces, process both historical and real-time streams, and apply machine learning for anomaly detection, classification and prediction. Observability supplies the raw material: MELT (metrics, events, logs and traces) gives the full-stack view that correlation and root cause analysis need.
| Component | Function | Why it matters to the decision maker |
|---|---|---|
| Data selection | Filters signal from noise | Controls alert volume and tooling cost |
| Pattern discovery | Finds relationships and trends across telemetry | Surfaces recurring failure modes |
| Inference | Determines probable root cause | Shortens diagnosis, but needs human review on edge cases |
| Collaboration | Centralises incident context across teams | Removes silos between development and operations |
| Automation | Executes remediation actions | Where governance and approval limits must be set |
Where does AIOps apply across IT operations?
Four domains show the clearest return, because each has high data volume, repeatable decisions and a measurable outcome.
| Domain | Typical problem | What agentic AIOps does | Measure |
|---|---|---|---|
| DevOps | Coordination gaps, manual monitoring, scaling many services | Detects recurring issues from history, gives a unified view of health and incident trends, automates routine responses | Time to resolution, deployment failure rate |
| Cloud | Hybrid estates, uneven utilisation, cost against performance | Learns usage patterns, scales resources up or down, flags idle resources and better-fitting instance types | Utilisation, cloud spend per service |
| Kubernetes and serverless | Dynamic allocation, scaling inefficiency, ephemeral workloads that are hard to see | Adjusts CPU and memory allocation, optimises load balancing, provides granular observability across microservices | Resource efficiency, saturation incidents |
| Incident management | Manual triage and ticketing, reactive handling, slow coordination | Detects and categorises incidents by severity, opens tickets for the right team, adds first diagnostics, keeps status updated | MTTR, incidents per month |
Read the DevOps row alongside our review of DevOps automation tools, and the incident row with our incident management process and tools guide. For container estates, our Kubernetes consulting services page sets out how we run cluster operations.
What stops AIOps programmes from delivering?
| Barrier | What it looks like | Response |
|---|---|---|
| Integration complexity | Legacy systems and inconsistent data pipelines | Integrate through existing monitoring and ticketing; do not require infrastructure replacement |
| Data quality | Noisy, duplicated or unlabelled telemetry | Clean and normalise data before training or deploying models |
| Organisational resistance | Concern about job displacement or lost manual control | Position agents as augmenting engineers; invest in training |
| Technical limits | False positives, model bias and opaque decisions | Keep human review for complex edge cases; AIOps augments judgement, it does not replace it |
How should an enterprise adopt AIOps in sequence?
Adopt in stages, and widen an agent's authority only after the previous stage has proved reliable.
- Fix the data first. Normalise logs, metrics and events and build dependable pipelines.
- Start with one or two scoped use cases that have clear success metrics, such as alert correlation or ticket triage.
- Run in advisory mode. Agents recommend; engineers act. Compare recommendations with what humans actually did.
- Automate low-risk actions with explicit limits, rollback and logging.
- Keep approvals for high-risk actions and route exceptions to the right decision maker.
- Train the team as part of the programme, not as overhead.
Gradual Adoption
Instead of implementing AIOps across the entire organization, start small with specific, well-defined use cases. This allows teams to learn and adapt to the new system while demonstrating the value of AIOps.
Data Preparation
For AIOps to be effective, data quality is paramount. Organizations should invest in cleaning and normalizing their operational data and creating robust data pipelines to ensure the success of AIOps initiatives.
For help running AIOps in production, see XenonStack’s AIOps and SRE services.
Which open-source tools sit underneath AIOps?
Open-source tools supply the telemetry and analysis layers that AIOps platforms build on. Facts below come from each project's own page.
| Tool | What it is | Best fit | Check before relying on it |
|---|---|---|---|
| Prometheus | Open-source monitoring and alerting toolkit with a multi-dimensional time-series data model and the PromQL query language; Apache 2 licence; CNCF project since 2016 | Metrics collection for cloud and Kubernetes | Metrics only; pair with logging and tracing |
| Grafana | Open-source visualisation and monitoring tool for dashboards across metrics, logs and traces; 150+ plugins | Unified dashboards across data sources | Dashboards alone do not correlate or act |
| OpenNMS | Network monitoring platform covering monitoring, traffic analysis and alerting; published under AGPLv3 | Network and service monitoring at scale | Network focus; Meridian is a subscription offering |
| Loglizer | Machine learning toolkit for log anomaly detection with supervised and unsupervised models | Research and prototyping of log anomaly detection | Its page shows its dated history ending in 2019 and no clear recent commit date; confirm maintenance status before production use |
How does AIOps differ from MLOps and DevOps?
| Aspect | AIOps | MLOps | DevOps |
|---|---|---|---|
| Focus | Optimising IT operations and infrastructure | Managing the machine learning model lifecycle | Integrating software development and IT operations |
| Data | Logs, metrics, events | Training and model performance data | Code, configuration, infrastructure |
| Main users | IT operations, site reliability engineers | Data scientists, ML engineers | Development and operations teams |
| Typical tools | Prometheus, Grafana, OpenNMS | Kubeflow, MLflow, DVC | Jenkins, Docker, Kubernetes, GitLab |
| Key challenge | Integration, data quality, false positives | Model drift, reproducibility, scaling | Communication gaps, manual deployment |
They complement each other: DevOps ships the software, MLOps keeps any models healthy (see our MLOps guide), and AIOps keeps the running estate reliable.
What governance, security and cost controls does agentic AIOps need?
| Control | Why it is needed | Practical rule |
|---|---|---|
| Action limits | An agent with broad permissions can cause an outage faster than a person | Grant least privilege per runbook; separate read, change and destructive actions |
| Approval routing | Some actions exceed an agent's authority | Route exceptions to the correct approver with the evidence attached |
| Audit trail | Regulators and post-incident reviews need to know who or what acted | Log every recommendation, approval and action with its inputs |
| Rollback | Automated fixes can be wrong | Require a tested rollback path before enabling automation |
| Cost | Telemetry volume and agent calls both grow | Set retention and sampling policies; track cost per resolved incident |
Exception routing is a good first governance pattern. The Exception Handling Agent detects situations that need human judgement, gathers context, routes them to the right decision maker and generates a Decision Trace. For incident detection, diagnosis and remediation by agents, see AgentSRE, which describes a group of AI agents that spot problems, find their causes and fix them.
When should you not automate with AIOps?
- Poor or sparse telemetry: models trained on noisy data produce confident but wrong recommendations.
- Rare, high-impact changes: keep a human decision where the cost of error is high and incidents are infrequent.
- No rollback or audit path: do not automate what you cannot reverse or explain.
- Unclear ownership: if no team owns the service, no one owns the agent's actions on it.
What is the future of AIOps with agentic AI?
The direction is towards agents that coordinate across monitoring, ticketing, cloud and deployment tools, with predictive maintenance and cross-platform context. The limiting factor will be governance and data quality rather than model capability, so build those foundations now.
To map one IT operations decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
How XenonStack helps: XenonStack builds agentic AIOps for enterprise IT teams, giving AI agents the operational context, safe action boundaries and a full decision trace they need to move from pilot to governed production. With XenonStack, incident detection, root-cause analysis and remediation run with human approval where it matters and an audit trail for every action.
Frequently asked questions about AIOps
What is AIOps?
AIOps combines big data and machine learning to automate IT operations processes, such as correlating events, detecting anomalies and finding cause and effect (Gartner glossary definition, as reproduced by AITopics).
How is agentic AIOps different from traditional AIOps?
Traditional AIOps stops at insight and recommendations. Agentic AIOps adds agents that plan and carry out actions through approved tools, within limits and approvals set by people.
What data does AIOps rely on?
Logs, metrics, events, traces and historical performance data. Observability supplies this foundation, and poor data quality limits results.
What is the biggest barrier to AIOps adoption?
Integration complexity and data quality, followed by organisational resistance and the need for human oversight of false positives and opaque decisions.
Which open-source tools support AIOps?
Prometheus for metrics, Grafana for dashboards, OpenNMS for network monitoring and Loglizer for log anomaly detection. They supply telemetry and analysis, not full autonomous operations.
Where should an enterprise start?
Start with one or two scoped use cases, such as alert correlation or ticket triage, run agents in advisory mode first, and automate only low-risk actions with rollback and logging.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE