Key takeaway
- Apache Drill explained: Drillbit architecture, query execution, 1.22.0 changes, current project status, and when to choose Trino, DataFusion or DuckDB.
Apache Drill is an open-source, distributed SQL query engine that queries files, NoSQL stores and relational databases in place, discovering the schema while it reads the data. Its architecture centres on a Drillbit service on each node, ZooKeeper for cluster coordination, and storage plugins that connect to each data source.
On status: Drill is not retired. It is not listed in the Apache Attic, and its latest release, 1.22.0, came out on 28 June 2025. Release activity has slowed to about one maintenance release a year since 2023, and no newer release appears on the download page as of 11 November 2026. Treat it as maintained but low-activity, and compare it with Trino, Apache DataFusion and DuckDB before starting new work on it.
What is Apache Drill and what can it query?
Drill runs standard SQL over data that does not fit a fixed relational schema. According to the Drill architecture introduction, it is not tied to Hadoop and can run in any distributed cluster environment. It processes data in record batches and discovers the schema during processing, which is why it can query nested JSON and Parquet without a load or transformation step first.
The Drill documentation lists storage plugins for these sources:
| Category | Sources listed in the Drill docs |
| Files and object storage | File system (local or distributed), S3, OCI Object Storage, Azure Blob Storage, Dropbox |
| Hadoop ecosystem | Hive, HBase |
| Databases and search | RDBMS (via JDBC), MongoDB, Cassandra, Elasticsearch, Druid, OpenTSDB |
| Streams and APIs | Kafka, HTTP, Splunk, Google Sheets |
| MapR | MapR-DB format still listed, but the MapR profile and plugin were disabled as unsupported in 1.22.0 |
If you are weighing these source types, our comparison of SQL, NoSQL and NewSQL databases explains the trade-offs between them.
Is Apache Drill still active in 2026?
Drill is an active Apache project, not an Attic project, but its pace is slow. The release history on the Drill blog shows the pattern:
| Release | Date | Type |
| 1.20.0 | 25 February 2022 | Feature release (Iceberg format plugin, HTTP plugin OAuth and pagination, more MongoDB pushdown) |
| 1.20.1 to 1.20.3 | May 2022 to January 2023 | Maintenance |
| 1.21.0 | 2 March 2023 | Feature release (new connectors and functions, stability) |
| 1.21.1 | 29 April 2023 | Maintenance |
| 1.21.2 | 23 June 2024 | Maintenance |
| 1.22.0 | 28 June 2025 | Latest release (see below) |
In plain terms: Drill still works and still ships fixes, but it is not where new query-engine investment is going. Plan any new platform on the assumption that features will arrive slowly.
How does the Apache Drill architecture work?
Drillbits and ZooKeeper
The Drillbit service is the core of Drill. It accepts client requests, processes queries and returns results. You run a Drillbit on each node in the cluster so that Drill can process data where it is stored instead of moving it across the network. ZooKeeper tracks which Drillbits belong to the cluster and checks their health; the docs describe it as the only prerequisite for Drill.
Client interfaces
Clients connect through the Drill shell, the Drill Web UI, ODBC and JDBC drivers (which is how BI tools connect), and a C++ API.
Storage plugins and schema discovery
Storage plugins connect Drill to each source and supply whatever metadata the source has. That ranges from full metadata in Hive, to partial metadata in HBase, to none for plain files. Plugins also tell the execution engine what the source can do, such as predicate pushdown. Where metadata is missing, Drill discovers the schema as it reads.
Query execution
The query execution docs describe this sequence:
- The Drillbit that receives the SQL becomes the Foreman and drives the whole query.
- A parser in the Foreman turns the SQL into Drill's logical operators, which together form a logical plan.
- A cost-based optimiser reorders operators and converts the logical plan into a physical plan that describes how to run the query.
- A parallelizer splits the physical plan into major fragments (phases) and minor fragments (units of parallel work), separated by exchange operators.
- Leaf fragments scan data in parallel, intermediate fragments combine partial results, and the root fragment in the Foreman returns the final result to the client. Each minor fragment runs in its own thread.
What changed in Drill 1.22.0?
The 1.22.0 release notes are mostly fixes and dependency upgrades. The changes that matter for platform owners are:
- Java 8 support removed (DRILL-8523). Check your runtime before upgrading.
- Hadoop upgraded from 3.2.4 to 3.3.6, and the HBase client to 2.6.1.
- MapR profile and plugin disabled as unsupported.
- Security fixes, including a Parquet upgrade for a CVE.
- New features: SFTP file system support, DNS lookup functions, REGEXP_EXTRACT, XML type inference and XSD support, and Splunk schema caching.
How does Drill compare with Trino, Apache DataFusion and DuckDB?
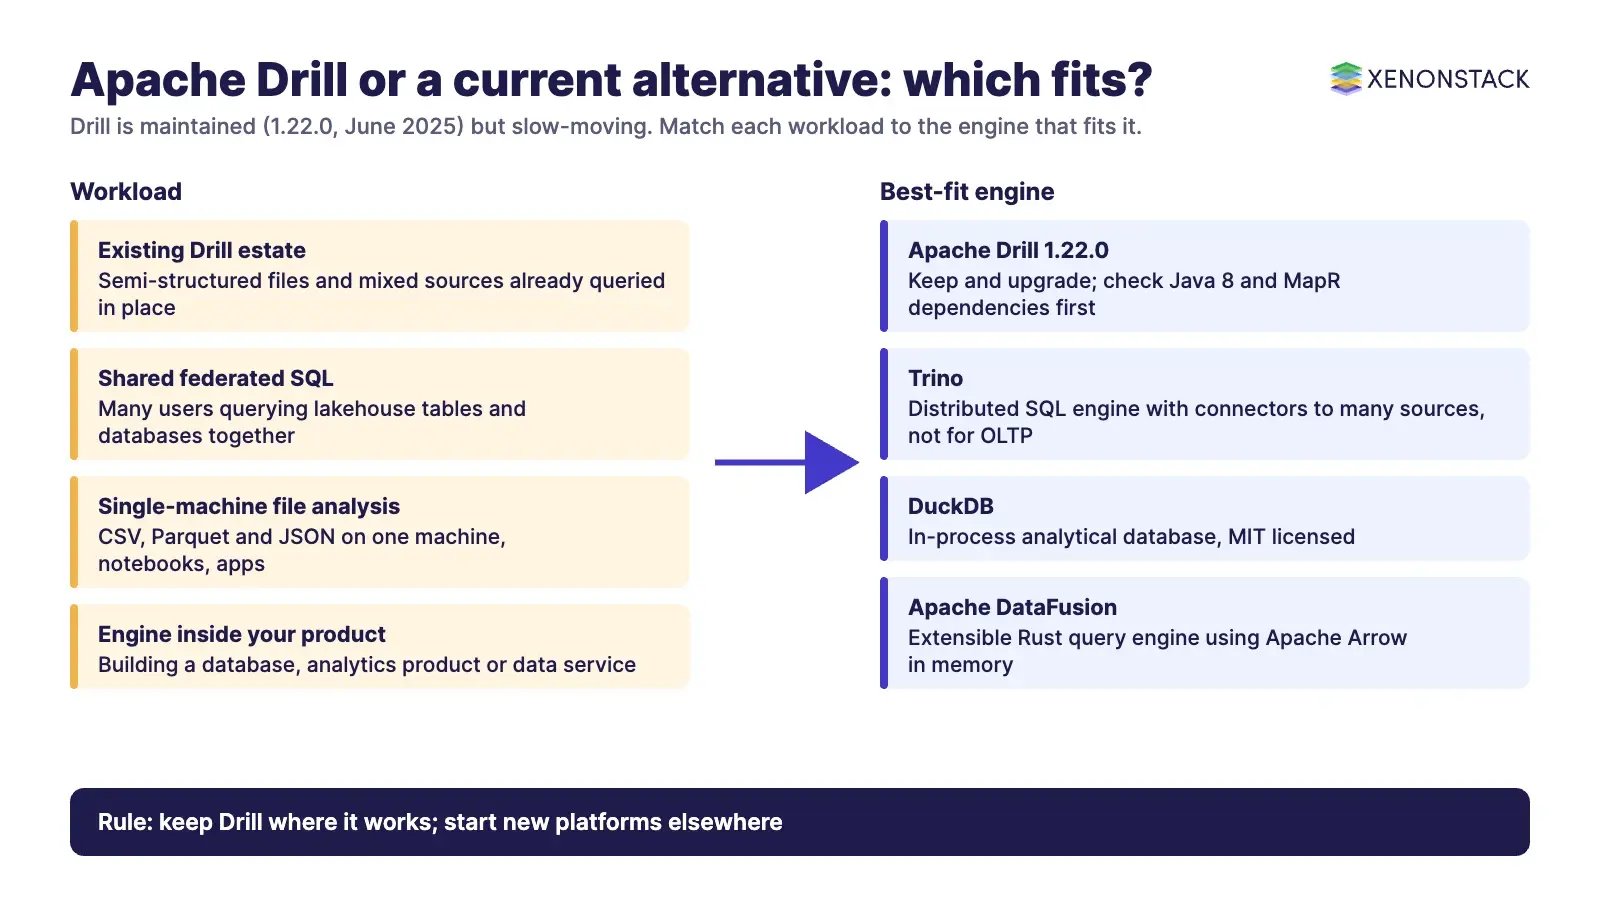
Each project describes itself differently, and the descriptions point to different jobs.
| Engine | What it is (in its own words) | When it fits | Current status |
| Apache Drill | Distributed SQL engine with schema discovery during processing | Existing deployments querying semi-structured files and mixed sources in place | Maintained; latest release 1.22.0, June 2025 |
| Trino | "Fast distributed SQL query engine for big data analytics"; not a general-purpose database and not built for OLTP | Shared, multi-user federated analytics across lakehouse tables and many databases through connectors such as Hive, Iceberg, Delta Lake, Kafka, MongoDB and PostgreSQL | Active; documentation at version 484 when read |
| Apache DataFusion | "An extensible query engine written in Rust that uses Apache Arrow as its in-memory format" | Teams building their own database, analytics product or data service who want to embed and customise a query engine | Active Apache project |
| DuckDB | An in-process analytical (OLAP) database, embedded in the host process, MIT licensed | Single-node analysis of CSV, Parquet and JSON files, notebooks, and embedded analytics in applications | Active |
A rough decision rule: choose Trino for a shared, distributed SQL layer over many sources; DuckDB when the data fits on one machine and you want minimal operations; DataFusion when you are building an engine into your own product; and keep Drill where it already runs well and the sources it covers still match your estate. Where business users need answers rather than SQL, AgentAnalyst lets teams ask questions of enterprise data in plain language and get real-time insights.
What governance, security and cost questions should you ask?
- Patch cadence. With about one release a year, security fixes in Drill's dependencies may arrive later than in faster-moving engines. Track CVEs in the libraries it ships, as the 1.22.0 Parquet fix shows.
- Runtime and platform. Drill 1.22.0 drops Java 8 and disables MapR. Confirm your Java version and remove any MapR dependency before upgrading.
- Access control. Querying sources in place means Drill sees whatever its plugins can reach. Scope plugin credentials to least privilege and keep audit logs of who queried what.
- Cost. A Drillbit on every data node uses memory and CPU on those nodes. For occasional analysis, a single-node engine may cost less to run.
When query results feed automated decisions rather than dashboards, the context and policy behind each decision also need a record. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents.
What adoption sequence works for teams running Drill today?
- Inventory. List the storage plugins, queries and BI connections that depend on Drill, and flag any MapR or Java 8 dependency.
- Upgrade to 1.22.0 if you will keep Drill for a while, so you have the latest fixes.
- Match workloads to engines. Shared federated SQL to Trino, single-node file analysis to DuckDB, embedded engines to DataFusion.
- Run in parallel. Point a copy of key queries at the candidate engine and compare results and run times on your own data.
- Retire gradually. Move BI connections one domain at a time, then decommission Drillbits.
Where the move is part of a wider platform change, our guides to data warehouse modernisation and Apache Spark optimisation cover the neighbouring decisions. For sub-second analytics on event streams, see our overview of Apache Druid, which Drill can also query through a storage plugin.
When should you not use Apache Drill?
- For a new, strategic SQL platform where you need frequent releases and a large contributor base.
- For transactional (OLTP) workloads; Drill is a query engine, not a database.
- For MapR-based estates, since the MapR plugin is disabled in 1.22.0.
- For small, single-machine analysis, where an in-process engine needs far less operational effort.
To map one data-driven decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions about Apache Drill
Is Apache Drill retired or in the Apache Attic?
No. Drill is not listed in the Apache Attic. Its latest release is 1.22.0, published on 28 June 2025, and releases have slowed to about one maintenance release a year since 2023.
What is a Drillbit?
A Drillbit is the core Drill service. It accepts client requests, processes queries and returns results. One runs on each node so Drill can process data where it is stored, and ZooKeeper tracks cluster membership and health.
Does Apache Drill need Hadoop?
No. Drill is not tied to Hadoop and can run in any distributed cluster environment. It can query Hive and HBase, but also local and object storage, relational databases, MongoDB, Kafka and other sources through storage plugins.
How does Drill handle data without a schema?
Drill processes data in record batches and discovers the schema during processing. Storage plugins supply whatever metadata a source has, from full metadata in Hive to none for plain files.
What are the main alternatives to Apache Drill?
Trino for distributed, federated SQL analytics; DuckDB for in-process analysis of files such as CSV, Parquet and JSON; and Apache DataFusion, a Rust query engine built on Apache Arrow, for teams embedding a query engine in their own product.
What changed in Drill 1.22.0?
Java 8 support was removed, Hadoop was upgraded to 3.3.6, the MapR profile and plugin were disabled, a Parquet CVE was fixed, and features such as SFTP support and new SQL functions were added.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE