Key takeaway
- Learn how DevOps, CI/CD and continuous training apply to deep learning pipelines on Kubernetes, with Kubeflow, maturity levels, tools and first steps.
DevOps for deep learning is the practice of building, testing, releasing and retraining deep learning models through automated pipelines, so that code, data and models move to production in a repeatable and auditable way. Kubernetes is a common place to run those pipelines because it gives training, serving and supporting services one way to be deployed, scaled and managed.
This guide is for platform, data and machine learning engineers who have a model that works in a notebook and need a reliable path to production. It covers the stages of a deep learning pipeline, how continuous integration, delivery and training change for models, what Kubernetes and Kubeflow add, and what to do first. For the wider pipeline view, see our guide to the machine learning pipeline.
What is a deep learning pipeline?
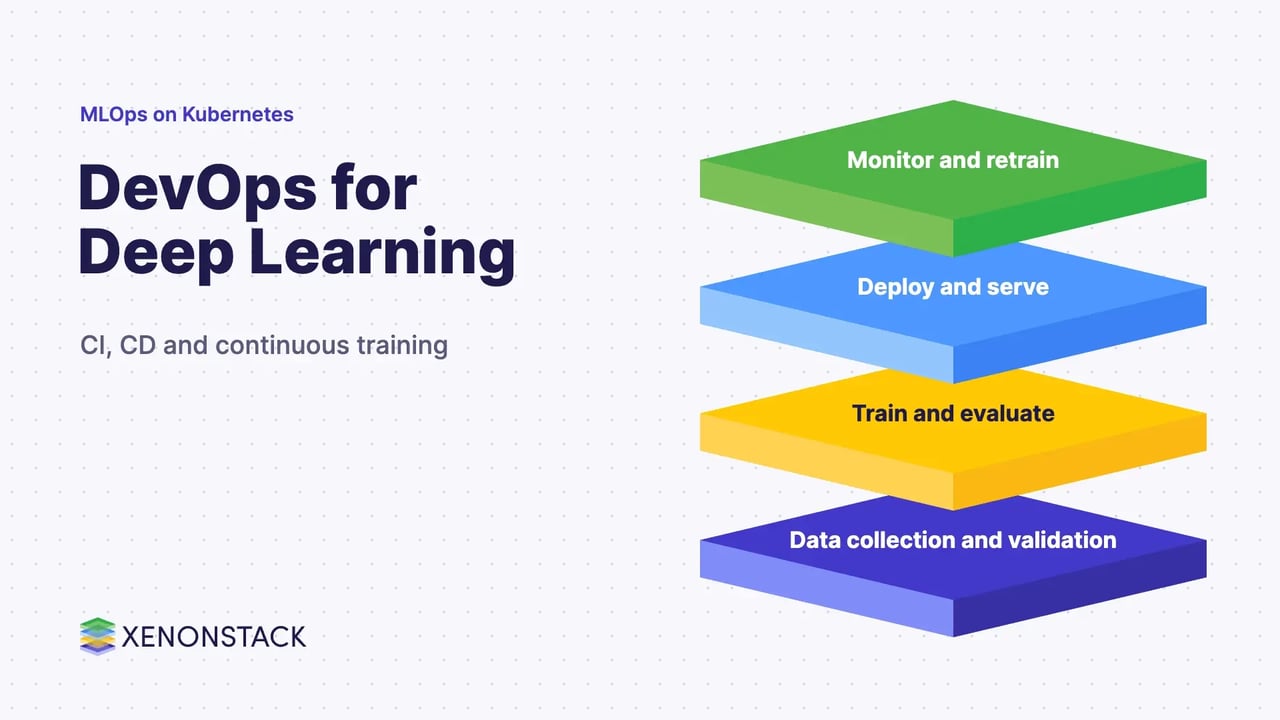
A deep learning pipeline is the ordered set of steps that takes raw data to a model serving predictions: collect and store data, prepare it, train a neural network, evaluate it, deploy it and monitor it. The architecture inside the training step can vary, for example convolutional networks for images or recurrent networks for sequences, but the surrounding stages stay broadly the same. That is why the pipeline, and not the network design, is what DevOps practices automate.
Deep learning workloads add demands that ordinary web services do not have: large datasets, long training runs, specialised hardware and models that go stale when data changes. A pipeline has to handle all of these as repeatable, versioned steps.
What does DevOps change for machine learning?
The Google Cloud MLOps guide describes how the familiar practices change for machine learning. CI "is no longer only about testing and validating code and components": it also covers testing data, data schemas and models. CD "is no longer about a single software package or a service, but a system": it delivers a training pipeline that in turn deploys a prediction service. The guide adds continuous training, which it calls "a new property, unique to ML systems", concerned with automatically retraining and serving models.
| Practice | In ordinary software | In deep learning |
|---|---|---|
| Continuous integration | Test and validate code | Also test data, data schemas and models |
| Continuous delivery | Ship one package or service | Ship a training pipeline that deploys a prediction service |
| Continuous training | Not applicable | Retrain and serve models automatically |
What are the stages of the pipeline and which tools fit?
Most teams combine open-source tools stage by stage. The table below keeps the tools commonly used for each stage; treat it as a menu, not a prescription, and check each project's documentation before choosing.
| Stage | What happens | Tools teams commonly use |
|---|---|---|
| Collect | Gather data from sources | Python, Scala, Go, R, Pentaho Data Integration, WEKA |
| Store | Keep raw and processed data | HDFS, Amazon S3, MongoDB, Cassandra, Redis, Apache Kafka, Elasticsearch |
| Enrich | Clean and transform data | Apache Spark, Apache NiFi, Apache Airflow, Apache Storm, Amazon EMR |
| Train | Fit the neural network | TensorFlow, PyTorch, MXNet |
| Visualise | Inspect data and results | Kibana, Grafana, D3.js |
| Run | Package and host the pipeline | Docker, Kubernetes, Amazon Elastic Container Service |
Some tools in older lists have changed since they were first popular, and MXNet in particular should be checked for current project status before you adopt it. For Spark-based work, our guide to the continuous delivery pipeline for Python shows how delivery automation looks in practice.
How do you automate it: the maturity levels?
The Google Cloud MLOps guide describes three levels. At level 0 every step is manual, "including data analysis, data preparation, model training, and validation", with no CI, CD or active monitoring. At level 1 the goal is "to perform continuous training of the model by automating the ML pipeline", adding data and model validation, pipeline triggers and metadata management. At level 2 a "robust automated CI/CD system" lets teams update the pipelines themselves quickly and reliably.
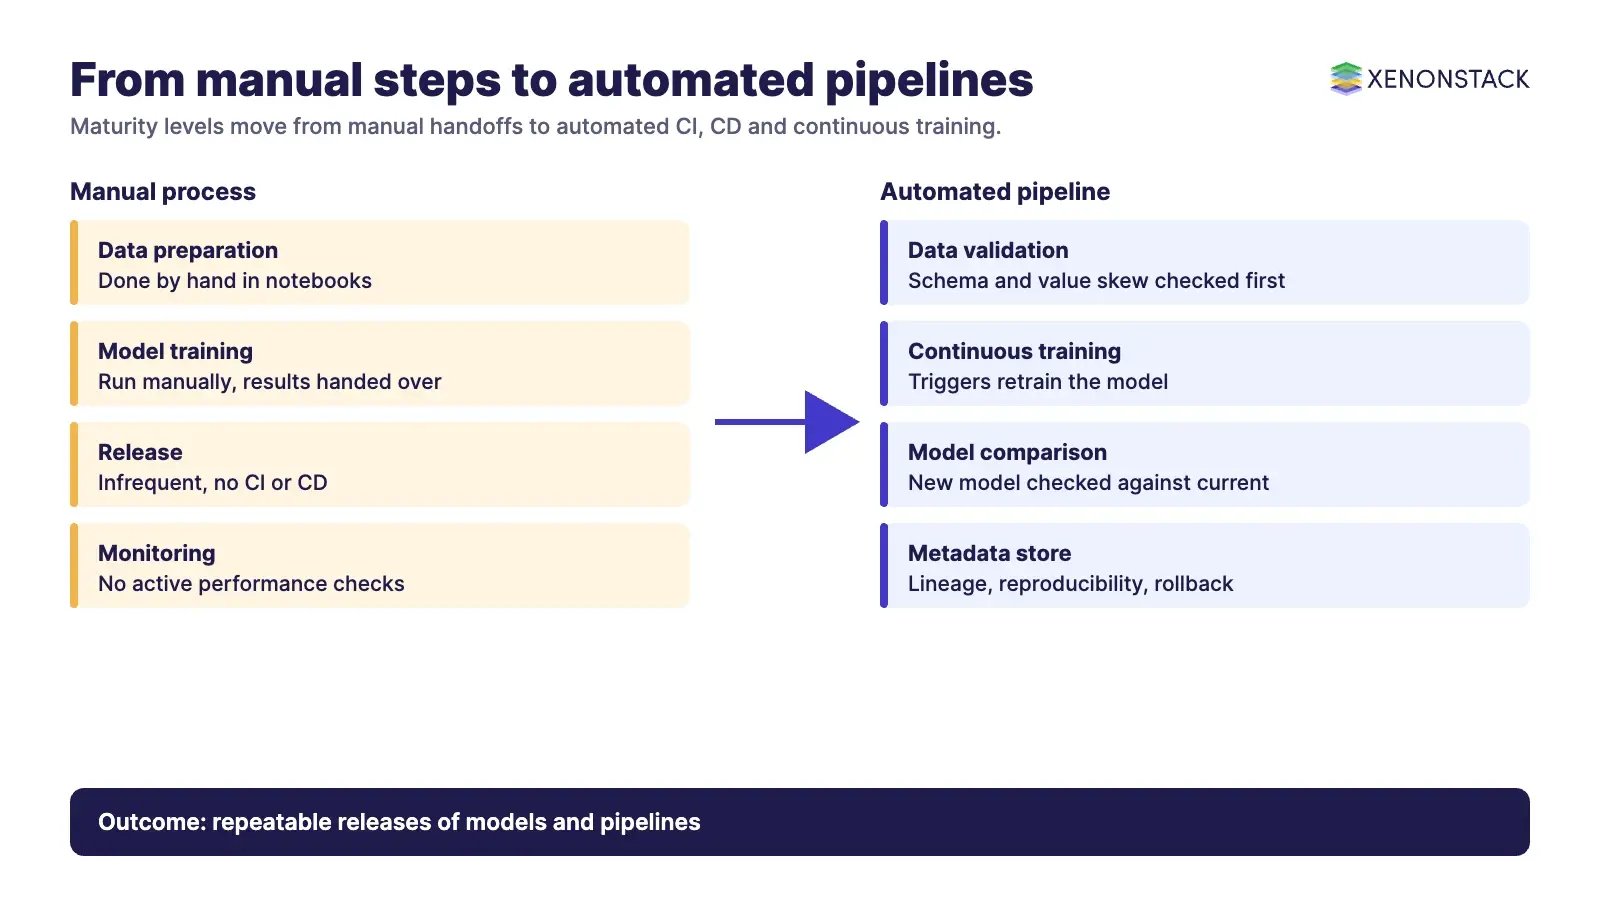
At level 1, the guide says validation checks data for schema and value skews before training and evaluates the new model against the current one before promotion. Triggers can be on demand, on a schedule, on new training data, on performance degradation or on concept drift. The metadata store records versions, parameters, artifact locations and evaluation metrics, which supports lineage, reproducibility and rollback.
What does Kubernetes add, and where does Kubeflow fit?
The Kubeflow architecture page says Kubeflow "builds on Kubernetes as a system for deploying, scaling, and managing AI platforms" and lists subprojects for each stage of the AI lifecycle. Kubeflow Pipelines can be used to build, deploy and manage each step of that lifecycle. Kubeflow Trainer targets large-scale distributed training and large language model fine-tuning, Notebooks supports interactive model development, and the Spark Operator supports data preparation and feature engineering. Check the page for the current list, because subprojects change over time.
In practice, Kubernetes gives each pipeline step a container, a resource request and a place in a scheduler, so the same definition runs on a laptop-sized cluster or a larger one. For a worked example of a delivery pipeline on cloud infrastructure, see our AWS DevOps pipeline use case.
What are the best practices?
- Manage data deliberately: analyse, validate and transform it as pipeline steps, not as one-off scripts.
- Treat training as code: model specification and training runs are versioned and reproducible.
- Evaluate before release: compare each new model with the one in service and gate promotion on the result.
- Deploy, predict and monitor: serve the model, watch it, and trigger retraining when behaviour degrades.
- Record metadata so any model can be traced to the data and code that produced it.
How do AI agents change DevOps for deep learning?
Agents can take on the routine work around a pipeline: watching triggers, running evaluation checks, opening a change when a data schema shifts and preparing a rollback for a person to approve. That makes the contracts between pipeline stages, and the records of what an agent did and why, more important than before. ElixirClaw is the AI agents computing platform for building and running agents like these, with people kept in the loop for approvals.
What should you do first?
- Write down your current pipeline stages and mark which are still manual.
- Put the training code and pipeline definition under version control.
- Add data validation and a model comparison step before any promotion.
- Containerise each stage and run it on Kubernetes.
- Add a trigger for retraining, then record metadata for every run.
To map one decision your agents make, and the data and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is DevOps for deep learning?
It is the practice of applying continuous integration, continuous delivery and continuous training to deep learning systems, so that code, data, models and the training pipeline are tested, versioned and released in a repeatable way.
Why run deep learning pipelines on Kubernetes?
Kubernetes provides a common system for deploying, scaling and managing workloads, and projects such as Kubeflow build on it to cover the stages of the AI lifecycle.
What is continuous training?
Continuous training is the automatic retraining and serving of models. The Google Cloud MLOps guide describes it as a property unique to machine learning systems.
What should be tested in a deep learning pipeline?
Test the code and components, but also the data and its schema, and the model itself, including a comparison of a new model against the one currently serving.
Do I need a feature store or a model registry?
Not on day one. The Google Cloud MLOps guide lists a feature store as optional at its automation level, while a model registry and a metadata store become part of a full CI/CD setup as the number of models grows.
Ready to put AI agents to work? See an ElixirClaw demo: the agentic OS to build, orchestrate and govern AI agents across your enterprise systems.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE