Key takeaway
- NLP sentiment analysis for customer feedback: what it is, how to choose rules, transformers, LLMs or cloud APIs, measure quality and act on the scores.
Sentiment analysis in NLP is the task of reading a piece of text, such as a review, survey answer, support email or chat transcript, and classifying the opinion in it as positive, negative or neutral, usually with a confidence score. Modern systems also score each sentence and each aspect, so one review can be positive about staff and negative about price. For customer feedback, that turns thousands of free-text comments into signals a team can count, trend and act on.
This guide is for leaders deciding how to run sentiment analysis on customer feedback in 2026: which approach fits (lexicon rules, trained classifiers, transformer models, large language models or managed cloud APIs), what has changed in the services, how to measure quality, and how to connect scores to decisions. For the wider discipline see our guide to text analytics, for tool selection see NLP tools compared, and for the underlying techniques see natural language processing.
What is sentiment analysis in NLP?
Sentiment analysis, also called opinion mining, is a text classification task inside natural language processing. The system takes text in and returns a label and a score. What differs between systems is the level they work at and the labels they return.
| Level | What it answers | Example on a hotel review |
|---|---|---|
| Document | What is the overall opinion of this text? | Mostly negative |
| Sentence | Which sentences carry the opinion? | "The room was clean" positive; "Check-in took an hour" negative |
| Aspect (target) | What is the opinion about each named thing? | Cleanliness positive, check-in negative, price neutral |
The managed services label and score text differently, which matters when you compare or switch them:
| Service | Labels and scores | Aspect-level option | Source |
|---|---|---|---|
| Azure Language (Foundry Tools) | Positive, neutral or negative per document and sentence, with confidence scores between 0 and 1 for each | Opinion mining (aspect-based) | Microsoft Learn |
| Amazon Comprehend | Positive, negative, mixed or neutral, with a score for each | Targeted sentiment per entity mention, English only | AWS docs |
| Google Cloud Natural Language | Score from -1.0 (negative) to 1.0 (positive) plus magnitude (strength of emotion, 0 upwards, not normalised for the document) | Entity sentiment per mention | Google Cloud docs |
| VADER (open source, MIT) | Compound score: 0.05 or above positive, -0.05 or below negative, between is neutral | No | GitHub |
Google's documentation makes a point worth keeping: a near-zero score can mean a neutral text or a mixed one, and magnitude tells them apart, because truly neutral documents have low magnitude. Any system you build should keep "mixed" separate from "neutral", or complaints hidden inside polite reviews disappear from the counts.
Which sentiment analysis approach fits your feedback?
There are five practical approaches. Most enterprise programmes use two of them: a fast, cheap method for volume and a stronger method for the cases that drive decisions.
| Approach | What it is | When it fits | Current status (read 12 Nov 2026) |
|---|---|---|---|
| Lexicon and rules | Word lists with sentiment scores plus rules for negation, intensifiers and emoji, for example VADER | Short social posts, quick baselines, explainable scores, no training data | VADER is MIT-licensed and published at ICWSM 2014; tuned for social media text |
| Classical machine learning | Bag-of-words or TF-IDF features with Naive Bayes, logistic regression or SVM | Stable domain, labelled data available, low compute budget | Mature; mostly used as a baseline |
| Fine-tuned transformer | A pre-trained encoder such as BERT trained further on your labelled feedback | High volume, a fixed label scheme, need for consistent, repeatable scores | BERT (Devlin et al., October 2018) set the pattern; fine-tuned encoders are a common choice for volume |
| Large language model prompting | An LLM classifies text from instructions and a few examples, and can return the reason and the aspect | Little labelled data, new categories, need for explanations | Strong in few-shot settings, weaker on complex structured tasks (Zhang et al., 2023) |
| Managed cloud API | Azure Language, Amazon Comprehend or Google Cloud Natural Language | Fast start, standard labels, no model to run | Azure sentiment retires 31 March 2029; Comprehend targeted sentiment is English only; Google v2 uses a PaLM-based model (preview, August 2023) |
The research view on LLMs is balanced. The 2023 reality check by Zhang and colleagues tested 13 sentiment tasks across 26 datasets and found that LLMs perform well on simpler tasks and significantly outperform small models in few-shot settings, but lag behind on more complex tasks that need deeper understanding or structured output. In practice, LLMs are a good way to label a training set or handle long, mixed feedback, while a fine-tuned model scores the daily volume.
What has changed in sentiment analysis services?
- Microsoft states that sentiment analysis and opinion mining retire from Azure Language on 31 March 2029 and directs new projects to Microsoft Foundry models. Teams building on Azure today should plan the migration now rather than at the deadline.
- Google Cloud released Natural Language API v2 in public preview on 28 August 2023 and moved sentiment analysis to a new PaLM-based model; the field
languagebecamelanguage_code. Check which version your integration calls. - Amazon Comprehend offers targeted sentiment, which scores each mention of an entity such as a brand or product, with a mixed label. AWS documents it for English only.
- Large language models are now a normal part of the toolset, mainly for labelling, explanation and aspect extraction, rather than a replacement for every classifier.
How does a sentiment pipeline for customer feedback work?
A production pipeline has six stages. The model is only one of them; most quality problems come from the stages around it.
- Collect and join. Pull reviews, surveys, support tickets, emails and chat transcripts, and keep the customer, product, channel and date with each item so scores can be sliced later.
- Clean and protect. Remove signatures, quoted replies and boilerplate; detect the language; mask personal data before text leaves your controlled environment.
- Keep the signals that carry sentiment. Do not strip negation words such as "not" and "never", and keep or map emoji. Aggressive stop-word removal, written for search, can flip the meaning of feedback.
- Find aspects. Extract what each opinion is about (delivery, billing, staff, a product feature) using entity recognition, a fixed taxonomy or an LLM.
- Classify. Score each sentence and aspect, keep mixed separate from neutral, and keep the model's confidence.
- Aggregate and route. Trend scores by aspect, product and segment, and send low-confidence or high-impact items to a person or a workflow.
Aspect-level analysis is where customer feedback becomes useful. It was set as a shared research task at SemEval-2014 Task 4, and the managed services now expose it as opinion mining (Azure), targeted sentiment (AWS) and entity sentiment (Google). A falling overall score tells you something is wrong; a falling score on "refund process" tells you what to fix.
How do you turn sentiment scores into decisions?
A sentiment dashboard on its own rarely changes outcomes. In our own customer work on customer email sentiment, we framed the solution as sentiment analysis plus decision intelligence (customer conversation intelligence) rather than a set of sentiment dashboards: each scored message should feed a decision, such as whether to escalate, who should respond and what the recovery action is, with the context and policy behind it recorded. This is the same idea behind intelligence-driven decision making.
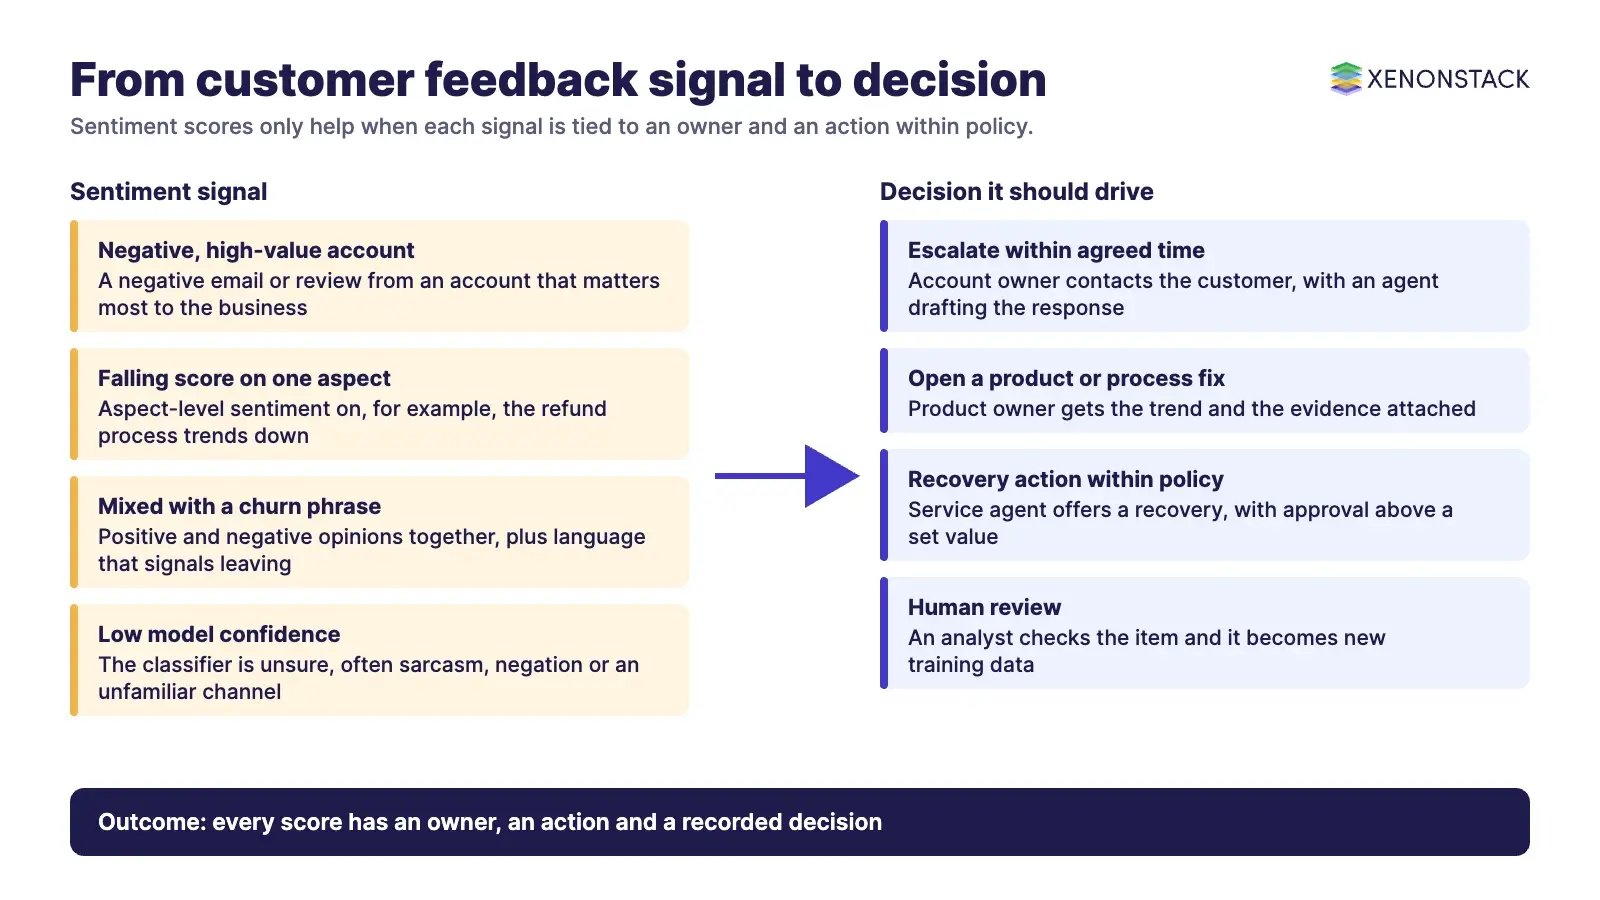
| Signal | Decision it should drive | Who or what acts |
|---|---|---|
| Negative sentiment on a high-value account | Escalate and contact within an agreed time | Account owner, with an agent drafting the response |
| Rising negative trend on one aspect | Open a product or process fix | Product owner, with the evidence attached |
| Mixed sentiment with a churn phrase | Offer a recovery action within policy | Service agent, with approval above a set value |
| Low model confidence | Send to human review and use as training data | Analyst |
Analysts need to ask follow-up questions of the scored data, such as which product line drove last week's fall. AgentAnalyst is an AI agent for natural-language analysis and real-time insights across enterprise data sources. On the front line, AgentForce provides AI teammates with assisted support, recommendations and business knowledge for customer service teams. Where an agent acts on a sentiment signal, for example offering a refund, ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents, so every action can be explained later.
The short video below shows one such decision in a hotel setting: winning back a loyal guest after a poor stay.
Video: a poor guest experience turned into a personalised recovery action.
How should you measure sentiment model quality?
- Build a labelled sample from your own feedback. Public benchmarks use movie reviews, tweets or restaurant reviews; your tickets and surveys use different language. Label a few hundred items per channel with two reviewers and agree on the rules for mixed and sarcastic text.
- Report precision, recall and F1 per class. Overall accuracy can hide failure on the negative class, which is often the smallest and the most important.
- Handle class imbalance. Feedback sets are often imbalanced, with few negative items in some channels. Use class weights, resampling or threshold tuning, and judge the model on the negative class.
- Test the hard cases. Negation, sarcasm, comparisons ("better than last time, still slow"), mixed reviews and code-switched or translated text.
- Watch for drift. New products, campaigns and channels change vocabulary. Recheck the labelled sample on a fixed schedule and after any service or model change.
What governance, privacy and cost questions should leaders ask?
| Area | Question to ask | Control |
|---|---|---|
| Personal data | Does feedback text with names, emails or account numbers leave our environment? | Mask personal data before scoring; set retention for raw text |
| Regulation | Are we inferring emotions of employees or students, or using voice or video? | The EU AI Act prohibits inferring emotions in workplaces and education (Article 5(1)(f)); get legal review |
| Bias | Does the model score some dialects, languages or customer groups more negatively? | Test per language and segment on the labelled sample |
| Explainability | Can we show why an item was scored negative and what action followed? | Keep aspect, confidence, model version and decision trace |
| Vendor change | What happens when an API is retired or a model version changes? | Abstract the scoring call; re-run the labelled sample before switching |
| Cost | Are we sending every message to a large model? | Use a cheaper model for volume and an LLM for the slice that needs it |
On regulation, the EU AI Act defines an emotion recognition system as one that identifies or infers emotions or intentions of people on the basis of their biometric data, and Article 5(1)(f) prohibits AI systems that infer the emotions of a person in the workplace or education institutions, except for medical or safety reasons. Text-only analysis of customer reviews is a different case, but contact-centre tools that score the emotion of staff from voice deserve legal review before use in the EU.
What adoption sequence works?
- Pick one decision. For example, which negative support emails get a same-day call. Define the action, the owner and the measure of success.
- Label a sample. Agree the label scheme (including mixed) and the aspects that matter, and label a sample from your real channels.
- Compare two approaches. Typically a managed API or fine-tuned model against an LLM prompt, measured per class on the same sample.
- Run in shadow. Score live feedback without acting on it, and compare with what people decided.
- Connect to the workflow. Route, escalate or draft responses, with human approval above agreed limits and a record of each decision.
- Extend by channel and language. Add channels one at a time and re-test each.
When should you not rely on automated sentiment analysis?
- Low volume. If a team can read every comment each week, reading beats scoring.
- High-stakes individual decisions. Do not deny a refund, end an account or judge an employee on a sentiment score alone.
- Unsupported languages or heavy jargon. Without a labelled test in that language or domain, scores are guesses.
- Questions sentiment cannot answer. Sentiment shows how people feel, not why. Pair it with aspect extraction and topic analysis, and keep reading samples of the raw text.
To map one customer-feedback decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is sentiment analysis in NLP?
Sentiment analysis, also called opinion mining, is the NLP task of classifying the opinion in a piece of text, usually as positive, negative or neutral, with a confidence score. It can run at document, sentence or aspect level, where aspect level ties the opinion to a named feature such as delivery or price.
What is aspect-based sentiment analysis?
Aspect-based sentiment analysis links each opinion to the thing it is about, so one review can be positive about staff and negative about price. It was set as a shared research task at SemEval-2014, and managed services now offer it: Azure calls it opinion mining and Amazon Comprehend calls it targeted sentiment.
Should we use a large language model for sentiment analysis?
Use one where you have little labelled data or need explanations alongside the label. A 2023 study by Zhang and colleagues found that LLMs do well on simpler sentiment tasks and clearly beat small models in few-shot settings, but lag behind on more complex, structured sentiment tasks. Test both on your own labelled sample before choosing.
How accurate is automated sentiment analysis on customer feedback?
There is no single figure. Accuracy depends on the domain, the language, the label scheme and how sarcasm and mixed opinions are handled. Measure precision, recall and F1 for each class on a labelled sample of your own feedback, and recheck it as products, channels and language change.
Does the EU AI Act restrict sentiment analysis?
The Act defines an emotion recognition system as one that infers emotions or intentions from biometric data, and Article 5(1)(f) prohibits inferring the emotions of people in workplaces and education institutions, except for medical or safety reasons. Text-only analysis of customer reviews is a different case, but voice or video emotion scoring of staff needs legal review.
Related reading: NLP vs NLU vs NLG.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE