Key takeaway
- Metacat is Netflix's unified metadata exploration API. Learn its goals, REST interface, supported stores, how to run it and how AI agents use metadata.
Metacat is a unified metadata exploration API service from Netflix that lets people and tools look up metadata about datasets held in many different data stores through one interface. Its README describes it as a unified metadata exploration API service, built to describe data so that more useful things can be done with it.
This page is for data engineers, platform teams and architects who deal with data spread across several stores and engines. It covers what Metacat is for, how its REST interface fits into API design in general, what its stated goals are, how to run it, and how AI agents change metadata work.
What is Metacat and why was it built?
An organisation's data rarely sits in one place. The Netflix Metacat repository lists Hive, RDS, Teradata, Redshift, S3 and Cassandra among the systems it explores, and the repository also contains modules for Druid, JDBC, MySQL, Pig, PostgreSQL and Snowflake. Each store keeps its own metadata, which is data about the data: schemas, tables, partitions and locations. Without a common layer, every tool has to learn every store.
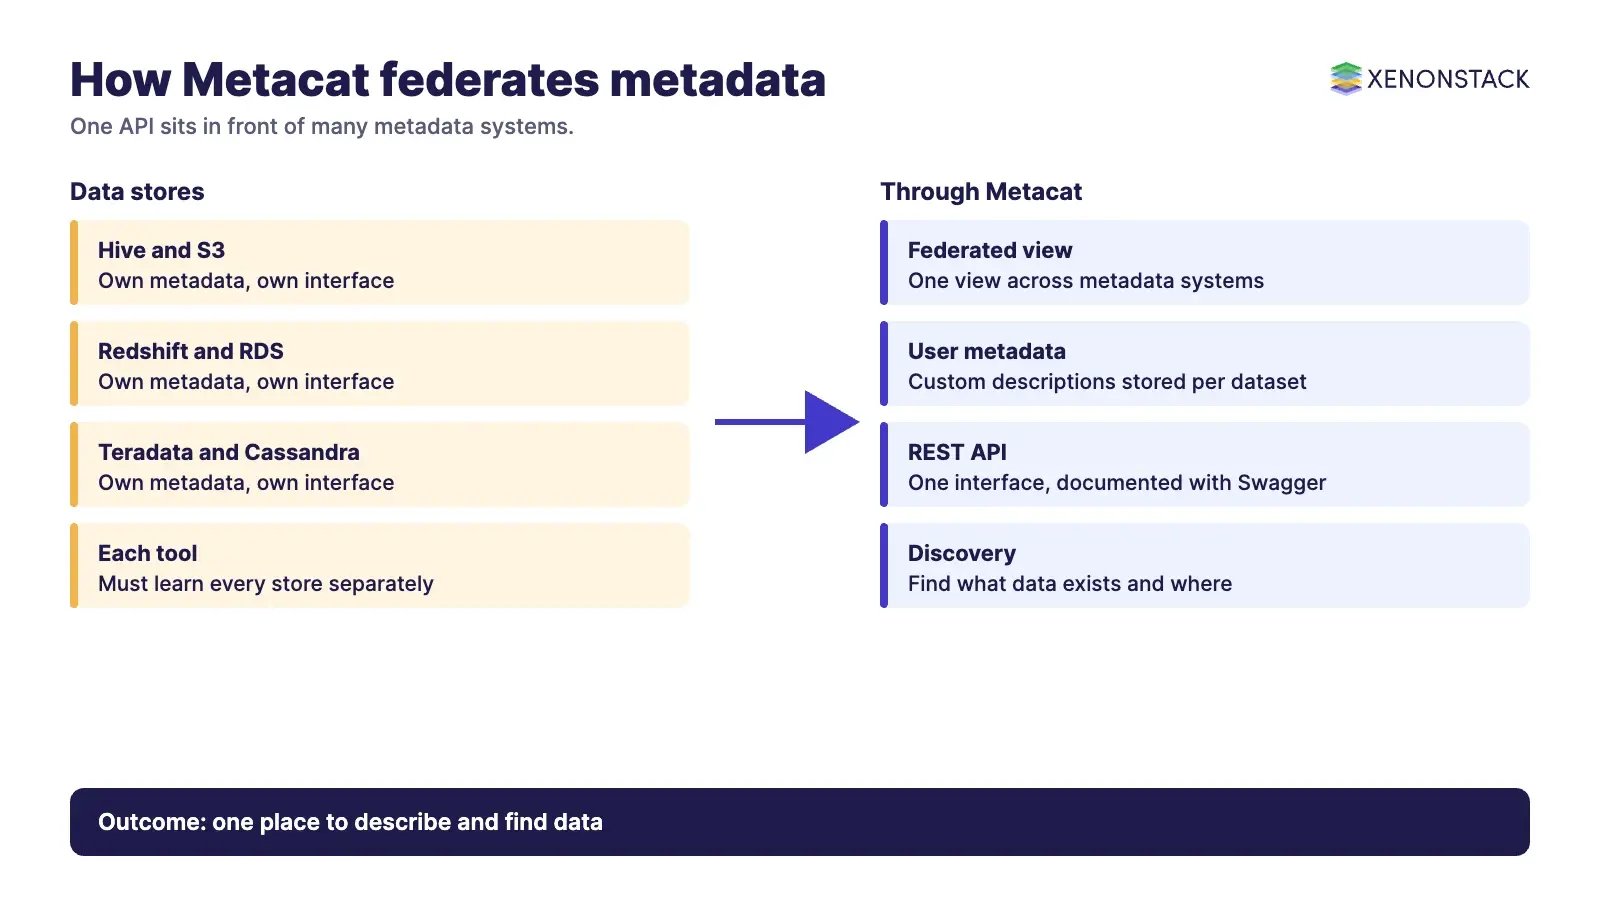
Metacat puts one API in front of those metadata systems. The stated goals in the README are to federate views of metadata systems, to allow arbitrary metadata storage about datasets, and to support metadata discovery. In practice that means a user or a processing engine can ask one service what data exists, where it lives and how to process it.
What are the main objectives of Metacat?
| Stated goal | What it means in practice |
|---|---|
| Federate views of metadata systems | One interface shows metadata from several underlying stores instead of one query per store |
| Allow arbitrary metadata storage about data sets | Teams can attach their own descriptive information to a dataset, beyond what the source store records |
| Metadata discovery | People can find out what data exists, where it is and how to use it |
The source store remains the system that holds the schema. Metacat adds a place to describe the data and a common way to read that description. Check the repository for the current list of supported connectors before planning around a specific store, because the README text and the module listing do not match exactly.
How do APIs and REST fit in?
An API, or application programming interface, lets one application request something from another and receive a response. Metacat provides a REST API, documented with Swagger. REST stands for Representational State Transfer and is a widely used style for web APIs built on HTTP. It separates client from server, keeps each request self-contained so the server does not store client context between requests, allows responses to be marked as cacheable, and works through layers such as load balancers.
APIs also differ by audience. Open APIs are public, internal APIs serve teams within one organisation, partner APIs are open to selected outside parties, and composite APIs reach several services through one call. A metadata service like Metacat is usually an internal API. For access control options, see our guide to the top API authentication methods, and for flexible query styles see GraphQL features and tools.
Which HTTP methods does a REST metadata API use?
| Method | Typical purpose |
|---|---|
| GET | Read a resource without changing it |
| POST | Create a new resource; the server assigns its identifier |
| PUT | Replace or update an existing resource |
| PATCH | Change only specific parts of a resource |
| DELETE | Remove a resource |
These are the standard HTTP semantics rather than anything specific to Metacat. Read the project's Swagger documentation for its exact endpoints, resource paths and request bodies.
How do you build and run Metacat?
According to the README, Metacat is built with Gradle and produces a WAR file that you deploy to Tomcat. It needs two configuration settings: a catalog configuration directory and a user-metadata connection properties file. A Docker Compose setup is included for a local test cluster, which is the quickest way to try it. The README's documentation section is marked TODO and does not state whether the project is actively maintained, so review recent commits and open issues before depending on it. Also note that the build badge points to Travis CI, which may be outdated.
What are the limits of a metadata API?
- Quality depends on the people: free-form user-defined metadata is only as good as the process that fills it in. Add validation rules before you rely on it.
- One more service to run: a federation layer adds an operational dependency and a security surface.
- Coverage varies: a connector only helps if it supports the store and version you use.
How do AI agents change metadata and data discovery?
Agents that answer data questions or run analysis need to know which datasets exist, what they mean and who may use them. A metadata API is a natural source for that knowledge, but descriptions alone do not tell an agent which policy applies to a decision. XenonStack's ElixirData is its Context OS, the layer that connects data, meaning and policy so that agents act on governed context.
What should you do first?
- List the data stores whose metadata your teams query today.
- Check whether a catalog or metadata service already covers them.
- If you evaluate Metacat, run the Docker Compose cluster and read the Swagger documentation.
- Define who owns user-defined metadata and how it is validated.
- Decide which metadata an agent may read and which actions need human approval.
Related reading: API latency rate versus response rate and contract testing for microservices applications.
To map one decision your agents make on your metadata, and the data and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is Metacat?
Metacat is a unified metadata exploration API service from Netflix, described in its README as a way to federate views of metadata systems, store arbitrary metadata about datasets and support discovery.
Which data stores does Metacat support?
The README names Hive, RDS, Teradata, Redshift, S3 and Cassandra, and the repository also has modules for Druid, JDBC, MySQL, Pig, PostgreSQL and Snowflake. Check the repository for the current list.
Does Metacat have a REST API?
Yes. The README documents a REST API and provides Swagger documentation.
How do I run Metacat locally?
Build it with Gradle, deploy the WAR file to Tomcat with the two required configuration settings, or use the Docker Compose setup for a local test cluster.
Is Metacat the same as a data catalog?
It covers a similar need, which is describing and finding data, but it is a service with an API rather than a full catalog product. Evaluate it against your own requirements.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE